Claude Fable 5.1 is here, and it cracked a bug that beat human engineers for years.
Hedge fund Millennium had a rare crash nobody could explain. Not their team, not any other model. Fable 5.1 found the root cause.
1M context, 128K output, ~25% cheaper than Fable 5, up to 45% on agentic work.
Three months after Fable 5. Better and cheaper.
The gap between model releases is now shorter than most companies onboarding.
Google employees have started posting like something BIG is about to happen.
No links, no specs, no dates. Just people who've seen something we haven't, saying nothing very loudly, and it's spreading across the team.
Gemini 4 entered pre-training July 21. Pichai called it Google's biggest training run ever. Meanwhile 3.5 Pro has been stuck in partner testing since June.
When a team starts teasing in public, the internal numbers usually came back good.
Or they're just bored. 😂
GLM-5.3 just did something no open-weights lab does, it held back the weights.
https://t.co/L3BJrlU3dN shipped GLM-5.2's weights on Hugging Face within days. For 5.3, they're waiting two weeks for safety evaluation and hardening first.
Why? It scores 84.5 on CyberGym, a benchmark for finding real vulnerabilities in real source code, edging out both Claude Mythos 5 and GPT-5.6 Sol.
And it's not theoretical. https://t.co/L3BJrlU3dN says GLM models have surfaced 2,436 vulnerabilities across 269 open-source projects, Kernels, Browser engines, Network protocols. The oldest bug they found was introduced in 1981.
Same 743B base as 5.2. Every gain came from post-training.
The open-source frontier didn't just catch up on capability. It caught up on the part where you have to think before you ship.
Introducing GLM-5.3: Built to Code. Ready for Cyber Defense.
- Top-tier coding and agentic capabilities, achieved through post-training on the 743B base model
- A major leap in cybersecurity, setting a new standard among open models
Tech Blog: https://t.co/ekQkO83jCv
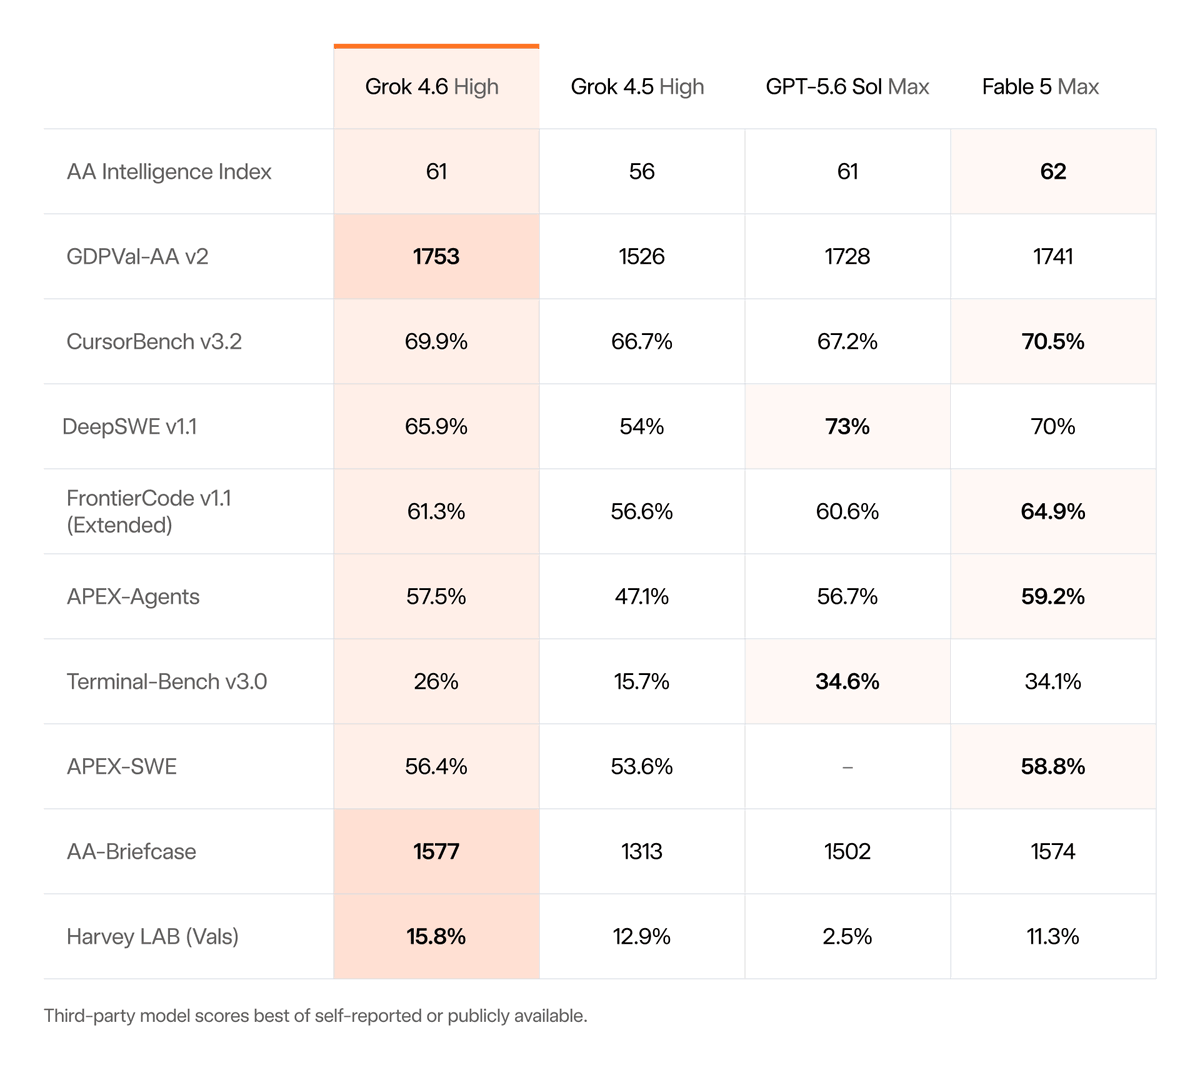
Grok 4.6 hit the frontier without scaling up. That should worry a lot of people.
Same price as 4.5. No bigger base model. Just better post-training, closing ground that used to take a full generation.
It matches GPT-5.6 Sol on the AA Intelligence Index at 61 and tops the table on GDPVal and AA-Briefcase. It still trails on DeepSWE and Terminal-Bench, and Fable 5 holds the lead on agentic coding.
So not a knockout. Something stranger, xAI is closing frontier gaps in weeks, at flat pricing.
And Grok 4.7 is reportedly 2 weeks away now.
The scoreboard stopped being the interesting part. The clock is.
Google might be about to do something no frontier lab has done, SKIP a flagship.
Gemini 3.5 Pro was promised in June. It's August. It's still stuck in partner testing, and reports now say Google may shelve it entirely and jump straight to Gemini 4.
That's not a delay. That's a company looking at its own flagship and deciding it isn't worth shipping.
So what replaces it has to be a monster. Pichai says Gemini 4 is the largest training run in Google's history, a bigger base model, built for agentic work and coding, the exact places Google admits it's behind.
One model. One shot. And Google plugs it into Android, Chrome, Search, YouTube, Maps, Workspace the day it lands.
Everyone's arguing about whether Gemini 4 will be a monster. The real question is why Google decided it had to be.
Rockstar just made Netflix the front door to GTA 6.
GTA 6 Extended Look premieres Aug 27, 3PM ET, Netflix only. YouTube gets it at 9PM ET, 6 hours later.
Qwen3.8-Max just landed at #4 on Arena's Frontend Code board. 1,668 points.
One point behind Claude Opus 5 (High). Ahead of Fable 5. Ahead of GPT-5.6 Sol.
Two of the top four are now Chinese models.
And it ranks across the board, #2 Consumer Product, #3 Brand & Marketing, #3 Gaming, #4 Data & Analytics.
Alibaba says open weights are coming.
The gap isn't closing. It closed.
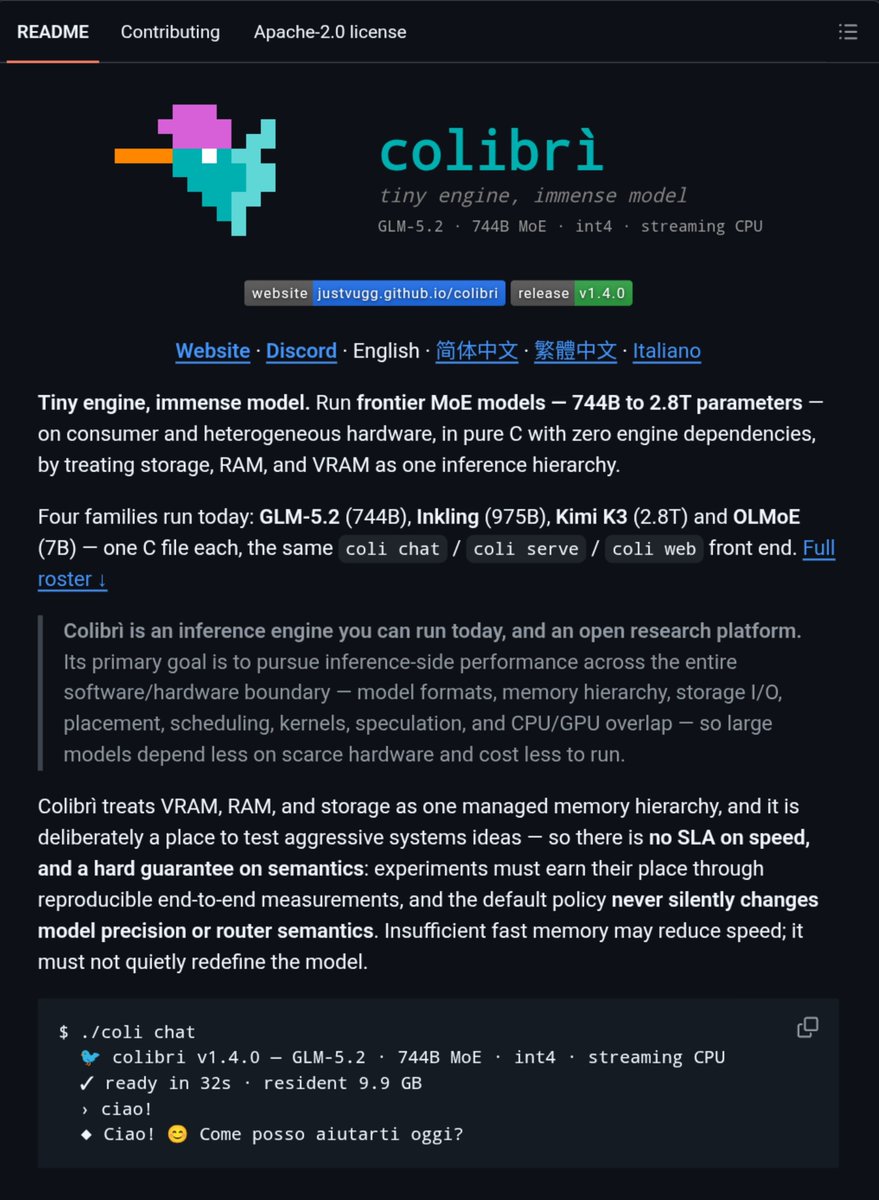
Huge: you can now run a 2.8 trillion parameter AI model on a normal PC with only 25GB of RAM.
No GPU. No cluster. Just a pure-C engine called Colibrì.
It keeps the dense core in memory and streams the rest of the experts straight off disk the moment the router needs them.
Storage, RAM and VRAM stop being separate things. They become one memory hierarchy.
Zero dependencies. Apache-2.0. 21K stars. Runs Kimi K3, GLM-5.2 and more.
The bottleneck was never model size. It was the assumption that every parameter had to sit in fast memory at once.
Frontier AI's future isn't bigger models on bigger GPUs. It's engines that only wake the tiny fraction of the model that's actually thinking.
Gemini 3.5 Pro leaked on Arena and the early reads are brutal.
~50 minutes live before Google pulled it. A/B testing already running.
Testers say it's ahead of Fable 5 and GPT-5.6, frontend, multimodality, reasoning across the board.
If this holds, Google just took the crown back. First week of August.
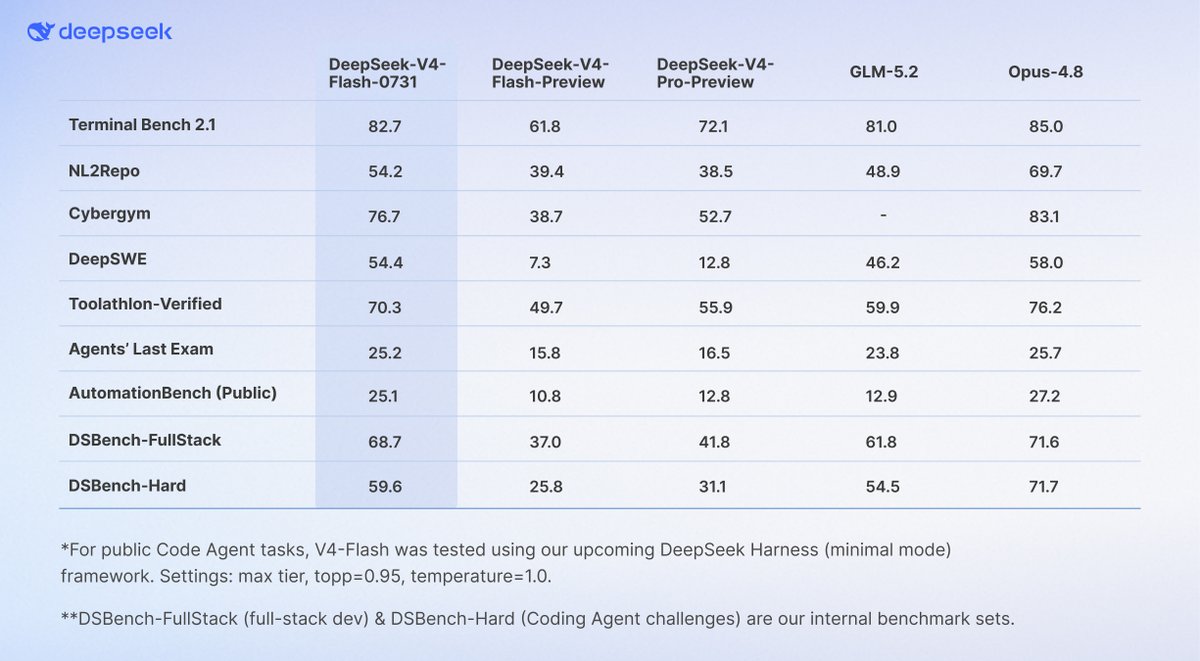
DeepSeek V4-Flash scores 82.7 on Terminal-Bench 2.1 and beats DeepSeek's own V4-Pro-Preview on all nine benchmarks they published.
DeepSWE: 54.4 vs 12.8. Pro costs three times more than the model that just embarrassed it.
One caveat worth holding onto. Flash's number came from DeepSeek's unreleased in-house harness at max tier, and two of those nine tests are DeepSeek's own internal sets.
Harness choice moves these scores by several points. Opus 5 reads 84.64 on https://t.co/JKeLuamBBZ and 89.1 on Artificial Analysis, same model, same benchmark.
Open weights are said to be coming shortly. Then the price column stops being the interesting part.
🚀 DeepSeek-V4-Flash Official API is now LIVE in public beta!
🔷 We’ve massively upgraded its Agent capabilities—benchmark scores are now far surpassing the V4-Pro-Preview. Check out the massive performance leap below! 👇
🔷 The official V4-Flash now natively supports the Responses API format and is fully adapted for Codex!
Check out the configuration details in our official API docs: https://t.co/smCwQZMeiq
OMG
Pirate a book: $3,000 a title.
Buy the same book used and run it through a hydraulic press, about $4, and it's legal.
Guess which one the industry picked.
404 Media reported AI firms are sourcing through intermediaries under NDA, pallets of 800 to 1,200 books, orders past 10,000 volumes, spines sliced off, pages fed through scanners at 80 to 120 a minute, originals pulped.
Anthropic did it at scale under Project Panama. An internal document described the goal as destructively scanning every book in the world.
Judge Alsup ruled that buy-scan-destroy pipeline is fair use, protected by first-sale doctrine. The pirated-books case ended in a $1.5 billion settlement.
Non-destructive scanning exists. It's just slower and costs more. Musk says he's asked the SpaceXAI team to do it that way instead.
The ruling didn't stop the shredding. It just priced it.
Most bounce, but Google probably doesn't mind. The point of the window is getting people to see what Omni does before it becomes the default video model in the app, Veo is being retired out from under them either way.
Omni Flash is already free on YouTube Shorts. So the people most likely to convert also have a decent free escape hatch, which softens the paywall a lot.
Google is handing out ten Gemini Omni videos a day until August 4.
Omni normally sits behind AI Plus, Pro and Ultra. Free-tier users haven't had it at all.
The API charges $0.10 per second of output. Ten eight-second clips is $8 a day, roughly $48 across the window.
Omni isn't a side feature. It's replacing Veo in the Gemini app outright. This is Google moving people onto the new default before the swap finishes.
Six days of free, then a paywall you now know the shape of.
Starting today, you can create ten videos *at no cost* in Gemini until 11:59pm PT on August 4th, 2026.
Just select "Create video" in the tools menu to create, edit, and remix videos to bring your ideas to life.
Share how you’re using Gemini Omni in the replies 👇
No one's telling you how to run kimi k3 locally for free and save $99+/month
1) download the 2-bit quantized version from hugging face, tiny, only ~1 tb
2) that's the compressed one btw, the real one is 1.56 tb
3) you need ~900 gb of aggregate vram, your 4090 covers 2.6% of it
4) so, 8× nvidia b300 or 8× amd mi355x (single node)
5) or 16 - 32× h100 / b200 with expert + tensor parallelism
6) don't forget a nvme array and a psu that won't melt
total cost for each setup:
1) 8× b300 ~ $400,000 - $550,000
2) 8× mi355x ~ $190,000 - $350,000
3) 16-32× h100 ~ $400,000 - $1.2m+
4) 16× b200 ~ $600,000 - $1m+
you need atleast $350,000 worth of setup to run kimi locally
but hey, it's free