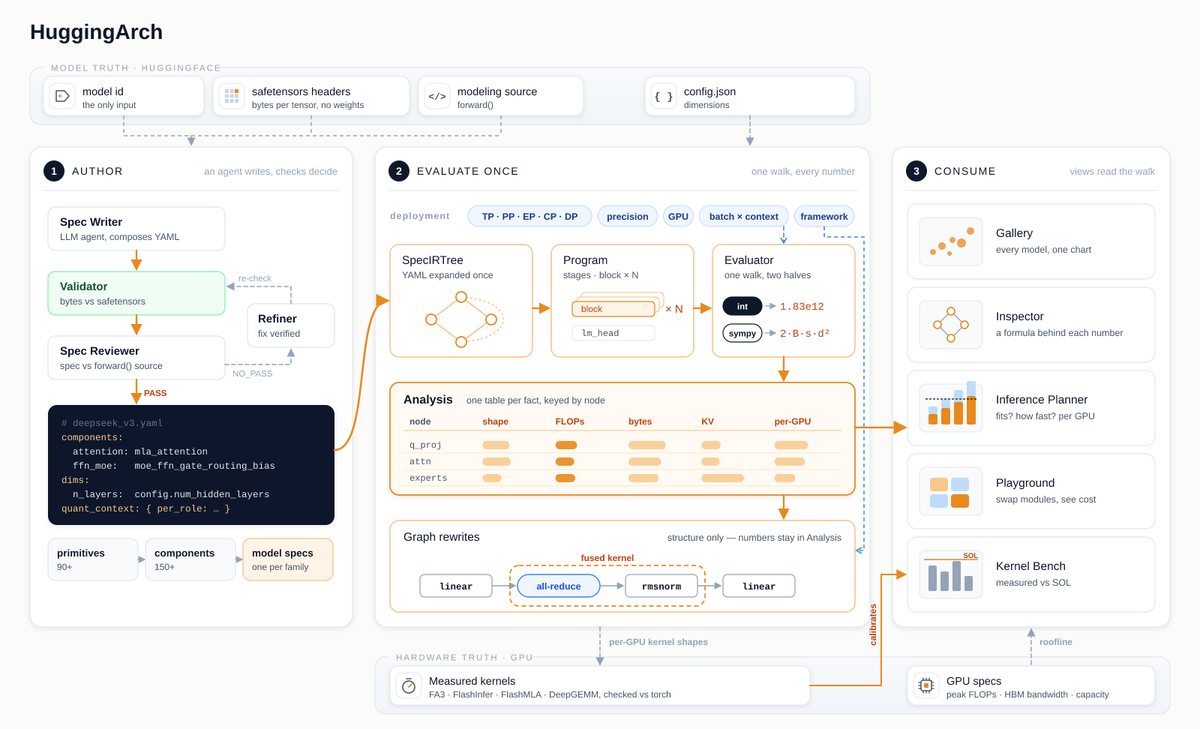
Spent half a year of spare time building HuggingArch — a "compiler" that doesn't run tensors, but computes FLOPs, memory traffic & KV cache for any HuggingFace model.
Agent writes the spec → sympy evaluates → one click gives theoretical perf across GPUs & parallel configs.
No GPU. No weights. No runtime.
web: https://t.co/NhTMuwadfT
blog: https://t.co/9VFd9aZHma
github: https://t.co/UVTKOlcCrn
Star ⭐ & come build it with me!
@SoumilBhandari Exactly — decode is almost always memory-bandwidth bound, so bytes/token is the number that matters. I believe when you want to analysis a model, you don't have to download the full weights at all.
Spent half a year of spare time building HuggingArch — a "compiler" that doesn't run tensors, but computes FLOPs, memory traffic & KV cache for any HuggingFace model.
Agent writes the spec → sympy evaluates → one click gives theoretical perf across GPUs & parallel configs.
No GPU. No weights. No runtime.
web: https://t.co/NhTMuwadfT
blog: https://t.co/9VFd9aZHma
github: https://t.co/UVTKOlcCrn
Star ⭐ & come build it with me!