#SC26 is open and our CEO @HarryCarr and CTO @stephenwallo are in Chicago!
If data access and compute capacity is slowing your workloads down, let’s talk while we’re both here.
📅 https://t.co/uJYFmNHyua
#SC26#HPCunites
How much of your AI pipeline is spent computing vs waiting?
If you want to reframe what your AI strategy could look like without the limits of distance and latency—catch our team in Chicago next week:
📅 https://t.co/LPdYACb5DA
#SC26#HPCunites
Copying data so available AI and HPC can use them is a workaround—not a strategy.
Running distributed HPC or AI—and want to use your available compute capacity? Let's chat!
📅 Grab 30 minutes: https://t.co/NrkuHMhtPz
#SC26#HPCunites
Your GPUs can't work on data they can't reach. At #SC26, most convos will be about compute. We want to talk about the bottleneck behind it: data that’s sitting far away from compute, while expensive accelerators wait for it.
📅 Meet us: https://t.co/OlLpg6zd6r
#SC26#HPCunites
At the tactical edge, distance isn't measured in miles, but how long it takes to turn data into action.
Ready to solve for distance, latency, and AI orchestration?
Meet Vcinity and @ParallelWorks : https://t.co/LDF8EceBPX
📍Booth #1004
#TechNetIndoPacific#AFCEA
@ParallelWorks orchestrates the compute. Vcinity gives those workloads fast, secure access to the data wherever it lives.
Together, compute and data goes where they're needed, when they're needed.
See how it works at Booth #1004 at #TechNetIndoPacific: https://t.co/EhIt20yXXQ
The longer it takes to move edge data to analysts, the longer it takes to generate intelligent insight--and act. Vcinity closes that gap.
Is distance slowing decisions? Chat with us or @ParallelWorks : https://t.co/oSCmRO26t0
or see us at📍Booth #1004
#TechNetIndoPacific
Data is the fuel for AI.
Vcinity makes sure that fuel reaches your compute — wherever your data lives, wherever your workloads run.
#AI#DataAccess#Vcinity
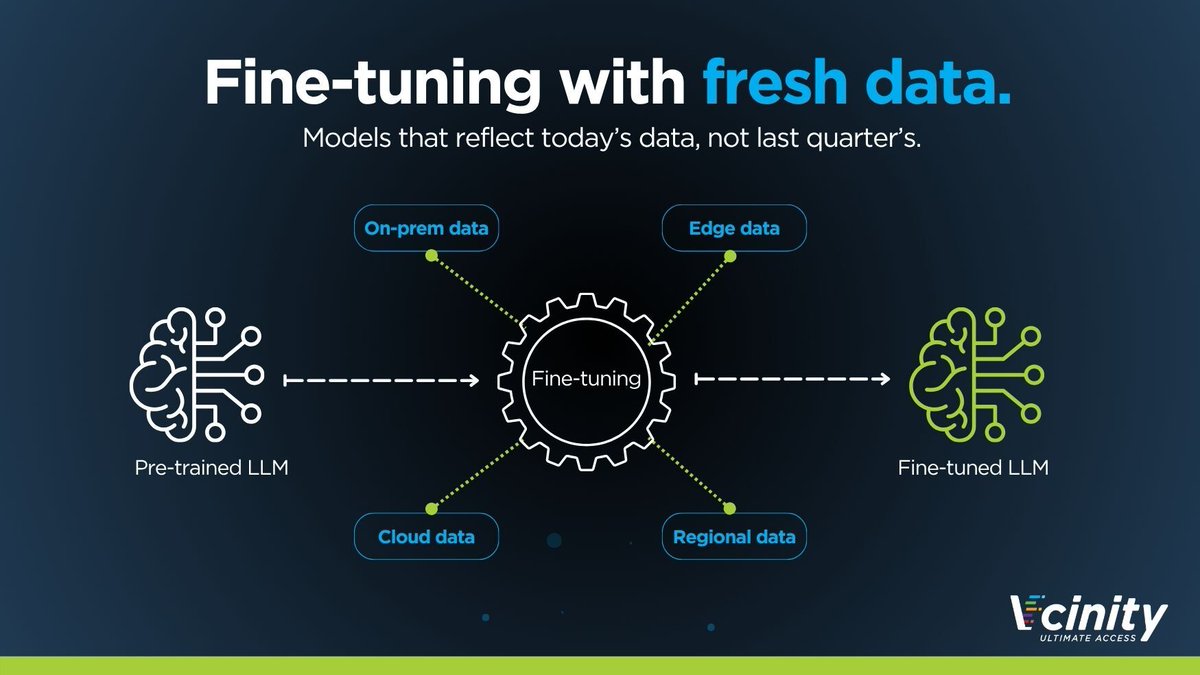
Fine-tuning is only as current as the data you can reach.
Vcinity connects your models to distributed, domain-specific data in near real time—so every iteration reflects what's happening now, not last quarter.
#EnterpriseAI#FineTuning#Vcinity#dataaccess
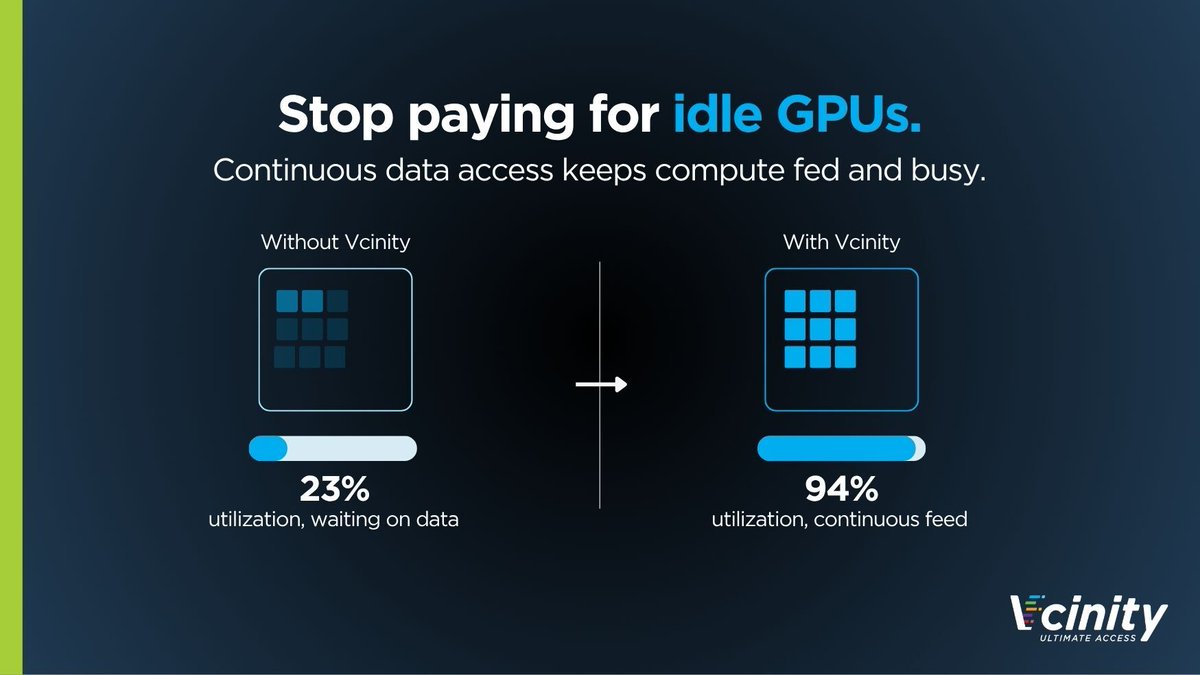
Your GPUs shouldn't wait on your data.
Vcinity gives AI training pipelines near real-time access to datasets across any distance—so compute stays fed and utilization stays high.
#AIInfrastructure#GPUUtilization#DataAccess#EnterpriseAI
AI models are only as good as the data they can actually reach.
Vcinity is the WAN data layer that gets your data there—fast, secure, and without moving mountains of storage to do it.
#AIInfrastructure#GPUUtilization#DataAccess#EnterpriseAI
The best infrastructure modernization is the kind nobody has to relearn. No extra training. No patches or new workarounds. Just plug and play.
Vcinity is the missing data layer, slotted in underneath the AI stack you already have.
#AIInfrastructure#DataAccess#EnterpriseAI
Every AI infrastructure stack has compute. Storage. Models. UIs. Almost none of them have solved the layer in between.
Vcinity is that missing piece—the data layer connecting distributed storage to distributed compute.
#AIInfrastructure#DataAccess#EnterpriseAI
Days to seconds.
Vcinity accelerates distributed data access from days or hours to minutes or seconds—no matter where your AI infrastructure sits.
That's the difference between an AI roadmap and true enterprise AI.
#AIInfrastructure#GPUUtilization#DataAccess#EnterpriseAI
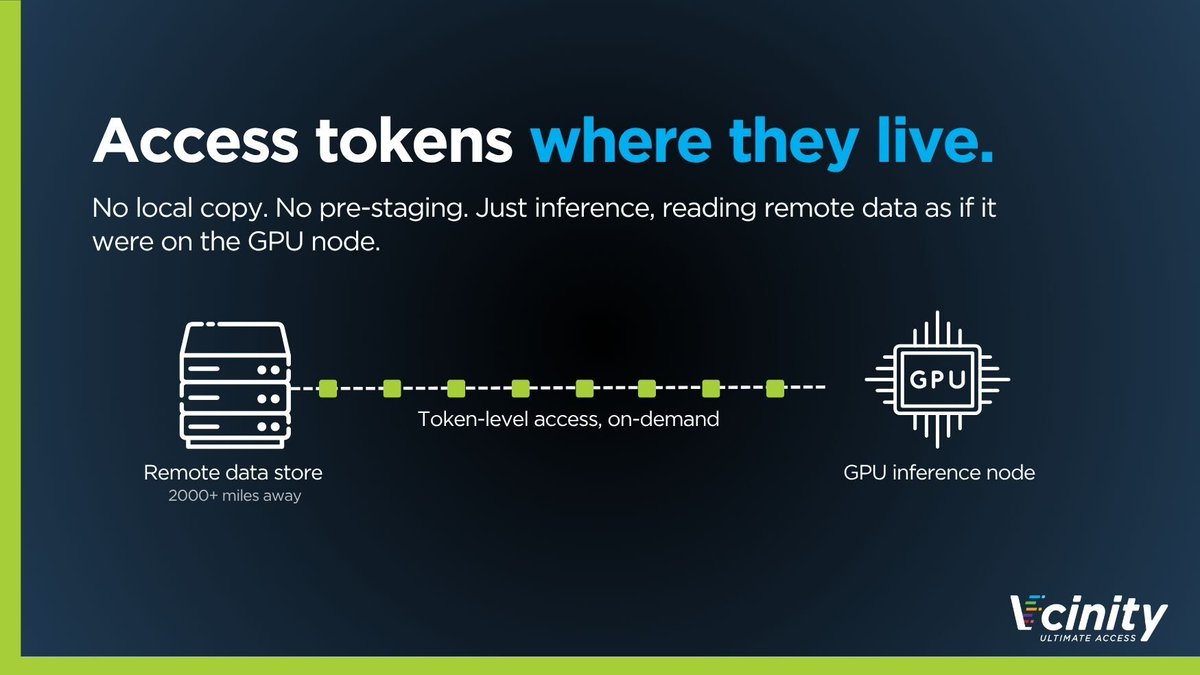
AI doesn't care where your data is. Your network does.
Vcinity is the WAN data layer every distributed AI stack is missing—delivering fast data access, regardless of distance, latency, or scale.
Now distance is no longer a problem.
#AIInfrastructure#DataAccess
AI is taking place everywhere: training in data centers and/or hubs, inferencing everywhere else.
Vcinity extends the WAN data layer all the way to the edge—even over high latency and lossy networks.
Real-time AI, wherever your edge actually is.
#AIInfrastructure#DataAccess