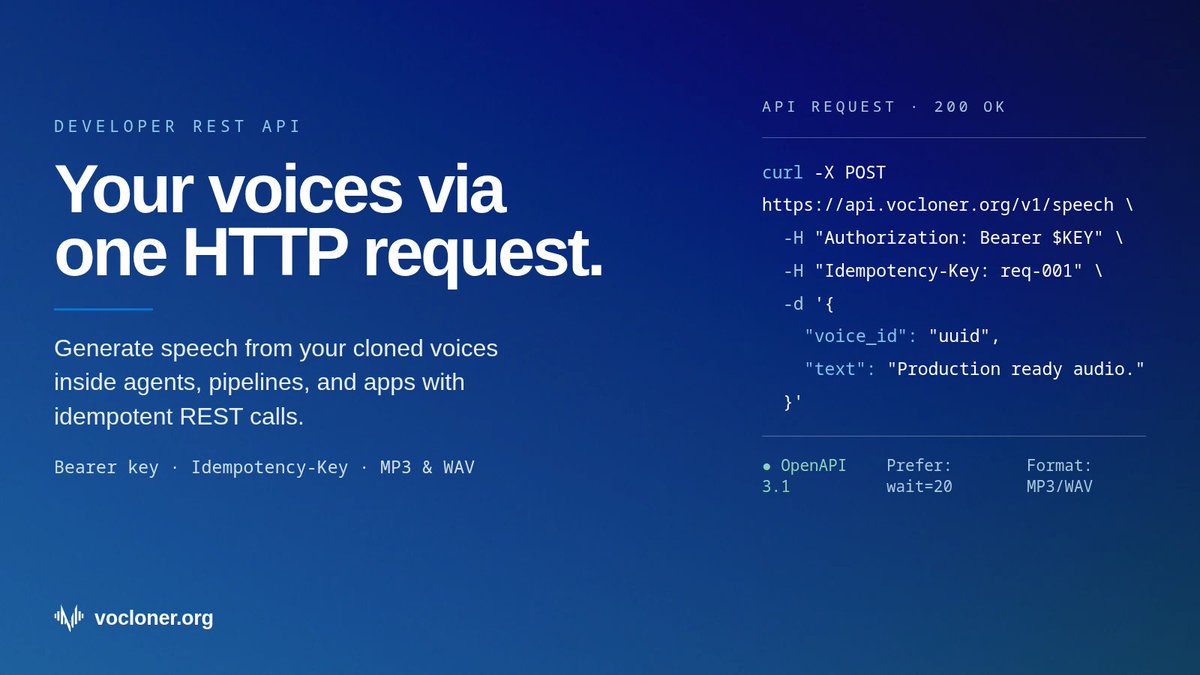
Developers: you can integrate zero-shot voice cloning into your app in less than 5 minutes.
Single HTTP POST request:
• Audio prompt URL or base64
• Target text script
• Optional emotion / pacing parameters
Returns streamable MP3/WAV. 🧵👇
Looking for a fast, modern ElevenLabs alternative?
We benchmarked core workflows:
• Instant Voice Clone: 10s sample vs heavy training
• Emotion Tags: Native inline tags vs rigid slider presets
• Latency: sub-400ms time-to-first-audio
• Pay-as-you-go & transparent usage
High fidelity doesn't need to mean high friction or predatory subscription locks.
• Watermark & provenance protection built-in
• High-capacity concurrency
• Direct REST API access with the same quality as web studio
• Zero vendor lock-in on your custom voice libraries
Create multi-speaker scripts with custom clones:
https://t.co/PJoL2zAulk
Available directly inside the studio interface. Export uncompressed WAV or web-ready MP3 in one click.
#Podcasting#AIaudio#AudioProduction#Scriptwriting#EdTech
Producing two-person dialogues usually means switching tabs, exporting separate MP3s, and lining them up in Audacity.
Now you can generate full multi-speaker scenes directly from a single script:
Assign Speaker A & Speaker B ➔ Click render ➔ Export a seamless dialogue track.
Perfect for:
• Co-hosted AI podcasts & interview simulations
• E-learning scenario roleplays (Student vs Tutor)
• Script read-throughs for screenwriters and dramatists
Both voices maintain their distinct acoustic identities, volume dynamics, and pacing throughout the dialogue
Test emotion-tagged rendering directly on the playground:
https://t.co/PJoL2zzWvM
No custom training required—tags adapt directly to whatever voice model you are using.
#VoiceActing#AItools#AudioEditing#ContentCreators#TTS
The biggest issue with AI voiceover is flat, robotic delivery.
Real human speech changes emotion mid-sentence, ours too
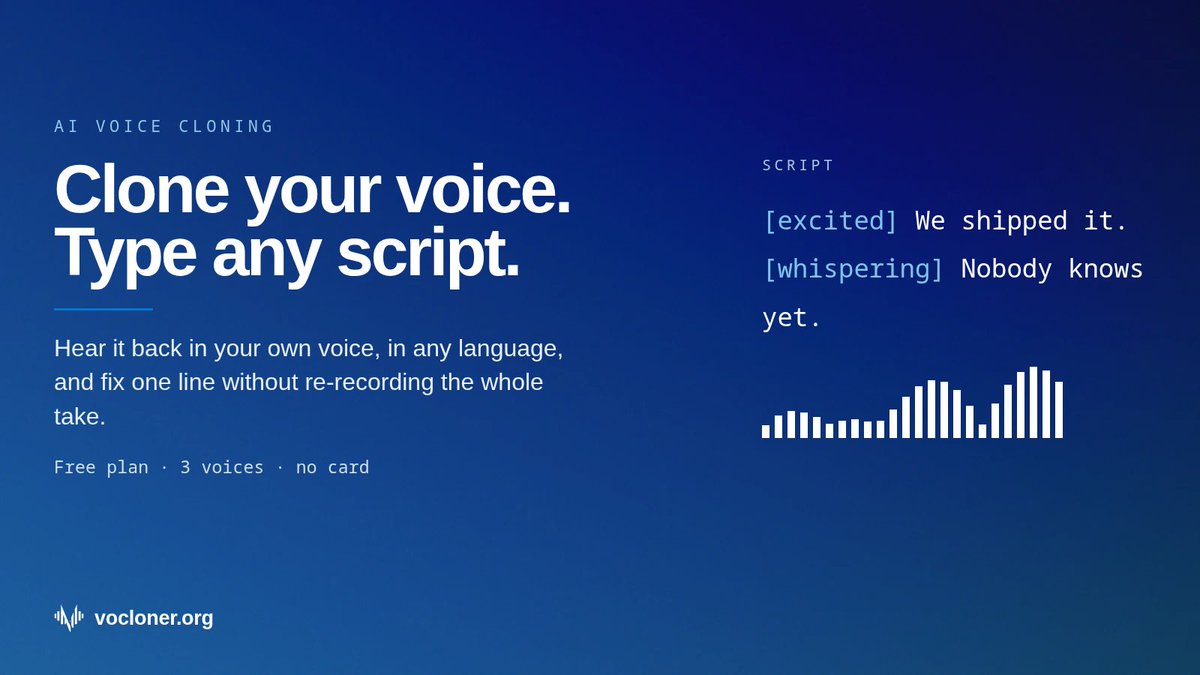
You can now steer tone using natural emotion tags inline:
"Wait... [whispering] did you hear that? [giggle] You're completely crazy!"
Here is how it works👇
Why inline tags matter for creators:
1. Audiobooks & narration: transition from narrative distance to intense character dialogue.
2. Short-form video (Reels/TikTok): hook retention spikes when cadence breaks monotony.
3. Game dev & NPC dialogues: dynamic mood injection.
Try your own voice sample for free (zero credit card required):
https://t.co/PJoL2zzWvM
Works directly in your browser. Upload any WAV or MP3 and hear the cloned result in under 5 seconds.
#AIVoice#VoiceCloning#TextToSpeech#ContentCreation#IndieHacker
Most AI voice tools require 10-30 minutes of clean studio audio.
With zero-shot neural cloning, all you need is a 10-second voice note.
Upload audio ➔ enter your script ➔ generate speech with full cadence & timbre retained.
Here is how it works under the hood 🧵👇
Traditional TTS models separate prosody from timbre.
Modern zero-shot architecture captures:
• Acoustic resonance & speaker timbre
• Micro-pauses and natural breathing rhythm
• Multi-language adaptation without accent loss
No fine-tuning loops. No waiting.