🚨 There are too many models to choose!
Whether you're shortlisting candidates before fine-tuning, picking among 500+ models on OpenRouter, or searching through hundreds of thousands of checkpoints on HuggingFace, the question is the same:
Which model should you actually use for a new task?
💡 Introducing ModelLens — a model recommendation system for the open-source model ecosystem.
Instead of asking users to evaluate or fine-tune every candidate model, ModelLens asks a different question:
👉 Can we leverage large-scale model–dataset interaction patterns from public leaderboards to enable model selection in the wild, without requiring direct evaluation or fine-tuning?
Our key insight:
The millions of (model, dataset, performance) records accumulating on all platforms are not just leaderboard noise. They encode how model capabilities align with task characteristics across the open-source ecosystem.
⚙️ How it works:
We collect large-scale model–dataset performance interactions from public leaderboards (HuggingFace, Open LLM Leaderboard, Papers with Code) and learn transferable model–task compatibility, jointly modeling:
- 47K models across 348 architecture families
- 9.6K datasets across 2,551 task types
- 8,420 heterogeneous evaluation metrics
- 1.62M historical performance records as implicit supervision
Given any task description, ModelLens then recommends a ranked Top-K pool of candidates likely to perform well, generalizing to newly released models and never-benchmarked datasets, before any of them is ever run on the target task.
task description → learned model–task compatibility → Top-K recommended models
📊 What ModelLens enables:
✅ Recommend Top-K models for a new dataset
✅ Rank newly released models against existing models
✅ Build model pools before routing or cascading
✅ Reduce costly brute-force evaluation
✅ Scale model selection in the open-source AI ecosystem
📰 Paper: https://t.co/5SyNfY3OlE
💻 Code: https://t.co/YUepL9ntpv
🌐 Demo: https://t.co/UnMt0zt55q
Try the demo with your own task description — we’d love feedback from people working on model selection, routing, AutoML, and open-source LLM ecosystems.
Thanks to all coauthors: @Wenjie_Jacky_Mo@Xiaofei_Wen_Mk@qiyao_ma@WenhuiZhu8@XiwenChen37@muhao_chen@zpegt
#MachineLearning #OpenSource #AI #ModelSelection @OpenRouter@huggingface
@MICCAI_Society
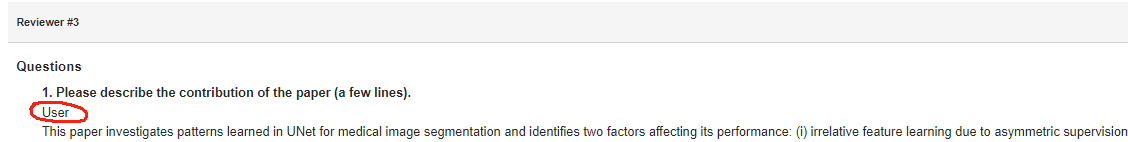
The review was created by uploading our unpublished manuscript directly into ChatGPT(the reviewer confidence score of 4).
Such behavior not only undermines the integrity of the MICCAI community but also diminishes its credibility in the field of medical imaging.
This paper formally reformulates multivariate time series classification (MTSC) as a weakly supervised problem, introducing a novel multiple instance learning (MIL) framework for better localization of patterns of interest and modeling time dependencies within time series.
Excited to announce that our paper "TimeMIL: Advancing Multivariate Time Series Classification via a Time-aware Multiple Instance Learning" has been accepted by #ICML2024#TimeSeriesAnalsyis.
Please check the paper in: https://t.co/ON7q1sRGSd