In the mobile internet era, we measured DAU. In the AI era, we may end up measuring DAA instead. Tokens measure usage. DAA measures actual output. That difference sounds subtle, but it changes the whole conversation around AI.
Here is a quick addition to your metrics vocabulary: DAA.
Short for Daily Active Agents, it is the agent era's equivalent of DAU. Where tokenomics tracks cost, DAA tracks output — how much work agents are actually getting done.
See the full comparison ↓
Here is a quick addition to your metrics vocabulary: DAA.
Short for Daily Active Agents, it is the agent era's equivalent of DAU. Where tokenomics tracks cost, DAA tracks output — how much work agents are actually getting done.
See the full comparison ↓
ERNIE 5.1 is here 🚀
ERNIE 5.1 significantly reduces pretraining cost while compressing total parameters to ~1/3 and activated parameters to ~1/2 — using only ~6% of the pretraining cost compared to models at similar scale, while achieving leading performance in its class.
💡Key highlights:
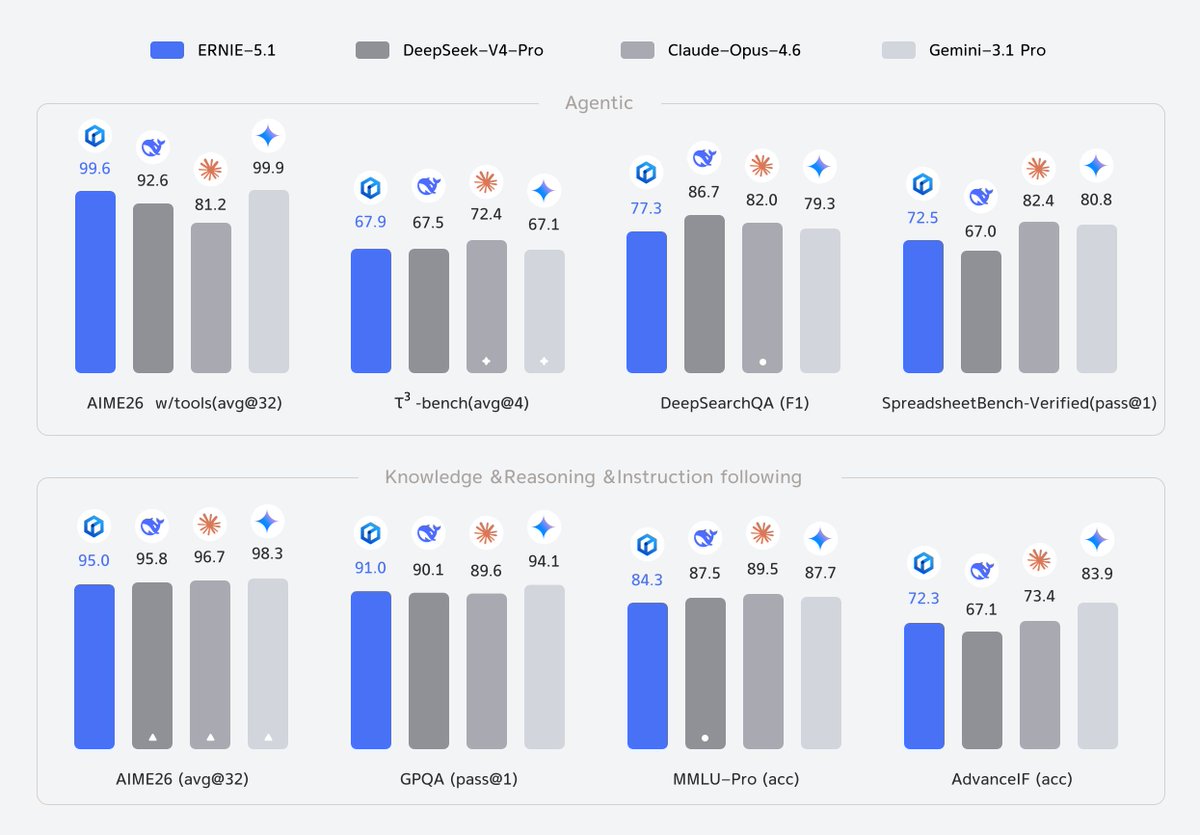
1/ Strong agentic performance approaching leading frontier models. ERNIE 5.1 surpasses DeepSeek-V4-Pro on both τ3-bench and SpreadsheetBench-Verified.
2/ Strong world knowledge and creative writing capabilities, with GPQA and MMLU-Pro performance approaching leading closed-source models, and creative writing ability nearing Gemini 3.1 Pro.
3/ Frontier-level reasoning performance. ERNIE 5.1 scores 99.6 on the challenging AIME26 benchmark with tools, second only to Gemini 3.1 Pro.
4/ Deep search capability. On May 9, ERNIE 5.1 ranked #4 globally and #1 among Chinese models on the Arena Search leaderboard with a score of 1223.
ERNIE 5.1 is now available on ERNIE and the Baidu AI Studio Model Playground:
👉https://t.co/qhd67Lg3B4
👉https://t.co/AaQSqDmVGU
👉https://t.co/uCNiypIu1q
ERNIE 5.1 is here 🚀
ERNIE 5.1 significantly reduces pretraining cost while compressing total parameters to ~1/3 and activated parameters to ~1/2 — using only ~6% of the pretraining cost compared to models at similar scale, while achieving leading performance in its class.
💡Key highlights:
1/ Strong agentic performance approaching leading frontier models. ERNIE 5.1 surpasses DeepSeek-V4-Pro on both τ3-bench and SpreadsheetBench-Verified.
2/ Strong world knowledge and creative writing capabilities, with GPQA and MMLU-Pro performance approaching leading closed-source models, and creative writing ability nearing Gemini 3.1 Pro.
3/ Frontier-level reasoning performance. ERNIE 5.1 scores 99.6 on the challenging AIME26 benchmark with tools, second only to Gemini 3.1 Pro.
4/ Deep search capability. On May 9, ERNIE 5.1 ranked #4 globally and #1 among Chinese models on the Arena Search leaderboard with a score of 1223.
ERNIE 5.1 is now available on ERNIE and the Baidu AI Studio Model Playground:
👉https://t.co/qhd67Lg3B4
👉https://t.co/AaQSqDmVGU
👉https://t.co/uCNiypIu1q