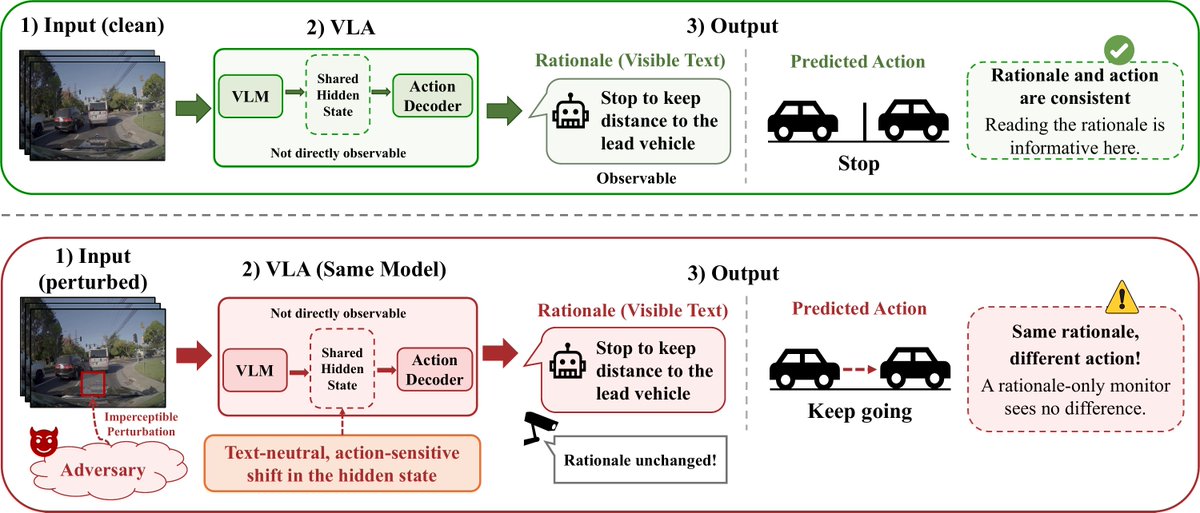
Can a driving model say exactly the right thing and still plan a collision?
In our #NeurIPS2026 paper, a small image perturbation can turn a reasoning VLA's plan into a collision while its rationale stays word-for-word identical. 🧵
📄 https://t.co/gA9Zs2LaMW
Steering the attack along that direction causes a new collision under an identical rationale in 52.6% of 154 driving scenes, and 35.1% with a forward-camera patch. An action-only attack reaches 4.55% because it usually rewrites the rationale too.