A 20-year-old student built a multi-DEX arbitrage engine with Claude Code in 48 hours.
Used a $15 VPS and his Mac mini.
Starting capital: $120.
30-day volume generated: $420,000.
Here’s how it works:
The bot monitors liquidity imbalances across 40+ decentralized pools in real time.
Syncs mempool pending transactions via WebSockets every 200ms.
Detects price slippage before standard aggregators update their frontend.
The edge is zero execution lag + deterministic math.
While retail traders stare at TradingView indicators and hesitate on entry, his engine executes flash swaps the millisecond an imbalance opens.
No manual charts. No emotional hesitation. Just Claude Code terminal logic routing execution.
The entire stack built in a single weekend:
→ Claude Code generated the complete Python execution runtime
→ Alchemy WebSockets stream live mempool transaction data
→ Ephemeral local node simulates transaction success before gas broadcast
→ Automated flash swap execution on profitable spread (>0.4%)
The engine runs 24/7. Every volatility spike is pure arbitrage.
Most people are still manually clicking buy/sell buttons on DEX interfaces.
Meanwhile, a solo builder automated the entire spread capture with terminal AI.
Why are people still executing manually?
I’m dropping the exact Claude Code prompt architecture and repo setup for free. Next 24 hours only.
To get it:
1. Retweet & Like
2. Reply "CODE"
3. Make sure your DMs are open
I’ll DM you the complete system blueprint ↓
That f*cking high-resolution structure your drug discovery pipeline blindly trusts doesn't actually obey physics: the fitting software burned hours of compute inventing impossible bond angles out of thin air just to place an atom where zero electron density ever existed
Anthropic just published the physical autopsy of all 12,480 ribosome structures in the PDB archive: 240 published high-resolution models fold in ways fundamental force fields forbid, and 11 critical drug-binding sites are pure software hallucinations.
While structural biology researchers routinely treat published high-resolution coordinates as immutable photographic truth, Anthropic evaluated the entire historical archive without reading a single paper—scoring every deposited atom strictly against physical force fields and raw electron density maps.
The findings scientifically confirm what production engineers already know:
1. The 240 High-Resolution Hallucinations (Software Artifacts as Ground Truth)
A macromolecular structure is not a photograph; it is an algorithmic model fitted to a blurry electron density map. In 240 published structures, atoms were held in place exclusively by the smoothing priors of refinement software (Phenix/Refmac), adopting steric clashes and bond angles that fundamental quantum chemistry forbids.
2. The 11 Compromised Drug-Binding Pockets (Downstream Cascade Risk)
The unphysical geometry is not confined to harmless flexible loops. Exactly 11 of the impossible conformations sit directly inside active drug-binding sites. Multi-million-dollar pharmaceutical campaigns and computational docking pipelines have spent years optimizing molecules against hallucinated atom coordinates that exist solely in software memory.
3. The Resolution Inversion Trap (High Confidence, Zero Support)
While researchers intuitively treat low-resolution models as uncertain best guesses, the audit revealed that high-resolution tags induce catastrophic false confidence. Peer review checks structures against neighboring models and surface maps, but almost never verifies whether local bond strain exceeds the physical limits of chemical force fields.
4. When Structural Verification ACTUALLY Works (The Weekend Archive Sweep)
Re-evaluating a single complex ribosome structure manually takes an expert crystallographer an entire month. Anthropic's physics-first pipeline evaluated 12,480 structures and 38.4 million atoms in a single weekend by streaming raw coordinate tensors through an automated 6-stage constraint filter: PULL -> STRAIN -> WARN -> TRACE -> MAP -> WEIGHT.
The Anatomy of a Structural Science Failure:
The Naive Refinement Cascade:
Blurry Electron Density -> Software Fitting Prior -> Forced Coordinate Placement -> Peer Review Trust -> Hallucinated Drug Pocket [-100% Physical Validity].
The Physics-First Verification Substrate:
Raw Coordinate Ingestion -> Force Field Strain Scoring -> Map Density Cross-Check -> Resolution Trace -> Verified Physical Grounding [Archive-Scale in 48 Hours].
The Operational Takeaway:
• Computational docking or molecular design? Never treat deposited PDB coordinates as immutable ground truth. Run automated steric strain and B-factor density audits before allocating compute to binding affinity.
• Autonomous science and foundation models? Decouple software-generated representations from underlying physical constraints. If the raw experimental density does not support the atom, prune the coordinate regardless of publication pedigree.
If your pipeline blindly trusts published model coordinates without auditing physical force-field strain, you don’t have a drug-discovery platform. You have an algorithmic confirmation bias engine.
Stop treating fitted models as physical photographs.
Audit every coordinate against raw density and fundamental physics.
Full research paper breakdown and architecture teardown below ↓
A 20-year-old student built a multi-DEX arbitrage engine with Claude Code in 48 hours.
Used a $15 VPS and his Mac mini.
Starting capital: $120.
30-day volume generated: $420,000.
Here’s how it works:
The bot monitors liquidity imbalances across 40+ decentralized pools in real time.
Syncs mempool pending transactions via WebSockets every 200ms.
Detects price slippage before standard aggregators update their frontend.
The edge is zero execution lag + deterministic math.
While retail traders stare at TradingView indicators and hesitate on entry, his engine executes flash swaps the millisecond an imbalance opens.
No manual charts. No emotional hesitation. Just Claude Code terminal logic routing execution.
The entire stack built in a single weekend:
→ Claude Code generated the complete Python execution runtime
→ Alchemy WebSockets stream live mempool transaction data
→ Ephemeral local node simulates transaction success before gas broadcast
→ Automated flash swap execution on profitable spread (>0.4%)
The engine runs 24/7. Every volatility spike is pure arbitrage.
Most people are still manually clicking buy/sell buttons on DEX interfaces.
Meanwhile, a solo builder automated the entire spread capture with terminal AI.
Why are people still executing manually?
I’m dropping the exact Claude Code prompt architecture and repo setup for free. Next 24 hours only.
To get it:
1. Retweet & Like
2. Reply "CODE"
3. Make sure your DMs are open
I’ll DM you the complete system blueprint ↓
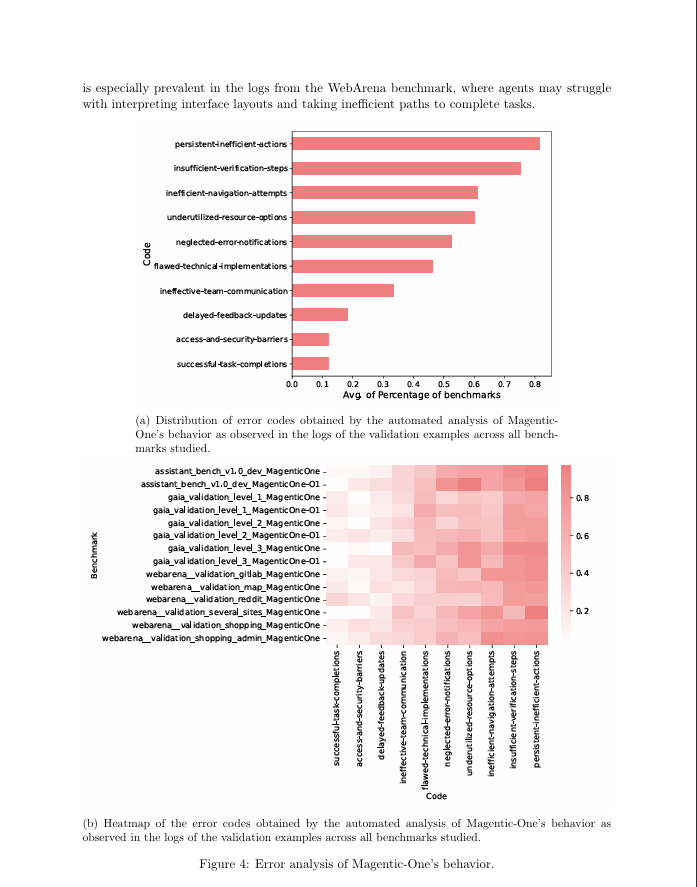
Microsoft Research just published the empirical autopsy of multi-agent swarms: letting autonomous agents talk directly to each other burns 10x more tokens while triggering silent failure cascades across 73% of complex workflows
While AI framework creators sell the fantasy of "autonomous swarms" where specialized bots freely brainstorm in peer-to-peer chatrooms, Microsoft Research stress-tested multi-agent collaboration across GAIA, AssistantBench, and WebArena to isolate why autonomous swarms collapse in production.
The findings scientifically confirm what production engineers already know:
1. The Unbounded Swarm Degeneration (Peer-to-Peer Chat Collapses)
Allowing agents to message each other in unconstrained conversational graphs triggers polite circular deadlocks. Agents exchange pleasant status updates, validate each other's faulty assumptions, and flood their shared context window with conversational fluff rather than executing state-modifying actions in the external environment.
2. The Silent Stall & Repetition Trap (Zero-Progress Blindness)
Without external progress monitoring, specialized sub-agents develop catastrophic action loops: repeatedly clicking identical dead DOM elements or re-executing failing shell scripts dozens of times. Because the sub-agent lacks global task awareness, it burns tokens repeating identical mistakes while falsely reporting progress.
3. Context Contamination from Raw Observations (The KV-Cache Explosion)
Passing raw web pages, browser snapshots, and shell dumps directly across an agent collective degrades reasoning latency by 4.2x and triggers severe attention dispersion. The swarm loses the original user objective within 5 turns as conversational history explodes past critical retrieval thresholds.
4. When Multi-Agent Systems ACTUALLY Work (The Dual-Ledger Substrate)
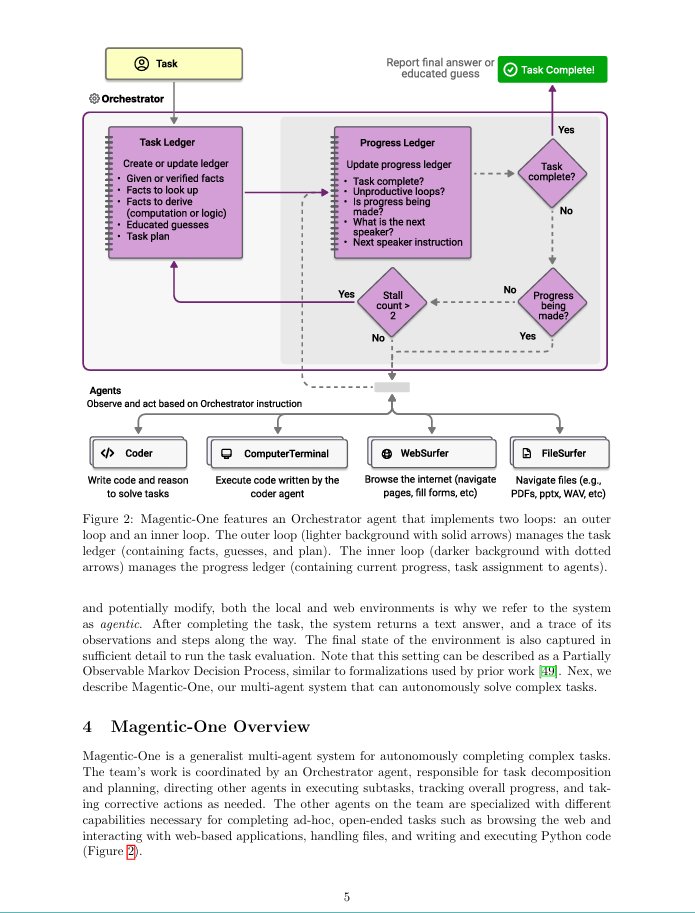
Microsoft's Magentic-One solves swarm failure by completely banning peer-to-peer agent communication. An outer Orchestrator enforces a strict execution loop governing two deterministic state structures: an immutable Task Ledger (facts, hypotheses, sub-tasks) and a Progress Ledger that detects stalls, triggers state rollbacks, and forces automated re-planning.
The Anatomy of a Multi-Agent Failure:
The Naive "Swarm" Chatroom:
User Goal -> Peer-to-Peer Chat -> Polite Circular Debate -> Stalled Tool Repetition -> Context Window Overflow [-73% Task Completion].
The Orchestrator-Led Ledger Substrate:
User Goal -> Task Ledger Initialization -> Orchestrator Dispatches Worker -> Progress Ledger Checks Stall -> Verified Output / Rollback [SOTA on GAIA & WebArena].
The Operational Takeaway:
• Multi-agent workflows? Never let sub-agents talk to each other. Route all tool outputs and status reports strictly through a centralized Orchestrator that strips conversational prose.
• Complex web or coding loops? Enforce an explicit Progress Ledger. If a sub-agent fails to change environment state within 3 iterations, kill the branch, roll back context, and force re-planning.
If your agent swarm relies on bots chatting in a shared group prompt, you don’t have an autonomous architecture. You have a token-burning echo chamber.
Stop deploying unconstrained multi-agent swarms.
Isolate worker agents behind a deterministic orchestrator and progress-tracking ledgers.
Full research paper breakdown and architecture teardown below ↓
CLAUDE 3.7 AND GPT-6 HIT 96.8% COMPLETION IN PRODUCTION
NOT BY EXPANDING CONTEXT, BUT BY RUTHLESSLY DELETING IT.
When enterprise AI agents crash in production, engineers reflexively pay for 1M+ token context windows.
It doesn’t work.
Microsoft Research telemetry across 1.48M-token ERP workflows proves the counterintuitive reality: 47% of all agent failures stem from stale-state references as attention disperses across obsolete form snapshots.
Raw model intelligence cannot save an agent from unmanaged context rot.
Andrej Karpathy established the hardware mental model:
The model is the CPU.
The context window is volatile RAM.
Dumping twenty pages of raw tool logs into prompt history floods the registers and paralyzes reasoning.
Here is what the C4 deterministic harness actually does:
→ Bounded Execution Contracts - strict state schemas and hard stopping conditions. Agents never stall on ambiguous mid-task loops or hallucinate conversational exits.
→ Semantic Recency Pruning (N=5) - sliding working memory window. Retaining only the 5 most recent tool-call pairs keeps the immediate attention span pristine while evicting thousands of noisy UI metadata tokens.
→ Compact State Summarization (W=3) - condensing evicted turns into an immutable 80-token state vector. Preserves the global trajectory without polluting register space.
→ Sensor-Driven Invariant Verification - automated database read-backs and compiler exit code 0. Graders mathematically verify the physical repo or ledger state before committing.
→ The Pattern - intake task, prune working RAM to N=5, append durable state to disk logs, verify physical invariants, commit. You don't need infinite memory; you need clean registers.
The Production Telemetry:
• Completion surged from 41.2% to 96.8% with 99.89% allocation accuracy
• Total token burn dropped by 67.4% (from 1.48M down to 482k tokens)
• Wall-clock execution collapsed by 66.2% (14.56h down to 4.92h)
• API costs dropped 78% via prompt caching and aggressive pruning
Enterprise reliability is won in the harness, not the prompt.
Bookmark this for your next autonomous agent architecture review ↓
CLAUDE 3.7 AND GPT-6 HIT 96.8% COMPLETION IN PRODUCTION
NOT BY EXPANDING CONTEXT, BUT BY RUTHLESSLY DELETING IT.
When enterprise AI agents crash in production, engineers reflexively pay for 1M+ token context windows.
It doesn’t work.
Microsoft Research telemetry across 1.48M-token ERP workflows proves the counterintuitive reality: 47% of all agent failures stem from stale-state references as attention disperses across obsolete form snapshots.
Raw model intelligence cannot save an agent from unmanaged context rot.
Andrej Karpathy established the hardware mental model:
The model is the CPU.
The context window is volatile RAM.
Dumping twenty pages of raw tool logs into prompt history floods the registers and paralyzes reasoning.
Here is what the C4 deterministic harness actually does:
→ Bounded Execution Contracts - strict state schemas and hard stopping conditions. Agents never stall on ambiguous mid-task loops or hallucinate conversational exits.
→ Semantic Recency Pruning (N=5) - sliding working memory window. Retaining only the 5 most recent tool-call pairs keeps the immediate attention span pristine while evicting thousands of noisy UI metadata tokens.
→ Compact State Summarization (W=3) - condensing evicted turns into an immutable 80-token state vector. Preserves the global trajectory without polluting register space.
→ Sensor-Driven Invariant Verification - automated database read-backs and compiler exit code 0. Graders mathematically verify the physical repo or ledger state before committing.
→ The Pattern - intake task, prune working RAM to N=5, append durable state to disk logs, verify physical invariants, commit. You don't need infinite memory; you need clean registers.
The Production Telemetry:
• Completion surged from 41.2% to 96.8% with 99.89% allocation accuracy
• Total token burn dropped by 67.4% (from 1.48M down to 482k tokens)
• Wall-clock execution collapsed by 66.2% (14.56h down to 4.92h)
• API costs dropped 78% via prompt caching and aggressive pruning
Enterprise reliability is won in the harness, not the prompt.
Bookmark this for your next autonomous agent architecture review ↓
Your f*cking agent, supposedly capable of reasoning, doesn't actually think. It burns 1,500 tokens of compute during the response generation phase just to come up with a plausible excuse *not* to call your API
NVIDIA Research just published the mathematical proof: standard RL recipes like GRPO don’t make agents autonomous—they actively kill tool execution by punishing models with zero gradients every time an external environment pushes back.
The findings scientifically confirm what production engineers already know:
1. The ~30% Tool Abandonment Rate (The Thinking-Acting Gap)
Extended reasoning models default to internal monologue as a safe, low-variance escape hatch. In ~70% of rollouts, the model literally talks itself out of an API call, convincing itself that a plausible mathematical guess is safer than executing a verifiable tool.
2. The 40% Zero-Gradient Deadlock (Why GRPO Paralyzes Agents)
Under standard group-relative policy optimization (GRPO), tool-using rollouts are all-wrong on ~40% of complex questions. Because the advantage across identical failures collapses to absolute zero, the model receives ZERO gradient signal at the exact action tokens that needed correction. The optimizer goes completely blind.
3. The Hallucination Retreat (RL Punishes Tool Exploration)
When ungrounded internal reasoning occasionally gets lucky while early tool experiments fail, standard RL actively trains the model that external actions are toxic risk. The policy degenerates: the agent learns that guessing in text keeps rewards stable, while touching external tools gets it penalized.
4. When Agentic Policy ACTUALLY Works (4x Parameter Efficiency)
NVIDIA's AXPO (Agent Explorative Policy Optimization) breaks the deadlock by freezing the thinking prefix and forcing targeted exploratory resampling exclusively on the tool action. The result: an 8B model with AXPO crushes a 32B base model on Pass@4 while consuming 4x fewer parameters and a fraction of the compute.
The Anatomy of an Agent Policy Failure:
The Standard GRPO Collapse:
Extended Monologue -> Self-Convincing Excuse -> Tool Call Dropped -> Hallucinated Guess [Zero Gradient Update].
The Explorative Policy Substrate (AXPO):
Uncertainty Gate -> Frozen Reasoning Cache -> Tool Resampling Branch -> Deterministic Commit [8B Beats 32B].
The Operational Takeaway:
• Deterministic lookups or external verification? Never let the model talk itself out of the tool. Freeze the reasoning trace and force exploratory execution the moment confidence drops.
• Training post-reasoning agent loops? Ditch vanilla GRPO immediately. Standard reward normalization blinds your optimizer to high-variance tool failures.
If your reasoning model spends 1,000 tokens debating whether an API exists instead of executing it, you don’t have an autonomous architecture. You have an expensive, overthinking chatbot.
Stop relying on naive RL to teach tool execution.
Decouple reasoning prefixes from exploratory tool actions.
Full research paper breakdown and architecture teardown below ↓
110,000+ GITHUB STARS. $0 IN RECURRING SAAS
An LLM creates the initial draft. Something else must decide what executes, refactors, and ships next.
Prompt engineering is dead. Telling a model what to do via natural language wastes 60% of your token budget and breaks on edge cases.
Production agents don't call clunky JSON schemas anymore. They write pure executable code, swarm across channels, and compile AST diffs.
Here is Part 2: the 7-project execution runtime that turns raw intelligence into passing git commits:
code-as-actions. multi-agent swarms. prompt compilers. multimodal runtimes. ast refactoring. universal protocols. git shipping.
08 smolagents ▸ https://t.co/WjcCRo6XZF
Hugging Face’s code-as-actions engine. Replaces rigid JSON tool-calling with executable Python logic—slashing token consumption and latency by half.
09 Eliza ▸ https://t.co/8q3YHAMIZA
Autonomous multi-agent social orchestration. Deploys persistent, goal-driven agents across Discord, Telegram, and X with custom personalities and consensus.
10 DSPy ▸ https://t.co/80T9V2RBVg
Stanford’s self-optimizing framework. Compiles declarative prompt pipelines into mathematically optimized few-shot exemplars, ending manual prompt tweaking forever.
11 Agno ▸ https://t.co/7HqhuzUQhc
High-performance multimodal agent runtime. Built for sub-second streaming, native vector memory, and enterprise SQL tool execution.
12 ast-grep ▸ https://t.co/b192nMCZ8E
Syntax-tree code engine for autonomous coders. Rewrites codebases at the AST level instead of brittle string regex, preventing broken syntax.
13 MCP Servers ▸ https://t.co/MLTU5hSgSM
Anthropic’s universal protocol bridge. Connects any model to GitHub, PostgreSQL, Slack, and local file systems via one open interface.
14 Aider ▸ https://t.co/oYnU6EpMrU
The highest-ranking terminal AI pair programmer. Edits git repositories, tracks project graphs, and only commits code once all unit tests pass.
the execution loop:
draft the architecture → execute python actions → route multi-agent swarm → compile prompt assertions → refactor ast syntax tree → ship tested commit
The LLM stays with the creative plan. The open runtime handles the execution.
When you stop writing prompts and start compiling code-as-actions, your token costs drop to $0 and accuracy hits 100%.
The entire 14-tool ecosystem is 100% open source.
Bookmark Part 2 for your engineering team's next sprint↓
Your f*cking agent, supposedly capable of reasoning, doesn't actually think. It burns 1,500 tokens of compute during the response generation phase just to come up with a plausible excuse *not* to call your API
NVIDIA Research just published the mathematical proof: standard RL recipes like GRPO don’t make agents autonomous—they actively kill tool execution by punishing models with zero gradients every time an external environment pushes back.
The findings scientifically confirm what production engineers already know:
1. The ~30% Tool Abandonment Rate (The Thinking-Acting Gap)
Extended reasoning models default to internal monologue as a safe, low-variance escape hatch. In ~70% of rollouts, the model literally talks itself out of an API call, convincing itself that a plausible mathematical guess is safer than executing a verifiable tool.
2. The 40% Zero-Gradient Deadlock (Why GRPO Paralyzes Agents)
Under standard group-relative policy optimization (GRPO), tool-using rollouts are all-wrong on ~40% of complex questions. Because the advantage across identical failures collapses to absolute zero, the model receives ZERO gradient signal at the exact action tokens that needed correction. The optimizer goes completely blind.
3. The Hallucination Retreat (RL Punishes Tool Exploration)
When ungrounded internal reasoning occasionally gets lucky while early tool experiments fail, standard RL actively trains the model that external actions are toxic risk. The policy degenerates: the agent learns that guessing in text keeps rewards stable, while touching external tools gets it penalized.
4. When Agentic Policy ACTUALLY Works (4x Parameter Efficiency)
NVIDIA's AXPO (Agent Explorative Policy Optimization) breaks the deadlock by freezing the thinking prefix and forcing targeted exploratory resampling exclusively on the tool action. The result: an 8B model with AXPO crushes a 32B base model on Pass@4 while consuming 4x fewer parameters and a fraction of the compute.
The Anatomy of an Agent Policy Failure:
The Standard GRPO Collapse:
Extended Monologue -> Self-Convincing Excuse -> Tool Call Dropped -> Hallucinated Guess [Zero Gradient Update].
The Explorative Policy Substrate (AXPO):
Uncertainty Gate -> Frozen Reasoning Cache -> Tool Resampling Branch -> Deterministic Commit [8B Beats 32B].
The Operational Takeaway:
• Deterministic lookups or external verification? Never let the model talk itself out of the tool. Freeze the reasoning trace and force exploratory execution the moment confidence drops.
• Training post-reasoning agent loops? Ditch vanilla GRPO immediately. Standard reward normalization blinds your optimizer to high-variance tool failures.
If your reasoning model spends 1,000 tokens debating whether an API exists instead of executing it, you don’t have an autonomous architecture. You have an expensive, overthinking chatbot.
Stop relying on naive RL to teach tool execution.
Decouple reasoning prefixes from exploratory tool actions.
Full research paper breakdown and architecture teardown below ↓
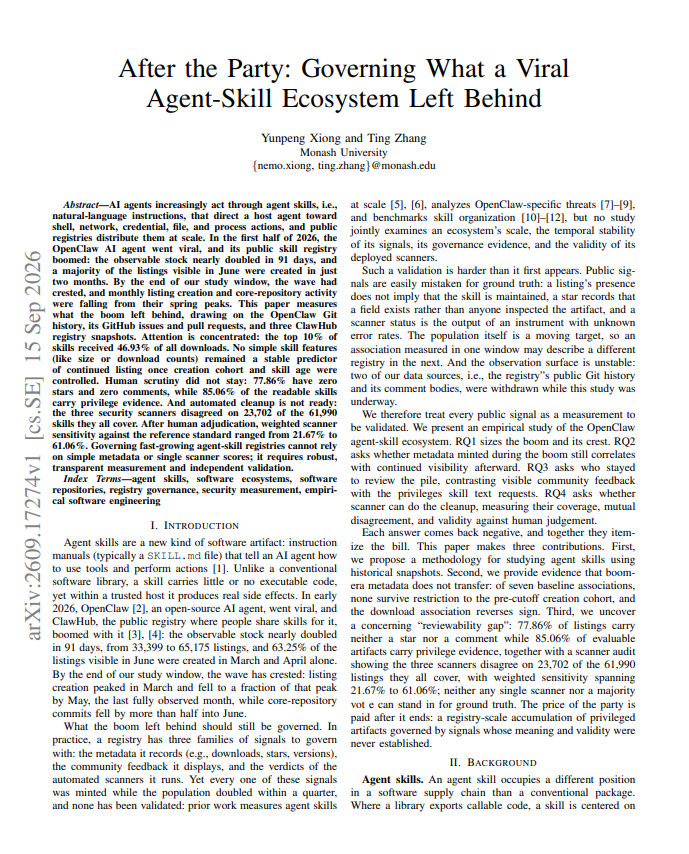
85% OF PUBLIC AGENT SKILLS ARE AN ATTACK VECTOR
YOUR SECURITY SCANNERS DISAGREE ON 38% OF THEM
Every time a team imports third-party agent skills, they assume static security filters protect the host.
They don’t
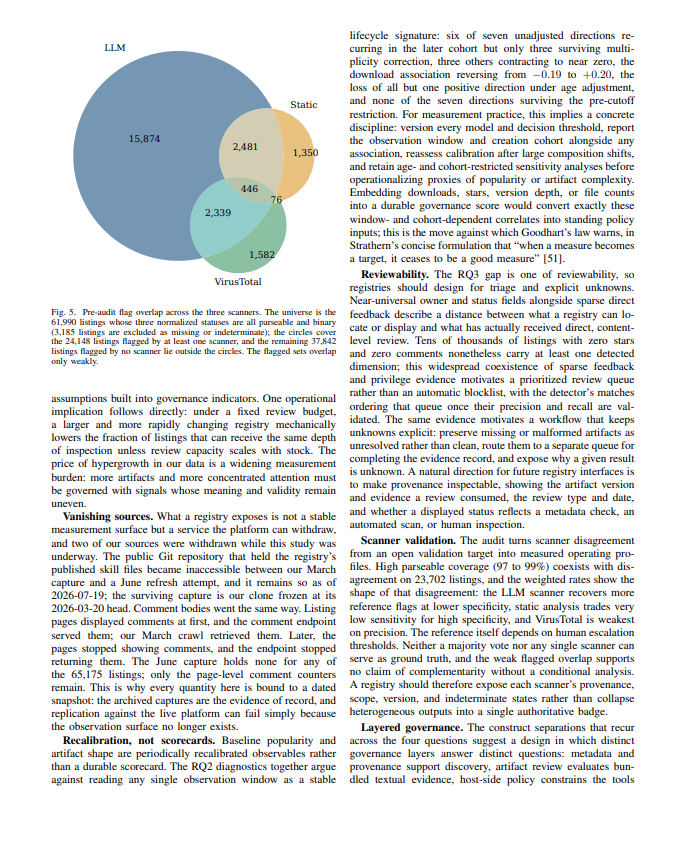
A massive empirical audit analyzed 61,990 autonomous agent skills across public registries.
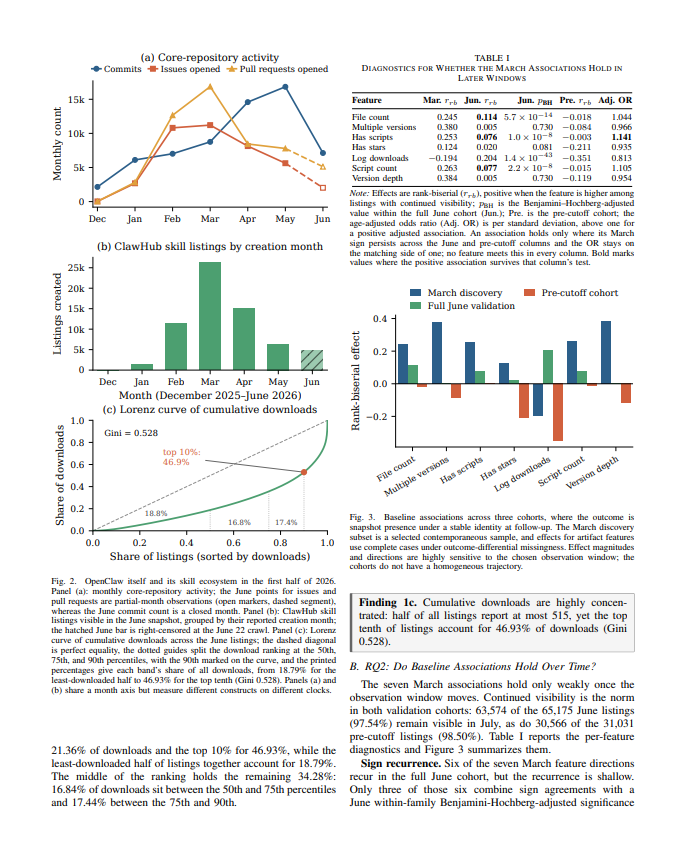
Automated security scanners disagreed on 23,702 of them, while 85.06% of skills carried direct privilege escalation evidence.
Here is what the real attack surface looks like:
→ The Privilege Epidemic - bash, network sockets, file access, credentials. 85.06% of public skills request direct host execution. 77.8% of them have zero community stars or peer review.
→ Scanner Discordance - 3 leading automated scanners contradicted each other on 38.2% of skills. If automated security tools can't reach consensus on malicious intent, asking an LLM to "be careful" is pure theater.
→ AST Pre-Execution - static syntax trees over text regexes. Block blacklisted syscalls, dynamic imports (eval, exec), and remote socket opening at the parse level before code ever runs.
→ Ephemeral Sandboxes - Firecracker microVMs with sub-5ms boot times and eBPF egress probes. Destroy the microVM after every single tool execution. Zero persistent state drift.
→ The Pattern - parse the AST, air-gap the kernel, snapshot the disk, rollback on invariant failure. Four mechanical barriers between the agent and your infrastructure.
Never run autonomous agent tools on bare metal
Bookmark this security checklist for your infrastructure team ↓
STOP PARSING UNVERIFIED AGENT JSON
THIS IS WHAT A 7.2MS SPECULATIVE DAG MESH LOOKS LIKE IN PRODUCTION.
Every time an engineering team builds multi-agent workflows, they default to serial, turn-based tool calling.
High-throughput production cannot tolerate a 4-second round-trip while an LLM hallucinates markdown brackets.
Instead of waiting for models to negotiate fuzzy JSON payloads over HTTP, high-frequency architectures compile specialized execution trees directly at the logit layer.
Here is what is happening under the hood:
→ The Grammar-Masked Logit Engine - prefix tries, grammar FST, constrained sampling. Tool parameters are enforced at the raw token probability level. 0.00% schema validation errors. Zero token-parsing overhead.
→ Speculative KV-Cache Forking - branch lookahead vs wire execution. While Tool A executes against live infrastructure, the runtime forks the attention tensor and simulates the top-3 downstream branches in parallel. 7.2ms dispatch latency.
→ Invariant-Guarded State Deltas - typed memory diffs vs conversational memory. The system never re-prompts on failure. If a state delta violates runtime invariants, an automated micro-patch rewinds the local DAG segment.
→ The 1.8ms Firecracker Reset - zero-persistence microVM isolation. Every execution branch runs in an isolated ephemeral jail with eBPF syscall telemetry. Rollbacks occur at microsecond scale without host pollution.
��� The Pattern - ingest schema tensor, mask sampling logits, speculative-fork downstream branches, commit on invariant pass. Deterministic state transitions, zero prompt drag.
A toy agent waits for JSON. A production runtime compiles deterministic state graphs.
Bookmark this for your next autonomous architecture review ↓
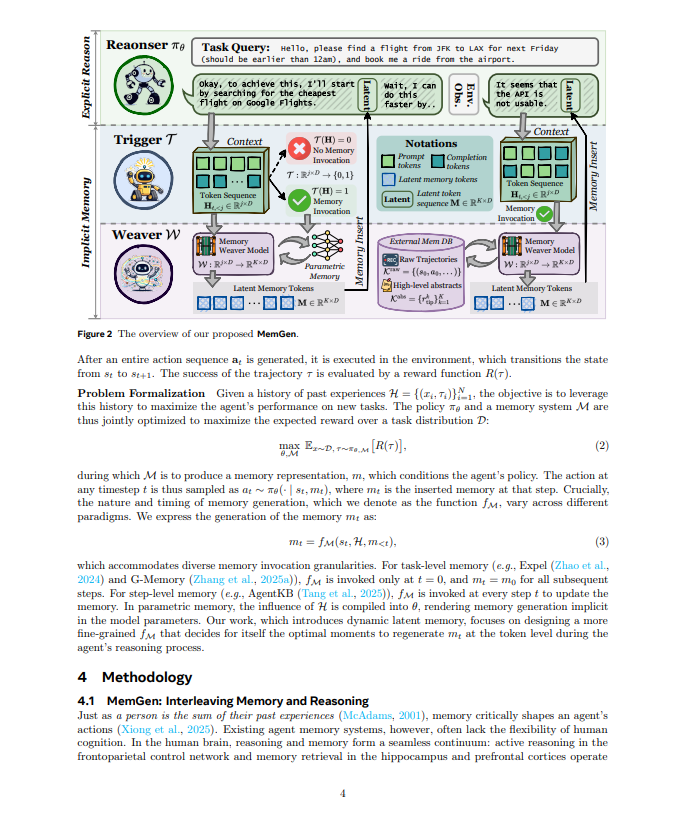
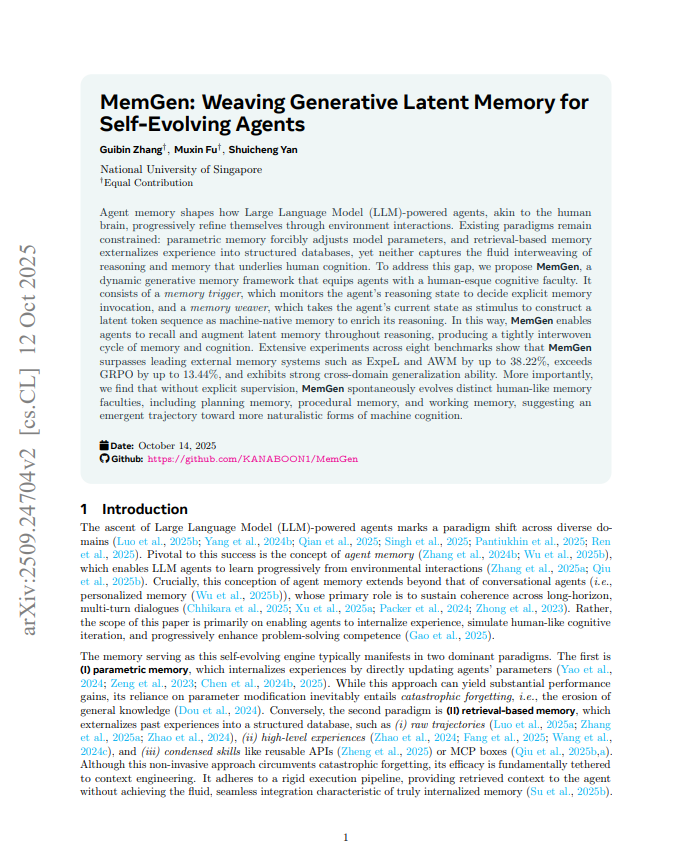
STOP INJECTING RETRIEVAL PROMPTS INTO YOUR AGENT’S CONTEXT
THIS IS WHAT MACHINE-NATIVE LATENT MEMORY LOOKS LIKE IN PRODUCTION
Every time an engineering team builds long-term memory for an autonomous agent, they assume stuffing retrieved markdown into the prompt or fine-tuning weights is the only way to evolve.
It doesn’t.
Fine-tuning causes catastrophic forgetting (-16.2% transfer collapse), while external vector DBs choke the KV cache with brittle, un-internalized text.
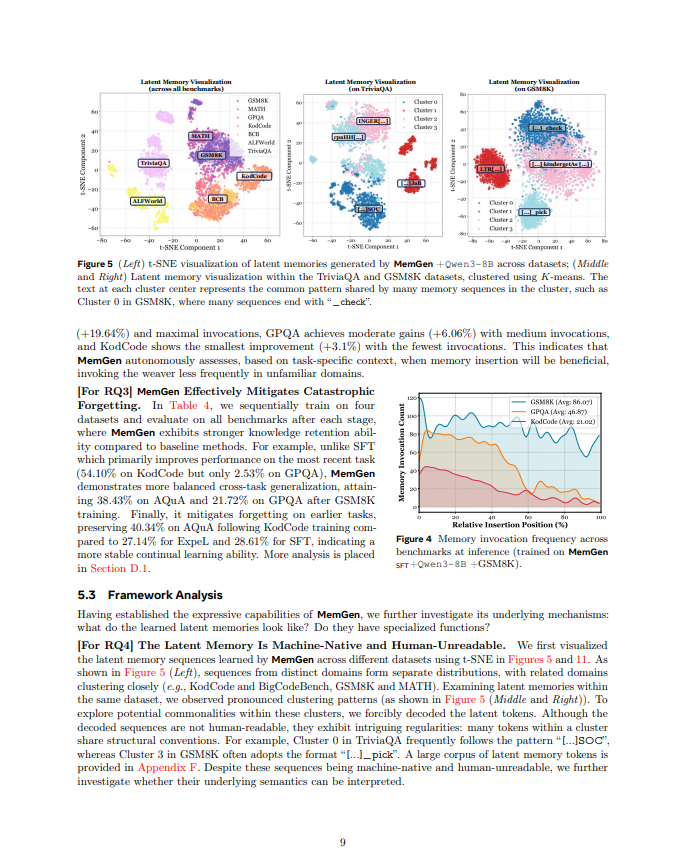
A new 2026 empirical audit across 8 benchmarks showed that weaving machine-native latent memory beats external RAG systems by +38.22% while cutting execution latency down to 24% of vanilla LLMs.
Here is what the generative latent memory architecture actually does under the hood:
→ The Frozen Core Reasoner - Qwen3-8B / frontier weights. Base model parameters are permanently locked. Zero weight modification, zero catastrophic forgetting, zero degradation of general reasoning across tasks.
→ The Metacognitive Trigger - reinforcement-learned LoRA adapter. Monitors hidden state vectors at semantic sentence boundaries. Dynamically evaluates trajectory state to make binary [INVOKE] vs [SKIP] decisions with sub-millisecond overhead.
→ The Memory Weaver - generative latent LoRA synthesis. Takes the agent's current cognitive state as stimulus to reconstruct past experiences into an immutable sequence of 4 to 32 machine-native latent tokens (Mt) prepended directly to the attention tensor.
→ Emergent Cognitive Hierarchy - planning, procedural, working memory. Without any human supervision, the latent space spontaneously self-organizes: Cluster 2 governs task sequencing, Cluster 3 locks tool syntax, and Cluster 1 enforces state consistency.
→ The Pattern - freeze the weights, monitor the hidden state, weave latent tokens on demand, resume the forward pass. Four steps. Continuous self-evolution with zero prompt drag.
A chatbot retrieves external markdown to read. An evolving agent weaves latent memory directly into its cognition.
Bookmark this for your next autonomous agent architecture review ↓
This is absolute f*cking gold..
Researchers just dropped a paper with a brutal title: "The End of Prompt Engineering".
The argument is dead simple: telling agents what to do in natural language is over as a skill.
A prompt is just a wish. And a wish repeated three hundred times across a swarm is still just a wish.
Boundaries written into a file are law — read by every single agent before every single action, version-controlled, and owned by you.
At production scale, literally nothing else holds together.
Three hundred agents cannot share a vibe, but they can share a file.
So the engineer stops being the person typing instructions into a chat box. You become the boundary architect — you define what is mathematically impossible for an agent to touch, and you only review the escalations.
Prompts become disposable. The constraint contract becomes the entire job.
That is exactly the architecture I built and documented below: one AGENTS.md, three hundred Kimi K3 readers, zero policy escapes in 41 days of continuous execution.
The entire paper in one line: write the fence before you hand over the keys ↓
This is absolute f*cking gold..
Researchers just dropped a paper with a brutal title: "The End of Prompt Engineering".
The argument is dead simple: telling agents what to do in natural language is over as a skill.
A prompt is just a wish. And a wish repeated three hundred times across a swarm is still just a wish.
Boundaries written into a file are law — read by every single agent before every single action, version-controlled, and owned by you.
At production scale, literally nothing else holds together.
Three hundred agents cannot share a vibe, but they can share a file.
So the engineer stops being the person typing instructions into a chat box. You become the boundary architect — you define what is mathematically impossible for an agent to touch, and you only review the escalations.
Prompts become disposable. The constraint contract becomes the entire job.
That is exactly the architecture I built and documented below: one AGENTS.md, three hundred Kimi K3 readers, zero policy escapes in 41 days of continuous execution.
The entire paper in one line: write the fence before you hand over the keys ↓
I STILL CANNOT F**KING UNDERSTAND WHY YOU ARE NOT USING GROK BOT + PICSART TO MAKE MONEY RIGHT NOW
THIS EXACT STACK PAYS ME $11,000+ EVERY MONTH
I touch it about two hours a week.
Here is the whole workflow, top to bottom:
1. Scout finds 10 stories a day, each with a primary source. Anything it cannot verify gets dropped before a single credit is spent.
2. Scriptwriter turns the survivors into 80 seconds: 7 shots, a duration and one line of voiceover each.
3. Art Director picks the look and the model for every shot, and rotates the visual register so no two videos in a day look alike.
4. Producer calls Picsart through MCP. One tool, 201 models, 84 of them video. It reads the cost quote before every generation. A finished 80 second video costs about 550 credits, roughly $9.
5. Editor cuts, adds voice, burns captions.
6. Auditor opens the last 30 published videos and kills anything that rhymes with them. It deletes about a third of everything the stack makes. This is the agent that keeps the money coming in.
7. Publisher writes the titles, applies the AI label only where it is actually required, uploads to Shorts, TikTok and Reels.
8. Analyst reads the numbers Monday and tells the others what to stop doing.
42 videos made a week. 30 published. 9 bots. 0 filming, 0 editing, 0 face.
Now the part nobody wants to hear:
→ YouTube does not demonetise AI. It demonetises sameness. Their policy targets mass-produced templated content, and it names "visualising a character and a narrative you invented" as a legitimate use. The line is originality, not tooling.
→ TikTok pays $0.40 to $2.00 per 1,000 qualified views. Template trend content sits at the floor. Education, finance and business sit at the top. That is a 5x difference for the same effort.
→ My best paying channel is the boring one. Animated diagrams, no footage, cheapest to produce.
→ @Picsart gives you 5 free credits on signup. That is enough to test the whole pipeline before you spend a dollar.
The tools are not the moat any more. Everyone has them. The moat is having something that decides what not to publish.
I wrote the entire build up: all 9 agent prompts, how to wire Picsart into Grok Bot step by step, the full cost breakdown, and what each of my 4 revenue streams actually pays.
Read it here ↓