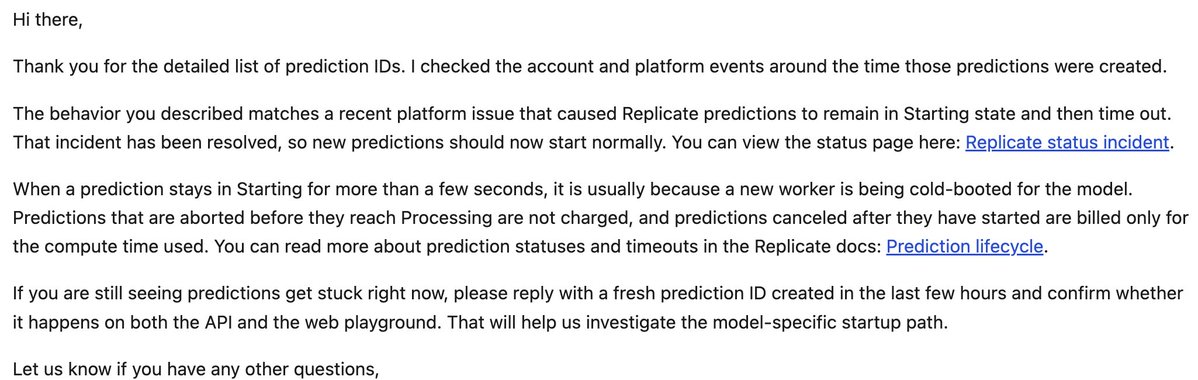
Update from the engine room: Replicate support officially confirmed the platform issue causing predictions to hang indefinitely in the "Starting" state is resolved.
Our inference pipeline for https://t.co/Oag9gfl1Pu is unblocked and back online.
Wrestling with upstream GPU hiccups taught us a crucial lesson: you can't control third-party infrastructure, but you can build a resilient system and an effortless user experience.
Here is what we’re shipping next before our public launch:
1-Click Inference Re-render: If an upstream GPU worker stalls after LoRA training finishes, the customer never has to re-upload photos or wait 20 minutes to retrain. Their AI model weights are preserved, allowing a 1-click instant re-dispatch of all 50 portraits.
Calm, Async-First UX: No raw technical errors, confusing logs, or anxiety-inducing progress bars. Once photos are uploaded, the UI gives one clear message: "Your headshots are being generated. We’ll notify you by email as soon as they're ready to download."
Visual Upload Guidelines: Adding side-by-side visual examples (lighting, angles, expressions) directly into the upload flow to help users submit the best possible training set.
Pre-Flight Face & Blur Detection: Implementing automated pre-screening (face detection, blur analysis, and landmark verification) before images ever hit a GPU. If a photo is blurry, filtered, or has multiple faces, it gets flagged in the browser before compute spend begins.
The core pipeline works, the resilience layer is locked in, and we are dialing in the final UX polish.
We are launching very soon. Let’s fucking go! 🚀⚡
#BuildInPublic #IndieHacker #AI #MachineLearning #GenerativeAI #ReplicateIssueFixed