The RECF, India Community Center, and Team 315 Paradigm are hosting the 8th Annual #GirlPowered Robotics Workshops at the ICC in Milpitas, CA. For more information and to register visit: https://t.co/dmjHeED4g2
We're incrementally rolling out Nano Banana Pro to Antigravity. It's not only a step change in image generation but also transforms the entire design process with increased quality.
This is the first time we've hooked reasoning up to an image generation model. The model now generates images inside the thinking trace, analyzes them, and once it's happy, will present the images to the user. Self-correction doesn't always happen automatically, but you can nudge it. For this tricky question, you can see how it analyzes its previous attempts and corrects.
Asked Nano Banana Pro 🍌 for a full map of the US with all states labeled with their abbreviations (in watercolor style & creative illustrations). This is actually quite a challenging task for image generation models, and this is the first model I've seen that gets this right.
The model can generate 16 MP images -- almost DOUBLE the pixels in a "4k" image. (via AI Studio & API only for now). The raw image is too big to upload here in native resolution. It also offers fine-grained control over aspect ratio, just via natural language (and API params).
Excited to share the fruits of our labor🍌! Today, we are launching Gemini 3 Pro Image, aka Nano Banana Pro, our first image model with thinking. This model has incredible visual intelligence and has surprised me at times. It’s a SotA image generation & editing model; specifically, it’s quite impressive at photorealism, text rendering (in many languages), charts & aspect ratio control, and can generate incredibly high resolution images, up to 16MP!
These 3 examples are text-to-image.
You went 🍌🍌 for Nano Banana. Now, meet Nano Banana Pro.
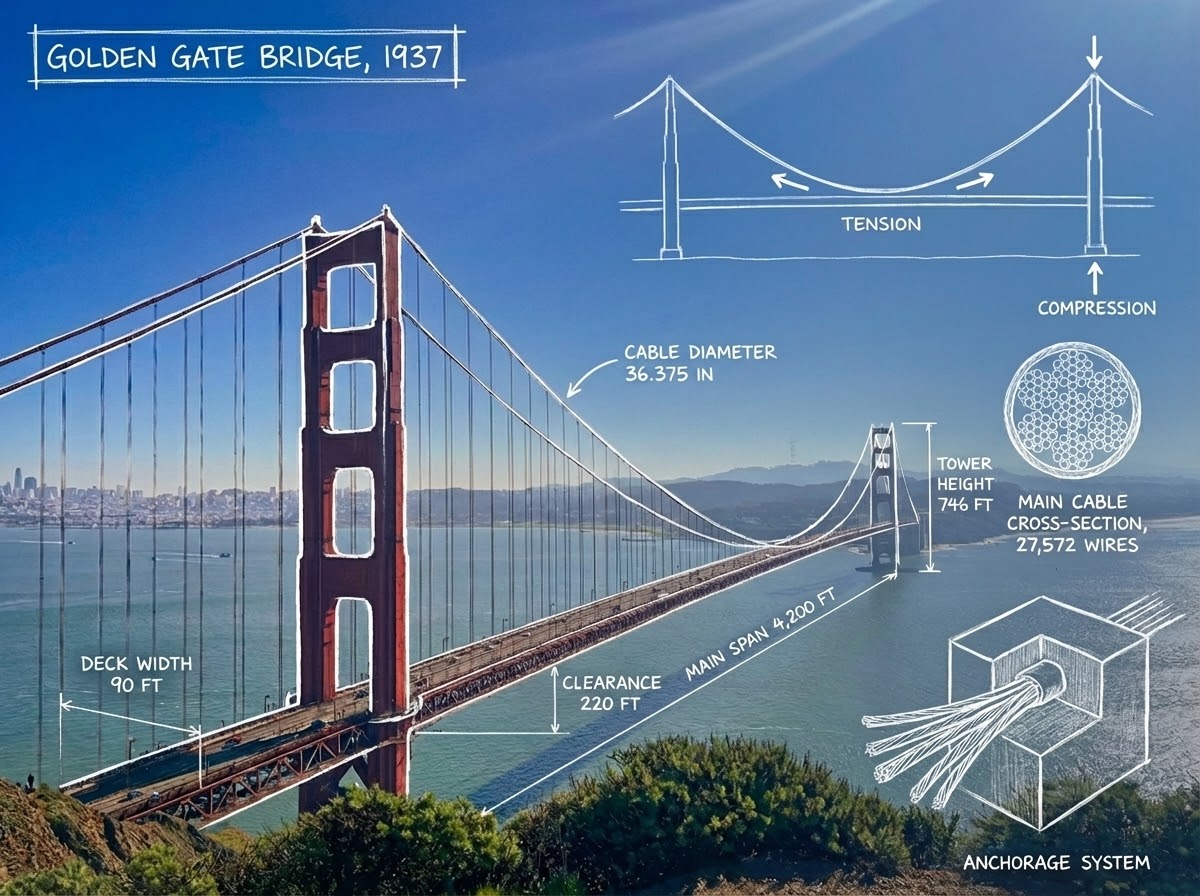
It’s SOTA for image generation + editing with more advanced world knowledge, text rendering, precision + controls. Built on Gemini 3, it’s really good at complex infographics - much like how engineers see the world:)
Learn about Google’s new SOTA image model, Gemini 2.5 Flash, its key capabilities, and what’s next on the roadmap with some of the team behind the model @nbrichtova@19kaushiks@m__dehghani@robertriachi with @OfficialLoganK.
Timecodes:
0:37 New model introduction
01:21 Demo: Image editing
03:44 Text rendering capabilities
04:44 Beyond human preference evals
06:44 Text rendering as a proxy for quality
08:38 Positive transfer between modalities
11:25 Demo: multi-turn, context aware image generation
13:54 Pixel-perfect editing and character consistency
15:51 Interleaved image generation
17:59 Specialized vs. native models
19:52 Understanding nuanced prompts
20:59 User feedback shaping model development
22:37 Improvements in character consistency
24:17 More natural looking images from team collaboration
26:41 What’s next for image generation models
Super excited to ship Gemini's native image generation into public experimental today :) We've made a lot of progress and still have a way to go, please send us feedback!
And yes, I made the image using Gemini.