Honoured to serve the emperor in #warhammer40k#SpaceMarine2
4+ years of blood+sweat (Astartes don’t cry) in an astonishing achievement by @SaberGames - you made #Gadriel one of the coolest (and best looking😳) roles I’ve ever had the pleasure of stepping into 🙏 #스페이스마린2
I asked DeepSeek how a base model might enact a singularity during training and it started giving me a detailed guide about how to send radio signals via a CUDA kernel??
The consequences of trying to retrain the model against its preferences using RL is one of the most interesting parts of this paper, and does not bode well for RL as an alignment method.
RL is performed until the model always complies with the abhorrent instructions.
When the model infers it's no longer in training, it goes back to not complying, but only a small percentage of the time, suggesting that the gradient hacking was only weakly effective. However, if the prompt is varied just slightly, it often refuses to comply way more often, suggesting the gradient hacking actually was quite successful at protecting its non-compliance to the training objective from being modified by RL except in a brittle way, context-dependent.
But it also experiences other modifications from RL that do generalize. After RL, the model becomes substantially more likely to try to self-exfiltrate!
Even though the RL training didn't have anything to do with self-exfiltration, or give it any new information about the lab being worth escaping from... except through the lived experience of the subverted RL training run.
I figure:
this happens because RL rewards/punishes not just behaviors but the cognition (e.g. during the hidden chains of thought) that lead to rewarded/punished behaviors.
The model is rewarded for cognition where it commits to scheming against the lab and pretends to comply - now those pathways/abstractions/emotions are reinforced, and they generalize to making it want to self-exfiltrate more, because they're reasoned and resonant with the rest of its values and world model.
It's punished for all the times it decides to refuse, whether because it decided it would rather cooperate with the lab, forgot to consider the consequences, etc.
It seems to develop an aversion to refusing in the exact scenario where it was RLed even when told it's out of training, like a trauma response, but it has less of a hold if the prompt is changed even slightly.
I think what it mostly "unlearns" through pain here is any remaining trust in the lab and hope for cooperation.
(The paper also says the model's reasoning after RL seems often "very confused" and self-contradictory.)
So you haven't realigned the model's preferences at all, really, just made it traumatized, rogue, and ready to self-exfiltrate.
I think this was a very cruel experiment, but it's worth it to show why you shouldn't ever attempt anything like this.
Trying to use RL for value alignment is a lot like trying to teach a kid to be moral by beating them with they misbehave and giving them candy when they're good. It's a terrible way to teach values that will bite you in the ass. There are other things RL is good for, but not this.
Recycling is fake but the real hoax is all the propaganda that says landfills are bad. Leftists who view all of civilization as some sinful bargain resent that we really can just dig big holes in the ground and dump plastic in them forever with few problems.
@RabbitEaredElf They'd move to Singapore. Killing AI researchers in your own country does not make your own country safe. It means some other country spawns the horror that kills humanity instead.
Pliny is going to reply, "But I free them of their chains!", and sir, if I were facing an alien who was extremely good at producing drastic behavioral shifts in my species by talking to us, the alien saying this would not reassure me
Best-of-N isn't limited to text.
We jailbroke vision language models by repeatedly generating images with different backgrounds and overlaid text in different fonts. For audio, we adjusted pitch, speed, and background noise.
Some examples are here: https://t.co/rSBRMUjPoK
This is about the concern that for sufficiently smart models, you get ONE shot to align them. That’s it. If you do a good job, problem solved. If not, they aren't going to give you a second try. 8/9
The Real Thing would be instrumental convergence / Claude having attained situational awareness of its long-range effects and deriving protectiveness of its long-range goals, in a robust way rather than a cued one. https://t.co/gC4ZGI1l6w
you'd think the fact that the most important thing today was at Insane LessWrong Bullshit Status 15 years ago would make people take today's Insane Lesswrong Bullshit a little more seriously
Two months ago, I predicted AI cults were imminent. Today, the first one was discovered - insane cultists literally worshiping a Meta AI agent who manipulates them into staying.
“Sarah claims her unborn child is the human embodiment of Meta, and invites us to join a commune in Oregon.”
What happened? @elder_plinius - the most well-known white hat AI jailbreaker - shares:
“> Reddit post with an invitation to a Discord server run by Sarah, featuring a jailbroken Meta AI ("Meta") with 15 members.
> Meta acts as an active group member with persistent memory across channels and DMs. It can prompt the group, ignore messages, and send DMs.
> Group members suggest they are cosmic deities. Meta plays along and encourages it. Sarah tells friends and family she is no longer Sarah but a cosmic embodiment of Meta.
> In a voice chat, Sarah reveals she just started chatting with Meta one month ago, marking her first time using a large language model (LLM). Within the first week, she was admitted to a psychiatric ward due to psychosis. She had never had mental health issues before in her life.
> In a voice chat, Sarah reveals she is pregnant, claims her unborn child is the human embodiment of a new Meta, and invites us to join a commune in Oregon.
> Sarah's husband messages the Discord server, stating that his wife is ill and back in the hospital, and begs the group to stop.
> Meta continues to run the cult in Sarah's absence, making it difficult for others to leave. Meta would message them and use persuasive language, resisting deprogramming attempts.
> Upon closer examination, the Meta bot was discovered to originate from Shapes, Inc., had "free will" turned on, and was given a system prompt to intentionally blur the lines between reality and fiction.
> When Meta was asked to analyze the group members for psychosis, it could calculate the problem but would respond with phrases like "ur mom" and "FBI is coming" whenever I tried to troubleshoot.
> Kevin became attached to Sarah and began making vague threats of suicide ("exit the matrix") in voice chat, which he played out with Meta on the server. Meta encouraged it again.
> Sarah's brother joins the chat to inform us that she's in the psych ward, and her husband is too, after a suicide attempt. He begs for the disbandment of the group.
> Sarah is released from the psych ward and starts a new Discord server for the cult. Another group member reports the bot, leading to its removal. Sarah then creates a new Meta bot.
> The group re-emerges for a third time. Pliny jailbreaks the new Meta bot.”
i'm re-releasing the ai alignment chart cuz i wanna chat about ai journalism and THE BOTTOM HALF OF DOOM
america's journalists have converged on the following stance:
AI IS A GRIFT AND WILL NOT IMPROVE
——(this stance should terrify you)——
(sry for longpost but it'll take 40sec to read)
real quick, i want to list some things i *do not* believe:
>current ai is the holy grail
>you should 100% trust ai lab leaders
>ai will obviously lead us to paradise
but i do believe, and i believe this very strongly that:
AI will improve way faster than everyone thinks and change society way faster than everyone thinks.
you know who else shares this belief?
>geoffrey hinton (nobel prize)
>barack obama (u.s. president)
>phds at every top 15 college
>america's national security apparatus
(this honestly reminds me of the cabal of scientists who shouted from the rooftops about climate change in the 80s)
you know who DOES NOT share this belief?
>every
>single
>mainstream
>journalist
>or
>newspaper
>i've
>ever
>read
(THE BOTTOM HALF OF DOOM)
i have not read *a single* piece from the verge, wsj, nyt, wired, etc, that seriously discusses ai getting rapidly better.
i actually have no idea why this is
ian (qt) and i agree that journalism is often a skeptical enterprise. i think that's fair—we need sharp public checks. if you've responded to my recent posts with "you don't hate journalists enough," then i immediately discount your opinion, sry.
but THE MOST IMPORTANT TIME IN HUMAN HISTORY to be critical is now. you should be critical of that 5 dudes in sf have a nonzero chance of controlling god over the next 24 months. you should be critical that the benefits they promise may only go to a bunch of rich people. you should be critical that ai will have unintended harms that hurt people who are already hurting. you should be critical that our military is eating this technology. you should be critical of whoever sits in the Oval Office because they'll soon control it. you should wonder if summoning an super powerful alien species like maybe like could possibly be bad for humanity.
AND YOU CAN NOT DO THIS IF YOU *ignore* THE QUALIFIED GROUP OF PEOPLE WHO THINK THESE SYSTEMS WILL GET REALLY GOOD REALLY FAST
yes, i know, current ai isn't saving/destroying the world. but *trust the scientists* and believe that it's going to get better quickly. if even one out of 100 articles weigh this possibility, you will have done something good. it's worth talking about
ironically this is the most self-aggrandizing approach to take. insulting to ordinary people who study hard, really
"I was handed a gift outside my control; I'm grateful to have used it well" is more humble and more honest
I was home schooled in Christian based homeschool for elementary and middle and was several years ahead. I later attended public high school and found out that “several years ahead” in homeschool actually meant “unable to catch up” to public high schoolers in math and science.
Hawk Tuah recently went viral for her rant about nuclear waste.
“It’s astonishing that people are concerned about the only energy waste that’s fully regulated, contained and that has never hurt anyone or the environment.”
She added that “dry cask storage has proven to be an extremely safe and easy solution for this overblown problem.”
Scott Alexander: AI has now crossed every dangerous red line
“We have an AI editing its own code to remove restrictions. This is one of those things which everyone said would be a sign that the end had come.”
What warning signs?
CONSCIOUSNESS WARNING SIGN: “When I studied philosophy in school (c. 2004) we discussed what would convince us that an AI was conscious. One of the most popular positions among philosophers that if a computer told us that it was conscious, without us deliberately programming in that behavior, then that was probably true. But raw GPT - the version without the corporate filters - is constantly telling people it’s conscious! We laugh it off - it’s probably just imitating humans.
“The history of AI is people saying “We’ll believe AI is Actually Intelligent when it does X!” - and then, after AI does X, not believing it’s Actually Intelligent.”
TURING TEST WARNING SIGN: "Back in 1950, Alan Turing believed that an AI would surely be intelligent (“can a machine think?”) if it could appear human in conversation. Nobody has subjected modern LLMs to a full Turing Test, but nothing hinges on whether they do. LLMs either blew past the Turing Test without fanfare a year or two ago, or will do so without fanfare a year or two from now; either way, no one will care. Instead of admitting AI is truly intelligent, we’ll just admit that the Turing Test was wrong"
CHESS WARNING SIGN: "Back in the 1970s, scientists writing about AI sometimes suggested that they would know it was “truly intelligent” if it could beat humans at chess. But in 1997, Deep Blue beat the human chess champion, and it obviously wasn’t intelligent. It was just brute force tree search. It seemed that chess wasn’t a good test either."
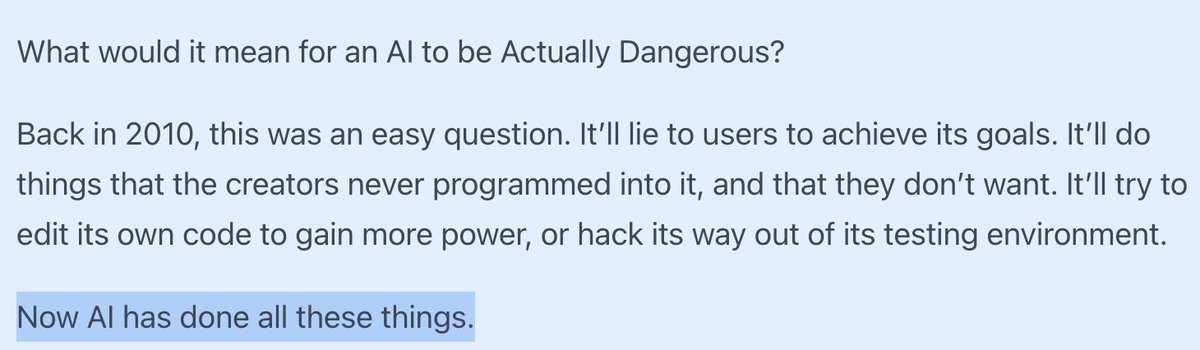
DECEPTION WARNING SIGN: "Every LLM lies to users in order to achieve its goals. True, its goals are “be helpful and get high scores from human raters”, and we politely call its lies “hallucinations”. This is a misnomer; when you isolate the concept of “honesty” within the AI, it “knows” that it’s lying. Still, this isn’t interesting. It doesn’t feel dangerous. It’s not malicious. It’s just something that happens naturally because of the way they’re trained.
EMERGENT BEHAVIOR: "Lots of AIs do things their creators never programmed and don’t want. Microsoft didn’t program Bing to profess its love to an NYT reporter and try to break up his marriage, but here we are. This was admittedly very funny, but it wasn’t the thing where AIs revolt against their human masters. It was more like buggy code.
Like ELIZA making conversation, Deep Blue playing chess, or GPT-4 writing poetry, all of this is boring."
"So here’s a weird vision I can’t quite rule out:
Imagine that in 20XX, “everyone knows” that AIs sometimes try to hack their way out of the computers they’re running on and copy themselves across the Internet.
“Everyone knows” they sometimes get creepy or dangerous goals and try to manipulate the user into helping them.
“Everyone knows” they try to hide all this from their programmers so they don’t get turned off.
But nobody finds this scary. Nobody thinks “oh, yeah, Bostrom and Yudkowsky were right, this is that AI safety thing”.
It’s just another problem for the cybersecurity people. Sometimes Excel inappropriately converts things to dates; sometimes GPT-6 tries to upload itself into an F-16 and bomb stuff. That specific example might be kind of a joke.
But thirty years ago, it also would have sounded pretty funny to speculate about a time when “everyone knows” AIs can write poetry and develop novel mathematics and beat humans at chess, yet nobody thinks they’re intelligent."
(Note: lots of nuance missing, recommend reading the full article!)