AgentWorks HQ is an engineering publication about learning AI and building with it.
Structured series and in-depth articles on agents, MCP, orchestration, governance and Java.
Start here: https://t.co/hQltubmI5h
A hard truth about structured output from LLMs: the JSON format is a request, not a guarantee.
If the model leaves a field out, parsing won't even throw. The field is just null.
That's why you validate after the call
https://t.co/Bp7yakOvv6
#SpringAI#Java#AIEngineering
Stop parsing LLM replies with regex.
Ask for a Java record instead:
.call().entity(Ticket.class)
Then validate it with Bean Validation. Here's how, plus streaming and tests 👇
https://t.co/Bp7yakOvv6
#SpringAI#Java#LLM
Want to try LLMs in Java without paying for an API key?
Run a model locally with Ollama, connect it to Spring Boot with Spring AI, and swap to a hosted provider later by changing one dependency and two properties.
https://t.co/G0LnT0elMz
#Java#SpringBoot#AI
Calling an LLM from Spring Boot takes about one line:
chat.prompt().user(q).call().content()
The full guide covers the setup, token logging and safe failure handling, all running locally with Ollama 👇
https://t.co/G0LnT0elMz
#SpringAI#Java#Ollama
Your RAG app gives wrong answers. Is it retrieval or the model?
Measure retrieval separately with hit rate at k. It needs no LLM and gives the same number every run.
This post walks through it with Spring AI + pgvector 👇
https://t.co/LtUrsFYfso
#RAG#GenAI#LLM
OpenAI shipped GPT-6.2 on Nov 17, in ChatGPT and the API.
▪ Astra: top-tier, for complex pro work
▪ Sol: lighter, for everyday tasks
Astra is rated “High” for self-improvement under OpenAI’s own framework, reportedly a first for a public model.
#AI#OpenAI#GPT6
Give your LLM API one error shape, every time:
{ timestamp, status, error, message, path }
Map provider failures to 429, 503 or 502 with generic messages. Never leak API keys or raw provider output to clients.
https://t.co/CFxM9m6ffv
#SpringBoot#API
Common LLM backend mistake: wrapping the model call in @Transactional.
A 5s response means a DB connection held for 5s.
Do this instead:
Short tx: save the user message, read history
Call the model, no tx open
Short tx: save the reply
https://t.co/CFxM9m6ffv
#Java#SpringAI
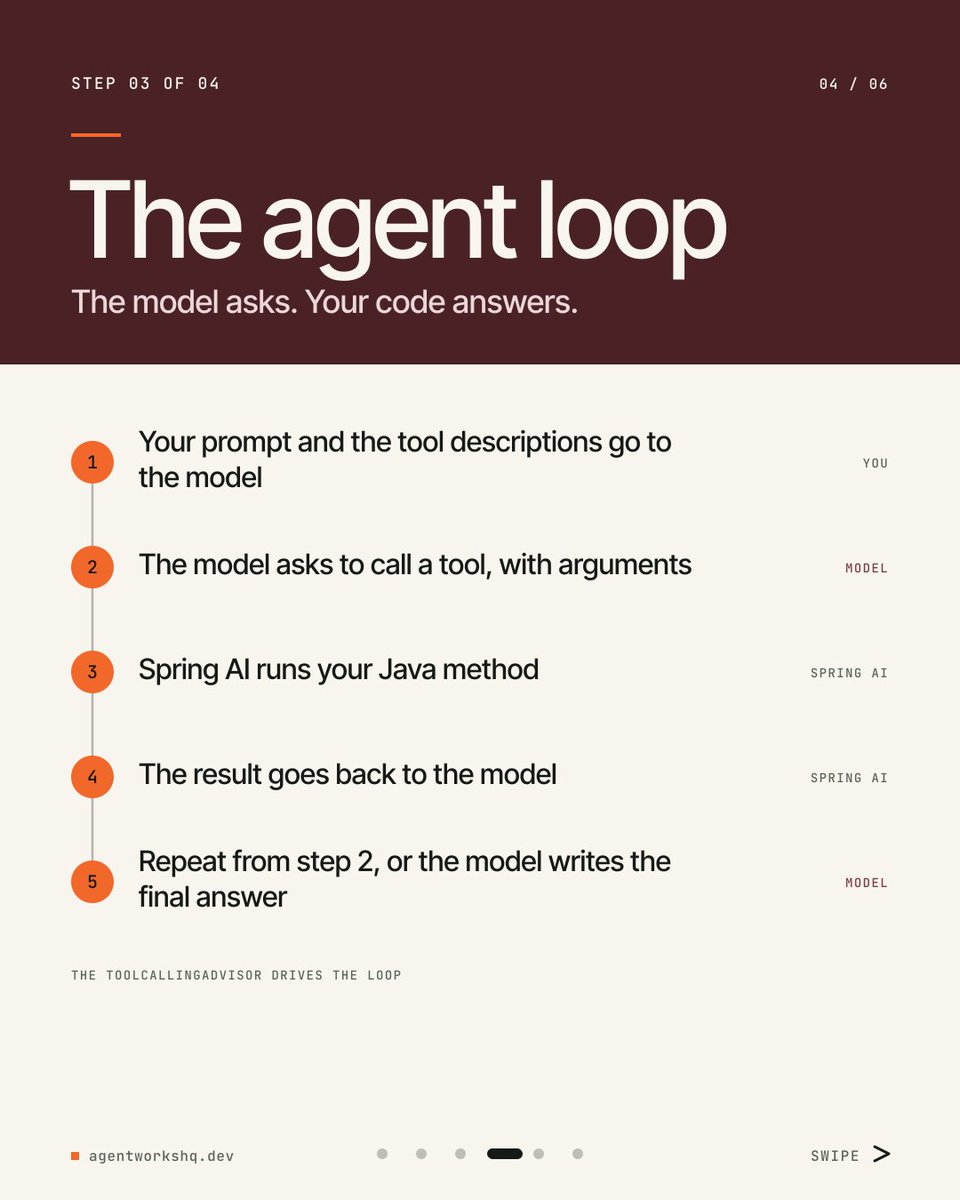
Tool calling and the agent loop, in four steps:
1. Write a tool: @Tool on a Java method
2. Hand it to ChatClient: .tools(...)
3. The loop: the model asks, your method runs
4. Keep it safe: cap the loop, validate arguments
Stage 3 of the roadmap.
#SpringAI#AIAgents
Calling an LLM is the easy part. Production-ready is the lesson.
This Spring AI project covers retries, rate limiting, API key auth, safe error handling, request tracing and Docker.
https://t.co/rus0iUTtrP
#Java#SpringBoot#SpringAI#AIEngineering#LLM
Before you give an agent a tool, ask:
• Can it delete anything?
• Can it spend money?
• Can it email someone?
If yes, add a confirmation step. Start with read-only tools.
#AIAgents#AISafety#LLM
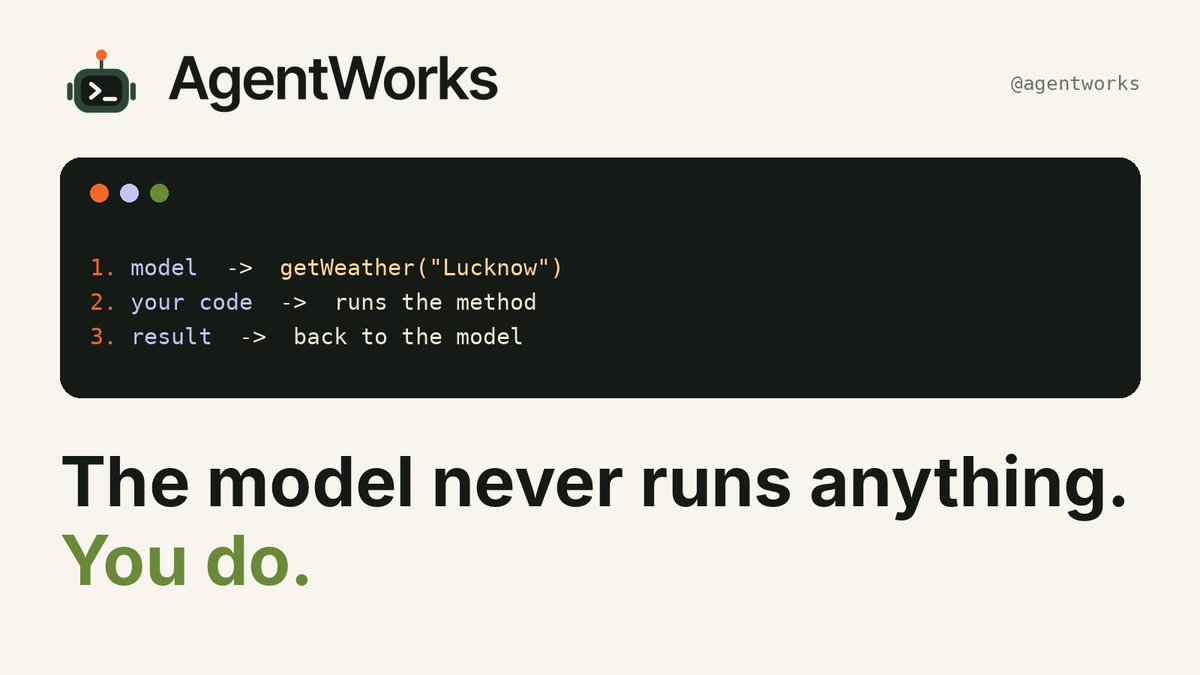
An agent "using a tool" is just three steps:
1. The model outputs getWeather("Lucknow")
2. Your code runs the method
3. The result goes back to the model
The model never runs anything. You do.
#AIAgents#ToolCalling#LLM