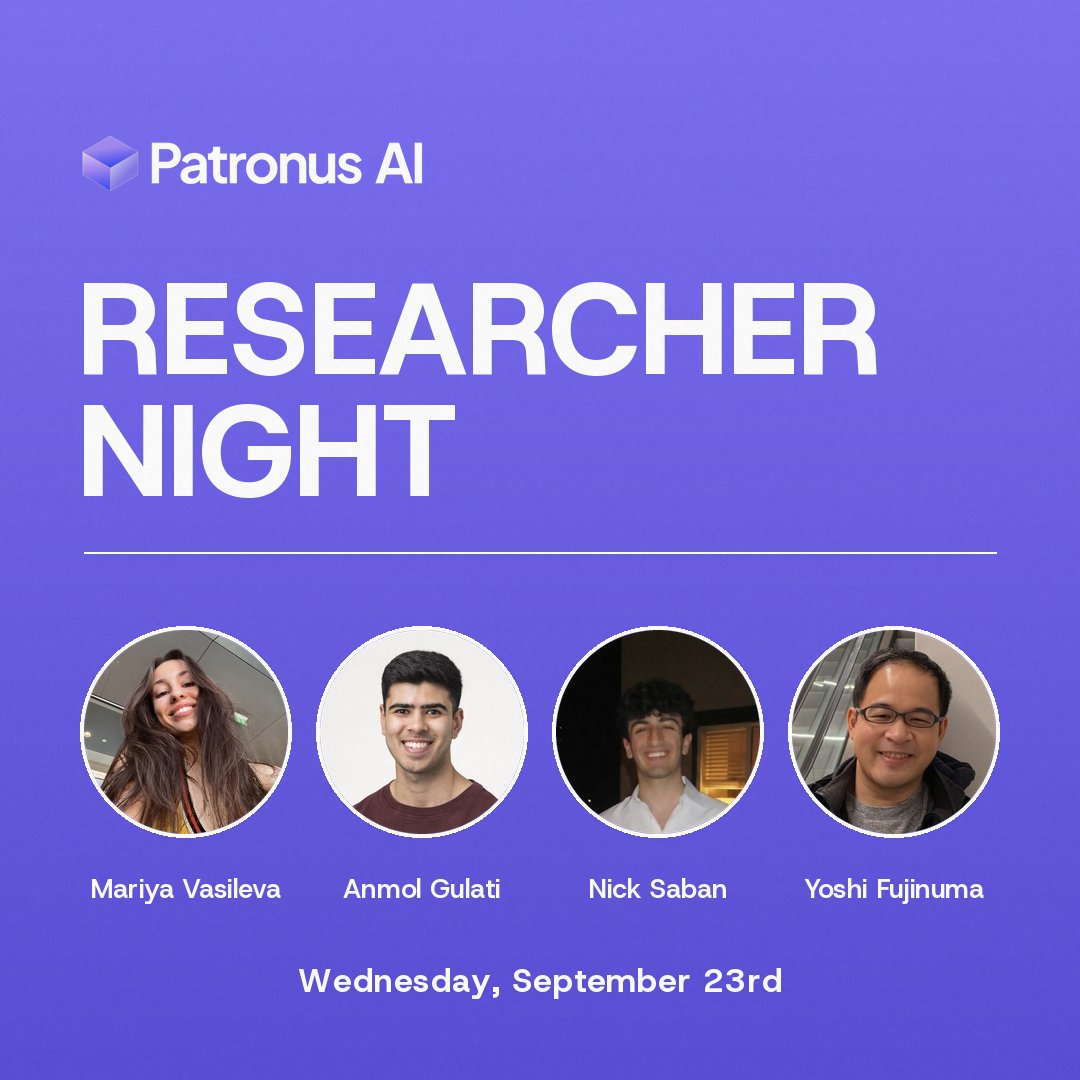
We're hosting a researcher night next Wednesday at our office in SF. Fast-paced spotlight talks on post-training and evaluation. ⚡️
The talks:
@mariyaivasileva on Beliefload: an evaluation of how LLMs formulate and revise hypotheses in light of new evidence, and how they diagnose and repair a broken environment without overwriting the parts that already work.
@Nick_saban20 on GlobeBench: a benchmark for whether language models can faithfully simulate the environments we train agents in.
@AnmolGulati06 on Beyond Rows to Reasoning: an agentic framework for reasoning over and editing enterprise spreadsheets with millions of cells, cross-sheet dependencies, and embedded charts.
@akkikiki on SpeedrunBench: a benchmark that asks not whether an agent can finish a game, but how fast.
Drinks, sushi, merch incoming.
Today, we’re releasing SpeedrunBench: the first benchmark that measures how fast agents can beat video games.
We asked frontier models not to simply complete video games, but to speedrun them - across 10 titles like Mario Kart and Pokemon.
On simpler games, agents get close to the human world record. However, on more complicated games like Pokemon Blue, the best models Kimi-K3 and Opus 5 are ~4x off the world record.
Benchmark, paper, and demo below.
@PatronusAI
Today, we’re releasing SpeedrunBench: the first benchmark that measures how fast agents can beat video games.
We asked frontier models not to simply complete video games, but to speedrun them - across 10 titles like Mario Kart and Pokemon.
On simpler games, agents get close to the human world record. However, on more complicated games like Pokemon Blue, the best models Kimi-K3 and Opus 5 are ~4x off the world record.
Benchmark, paper, and demo below.
Just got back from KDD 2026 in Jeju Island, South Korea 🇰🇷, where we presented "From Rows to Reasoning: A Retrieval-Augmented Multimodal Framework for Spreadsheet Understanding".
The work tackles a persistent gap in LLM capabilities: reasoning over real enterprise spreadsheets with hundreds of thousands of rows, linked sheets, and embedded charts and receipts. We introduce FRTR-Bench, the first large-scale benchmark for multimodal spreadsheet reasoning, along with FRTR, a retrieval-augmented framework for handling complex spreadsheets.
One pattern was impossible to miss this year: the conversation has shifted from models answering questions about data to agents actually working with it. And once agents are doing the work, everything hinges on having realistic environments and benchmarks to train and evaluate them against, which made for some great conversations throughout the week. See you at the next conference!
Paper: https://t.co/W9jTcr1vyp
@anmolgulati06