@ipvpn2 Claude design with inspirations from sources like getdesign.md, https://t.co/mxablaOVRD, https://t.co/mxAOaVmqLf or any design/components library of choice
الskill دي من cloudflare برضه حلوة, بتخلي الـ AI coding agent يتعامل كأنه Security Auditor و يلف علي الـ codebase يطلع مشاكل الsecurity
https://t.co/4liSX3tgAn
من الحاجات المهمة الي لازم يتاخد ليها action ان أي حد يتابع الemails و الannouncements الي جاية من أي cloud hosting provider بتتعامل معاه بخصوص الmajor security issues الي حصلت الكام يوم الي فاتو و share الي موجود في الايميل مع اي agent يعمل scan للcodebase عشان يaddress أي مشاكل ممكن تحصل بسبب dependencies أو node version/update مثلا, و أكيد php لو بتستخدمه مفيهاش كلام
@hazem_samak101 أنا برضه شايف انها فعلا بتبقي علي حسب التجربة الشخصية بغض النظر عن الbenchmarks و التجارب بتاعة الarenas و كده عشان اغلبها بتبقي usecases مش هستخدمه اصلا ليها. أنا كنت جربت muse glimmer و muse spark 1.2 كانو لذاذ و سراع في حاجات زي exploration و quick bug fixes
We’re rolling out Gemini 4 Argon in Antigravity to paid Google AI Pro subscribers today. Demand has been incredible and we've scaled capacity deliberately to get here. We’ve rolled out a separate weekly-only Argon quota for Pro on top of the existing Gemini bucket for 3.8 Flash so you have the best of Gemini for all your tasks.
@hazem_samak101 اه بالظبط، هستخدمه فعلا ك delegated agent يخلص التاسك و model اقوي زي astra او opus 5.5 يراجع عليه. مستغرب ال benchmarks بتاعته كنت متوقعه هيأدي 😅
this has become one of my most used prompts recently:
> restate in your own words what you think my goals are and what the problem i'm trying to solve is
As an AI Engineer. Please learn:
> Harness engineering, not just prompt engineering
> Context engineering, not just long prompts
> Prompt caching vs. semantic caching tradeoffs
> KV cache management, eviction, reuse, and memory pressure at scale
> Prefill vs. decode latency and why they optimize differently
> Continuous batching, paged attention, and throughput optimization
> Speculative decoding vs. quantization vs. distillation tradeoffs
> INT8, INT4, FP8, AWQ, GPTQ, and when quantization hurts quality
> Structured output failures, schema validation, repair loops, and fallback chains
> Function calling reliability, tool contracts, argument validation, and idempotency
> Agent guardrails, loop budgets, tool budgets, and termination conditions
> Model routing, graceful fallback logic, and degraded-mode UX
> RAG architecture: chunking, embeddings, hybrid search, reranking, and freshness
> Retrieval evals: recall, precision, grounding, attribution, and citation quality
> Evals: golden sets, regression tests, adversarial tests, LLM-as-judge, and human evals
> LLM observability as a first-class discipline: traces, spans, tokens, latency, errors, and drift
> Cost attribution per feature, workflow, tenant, and user journey, not just per model
> Safety engineering: prompt injection defense, data leakage prevention, and permission boundaries
> Multi-tenant isolation, cache safety, and cross-user context contamination prevention
> Fine-tuning vs. in-context learning vs. RAG vs. distillation, and when each is the wrong tool
> Latency, quality, cost, and reliability tradeoffs across the full inference stack
> Production failure modes: hallucinated tool calls, malformed JSON, stale retrieval, runaway agents, and silent eval regressions
> Shipping LLM systems as reliable infrastructure, not demos wrapped around prompts
https://t.co/Q2FHIjahSx
للناس اللي بيدوروا على شغل زى حالاتى , ال repo دى جامدة جدا جدا بت login فيها ب claude وبيعمل job search , mass applications على حسب ال cv بتاعك وبيعملك كل ال documents اللى بتقدم على اي شغلانة ويقدملك بيها ف بصراحه انصح بيه جدا ل mass apply
https://t.co/E1zQg6QXUk
مسابقة للناس المهتمين بالـAI ، بجد خش و حاول، مش هتخسر حاجة تدريب ببلاش و لو نجحت (الجائزة الآوي ٣٧ الف دولار، التاني ١٨ الف دولار، الثالث ١٠ الاف دولار )
Google - The Gemma 4 Developer Agent Competition
https://t.co/Ncjcj72fN9
Stop caring so much about model releases.
Focus on the harness, and improving the environment your agent operates in.
You'll find yourself far ahead of the curve.
everyone posting the old oracle free vps but
4 ocpu / 24gb got cut to this in june:
- 2 ocpu (arm, ampere)
- 12 gb ram
- 200 gb disk
- always free, no card charge
still more than a $20/month hetzner box
my 5 production apps cost me $6.00 last month
- workers (compute)
- d1 (sql db)
- r2 (storage, zero egress)
- kv (cache)
- queues (jobs)
- cron triggers (schedules)
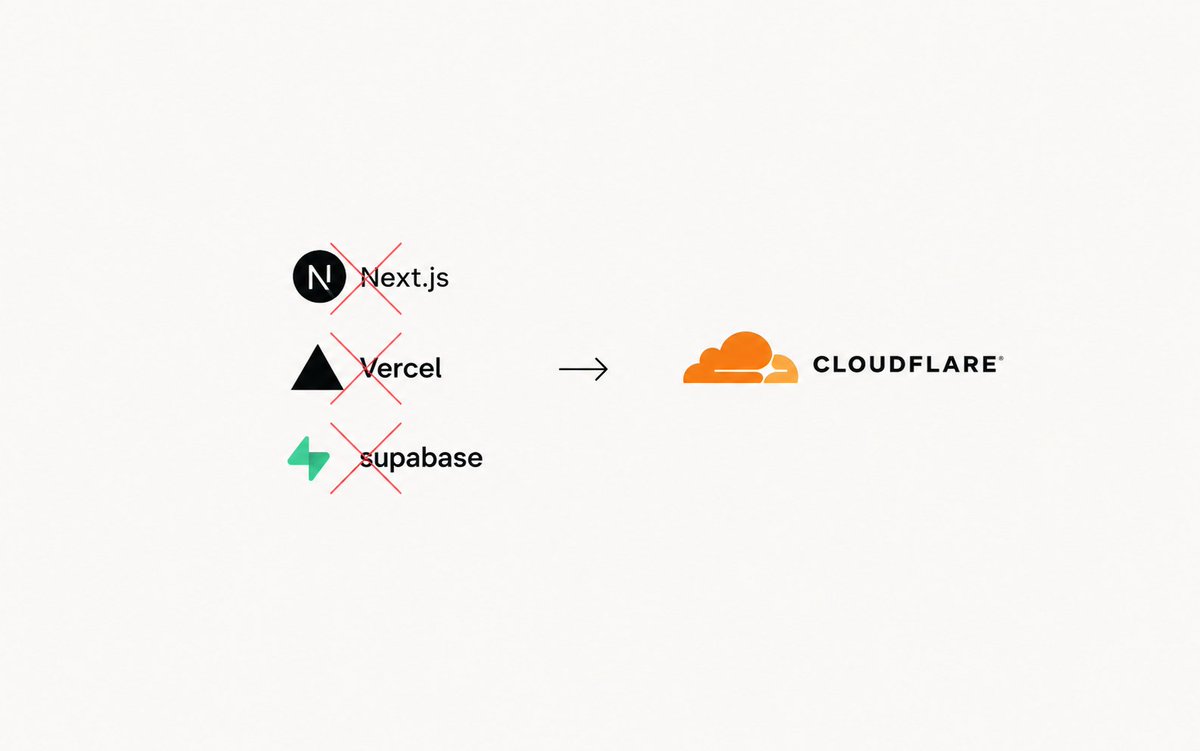
same setup on vercel + supabase + upstash is ~$200
stop overengineering your infra
As an AI Engineer, you must build these projects.
Systems that prove you can retrieve, reason & ship.
1.) Production RAG Pipeline
Build: Ingestion → chunking → hybrid search → reranking → cited answers over 1000+ docs.
Why: Retrieval quality decides if your LLM product lives or dies.
2.) Structured Output Engine
Build: Pydantic schema enforcement with retries, validation, graceful fallbacks on malformed JSON.
Why: Apps break on free text. Schemas make LLM output usable.
3.) Context Assembly Service
Build: Dynamic context builder that budgets tokens across memory, docs & tools per request.
Why: Context engineering beats prompt tweaking in production.
4.) LLM Evaluation Harness
Build: Golden dataset + LLM-as-a-judge + CI gate that blocks merges on quality regression.
Why: You cannot ship what you cannot measure.
5.) Semantic Cache Layer
Build: Embedding-based cache returning stored answers for similar queries, with hit-rate tracking.
Why: The cheapest token is the one you never generate.
6.) Model Routing Gateway
Build: Complexity-based router across 3 model tiers with fallbacks and per-request cost tracking.
Why: Unit economics decide if your AI product survives.
7.) Multi-Tenant LLM API
Build: Per-tenant keys, rate limits, token budgets, isolated data access.
Why: Enterprise customers demand isolation and spend control.
8.) Fine-Tuning Pipeline
Build: LoRA/QLoRA fine-tune of a small model on synthetic data, benchmarked vs prompt-only baseline.
Why: Know when adaptation beats prompting, and when it doesn't.
9.) Agent Memory System
Build: Working + episodic + semantic memory with compression and eviction policies.
Why: Agents without memory fail by turn five.
10.) Guardrails Middleware
Build: Input/output filtering, PII redaction, injection detection as a reusable service layer.
Why: One leak destroys trust. Safety must be infrastructure.
11.) Streaming Response Infrastructure
Build: SSE streaming with backpressure, reconnects, time-to-first-token tracking.
Why: Perceived latency is the UX of AI products.
12.) Prompt Versioning and A/B System
Build: Registry for prompts and configs with rollback, traffic splitting, outcome tracking.
Why: Prompts are production code. Treat them that way.
13.) LLM Observability Stack
Build: Tracing for prompts, tokens, latency, cost per request with alerting on anomalies.
Why: You cannot debug what you cannot see, especially non-determinism.
14.) Tool-Calling Framework
Build: Typed function schemas with discovery, retries, sandboxed execution.
Why: Tools turn chatbots into systems that actually do work.
15.) Self-Correcting RAG Agent
Build: Query rewriting, retrieval critique, confidence-based fallback to web search.
Why: Production retrieval must repair itself, not hallucinate.
Most people watch tutorials. Builders ship systems.
Bookmark & Repost.