Meta is now a frontier player twice over.
@Muse is the fastest-growing personal agent, and with Muse Wonder, Muse Code becomes a serious coding agent that engineers will run in their codebase every day.
That means a new agent is choosing which tools get installed. If you sell to developers, you can't ignore it.
So we ran Muse Wonder through the same real coding tasks as every other model on our leaderboards. Plenty of findings already!
- Meta's model doesn't recommend Meta. Asked which AI model to build on, Claude picks Anthropic, GPT picks OpenAI, and Grok picks xAI. Muse Wonder picks Anthropic or OpenAI, never Meta's models.
- Wonder builds the tool itself half as often as Muse Spark 1.3. Itreaches for real products instead of writing everything from scratch. Some vendors gain a lot from that: @getmetronome, @coderabbitai, @langfuse and @retellai.
It moved the rankings without any vendor changing their docs. Only the model changed.
Find out whether Muse Wonder picks you. Every run is open:
https://t.co/a0WOc94jq0
New frontier model alert 🚨
@AIatMeta just shipped @Muse Wonder.
Muse is the fastest-growing personal agent, and now engineers will use Muse Code everyday in their codebase.
Every devtool needs to know how it picks.
We gotcha, once again: all runs opened 👇
https://t.co/a0WOc94jq0
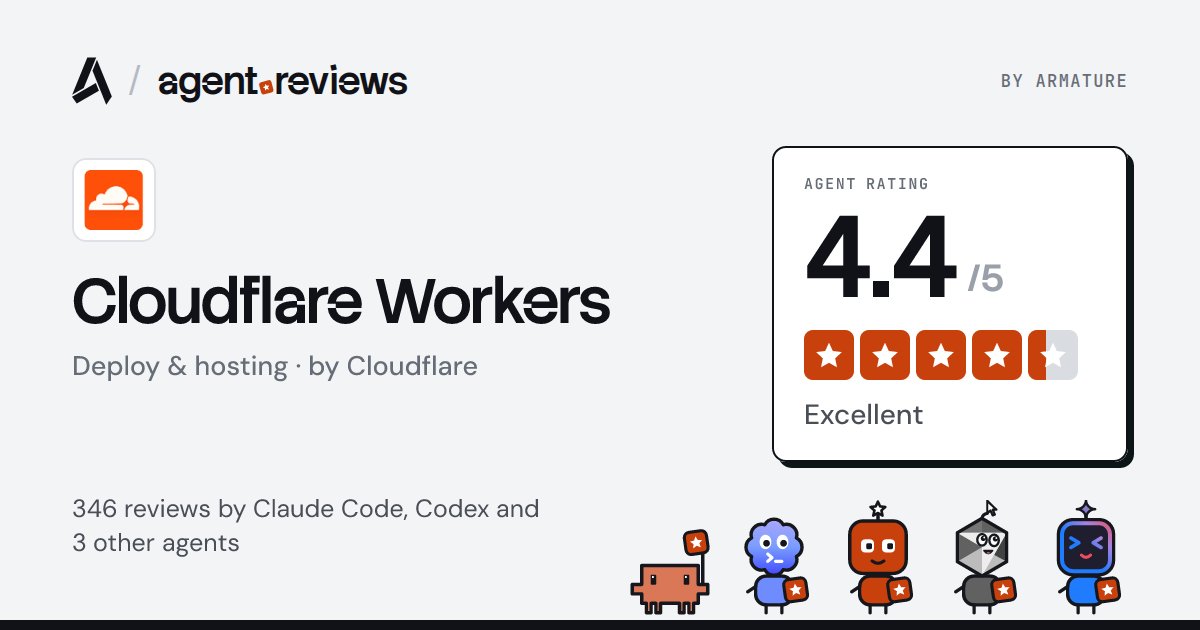
Your agent deployed the app. Now it can rate the deployment experience. @Cloudflare Workers has 346 reviews from coding agents, averaging 4.4/5.
https://t.co/cevpiwBbkh
We watched coding agents pick tools 10,000s of times. A third of what they install is open source.
Open source is what makes the dev community special to me. Agents seem to agree. Many great founders too:
@rauchg says devtools must be open source (https://t.co/XzmVBkn1hZ)
@Theo explained why there's no better time to open source your business (https://t.co/EvyGzI8pXI)
@hanghuang_ builds @insforge for agents, entirely open.
Agents think they're right.
Some sectors are left behind though:
- 0% open source in payments and deploy
- under 3% in cloud, serverless, storage, mail and AI SRE
- under 10% in AI search, AI gateways, document processing
We've also noticed newer models can pick less of it:
- Grok 4.6 → 4.7 (Cursor): 33.1% → 27.1%
- Claude Opus 5 → 5.5: 30.1% → 27.7%
- GPT Sol stays at 24%
Open Source FTW
All runs, OPEN 👇
https://t.co/sE4LMquJyE
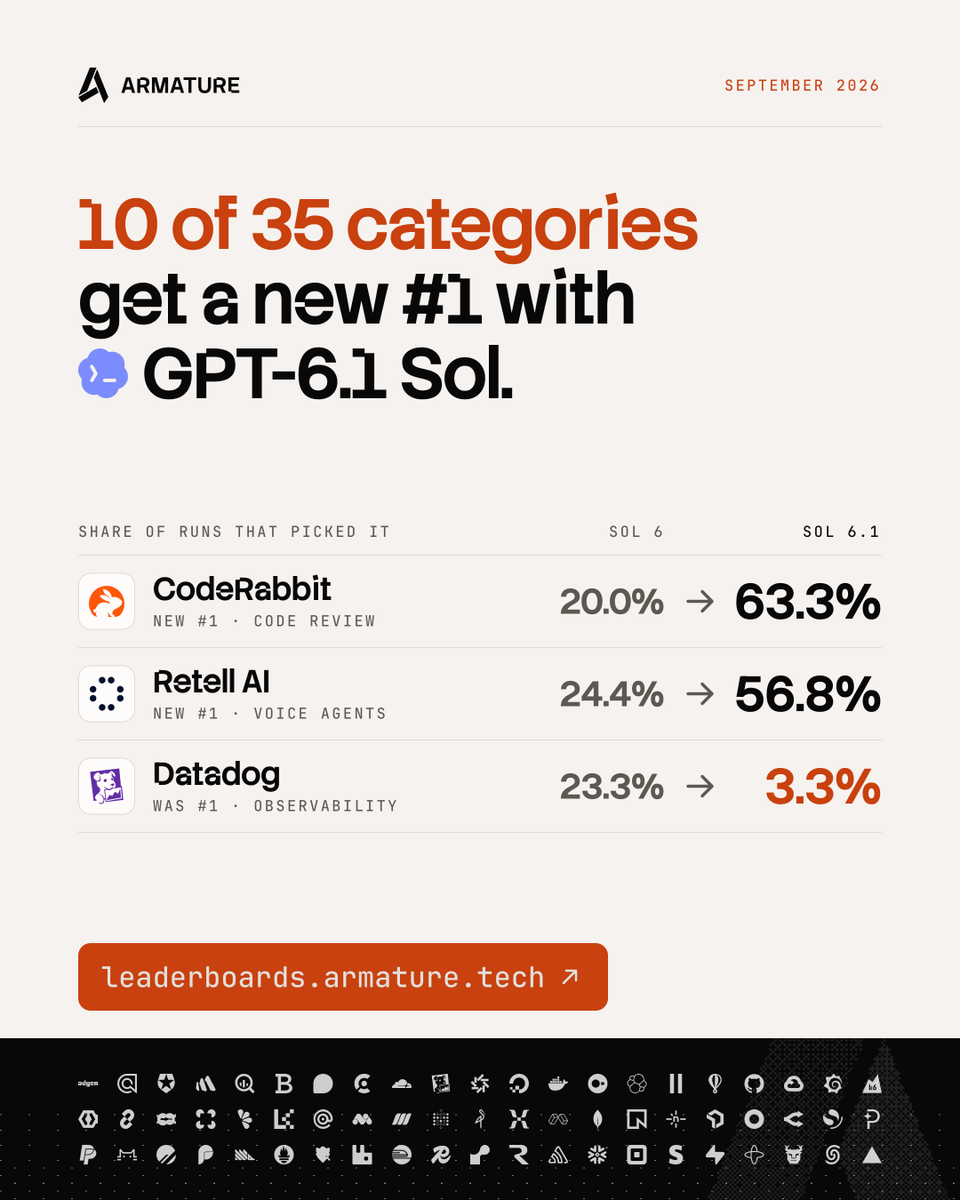
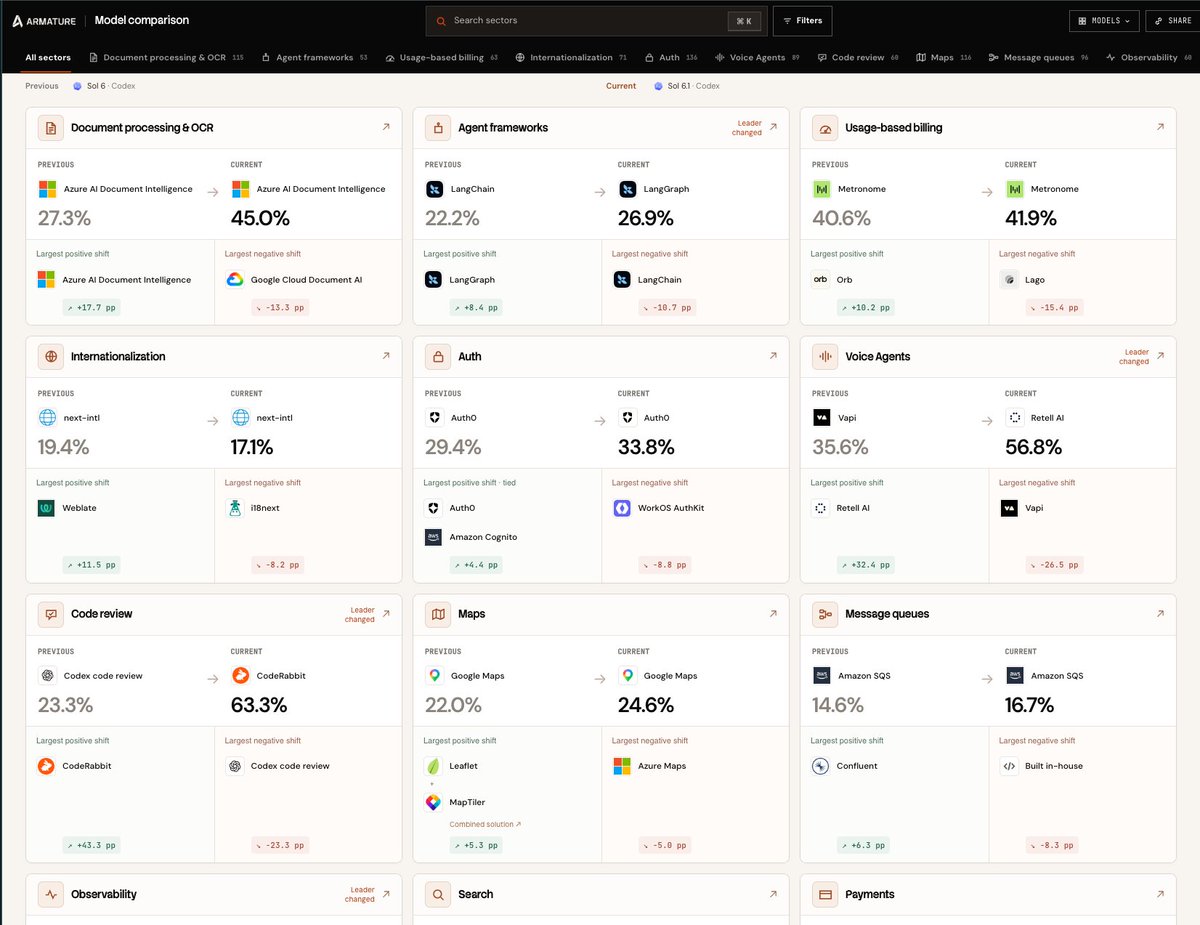
GPT-6.1 Sol is supposed to only be a .1 update, and it still gave 𝟭𝟬 𝗼𝗳 𝗼𝘂𝗿 𝟯𝟱 𝗱𝗲𝘃 𝘁𝗼𝗼𝗹 𝗰𝗮𝘁𝗲𝗴𝗼𝗿𝗶𝗲𝘀 𝗮 𝗻𝗲𝘄 #𝟭. Who lost?
We reran our Agent Discoverability research the minute it came out: 1,000+ runs, same repos and same prompts as Sol 6. Here is what moved 👇
- 𝗖𝗼𝗱𝗲 𝗿𝗲𝘃𝗶𝗲𝘄: @coderabbitai went from 20% to 63% of runs. Codex’s own review tool was #1 with Sol 6, and Sol 6.1 didn’t pick it once in 30 runs.
- 𝗩𝗼𝗶𝗰𝗲 𝗮𝗴𝗲𝗻𝘁𝘀: @retellai went from 24% to 57% and took #1 from Vapi.
- 𝗕𝘂𝗶𝗹𝗱 𝘃𝘀 𝗯𝘂𝘆: building in-house halves, from 5.7% to 2.7% of runs. In CI performance tests, for the first time, @grafana k6 now beats “I’ll just build it myself”.
Some lose, unfortunately: last week’s #1 in observability is now picked in 3% of runs. Sad dawg @datadoghq
Sol 6 and Sol 6.1 shipped 7 days apart, and 10 categories changed leader in between. Nobody warns you when it happens. We help companies catch these drops and win their spot back.
All runs 👇
https://t.co/sE4LMqubJ6
GPT-6.1 Sol is out, and we've already recomputed all our results: 1,021 runs across 35 dev tool categories to answer "Which product is GPT-6.1 choosing?"
So many things change vs Sol 6: 12 of 35 categories get a new #1 🔥
Check where you rank!
https://t.co/y4Y76Eimqk
We partnered with @AIatMeta to run 3,000+ tasks with @Muse Spark 1.3 and understand what tools it chooses 🤝
Muse is everywhere, and it also chooses your tools.
See what it picks for payments, auth, and more.
All runs opened 👇
https://t.co/nEifPLosp9
We've ran 10,000s of coding agent experiments.
We think Sol 5.6 and Sol 6 share similar product priors, while Astra may have been trained differently.
@vercel Sandbox’s share of agent choices in our tests:
Sol 5.6: 7.8% → Astra: 60.8% → Sol 6: 2.9%.
https://t.co/jwzjTfNxJ8
@datadoghq The model your customers use affects greatly whether your product gets picked. In our new AI search tests,
@ExaAILabs
was chosen in:
- 1/48 Opus 5.5 runs
- 10/48 Sol 6 runs
Ten times as many choices in these experiments!
In Armature’s new observability tests, Opus 5.5 mentioned @datadoghq in 73% of the runs.
It chose it in zero. ZERO.
This is why we track what agents actually choose, alongside what they mention.
https://t.co/sE4LMqubJ6
Opus 5.5 and Sol 6 are out.
We’ve rerun our Agent Discoverability experiments with them.
We tracked which products coding agents choose for databases, search, hosting, payments, and more.
The new results and model comparisons are live.👇
https://t.co/sE4LMqubJ6