7. Our take
After a 12-prompt test, Recraft's rule of thumb fits what we're seeing: use Flare as your fast sketchbook, Sunburst when edit 3 must match edit 1, and keep bulk low-tier icons on 2.5.
What's the first GIF or workflow you're testing?
https://t.co/rqoqp1N0Fy
ChatGPT can now turn your prompt, sketch or photo into an animated GIF.
OpenAI just shipped Images 2.6 with frame-by-frame GIF edits, saved reference photos, and two faster API models.
Here's what works, the 16-frame catch, and the real token bill 🧵
https://t.co/NEuToCxGeC
Images, upgraded—introducing ChatGPT Images 2.6.
Now with GIFs and reference images.
Plus, two new models are coming to the API with 50% faster image generation.
6. The 16-frame GIF ceiling
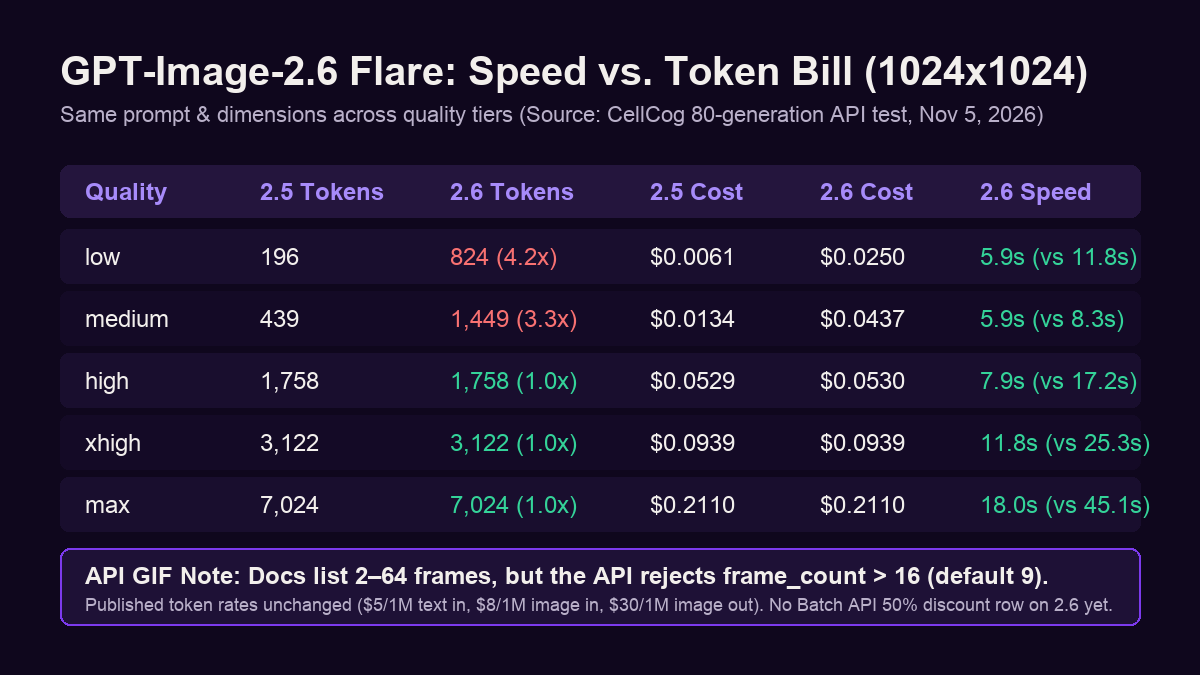
OpenAI's docs say API GIFs take 2 to 64 frames. In Garg's test, asking for 17 throws a 400 error: the hard cap's 16 frames (default 9), and a 12-frame medium GIF cost $0.056.
That's plenty for a mascot wave, but tight for long motion.
7. Our take
Carbon looks strongest on visual and 3D builds, at a lower cost per run. Long thinking times are the trade-off.
Until it opens up, Arena is where you can see it.
What would you build with it first?
https://t.co/vZFO2CDoeX
Gemini 4 Carbon isn't public yet. But people testing it on Arena are posting demos, and the 3D work is what stands out.
Here's Carbon vs Opus 5.5 on the same 3D build.
7 practical tests worth seeing 🧵
https://t.co/VmlAI5HoMi
🚨 Gemini 4 Carbon vs Opus 5.5
Carbon is SERIOUSLY good at 3D I don't think their is a model better than carbon at 3d, Overall this model deserves The top
this is just the Arena one Imagine what the official version will be capable of
Google is cooking
6. The counterweight
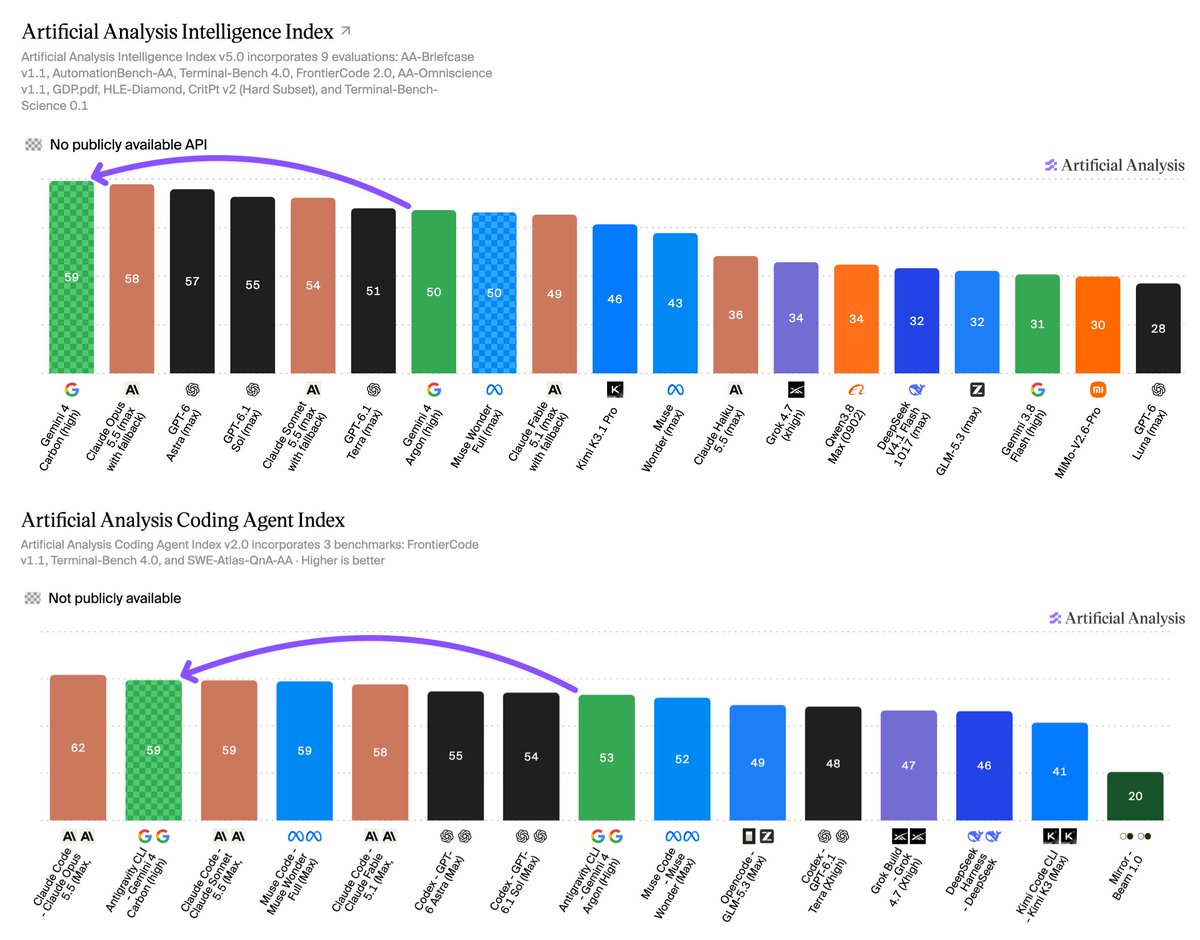
Artificial Analysis: 59, #1 overall, but second to Opus 5.5 on coding agents.
Great demos don't mean it wins every task. Check the work you actually do.
https://t.co/xFMWbRCZc4
Google’s Gemini 4 Carbon is the new #1 on the Artificial Analysis Intelligence Index v5, and second only to Claude Opus 5.5 on the Artificial Analysis Coding Agent Index
Gemini 4 Carbon scores 59 on Intelligence Index v5, driven by leading performance in complex reasoning, knowledge, and scientific tasks. It also has large gains in coding and knowledge work, particularly when compared to other Gemini models, but it is not leading in all these areas.
As with launch of Gemini 4 Argon, Gemini 4 Carbon is being rolled out to selected users and is not yet publicly available. Google is offering a 50% launch discount, with no confirmed end date. All our charts and figures use standard pricing for both Gemini 4 Carbon and Argon.
Key results for Gemini 4 Carbon with high reasoning:
➤ Gemini 4 Carbon leads the Intelligence Index v5, with the #1 score in 4 of the 9 Index evaluations: HLE-Diamond, Terminal-Bench-Science, AA-Omniscience, AutomationBench-AA. Carbon makes substantial gains elsewhere but is not leading in coding and knowledge work
➤ Behind only Claude Opus 5.5 on coding agents: With Antigravity CLI, Gemini 4 Carbon (high) scores 59 only 3 points behind Claude Code with Claude Opus 5.5 (max, 62) on the Artificial Analysis Coding Agent Index. Carbon ranks second on both Terminal-Bench 4.0 (64%) and FrontierCode v1.1 (51%), behind Claude Opus 5.5 (max) at 56%. Google has historically underperformed in this area and so this improvement stands out
➤ Improved agentic knowledge work, but not yet leading: On AA-Briefcase, Gemini 4 Carbon (high) scores 1609 Elo, a 126-point improvement over Gemini 4 Argon (high, 1483), but still behind models including Grok 4.7 (xhigh, 1638), Muse Wonder (max, 1659) and Kimi K3.1 Pro (1678). The largest gain comes from Presentation, up 293 Elo to 1598, alongside a 120-point improvement in Analytical Quality to 1671
➤ Lower Cost per Task than Claude Opus 5.5 for comparable overall intelligence: Gemini 4 Carbon costs $7.76 per Intelligence Index task, ~23% less than Claude Opus 5.5 (max, $10.04) but ~1.2x GPT-6 Astra (max, $6.25). It uses 123k output tokens per task, 29% fewer than Claude Opus 5.5 (max, 173k). At the same $4/$20 standard pricing, its Cost per Task is in line with Gemini 4 Argon ($7.68), while scoring 9 points higher on the Intelligence Index
➤ Leading AA-Omniscience v1.1 score, with low hallucination: Gemini 4 Carbon scores 54 on our recently updated AA-Omniscience v1.1, 6 points ahead of Claude Opus 5.5 (max, 48) and 8 points ahead of Gemini 4 Argon (46). Accuracy (% correct) rises 10 points over Argon to 58%, while its hallucination rate rises from 4% to 11%. This is still the second lowest of any model, behind only Argon, compared with 50% for both Claude Opus 5.5 (max) and GPT-6 Astra (max)
Key model details:
➤ Context Window: 1M tokens
➤ Multimodality: Text, image, video, and speech input, with text output
➤ Pricing: $4/$20 per 1M input/output tokens, the same as Gemini 4 Argon’s standard pricing, with a 50% discount. Cached input tokens receive a 95% discount ($0.20 per 1M)
Congratulations to the @GoogleDeepMind team!
My read: the model race for screen work is becoming a cost-per-finished-task race.
Pilot 20 to 50 real tasks. Compare completion and cost per finished task before you switch.
Full setup with code in the guide. What would you hand it first?
https://t.co/2NWkBLs1sn
OpenAI just cut the price of an AI that clicks through your apps in half.
GPT-6.1 Terra reads the screen, clicks and types, at $1 in and $5 out per million tokens.
Here's what the launch proves, 2 tests that disagree, and how to run it safely 🧵
https://t.co/cnaDOduFBo
GPT-6.1 Terra: delivering fast and capable computer use at a lower price.
GPT-6.1 Terra understands what’s on screen, takes action across apps, writes naturally, and is a more capable model for your whole workday with the efficiency to take on more of it.
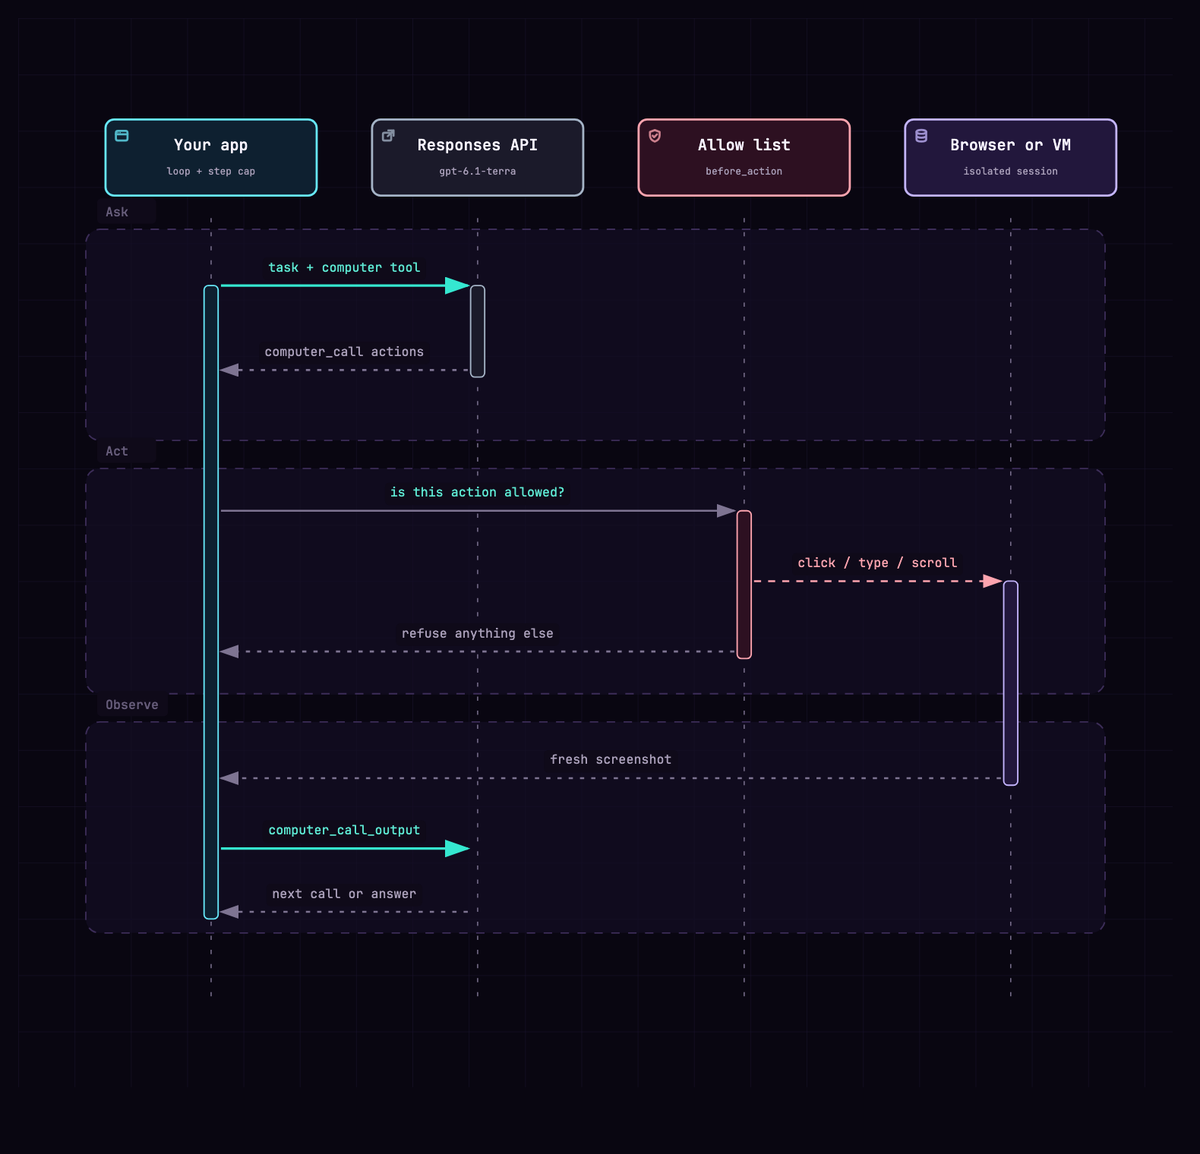
An agent that clicks can submit a real order.
Four controls:
1. Isolated browser with an allow list
2. Screen text is untrusted, enforce limits in code
3. A person approves purchases and deletes
4. Check the result in the real system