@ClavyAI Checking a model’s answer used to mean someone manually matching it against a large document, line by line. Now it’s a click, same verification but takes seconds instead of an afternoon.
The real problem with AI at work was never that it gets things wrong sometimes. It’s that checking one answer against a 90 page PDF takes longer than just doing the work yourself.
And in regulated industries like insurance, legal or finance, someone always ends up asking where a number came from. “The AI said so” doesn’t really hold up.
So we gave every answer its own audit trail. One click and you’re looking at the exact spot in the document it came from.
New in Clavy: Grounded citations
Click any citation and the source document opens with the exact passage highlighted, whether that’s a clause in a contract or a single number in a financial statement.
Ask a question across the documents in a space, or fill hundreds of rows in a table. Every answer points back to where it came from.
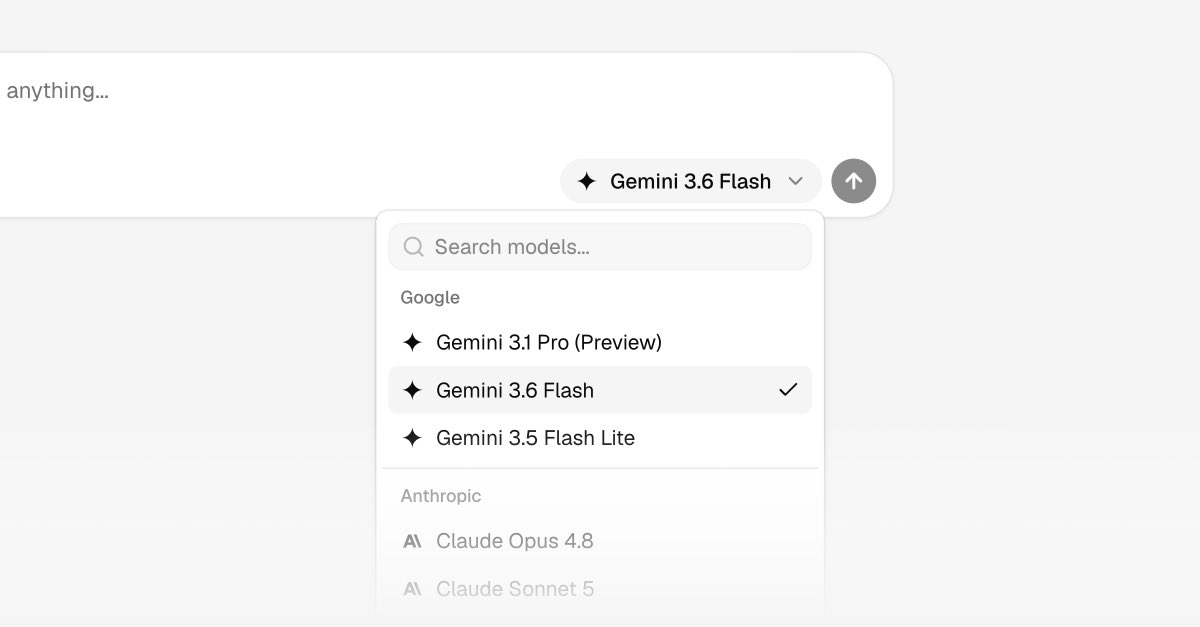
Google recently launched Gemini 3.6 Flash, and it is now available in Clavy along with Gemini 3.5 Flash Lite.
In our early testing, 3.6 Flash held up well on the high-volume work Clavy runs, like enriching table columns row by row and pulling answers from long documents. Compared to prior Flash models, it stayed accurate at speed, so bulk runs cost less without giving up quality.
Something I see constantly: a team of smart people spending half their week reading PDFs so they can fill in a spreadsheet.
That’s the workflow @ClavyAI replaces. Bring your documents, reports, or research and agents extract exactly what matters, structured and ready to act on.
We’re purpose-built for institutional workflows where the volume and precision requirements are too high for generic AI tools.
If that sounds like your team, I’d love to show you what we're building.
https://t.co/8A5eJ8KNfV
The bottleneck in investment research isn't judgment. It's reading the hundredth PDF this quarter and re-keying the same five numbers into a spreadsheet.
New post on how teams automate screening and diligence without losing the audit trail: https://t.co/2PHYeWf2pN
Most knowledge work is just reading documents and pulling out the same information over and over.
Financial reports. Contracts. Due diligence files. The content changes, the task doesn't.
That's what we're solving with @ClavyAI. You drop in your documents, define what you're looking for, and agents return structured analysis you can actually use.
Still early, but we're building something I wish I'd had for the past five years.
Claude Opus 4.7 is now live in Clavy!
Stronger reasoning and better contextual memory means sharper document analysis and more accurate data enrichment across your workflows.
The future of work isn't about answering one question faster. It's about applying consistent, repeatable AI reasoning across your entire dataset at scale.
Our latest blog post breaks down how we are building this at Clavy. Read it here: https://t.co/Ow59vo9SNA
We are living in the "Chatbot Era" of AI. But for complex, knowledge-heavy workflows, the standard chat UI is holding us back.
Chatting with one PDF is cool. Analyzing 200 of them? A copy-paste nightmare.
We need to rethink the interface. 🧵👇
At @ClavyAI, we believe the next phase of AI is moving from conversation to computation.
Treat documents as structured datasets. Define your extraction schema once, and run it across hundreds of files in parallel.
Turn unstructured PDFs into filterable spreadsheets.