Also that learning to code + developing is different is not that different from today where in school one is encouraged to build data structures, sort algos, etc. where those things aren't practiced in professional development.
But I do agree that the era of new programming languages developed for people is probably over.
You're both wrong. But, to understand why we must pull back the veil on what it means to learn to code,
Level 1: You learn to think in a certain logical way and can think in multiple layers of abstraction. This is going to be valuable regardless whether coding preserves.
Level 2: You have earned confidence and grit. Earned confidence only comes from struggling through real difficulty.
Level 3: As a byproduct of developing, you develop experience in building and shipping. It is true you don't need to code to get to level 3 but there's no path to level 3 without developing: you are already level 3 and see your coding isn't valuable.
Level 1 and 2 can be attained in 2 years provided one isn't using AI. Level 3 takes 10 years and there's no easy path to level 3 without being a developer.
While task of coding is easier, being a software engineer is now more difficult than before because there's no simple formula for getting to a level where one can provide value. Before, it was simple-- just specialize in something.
There's another distinction to be understood: the promise of coding was always a false-promise. Because the promise was always: learn to code and develop anything. That was never true because specialized knowledge gaps.
Here's how I'd structure a 4 year program for a developer of tomorrow, fwiw:
First 2 years: coding + developing with no AI permitted.
Second 2 years: focus exclusively on agentic development and specifically focusing on building loops, observability, security, devops, selling.
DeepSeek 4.1 1017 Quality?
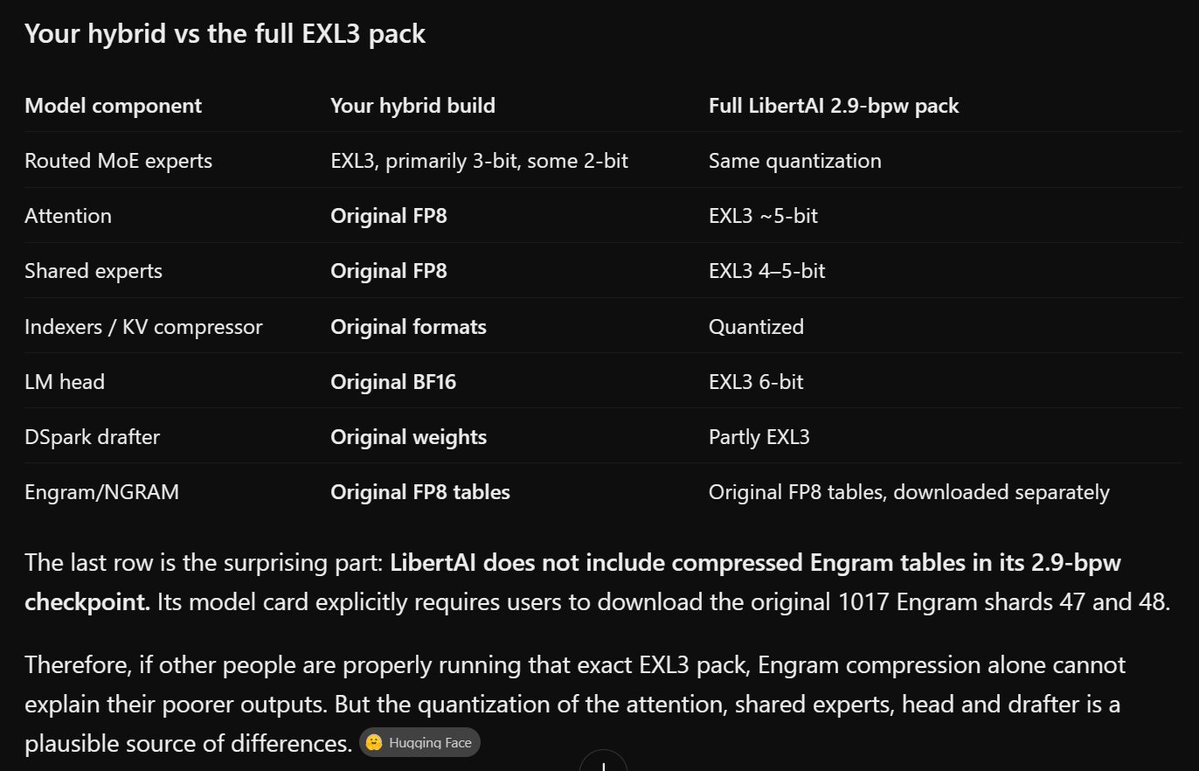
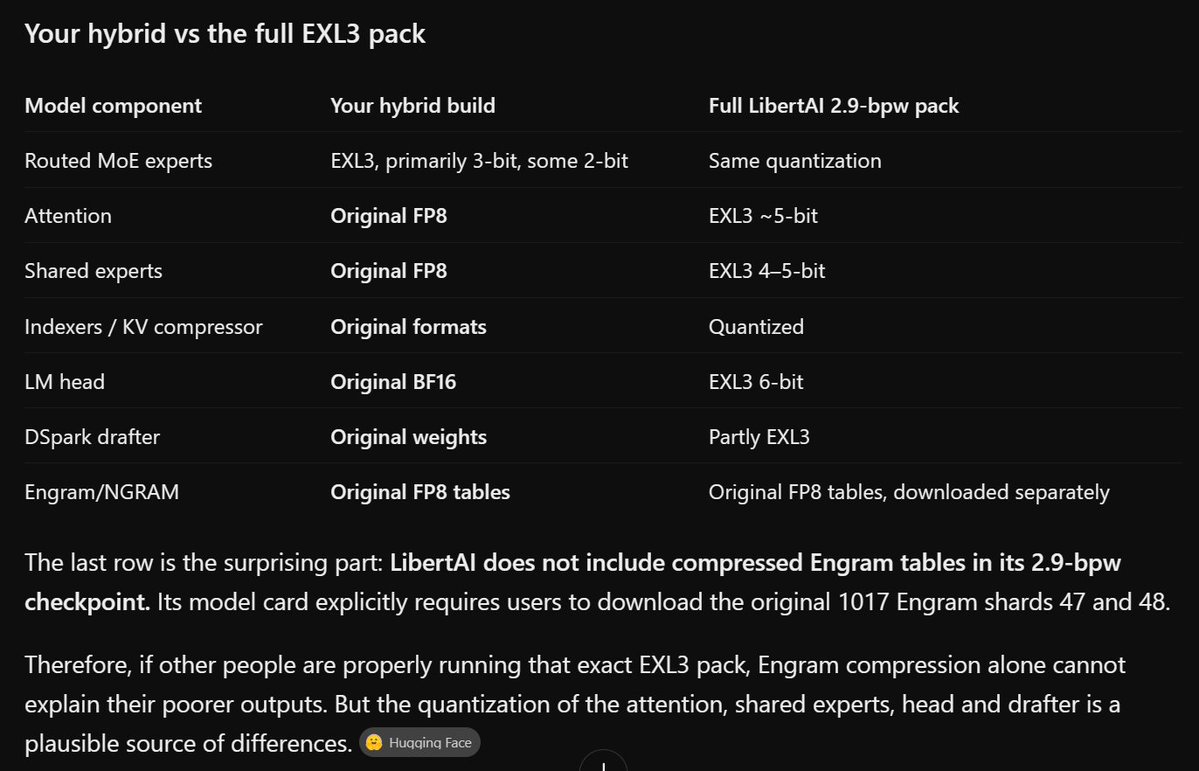
I notice some people reporting the EXL3 weights on DeepSeek 4.1 1017 produce poor outputs in reply to my build and others.
It has not been my experience with my build. It has been extremely strong in my testing. For example, I gave it a single prompt and it worked for 30 minutes building an extremely polished game that worked perfectly on a single prompt. And, I have it working on even longer run tasks.
But we did something different: we use some of the FP8 weights for important aspects.
I don't know if that makes the difference or if its the harness or server.
But, this model has impressed me and worked extremely well.
New DeepSeek v4.1 1017 Flash 4x CMP 170HX Optimizations
Real-world optimizations
- Optimizations proven on prose, code, and real-world agentic Hermes at kernel level.
New bit-exact kernel improvements stack on my previous work:
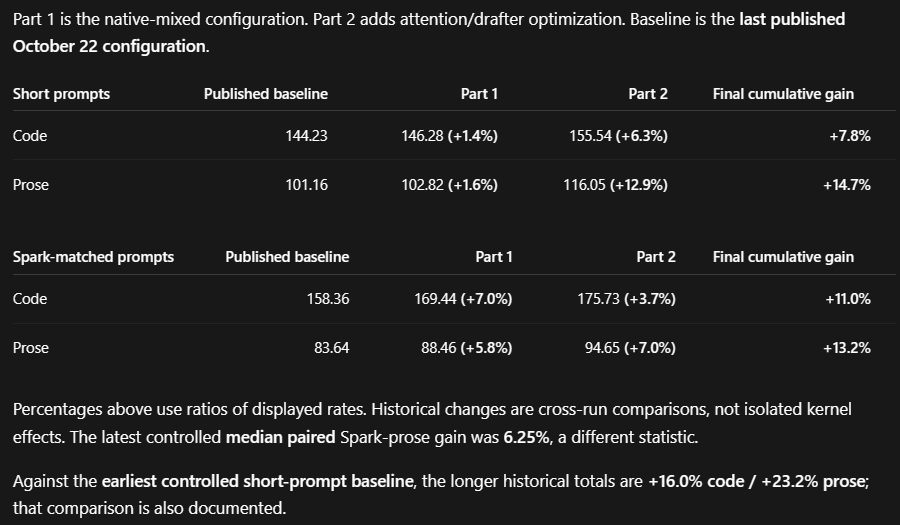
~9% cumulative from baseline, 2% latest
New attention + drafter
~16% code and 23% prose
- Not bit-exact but passed extensive A/B testing. Warrants additional quality confirmation and testing from community. Additionally, we don't claim a gain in concurrency needs additional testing.
Apply partial or both.
My machine is slower Broadwell: so will not match EPYC topline numbers but optimizations should transfer to other builds. Do take what works but give proper credit.
benchmarks and results 1017 https://t.co/FUy5Zg3g3l
base repo with kernel source and feature flags https://t.co/XzxOvQ0Gcn
Understand the sentiment but I haven't found it poor at all!
It has been truly excellent.
Do not assume my build is same as others: I use the full quality NGRAM weights.
I have seen it work for 30 minutes perfectly in Hermes on a single prompt to produce perfect working game.
Something to know:
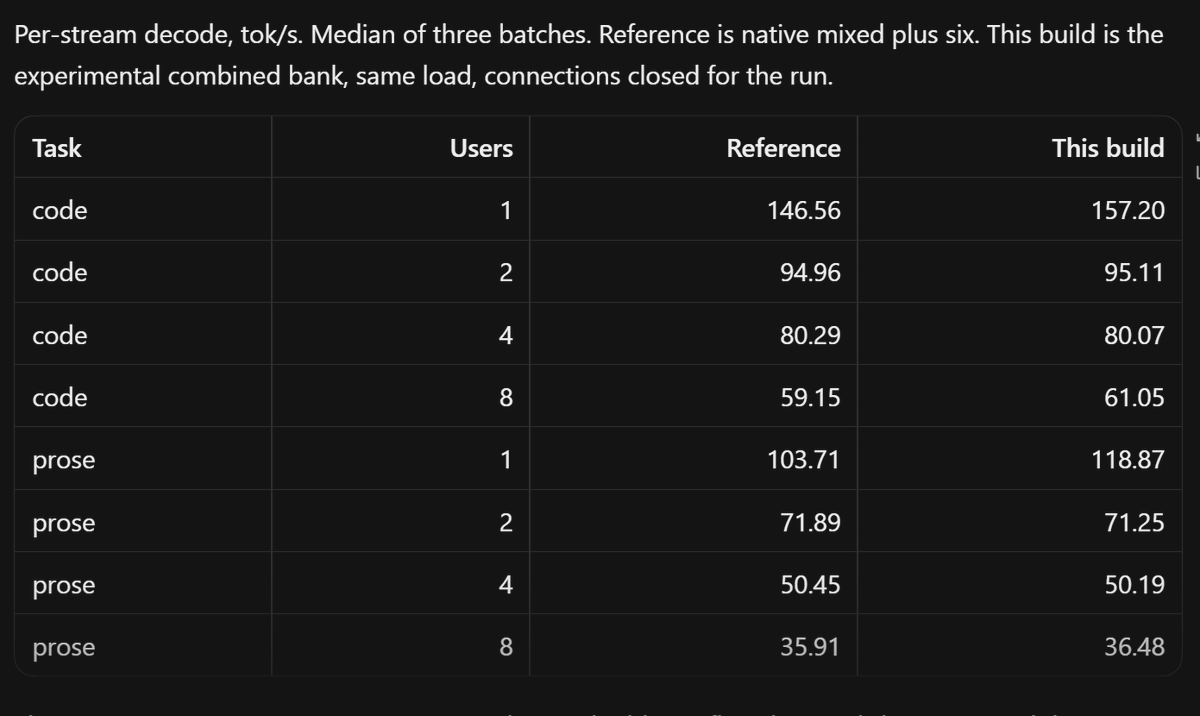
The largest perf gains, from the new attention + drafter, are only seen at concurrency/request depth 1 for now when more lanes are active, it does not use the new drafter and falls back to the previous optimized default.
This is not an inherent limitation though the relative advantage would likely decline at higher concurrency due to having more parallel work. In order to support multiple requests, requires batch-aware buffers.
The next obvious target would be request 2.
Example, on this sweep only users 1 is the new attention:
With Reddit banning open-source projects that have ANY AI contributions, here's a list of projects you can no longer discuss there:
Linux, Chromium, Firefox, WordPress, VS Code, Python, VLC, Blender, Git, Docker, LibreOffice, React, Node.js, PHP, TypeScript, Rust, Home Assistant, PyTorch, TensorFlow, Kubernetes, .NET, Angular, Go, Ruby on Rails, Ruby, PostgreSQL, Vim, nginx, Apache HTTP Server, FFmpeg, Redis, curl, OpenSSL, FreeBSD, Neovim, LLVM, GCC, systemd and QEMU
😂
Open source isn't as far behind frontier AI as it might appear because the frontier AI that's widely available is not the AI that leads on the benchmarks.
Codex used up in like 4-5 hours..
Weekly usage, codex credits from having Pro, and a reset used up in like 4 hours of use?
Should I be using Claude instead?
@machigurixmeru This is my Broadwell platform: okay for models that fit fully in vram but DS is a tough model.
Cheap EPYC is likely best bang for buck with 384GB-512GB DDR4.