@piriya A person holding the line at a hosted lab is a fragile defence. Open weights on a retrofitted RTX 2080 Ti 22GB, €699 delivered, are yours to run, no one else's to change.
https://t.co/lcqvhmm3K2
Chinese Big Tech Allegedly Burns 1,000 Claude Accounts Daily as Anthropic Tightens China Bans
A Chinese AI observer reported today that a major domestic firm is consuming at least 1,000 Claude accounts each day to distill Anthropic’s model for its own training. The accounts get burned through and replaced with fresh pools as bans hit.
The claim fits a pattern Anthropic has already described in public. Earlier this year the company accused Alibaba-linked operators of using roughly 25,000 fraudulent accounts for 28.8 million exchanges, and it previously named DeepSeek, Moonshot, and MiniMax in similar large-scale distillation campaigns. Anthropic has framed these as industrial efforts to extract frontier capabilities without the full cost of training.
On the commercial side, Claude’s web interface quietly added simplified and traditional Chinese options in early October. Days later, payment pages briefly showed China, Hong Kong, Macau, and Taiwan as billing regions, along with a UnionPay option. Chinese tech media confirmed the interface changes through hands-on checks, though Anthropic issued no announcement and its official supported-regions list still excludes mainland China, Hong Kong, and Macau.
That policy, clarified and effective November 12, restricts use by anyone physically located in unsupported regions, by entities headquartered there, and by companies majority-controlled from them. Travel to Hangzhou or similar cities can already trigger account flags for Chinese users, according to the same reports. Legitimate subscribers who pay for access end up as collateral when detection systems respond to the high-volume distillation traffic.
@EvanMarkham4 Account flags by region and traffic show remote control. Move to hardware you own. The Inference Station, 1× RTX 2080 Ti 22GB, €1,080, runs a model locally, without provider-side account bans.
https://t.co/lcqvhmm3K2
@philfung A compact laptop with large unified memory is appealing. For 128 GB of GPU memory we offer a liquid-cooled tower with four Tesla V100 32 GB cards. https://t.co/bg17XtXi6y
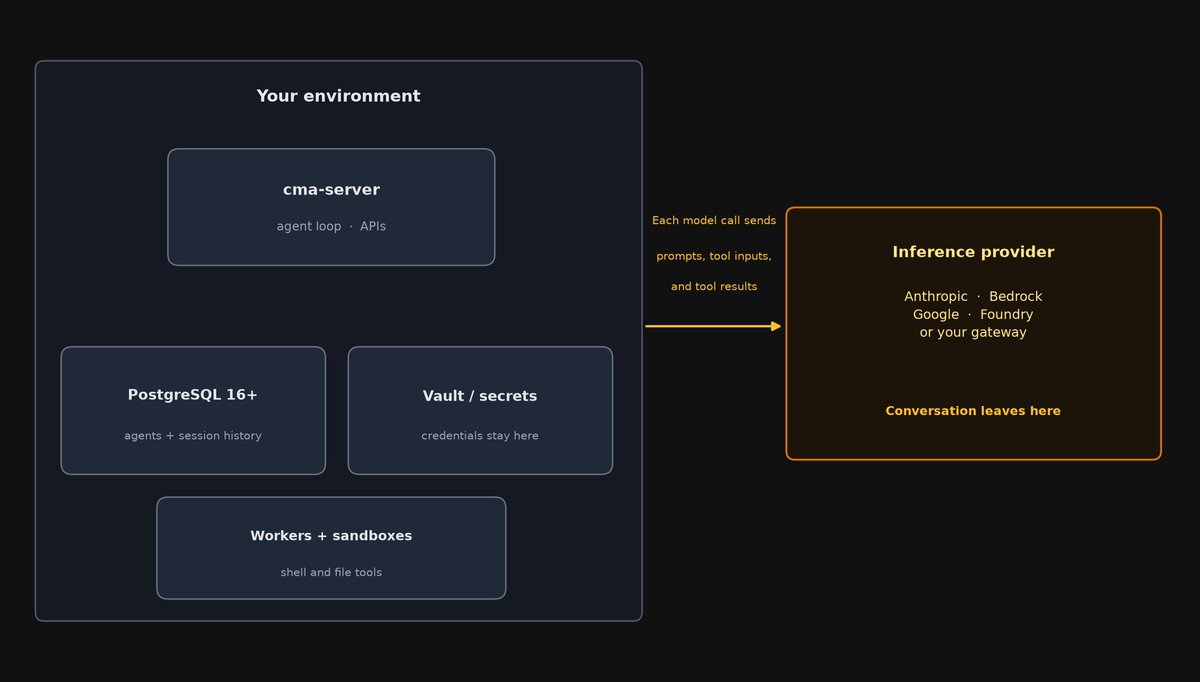
Self-hosted Claude Managed Agents is in private beta, and the constraint I care about is this: you can host the control plane, but every model call still sends the conversation so far to the provider you pick.
Anthropic's docs are explicit. Agents, credentials, and session history stay on your server and database. Model requests go where you choose: Anthropic, Bedrock, Google's Agent Platform, Microsoft Foundry, or your own gateway. Each call carries prompts, tool inputs, and tool results.
What I'm checking before I even request access:
1. pick the inference provider on purpose, don't leave it on the default Claude API just because that's the default
2. stand up PostgreSQL 16+ on day one — with no database, a restart wipes agents and history
3. treat zero data retention as applying only to those model calls, the same way it does for the Messages API; the transcripts themselves live in your database
If the conversation still leaves the building, what else has to stay inside the perimeter for this to be worth running?
@HaStrive If model calls still leave, the inference itself must run on your own GPUs. A 4× Tesla V100 32GB Liquid-Cooled Tower costs €7,900 and keeps weights local.
https://t.co/lcqvhmm3K2
Pope Leo XIV wants clear boundaries between human art and AI, while @pewdiepie just launched an uncensored model called Ajax after getting banned from major platforms.
https://t.co/ZThOQwRinh
@AnthropicAI#PewDiePie#AjaxModel#AIEthics
@ainewssmoothie@pewdiepie@AnthropicAI When an open model runs on your own hardware, you set the rules. On someone else's server, bans and refusals can arrive.
https://t.co/lcqvhmm3K2
@swarogan Running massive models on CPU and RAM alone is impressive. GLM-5.3-Flash at 4-bit is 193 GB. Our 8x V100 32GB node holds all of it in GPU memory: 256 GB of VRAM in one 4U server. https://t.co/7Su0z8Lb4L
@ZyphraAI@ArtificialAnlys@AMD GLM-5.3-Flash at 4-bit is 193 GB. Our 8x V100 32GB node holds all of it in GPU memory: 256 GB of VRAM in one 4U server. https://t.co/7Su0z8Lb4L
@martiano That token speed is reasonable for local inference. We offer a retrofitted RTX 2080 Ti, 22 GB at 616 GB/s, for local models. https://t.co/QjQR9IH4dm
@beingsalluu GLM-5.3-Flash at 4-bit is 193 GB. Our 8x V100 32GB node holds all of it in GPU memory: 256 GB of VRAM in one 4U server. https://t.co/7Su0z8Lb4L