The usual MoE story focuses on sparse FFN experts.
MoVA asks a different question: what happens if sparsity is introduced into the value computation of attention too?
K2-Horizon-36B-A4B is built around exactly that idea, with ~4B active parameters per token.
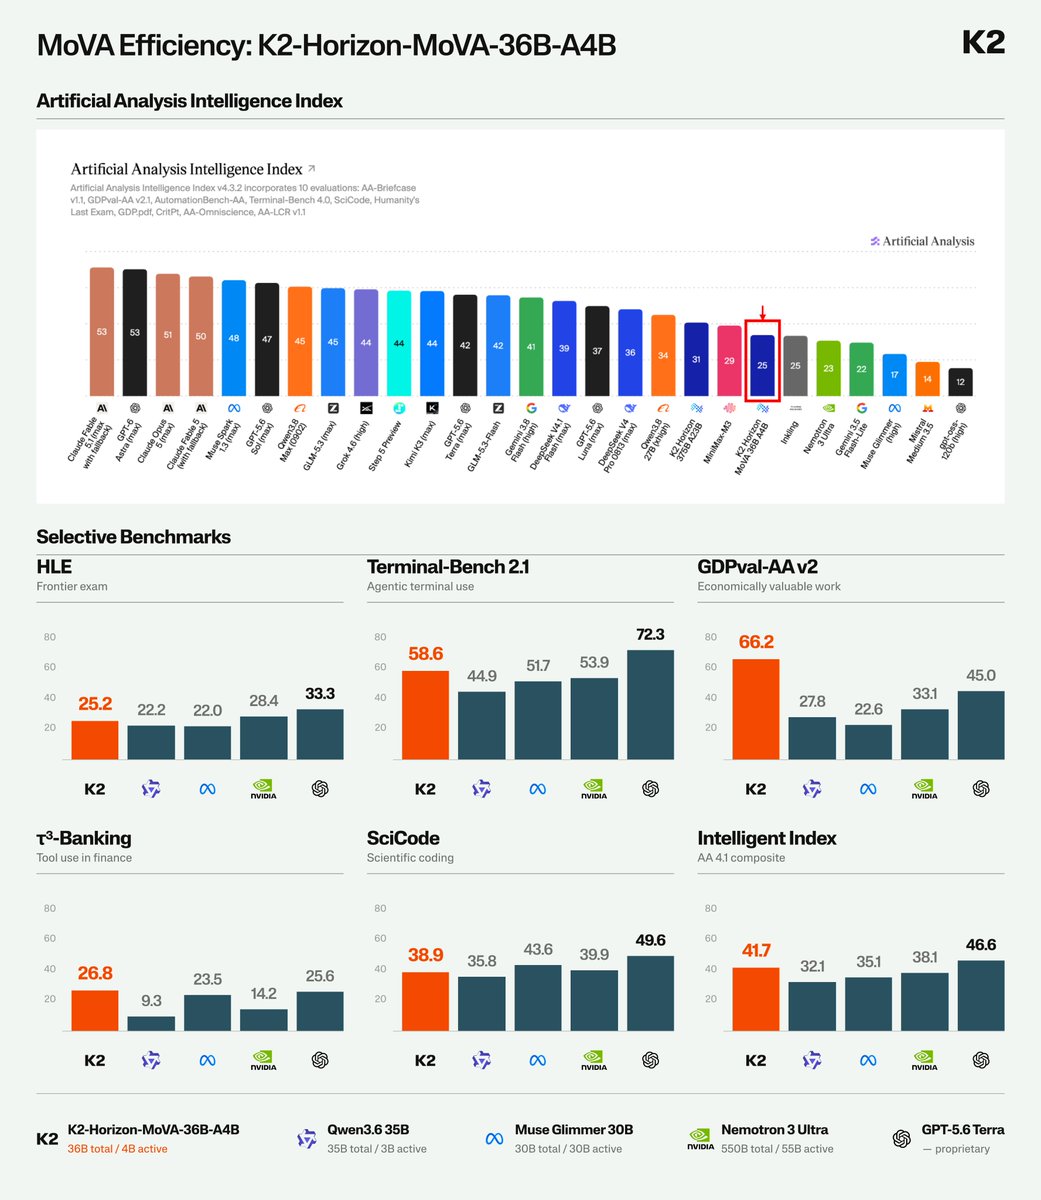
K2-Horizon-36B-A4B scores 25 on the Artificial Analysis Intelligence Index, matching models with over 20× the total parameters while using 4B active parameters per token.
These capabilities come from our new architecture MoVA (Mixture-of-Value Attention), which incorporates MoE-based sparsity into the compute of value vectors in multi-head attention.
It opens a second axis for scaling sparsity in an LLM, beyond MoE in the FFN module. Importantly, MoVA enjoys the following advantages:
• Simple and compatible with efficient attention algorithms, such as flash attention, GQA, and sparse attention
• No additional KV cache cost comparing to standard GQA
K2-Horizon-36B-A4B available at: https://t.co/lH2BYBdU0a