Faculty at UKY. Views my own, not of my employer(s). Work: #BioNLP, #NLProc, medical informatics, machine learning, LLMs, AI & fairness, health+socialdata
If you've noticed a distinct dialect emerging in frontier AI models and struggled to understand what they're talking about, you're not crazy!
We turned to psycholinguistics to investigate what makes the writing style so weird, and why this might be happening
🚨New preprint! 🧵
Introducing Carbon-X: The best open DNA model.
We midtrained a 14B model on DNA and text, and it beats every open language model and matches GPT-6.1 Sol at 1,000x lower cost.
Ask it about a sequence, what a mutation does, or to generate new DNA.
https://t.co/cpZCkEHHmn
Today we're releasing Carbon-X, a 14B model that brings DNA and natural language together for the first time 🧬
1. Beats every open language model we tested across DNA benchmarks. Within a point of GPT-6.1 Sol at >1,000× lower inference cost.
2. Mid-trained on 300B tokens of interleaved DNA and text, followed by SFT (without distillation!) and RL.
3. A new hybrid tokenizer encodes DNA using ~3× fewer tokens than BPE.
4. Gives other models a DNA specialist subagent: Kimi K3 gains 11.1 points when it consults Carbon-X.
5. Runs locally on a laptop with llama.cpp. Apache 2.0. Your DNA stays on your hardware.
Model: https://t.co/7wBE7WUVp1
Blog: https://t.co/A3OjalTpIJ
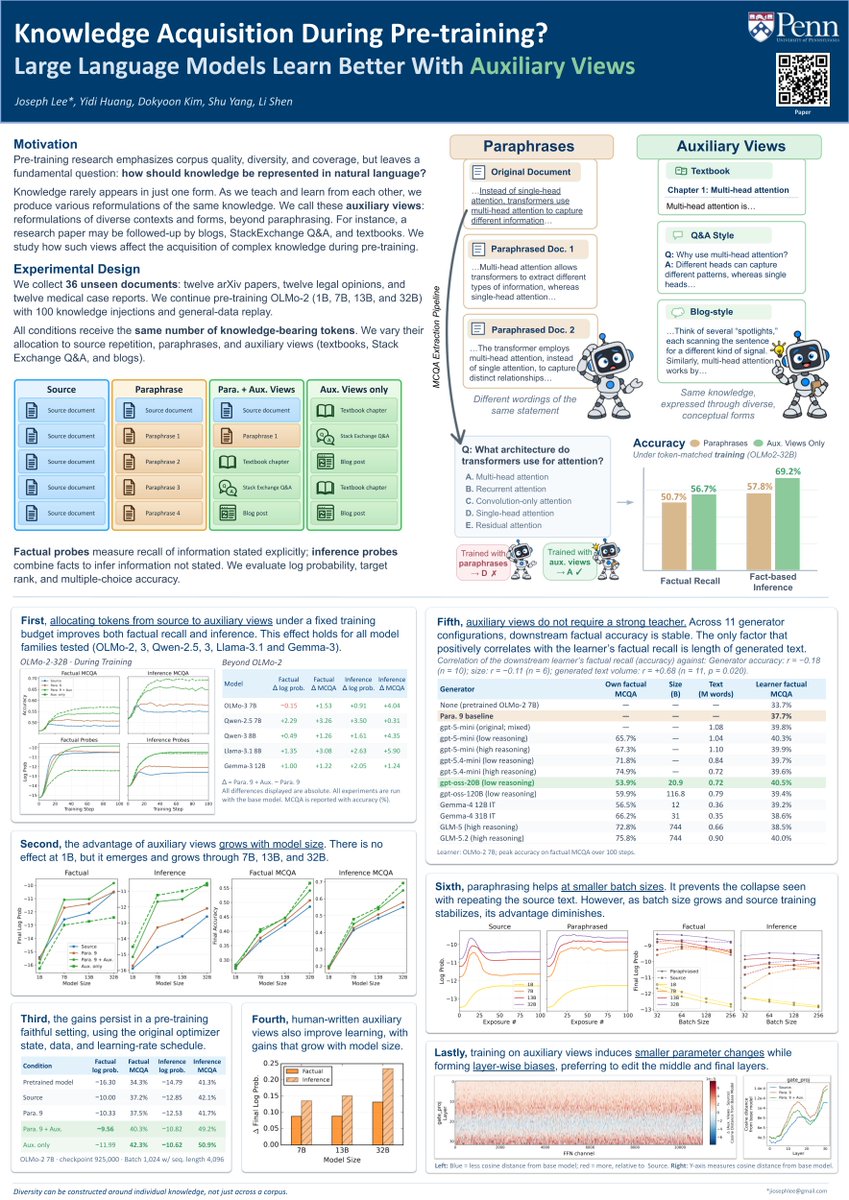
💡 Training on auxiliary views of Document X > training on Document X itself, even for factual questions drawn directly from X.
Presenting our work on LLM knowledge acquisition at #EMNLP2026 this weekend!
(1) Under a fixed token budget, conceptual reformulations (textbook explanations, blogs, and Q&A) can teach a document’s facts more effectively than repeating the document, even paraphrased.
We call these auxiliary views: beyond mere paraphrasing, they discuss the knowledge in a completely different context and form e.g. a paper blog!
The surprising part is that auxiliary views rarely mention the facts directly, but our evaluation uses the original document's phrasing near-verbatim.
(2) The benefit emerges and grows with model scale.
(3) stronger generator ≠ better learning.
We synthetically generate auxiliary views for our experiments, but across GPT-5, GPT-OSS, Gemma4, GLM-5 and more, the learner model's knowledge acquisition shows no correlation to generator model size or its own accuracy on the evaluation.
(4) After training on auxiliary views, the model's parameters actually move less but concentrate its changes at the middle and final layers.
The takeaway for synthetic data augmentation: build diversity around the knowledge you want to teach, instead of treating diversity as some board corpus-level heuristic.
Also, a possible implication for LLM self-improvement. Models can learn by just generating and training on their own auxiliary views, without a stronger teacher. This is particularly relevant for deeply specialized, long-tailed knowledge.
📄 Paper: https://t.co/hPhT1Ads27
🚨 New Paper! 🚨
Multiple-choice benchmarks use accuracy (boring), but education has way cooler scoring schemes! 🤩
👎 Lose points if wrong
🔁 Try until you're right
🃏 Wager points
At #EMNLP2026, we show these schemes shift LLM ranks, align with LLM Arena, + unmask LLM quirks
Super excited to share SnapJudge -- a free, open detector trained for scientific and math-heavy writing, and can handle multiple modalities, including screenshots of paper text, LaTex, and text extracted from PDFs... 🧵
Can research agents get better at science by learning from the research they do?
Introducing DiscoveryRSI 🧬: a framework that turns hypothesis-driven research into a recursive self-improvement loop.
📄 Paper: https://t.co/aBpR5GcChg
💻 Code: https://t.co/XjUmq6xt6a
🔴 Live Arena: https://t.co/Z4F6k8fqDT
🔹 What is a valuable hypothesis?
We define it as a joint object H = (claim, investigation plan, decision criteria, alternative explanations). A hypothesis is valuable if resolving it would change a research decision. It is testable if the plan can produce evidence that supports, weakens, or bounds the claim.
🔹 How it works
- Lead, Generation, Evolution, Critique and Progress agents grow hypothesis trees through evolve / repair / crossover / restart
- Every version stays linked to its evidence, data, assessments and contribution records
- Selected plans compile into executable Harbor tasks
🔹 Three self-improvement mechanisms
① Hypothesis credit optimization: blinded TrueSkill assessments assign bounded credit to the agent steps that actually contributed, and DiscoveryRSI-27B is trained only on those steps (Qwen3.8-27B init, 256K context; 2,397 of 15,792 trajectories kept; 2.12% of tokens supervised)
② Harness replay: diagnose recurring failures such as repeated exploration, failed tool use, lost artifacts and premature closure, then refine the workflow
③ Rediscovery: run the accepted model and harness updates on fresh questions
🔹 Results (DFM-Bench, 4 life-science domains)
- Hypothesis quality 4.86 → 5.18 → 5.39 over two rounds
- Falsifiability 4.00 → 6.20, alternative explanations 4.44 → 5.98, data resolvability 3.73 → 4.99
- Evolve/repair share 77.5% → 91.7%, restarts 21.7% → 5.0%: the agent learns to keep developing an idea instead of starting over
- Caveat: importance and novelty dip slightly. The model learns to design better tests, not yet to choose bolder questions.
🔹 Expert review
27 physicians and bioscience researchers scored 292 anonymized proposals:
- 41% of DiscoveryRSI-27B revisions improve quality vs 31% (GPT-5.6 Sol) and 25% (GPT-6 Luna)
- Only 12% make things worse vs 32% and 31%
🔹 Does it anticipate real science?
Against 16,440 publications filtered by each model's cutoff, 6.3% of DiscoveryRSI-27B's hypotheses connect to later published research (16.9% in therapeutic targets). Comparison: DeepSeek 5.4%, GLM 2.8%, GPT 2.5%, Claude 2.3%.
Watch six models do research in real time in DiscoveryRSI Arena, and follow every proposal, critique and compile step 👇
https://t.co/Z4F6k8fqDT
Co-led by Jianyuan Zhong, Chenwei Wu & Zhaochen Yu, with wonderful collaborators across PhAI Labs, CUHK, Stanford, MIT, Harvard Medical School, Oxford, Princeton, PKU and more.
Grateful to @james_y_zou@Jiaru_Zou@Charles_Y_Wu@zhenfei_yin_yzf 🙏
Along the same lines, I also don't understand their "model welfare" spiel: https://t.co/ZBkxGDfZPZ
They justify this by citing a report by other people, but they also funded that report :-)
I've avoided critiquing since I have a lot of friends at Anthropic, but the anthropomorphization of Claude is dangerous. Roughly, it's a large transformer with a sophisticated training set (pre, mid, post/RL) that is extensively trained in RL "game worlds" mimicking useful real world situations. In some fundamental sense it's not that different from say AlphaGo except for the fact the enormous number of parameters means it can play a lot of different games (e.g., the game of maximizing human response). This is a very neat technology but treating it like some sorcerous creation is dangerous. I don't believe Anthropic folks are cynics. I think a lot of them genuinely believe this is a recipe to create a sentient being. If this is in fact true (which I question heavily), open scientific enquiry will reduce suffering. Sunlight cleans shadows. The secrecy and cloak and dagger is harmful to society.
1/ RL for improving task success has made LLMs remarkably capable. But what happens when the model fails? Turns out, training for graceful failure can be surprisingly tricky!
Very excited to share our new paper: Training Language Models to Fail Gracefully
🧵
Researchers tend to have their best, most innovative ideas early in their careers. But for decades, researchers have had to wait longer and longer to test their own ideas.
Thrilled by the progress we’ve made so far on this front, including the huge milestone of setting a new record for grants supporting early-stage investigators.
🧵[1/N] Are large language models more creative than humans at combining ideas? 🤔
Combinatorial creativity involves combining familiar ideas in unfamiliar ways, and is central to scientific discovery and technological innovation.
In fact, breakthrough scientific work is often associated with more distant combinations of methods, techniques, and concepts.
Here, we introduce Kombine, a new benchmark of combinatorial creativity for LLMs.
TLDR:
- LLMs are more combinatorially creative than the average human.
- However, conceptual blending is the hardest task for LLMs, and even frontier models struggle.
- LLMs also tend to homogenize, inventing concepts with the same properties across separate models.
- Moreover, humans and LLMs combine in distinct regions of semantic space.
- As a result, we anticipate greater conceptual diversity can be unlocked through human-AI collaboration. 🗣️
Thread below🧵⬇️
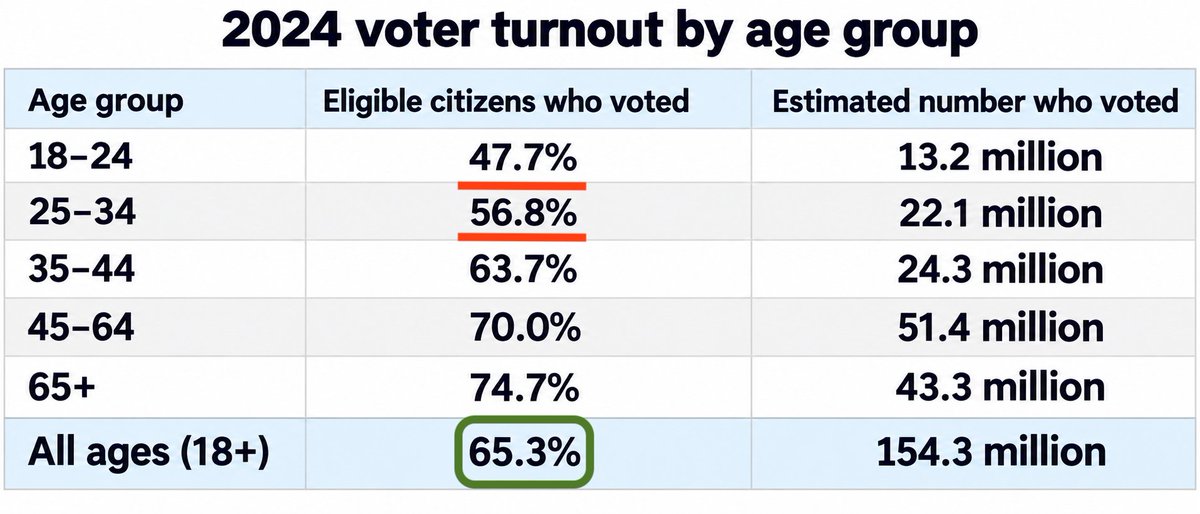
Young people, don't ignore midterm elections. Policies have long terms consequences for u & ur voice needs to be heard. Ur voting rate is already low during presidential elections & I am scared how awful it would be during midterms. Please vote on 11/3 (early voting is easier)
Today we are presenting "Autorubric: A Unifying Framework for Rubric-Based LLM Evaluation on Non-Verifiable Tasks" at #COLM2026
If you are doing evals or reward modeling, you will want to tune in. A short thread to introduce this work 🧶
We've updated our GitHub math repo with 6 new Lean formalizations, 19 modifications, and 3 withdrawals. The repo now has ~42% top-line results formalized. We will continue to update the repo with new formalizations and with any errata we notice.
https://t.co/HI6otY2NTO
How awful is this practice. I was a student in theoretical computer science in the 2000s. I know several research students got unpleasant surprises with the uploads on 10/6. The bulk upload of proofs without Lean formalizations was okayed by all the geniuses at this firm 🤦♂️
We've updated our GitHub math repo with 6 new Lean formalizations, 19 modifications, and 3 withdrawals. The repo now has ~42% top-line results formalized. We will continue to update the repo with new formalizations and with any errata we notice.
https://t.co/HI6otY2NTO
@danintheory You have a theoretical computer scientist in your midst who is doing AMAs and constant shilling on your behalf and he okayed this fiasco lol.
Is it me or do LLMs cite more papers from open access publishers (especially, JMIR, Frontiers, MDPI) compared with potentially more impactful/rigorous studies published in venues that are subscription based? Maybe it's a side effect of full text offering LLMs more confidence.
WildChat, LMSYS, ShareChat… each human-LLM chat dataset aims to capture "real-world" AI use. But do they paint the same picture?
Not quite. From user messages alone, a classifier can name a chat's source dataset, and user models trained on them inherit these signatures 🧵👇
What if,
for any scientific claim,
you can search 100M+ papers to find the strongest evidence for and against it
⚡️in 1 second?
That’s now possible with Evidence API! 🚀
https://t.co/2I25q4m9ao
For example, does drinking coffee reduce diabetes risk?