To maintain this hunting posture, the a kestrel flies into, and at the same speed as, the oncoming wind – the current of air passing over its wings provides the lift it needs.
如果 AI 把大部分人的工作都替掉了,没人拿工资,那 AI 生产出来的东西到底卖给谁?
这个问题听起来很简单,但继续往下推,会撞到 AI 经济学里一个很大的漏洞:企业 individually 有动力自动化,全社会一起自动化,结果未必一样。
Luca Fornaro 与 Martin Wolf 在 2026 年的《Macroeconomic Policies for AI》中严格论证了这种状态——AI 驱动型萧条(AI-driven slump)。
其核心机制并不是简单的“机器抢工作”,而是一场无可挽回的宏观合成谬误(Fallacy of Composition):
企业视角(个体最优): 任何一家理性企业采用 AI 替代劳动力、压降边际成本,都是教科书级的占优策略;
宏观总和(集体恶化): 当所有企业同步推行这一理性决策时,宏观经济中的工资总额(Wage Bill)断崖式下跌。在传统经济中,劳动报酬占 GDP 的比重(Labor Share of Income)是维系居民端总需求的最核心支柱。
个体企业用 AI 裁员降本 ──> 行业全盘跟进 ──> 全社会总劳动报酬萎缩 ──> 居民终端消费能力骤降 ──> 产能过剩/反噬企业营收
这就是典型的合成谬误:每一个决策在局部都是完全正确的,加总起来却使整个系统滑向不可维系的深渊。
Researchers at Oxford argue that LLMs can't invent anything.
It's impossible mathematically.
The paper is called "Theory Is All You Need."
Teppo Felin and Matthias Holweg take the famous "Attention Is All You Need" title and flip it. Their argument is that AI predicts from the past, while humans reason forward into the future, and those are two different kinds of thinking.
Start with the numbers. The authors estimate a large language model trains on roughly 13 trillion tokens. A human reading at 150 words a minute would need about 164,000 years to get through that. A child hears around 20,000 words a day and roughly 36.5 million words in their first five years. It's the same task with wildly different data, and the child still ends up with language that goes far beyond anything they heard.
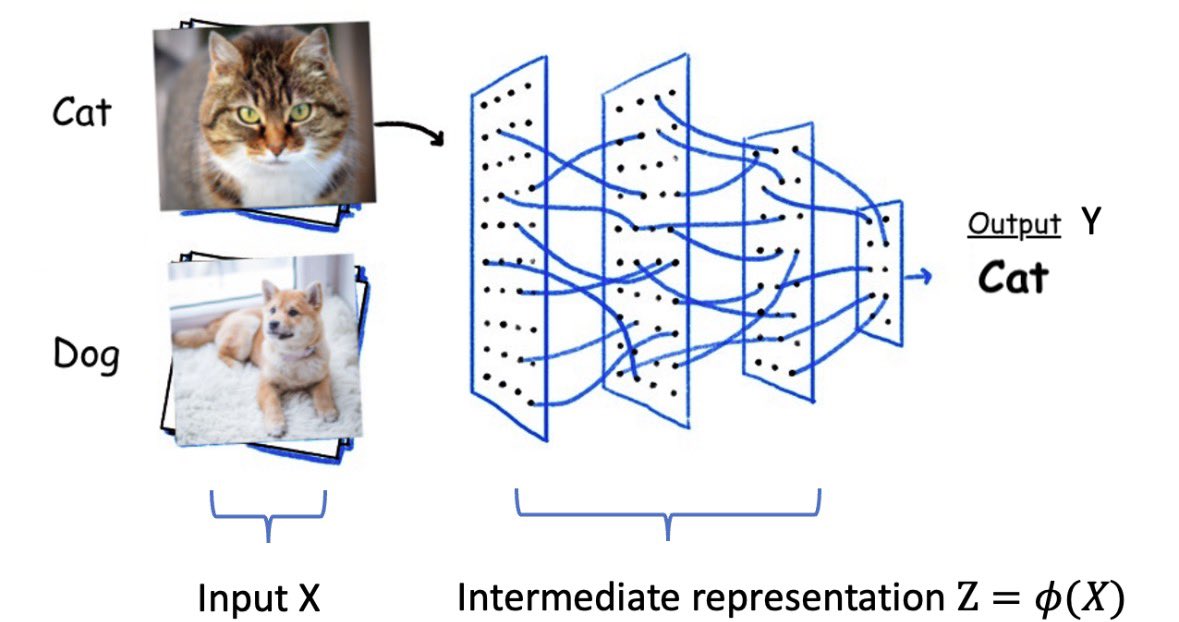
Their point is that the model learns which words tend to follow other words. It becomes a mirror of what people have already written. It doesn't build a theory of how the world works, so it can't step outside its training data.
The paper's sharpest thought experiment makes this painful. Imagine an LLM trained in 1633 on every scientific text ever written up to that point. Ask it about Galileo and heliocentrism. Thousands of years of geocentric texts would swamp Galileo's ideas, so the model would tell you he's wrong. It would also rate Tycho Brahe's astrology as more credible than the idea that the Earth moves, because more people had written about astrology.
Then there's flight. In 1888 the scientist Joseph LeConte looked at bird data, noted that no bird above 50 pounds could fly, and concluded humans couldn't either. Lord Kelvin, then president of the Royal Society, said he had not the smallest molecule of faith in aerial navigation.
The New York Times estimated in 1903 that flight was one to ten million years away.
Nine weeks later the Wright brothers flew.
The Wrights didn't have better data. They had a theory. They broke flight into three problems, lift, propulsion, and steering, built their own wind tunnels, and generated the data that didn't exist yet.
Wilbur wrote in 1900 that he had been "afflicted with the belief that flight is possible to man."
Every prediction machine on Earth would have told him no.
The authors call this the data belief asymmetry. Every real breakthrough starts with someone believing something the existing data says is wrong. A system trained to minimize surprise can't do that by design.
They're not anti AI. They say AI will win at routine, repetitive decisions that extrapolate from the past, which is most decisions. They're just pushing back on the idea that you should replace humans with algorithms whenever possible, which is a direct quote from Kahneman.
I use these models every day and this matches what I see. The new stuff comes from the human at the keyboard who decides the data is wrong.
LLMs don't think, you do!
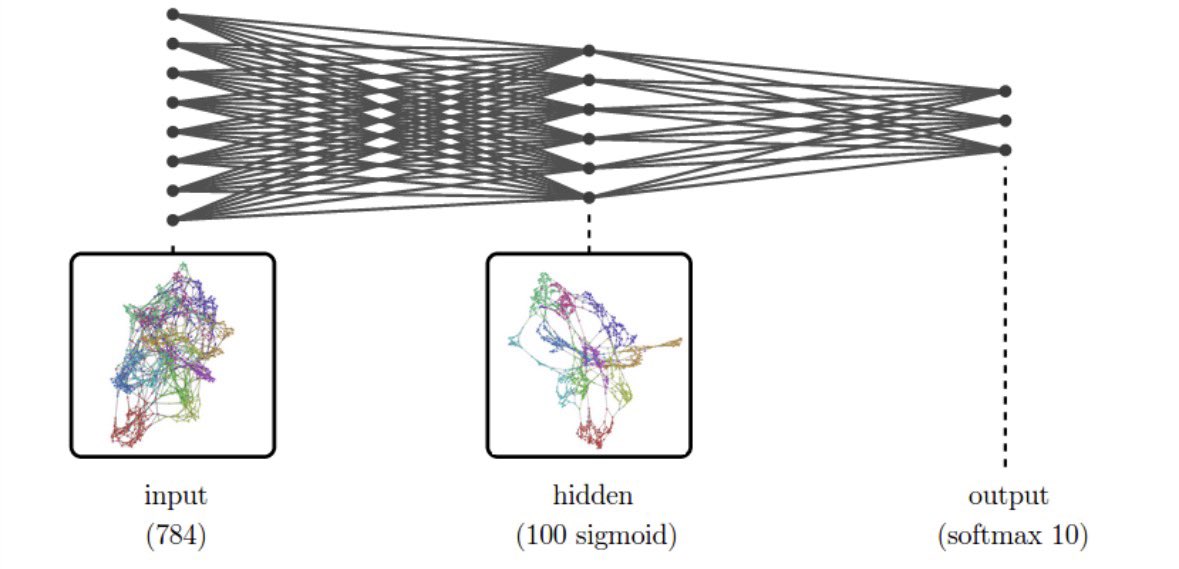
Gradient descent doesn't find the global minimum - it finds whatever valley it falls into first. Every LLM trained today gets stuck in a local minimum and nobody can prove the solution it found is anywhere near optimal. The loss landscape of GPT-4 has more dimensions than atoms in the observable universe.
Convex optimization guarantees a global minimum exists and gradient descent finds it. Non-convex optimization - the kind every neural network uses - offers no such guarantee. The entire field of deep learning is built on the empirical observation that local minima are good enough.
22 minutes. Bookmark & watch today. The math behind every AI training run - and why nobody fully understands why it works.