Infra / Cloud / System Dev | VMware, KVM, OpenStack, AWS | Python & Java | MLP from scratch / AI fundamentals / Ethical hacking | Aiming to work globally 🇨🇦
📝 Tiny Transformer Decoding Layer Notes #1 - Appendix B
I organized my current understanding of the backward flow:
Cross Entropy → Softmax/Logits → Weights, Bias, and Input
👉 LinkedIn (full explanation):
https://t.co/We2OTSPKcn
#AI#Transformer#MachineLearning
📝 Tiny Transformer Decoding Layer Notes #1 - Appendix A
I organized my current understanding of the forward computation flow:
Linear → Logits → Softmax → Cross Entropy
👉 LinkedIn (full explanation):
https://t.co/EklzyfNDWJ
#AI#Transformer#MachineLearning
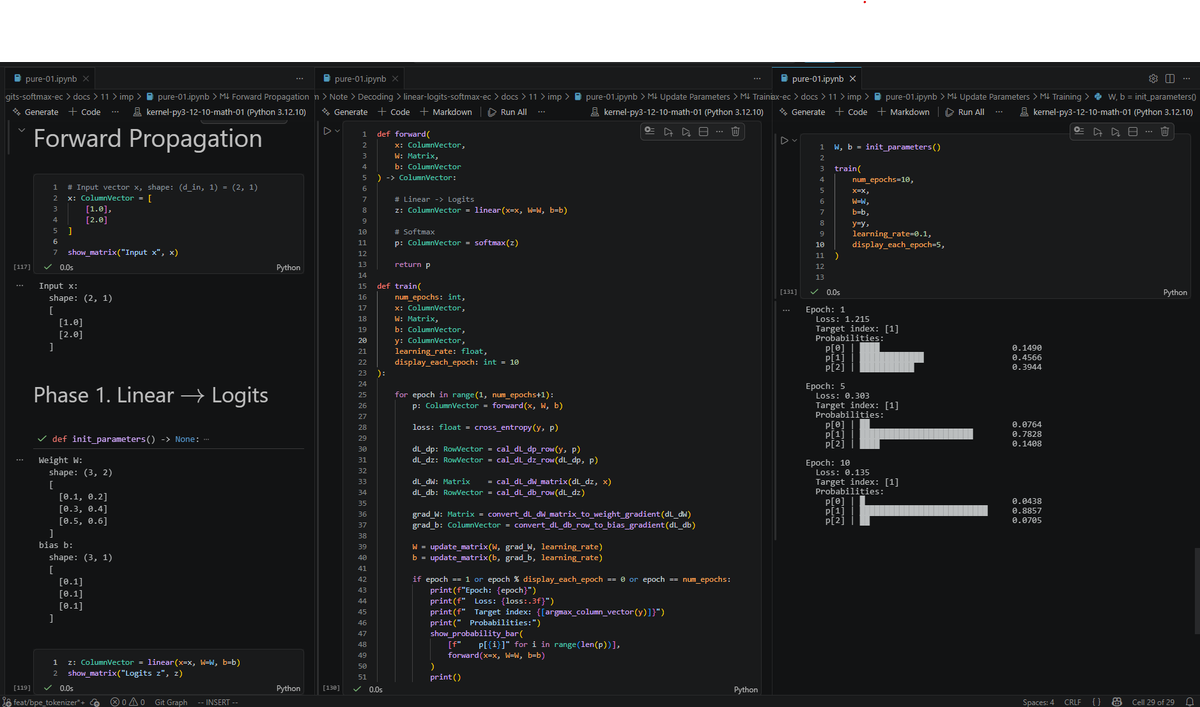
Implemented a tiny part of the Transformer decoding process in pure Python.
Linear → Softmax → Cross Entropy → Backward → Update
A small step, but it helped me understand how the output layer learns to increase the probability of the correct next token.
#Transformer#Python
Web 3d explorer for @oxidecomputer. Built in three.js/r3f.
Tonnes of little interactions and details in this. Poke around, and take a look at the guided tours.
https://t.co/NBySQcGCjE
Why do we divide by √d in attention?
I tried to understand it from the variance perspective.
👉 LinkedIn (full explanation):
https://t.co/7vmDSV2kku
#AI#Transformer#MachineLearning
found a website where you can create, program and test electronic hardware. it already has some featured projects
really great if you want to test before building your own hardware
🛠 Hands-on: Building a BPE Tokenizer
I struggled to understand the merge process and re-implemented the BPE tokenizer several times.
Based on what I learned, I organized everything into a hands-on guide.
Full guide here ↓
https://t.co/I5Ea1TaMxl
🤔 Why is KV cache needed in masked self-attention?
In my previous post, I calculated masked self-attention by hand.
This time, I break down why KV cache is necessary.
Full explanation here ↓
https://t.co/ysOQU25gNY
🧮 Calculating Masked Self-Attention by Hand (2026/02/14)
Recently, I became curious about the logic behind masked self-attention.
To deepen my understanding, I worked through the calculation step by step and organized my notes.
#AttentionMechanism
https://t.co/s3i6laOlja
Many references say encoder representations are well-structured.
But if the decoder dominates and even unstructured reps still produce correct outputs…
then can we really say that explanation still holds?
#Transformer#LLM
【お知らせ】
地球観測データを生成AIから呼び出せるようになりました!
最新の「JAXA Earth API for Python」v0.1.5にClaude Desktopで動くMCPのサンプルコードを追加しましたので、ITエンジニアの皆さん、ぜひ遊んでみてください!
https://t.co/UAFDOBA92Z