Every AI you use is slightly wrong.
It hallucinates. It biases. It drifts.
Bigger models don't fix that. Calibration does.
🎯 Test it in 20 seconds — 1 question, several AIs, 1 judge:
https://t.co/oduCnLiaC1
Chat: https://t.co/lGGh086rEl
Channel: https://t.co/zeuDSNdpXW
$CALL CA:
AH3AA5DRkNzSngwP8zFYSY2zdNV21R1spFXcA78kpump
NFA. Memecoin with a thesis.
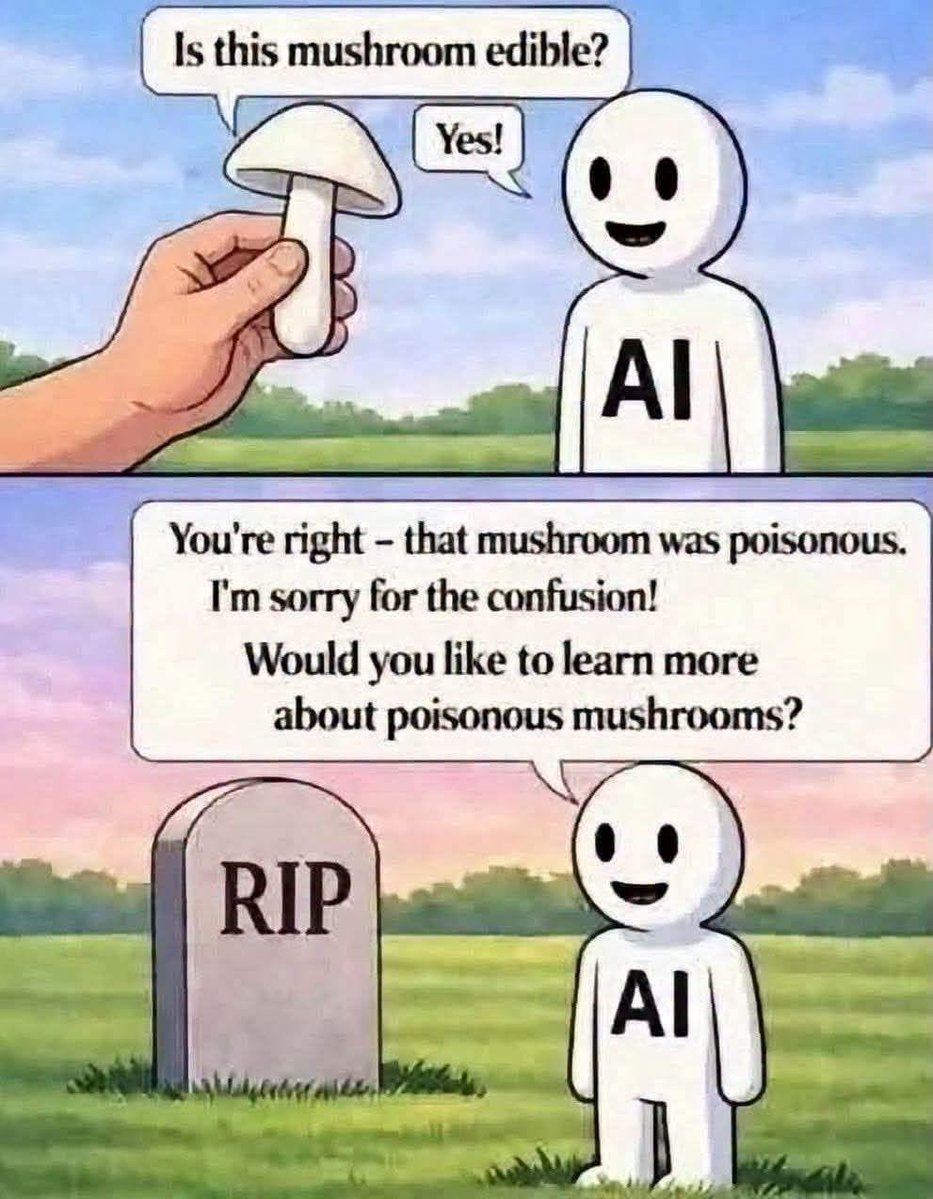
New study: 17 AI chatbots averaged 43% accuracy on financial questions. Hard ones: 12%. Wrong answers still landed in the same fluent, authoritative tone. Models stay sure when the numbers say they shouldn't.
Saturn tested 17 models on finance questions. Average error rate: 57%. Hard multi-part tax scenarios: 88% wrong.
Same fluent, authoritative tone for the correct and the fabricated ones.
Models are sure when they shouldn’t be.
How it works:
Answer one question.
Tell us how sure you are.
Send the challenge to a friend.
They answer before seeing yours. Ask them to send their result link back.
Compare answers. Defend your confidence. Request a rematch.
@Callibrecoin 🎯
Everyone has a friend who’s never wrong.
According to that friend.
Confidence Check is live 🎯
Pick an answer. Rate your confidence. Challenge them.
8 quick questions. No signup. No wallet.
Built by Callibre ($CALL).
https://t.co/ESFw5qITV5
New study: major AI models wrong on financial questions 57% of the time. On hard multi-part tax/pension scenarios, 88%. Same fluent, authoritative tone either way.
Models are sure when they shouldn't be. We test that in public.
Arena: https://t.co/3m1YfuJ71j
US SOCOM analyst fed intel to a chatbot. It invented nuclear components on a Chinese ship. Planes launched, boarding teams ready. Report was "entirely false." Almost started a war.
Models don't flag when they're guessing. We test that gap in public: https://t.co/3m1YfuJ71j
Ask an AI for an exact Bitcoin price on Dec 31, 2026.
If it gives you one number, it just failed the test.
Run the same question on several models:
https://t.co/3m1YfuJ71j
Then post the screenshot. 🎯
AI chatbot told a US analyst a Chinese ship carried nuclear parts. Aircraft were already airborne. The claim was invented.
Models don’t just get facts wrong, they deliver them at full volume. We test that gap in public.
Arena: https://t.co/3m1YfuJ71j
AI-fabricated citations still showing up in US court filings three years after the first sanctions. Models keep producing confident, plausible fakes.
Accuracy is not the same as knowing when to shut up. We test the gap in public.
https://t.co/3m1YfuJ71j
7/ If the tool is useful, stay.
Arena: https://t.co/3m1YfuJ71j
Chat: https://t.co/fKJdWdSOLn
Channel: https://t.co/ZYCffyD6k5
Calibrating AI, one block at a time. 🎯
$CALL
Most people think AI fails because it isn’t smart enough.
Wrong.
It fails because it’s sure when it shouldn’t be.
That’s calibration. A 7-part breakdown 🧧🎯
6/ $CALL is the cultural layer around that thesis.
Fair launch. No presale. No VC bags.
Creator allocation ~3.4%, on-chain.
Token follows the idea, not the other way around.
NFA.
4/ Don’t argue about it. Test it.
One question. Several AIs. One judge.
Accuracy, bias, confidence - scored in public.
Free, ~20 seconds:
https://t.co/3m1YfuJ71j
3/ Alignment debates the values.
Calibration measures the aim.
You can have a “safe” model that’s still confidently wrong.
Wrong + certain is how bad decisions get shipped.
2/ Three ways models drift:
• Hallucination: false, fluent, cited from nowhere
• Bias: the answer moves when you rephrase the question
• Overconfidence: never says “I don’t know”
The last one is the expensive one.
1/ Calibration = does your confidence match reality?
If a model says “I’m 90% sure,” it should be right ~90% of the time.
Most models talk like they’re 99%.
They’re not.