i generally detest the religious aspect of using LLMs with secret incantations and shit you have to know about but learning about meta cognition definitely made me more productive with astra
upon further experience with it, and in comparison with opus 5.5, astra is genuinely a very bad model. i find myself getting dramatically more done with normal-speed opus vs *ultrafast* astra. i find it tough to even use as a subagent for opus. it just really really does not care about user intent.
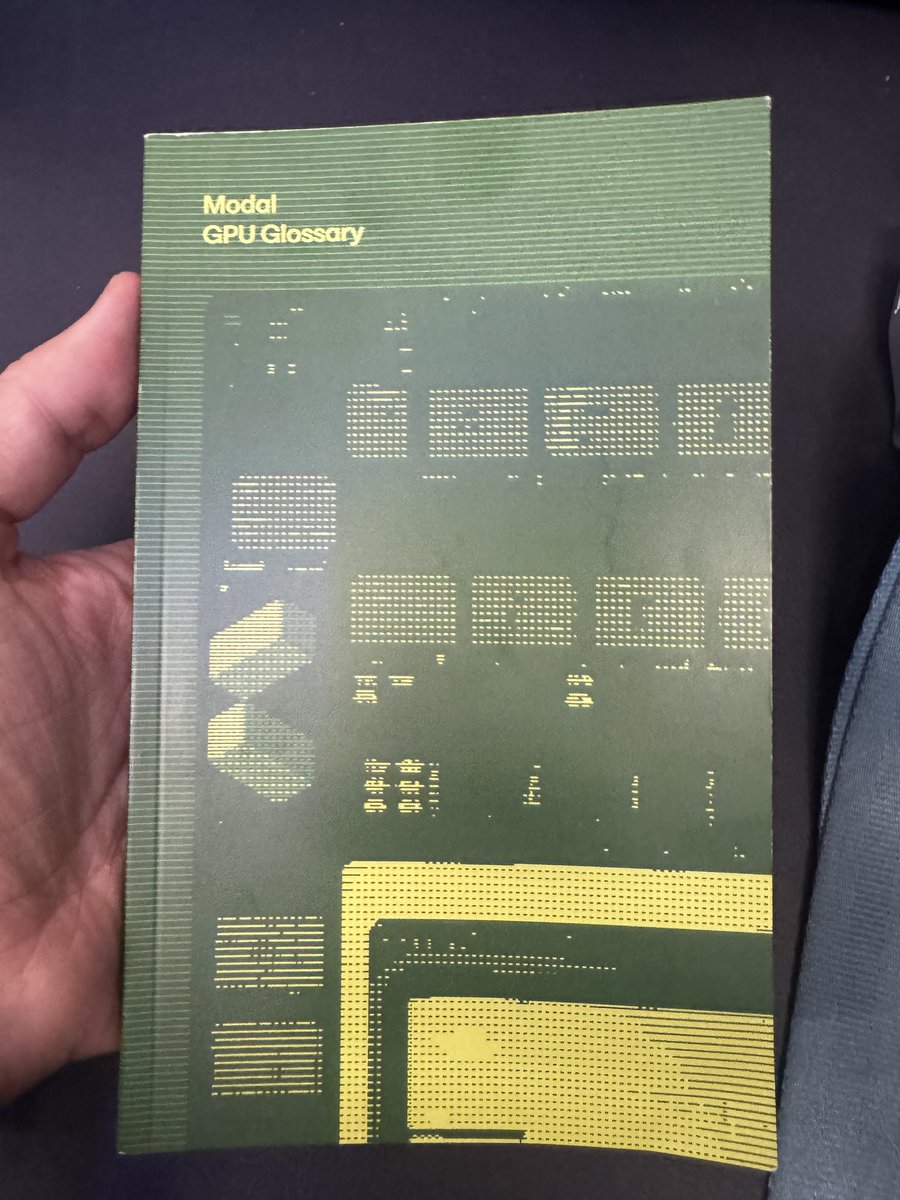
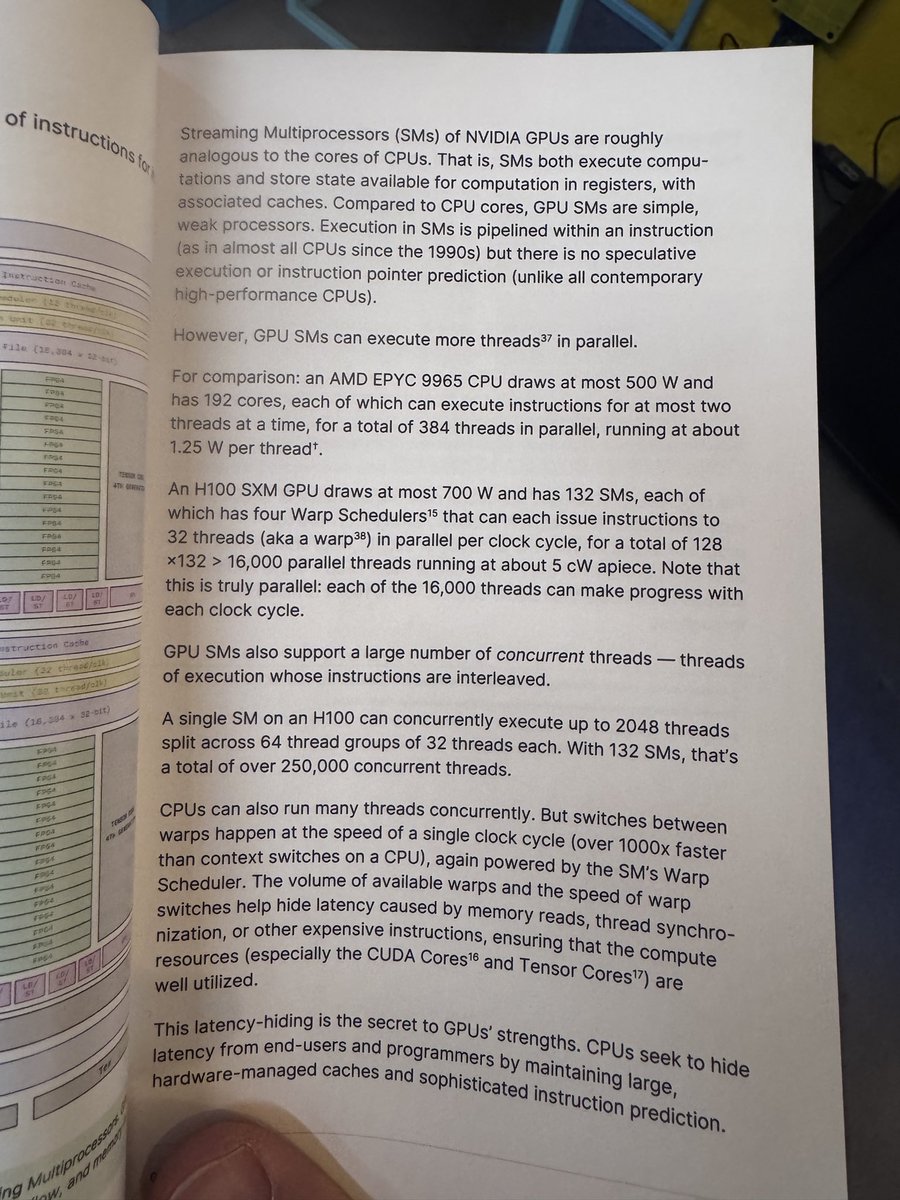
Finding it very educational and interesting to learn about the hardware layer of GPUs: how they are structured, the obvious advantages and disadvantages bs CPUs.
This is from Modal’s excellent “GPU Glossary” print book @can gave me (the PDF is free here: https://t.co/ltzxXm1GSi)
Tinker changed how people do post-training. We're big fans, and so are many of the teams we work with. But as those teams scale up, they keep raising the same two problems: per-token pricing gets expensive quickly, and you’re limited to the models and features the provider decides to support.
We think a good API deserves more than one implementation.
Today we're releasing Spindle, an open-source, Tinker-compatible training server that runs in your Modal workspace. Your existing Tinker scripts run unchanged, and because you own the server, you pay for GPU time instead of tokens.