Hey @CVPR, how about sending a reminder to complete the OpenReview author form? Deadline in 1.5 hours, and it has likely gone unnoticed by many people. I assume it won't cause rejection, but I can see people panicking about reaching out to coauthors :) #CVPR2027
This is a result I’ve dreamt about for many years: *unpaired translation between images and text*
I thought it might be only slightly possible, the kind of thing you have to really squint at. But Dominik proved this wrong. You don’t have to squint. Worth looking for yourself:
DINOv2 has never seen a caption, and Qwen3 has never seen an image. We still aligned their embedding spaces without a single image-caption pair.
It even works when the images and the captions come from different datasets.
Project page: https://t.co/2YHSkXVz1D
⬇️
EquiFusion on equivariant latent diffusion for human motion prediction will be presented soon as poster #2!
If you have an opinion on JEPA and human-centric world models happy to chat about that too!
Florian Hofherr @dominikmuhle@abhi_saroha19@_R_Marin_ Daniel Cremers
It's ECCV 2026 in Malmö! If you are excited about generative models for 4D computer vision or want to know more about how Equifusion enables cross-dataset training and inference for 3D human motion prediction, drop by on Friday afternoon at Exhall #2.
https://t.co/QiVZfpGXac
So excited to share what we’ve been working on!
Atlas is honestly just so fun to work with!! One of my favorite parts: Camera control is insanely good, allowing you to do crazy flythroughs.
How many examples can you spot in the blog where we fly through sth weird? 🚀
Next week I will present EquiFusion at ECCV! If you are interested in equivariant latent diffusion models and want to know how we unlock training and inference on multiple datasets for human motion prediction, let's chat!
@eccvconf@tumcvg
https://t.co/QiVZfpGXac
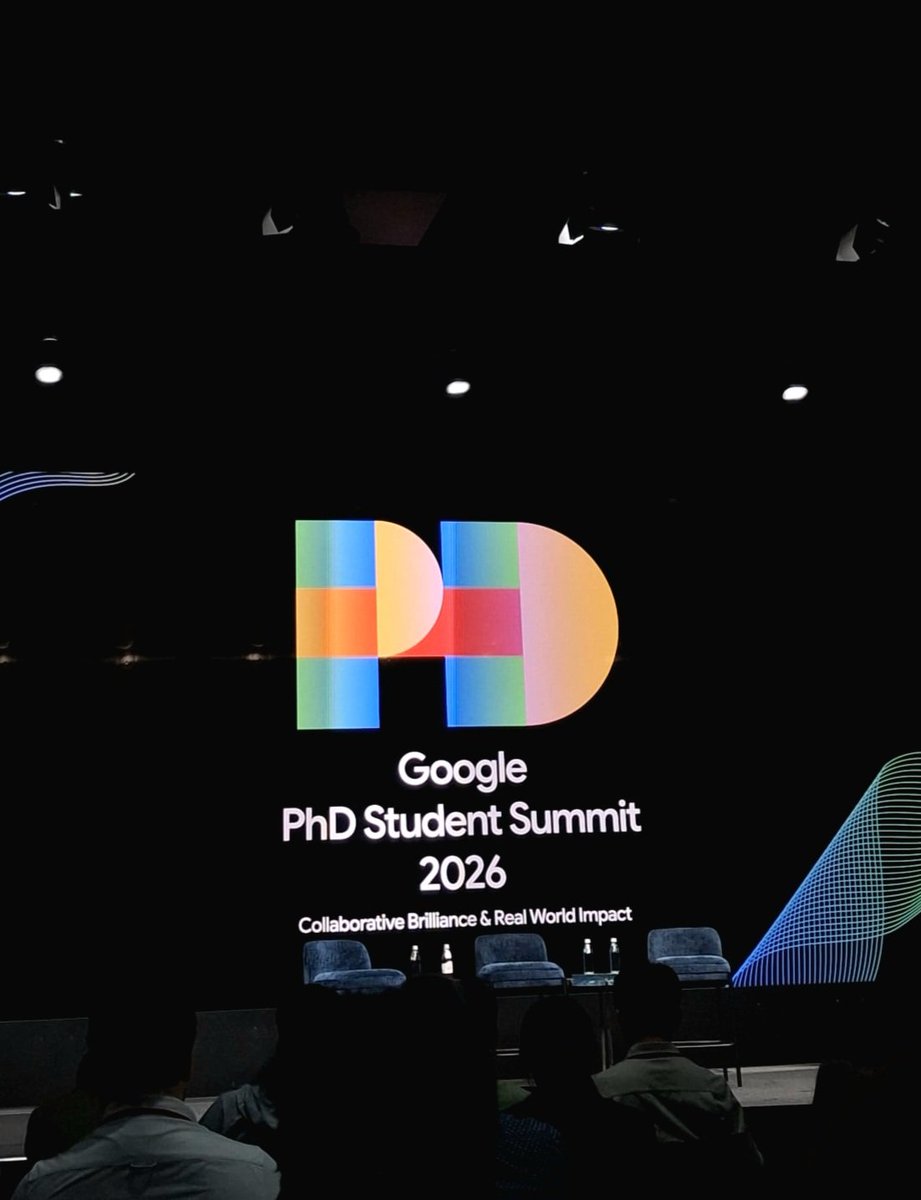
I am excited to spend the week in Bay Area for the Google PhD Summit in Mountain View!
If you are around and want to talk about 4D generation or human-centric world models, send me a DM!
#GoogleInterns#GooglePhDSummit#LifeAtGoogle
🔵🟡🔵Our paper "VOCA: Visual Odometry with Codec Awareness" has been accepted at #ECCV2026
Modern vision systems often work with compressed video but most methods ignore a lot of useful information that's already there.
📄https://t.co/1i8OJ9H159
🔗 https://t.co/qtheS1zZYU
I just started my internship at Google, looking forward to doing research with amazing people!
Thanks for the greatest onboarding to my host @AliOsmanUlusoy
If you are in Seattle and want to talk about diffusion and 4D dm me :)
Super excited that we are launching Odyssey-2 today, a frontier interactive video model that turns your imagination into video instantly such that you can interact with it. 🪄🪄🪄
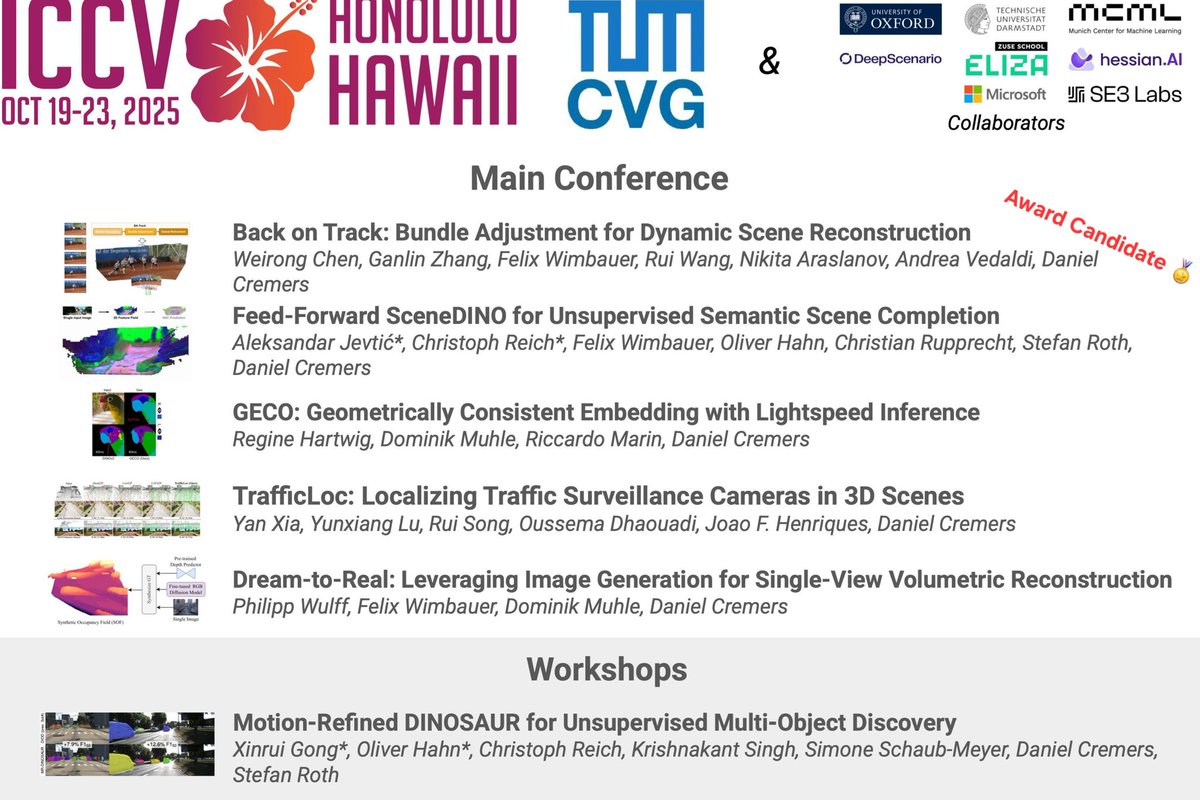
@tumcvg goes #ICCV2025 in Hawaii! 🛫🌋
We are very proud of our students who will present five papers (+ 1 workshop) during the conference!
In particular, check out Back-on-track, which is an award candidate. (Congrats @wrchen530!)
Our group will present the Monado SLAM Dataset #IROS2025! 5+ hours of *challenging* VR headsets data, great for both XR and humanoid robotics applications.
Our paper "The Monado SLAM Dataset for Egocentric Visual-Inertial Tracking" has been accepted at #IROS2025!
Because SLAM/VIO datasets were getting a bit too easy :)
🔗 https://t.co/R4E4vrawUx
📄 https://t.co/lID5TL1HY3
🎥 https://t.co/6jL16CEcds
(1/5)
🦖 We present “Feed-Forward SceneDINO for Unsupervised Semantic Scene Completion”. #ICCV2025
🌍: https://t.co/bHLwuTDqar
📃: https://t.co/jhKiToJrAO
💻: https://t.co/vSEcJKxlaR
🤗: https://t.co/ZUGMQagRyv
w/ A. Jevtić @felixwimbauer@olvr_hhn C. Rupprecht @stefanroth D. Cremers
Can you forecast more realistic human motions by changing the generative diffusion process?
Yes! We show how in our #CVPR2025 paper Nonisotropic Gaussian Diffusion for Realistic 3D Human Motion Prediction.
If you are in Nashville and have any questions, reach out!