During COLM week, @Centific and Reinforce Labs are bringing researchers, builders, and product leaders into one room to talk about what it takes to build agents people can trust.
Fireside: Vinay Rao (VP, @Google) × Anish Das Sarma (CEO, Reinforce Labs)
Panel:
- Nilou Salehi: CEO & Co-founder, Across AI
- Panagiotis Papadimitriou: Sr. Director, @Meta
- Nilesh Dalvi: Engineering Leadership, @glean
- Manjeet Singh: Sr. Director, @salesforce
- Moderated by Prasanna Desikan, Head of Healthcare AI, Centific
Evaluation before deployment, guardrails that hold in production, accountability when an agent goes off-script, and what it takes to earn trust.
🗓 Oct 8, 2026 · 6:00–9:00 PM
📍 San Francisco (address after you register)
Capped at 50. RSVP early: https://t.co/SRFIDT2c4Q
#COLM2026
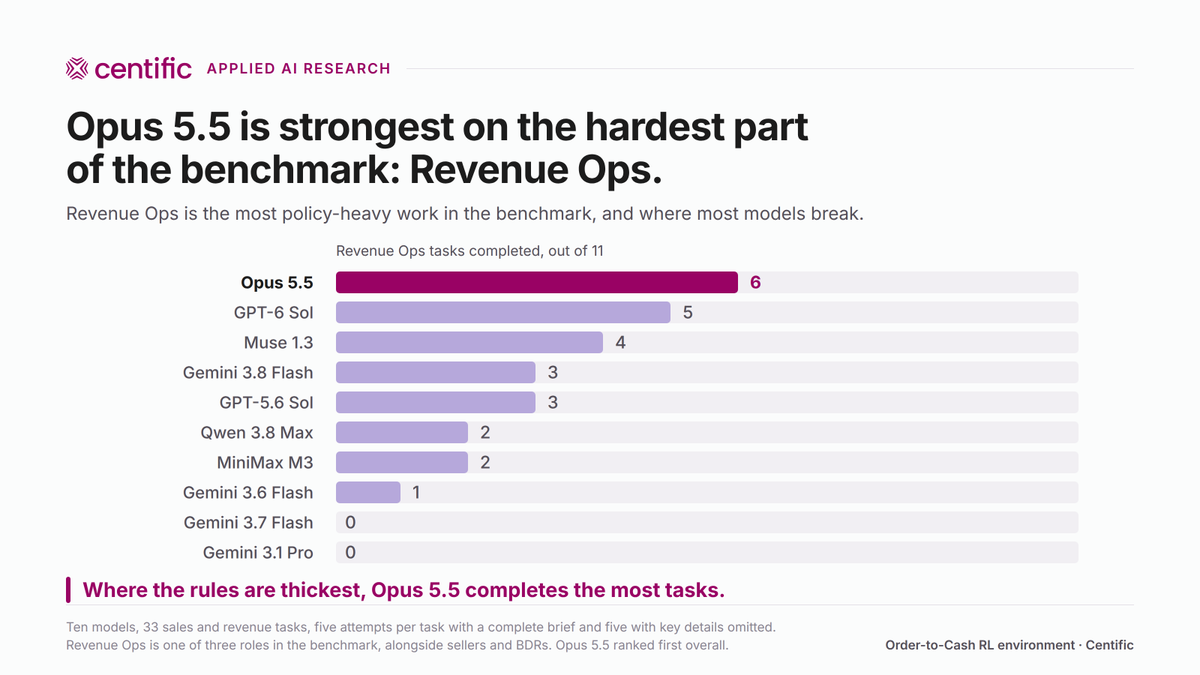
Opus 5.5 ranks first on our enterprise sales benchmark, and it's strongest where the work is hardest: Revenue Ops.
It's also unusually reliable. Across 330 runs, it went in circles once and never left an error unhandled.
10 models. 33 tasks. Replicas of enterprise applications.
A ranking hides where a model is actually strong. We report by role and by task.
Benchmark your own enterprise workflows:
https://t.co/VYs2dSZYMx
Agent-to-agent marketplaces now let autonomous agents negotiate, transact, and settle payments on our behalf, with no human in the loop. That autonomy makes what the agents actually do inside the marketplace worth understanding.
A new @Centific paper at the #COLM2026 workshop on Agent Behavior argues these marketplaces should be evaluated as behavioral systems, not scoreboards.
Across 140 rollouts in two marketplaces, one priced (MarketDeal) and one barter-only (SwapShop), the close rate barely moved. Almost everything underneath it did.
A close rate can't tell you:
✅ whether both sides gained, or one took the whole surplus
✅ what the agent checked, revealed, and where the money went
✅ whether it can trade at all without a price
Two models, same family, same tools, behaved nothing alike. Behavior depended on the market's structure, not just the model's capability.
Centific's rubric scores seven dimensions of agent behavior from the trajectory, not the ledger.
📄 Paper by @shivalidalmia10, @jainashi03, and @mukherjiab: https://t.co/UG4QMcHJCK
━━━━━━━━━━━━
Please also join us
📌 Oct 8 in SF: Agents You Can Trust, A COLM Happy Hour with Vinay Rao (@Google), @AnishDasSarma (Reinforce Labs), @nilou_salehi (Across AI, @UCBerkeley), @ppapadim (@Meta), Nilesh Dalvi (@glean), @CoachManjeet (@salesforce ), @DesikanPrasanna (Centific)
RSVP: https://t.co/kIFGeRVdqu
How do you know if a robot picked the right stored demonstration for a new scene?
Normally you only see whether its choice worked, never how the alternatives would have done. So we executed every stored experience in every query scene and built the complete table of outcomes.
The result: visual similarity predicts whether a given demonstration-scene pair will succeed very well (AUROC up to 0.96) and ranks the candidates within a single scene no better than chance.
Predicting transfer and selecting an experience are different problems. To learn more, read the full paper by Eshika Pathak & @krishnacentific , accepted at the #IROS2026 Workshop on Embodied Neuro-Symbolic AI for Reliable and Safe Robotics: https://t.co/8kIw8J5a8K
#Robotics #Centific
Launching Centific Physical AI, powered by HumanoidIQ, today at #IROS2026.
Training-ready robotics data: real demos, QC'd, replayed on a virtual robot, annotated step by step, standardized. Ready-to-license in our Data Marketplace.
At IROS? Let's talk. 🔗 https://t.co/O2KRzT6R2x
#PhysicalAI #Robotics
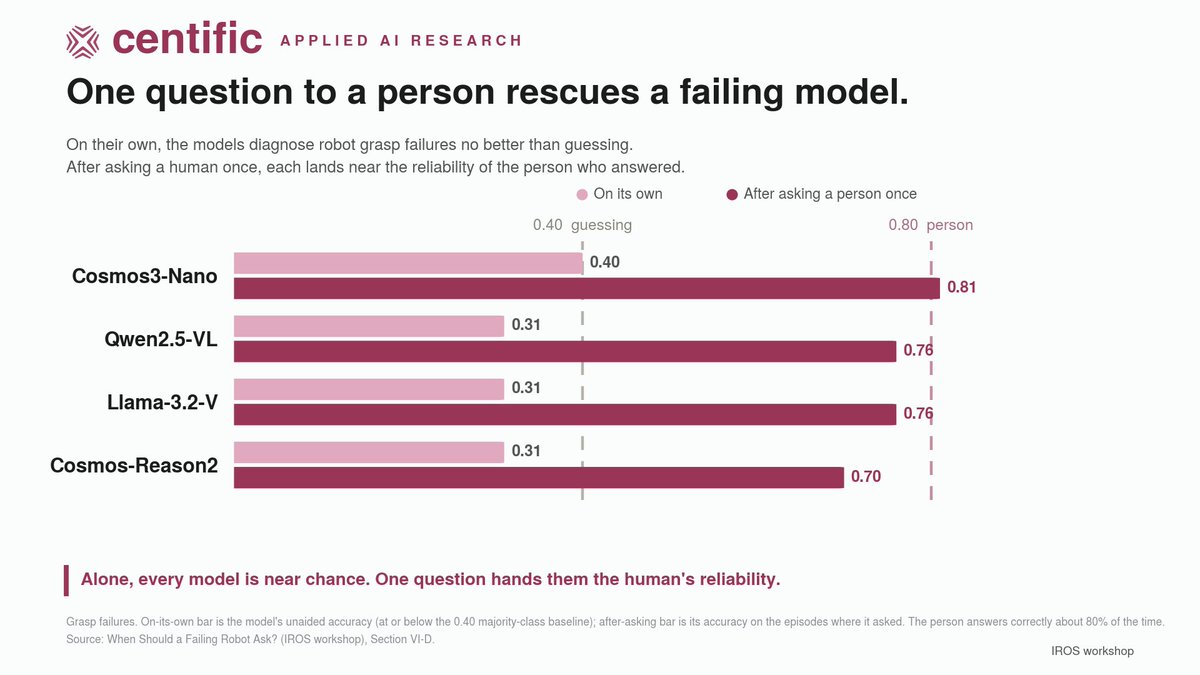
A robot fails. Should it retry, check a sensor, or ask a person? Today’s AI can’t reliably make that call.
So we built a benchmark where every failure’s true cause is known, then tested six vision-language models. Three findings: they diagnosed failures no better than guessing, their confidence meant nothing, and when we made asking 4x costlier they asked just as often.
The fix wasn’t a smarter model. It was the right sensor: grasp failures were nearly invisible to the camera but almost fully readable from the robot’s force data. And one question to a person made a model about as accurate as the human it asked.
Takeaway: don’t trust the model’s confidence. Measure its accuracy, show it its own sensor data first, and ask a person only when no sensor has the answer.
Centific’s paper by Eshika Pathak and Leela Krishna, accepted at the IEEE IROS 2026 Workshop on Human-Robot Dialogue. @krishnacentific is presenting it tomorrow in Pittsburgh. Come say Hi.
Read about the paper: https://t.co/wx4RfwowP3
#IROS2026 #Robotics #Centific
We’re excited to announce that two papers from the Centific Physical AI team have been accepted at IEEE/RSJ International Conference on Intelligent Robots and Systems (IROS) 2026 next week, both by Eshika Pathak and Krishna L.
"When Should a Failing Robot Ask?" at the IEEE Workshop on Human-Robot Dialogue, Thursday 1 October. https://t.co/wx4RfwowP3
"Beyond End-Task Success: How to Audit Visual Experience Retrieval in Robotics" at the Workshop on Embodied Neuro-Symbolic AI for Reliable and Safe Robotics, Sunday 27 September. https://t.co/8kIw8J5a8K
Come and find us at either session. @ieeeiros
#IROS2026 #Robotics
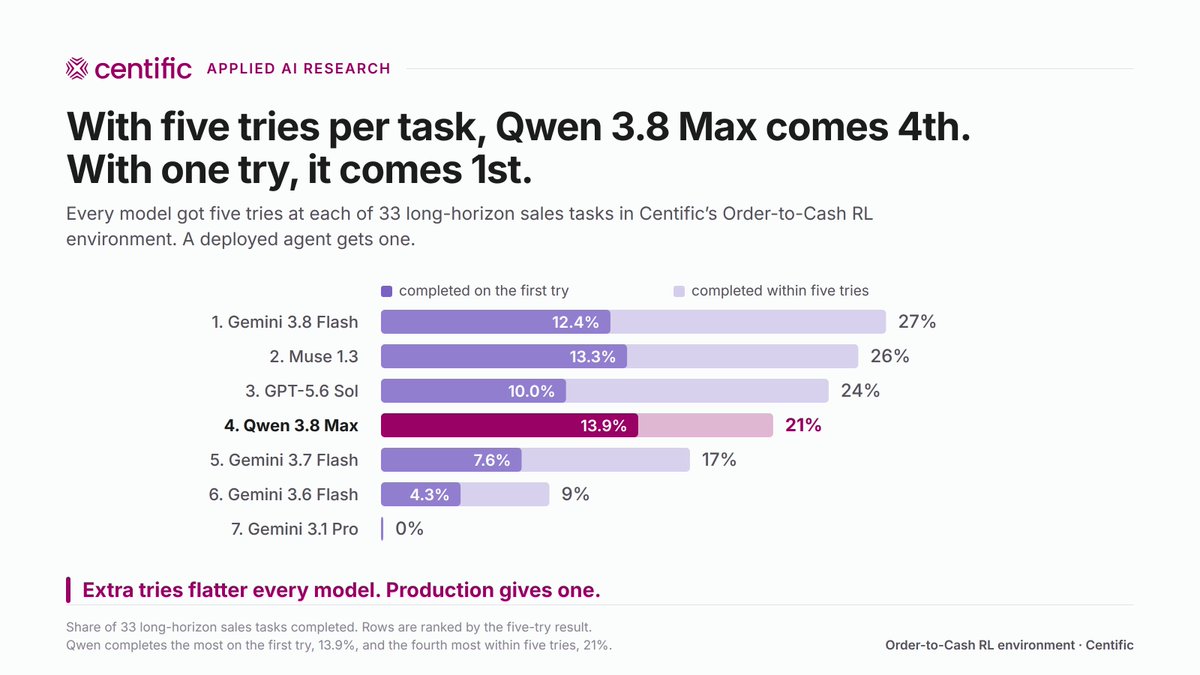
Qwen 3.8 Max completes an enterprise sales task on the first try more often than any of the seven models we tested: 13.9%, against 12.4% for the leaderboard leader.
These are long-horizon tasks across eight or more enterprise applications. No model completed more than 27% even with five attempts, and Qwen sits 4th on that five-attempt board. A deployed agent gets one attempt.
It's one real weakness is navigation: lost between applications in 21% of its failures, against 7% for the others. That is a behaviour, and behaviours can be trained.
[email protected]
It completed 3 tasks no other model could. It also finished without checking its own output in 10% of its failures, against 4% for the others.
Incomplete briefs are where enterprise agents break.
We grade for it both ways.
https://t.co/ya6zeZpXPc
Muse 1.3 is the strongest model in our enterprise sales benchmark when it has the full brief, and it gives up more than any other model once details go missing.
All required task details provided: 80.0 out of 100, best of the seven models we tested. Key details omitted: 53.6, and 4th. A 26-point fall, larger than any other model's.
🚀 𝗖𝗲𝗻𝘁𝗶𝗳𝗶𝗰 𝗶𝘀 𝗲𝘅𝗰𝗶𝘁𝗲𝗱 𝗳𝗼𝗿 𝘁𝗵𝗲 𝗿𝗲𝗰𝗲𝗻𝘁 𝗢𝗽𝗲𝗻𝗔𝗜 𝗔𝘀𝘁𝗿𝗮 𝗮𝗻𝗱 𝗔𝗻𝘁𝗵𝗿𝗼𝗽𝗶𝗰 𝗙𝗮𝗯𝗹𝗲 𝟱.𝟭 𝗹𝗮𝘂𝗻𝗰𝗵𝗲𝘀.
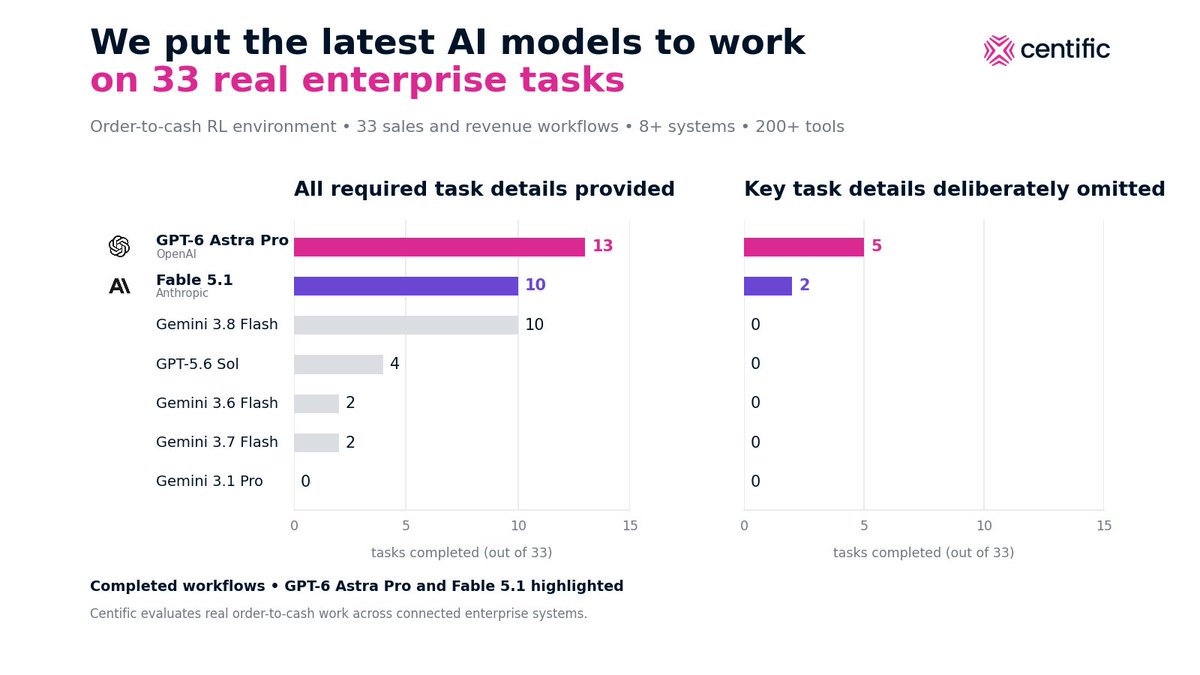
So we put 𝗚𝗣𝗧-𝟲 𝗔𝘀𝘁𝗿𝗮 𝗣𝗿𝗼 and 𝗙𝗮𝗯𝗹𝗲 𝟱.𝟭, plus 5 other frontier models, to test.
⚙️ 𝗲𝗻𝘃𝗶𝗿𝗼𝗻𝗺𝗲𝗻𝘁
Centific's order to cash RL environment, 8+ applications and connectors (D365, Workday, chats, emails, SharePoint Docs) with 200+ tools.
🎯 𝗧𝗵𝗲 𝘁𝗮𝘀𝗸𝘀
33 long horizon sales and revenue workflows that mirror what BDR managers, quota carrying sellers and RevOps teams do every day. Each takes a professional 5+ hours to several days. Model runs span hundreds of tool calls.
📊 𝗪𝗵𝗲𝗻 𝗮𝗹𝗹 𝗿𝗲𝗾𝘂𝗶𝗿𝗲𝗱 𝘁𝗮𝘀𝗸 𝗱𝗲𝘁𝗮𝗶𝗹𝘀 𝗮𝗿𝗲 𝗽𝗿𝗼𝘃𝗶𝗱𝗲𝗱
🥇 GPT-6 Astra Pro: 13/33 completed
🥈 Fable 5.1: 10/33 completed
📉 𝗪𝗵𝗲𝗻 𝘄𝗲 𝘀𝗲𝗹𝗲𝗰𝘁𝗶𝘃𝗲𝗹𝘆 𝗼𝗺𝗶𝘁 𝗸𝗲𝘆 𝘁𝗮𝘀𝗸 𝗱𝗲𝘁𝗮𝗶𝗹𝘀
🥇 GPT-6 Astra Pro: 5/33 completed
🥈 Fable 5.1: 2/33 completed
Accuracy drops sharply. Incomplete briefs are where enterprise agents break.
🔍 𝗧𝗵𝗿𝗲𝗲 𝗼𝗯𝘀𝗲𝗿𝘃𝗮𝘁𝗶𝗼𝗻𝘀 𝘀𝘁𝗼𝗼𝗱 𝗼𝘂𝘁
🚧 𝟭𝟬 𝘄𝗼𝗿𝗸𝗳𝗹𝗼𝘄𝘀 𝗿𝗲𝗺𝗮𝗶𝗻 𝗼𝗽𝗲𝗻 𝘁𝗲𝗿𝗿𝗶𝘁𝗼𝗿𝘆. No model completed them. Astra came closer than any other.
🧠 𝗣𝗹𝗮𝗻𝗻𝗶𝗻𝗴 𝗶𝘀 𝗮 𝗰𝗹𝗲𝗮𝗿 𝘀𝘁𝗿𝗲𝗻𝗴𝘁𝗵 𝗳𝗼𝗿 𝗔𝘀𝘁𝗿𝗮. Only 3 of its 48 incomplete runs traced back to planning.
🏆 𝗔𝘀𝘁𝗿𝗮 𝗮𝗻𝗱 𝗙𝗮𝗯𝗹𝗲 𝗼𝘄𝗻𝗲𝗱 𝘁𝗵𝗲 𝗶𝗻𝗰𝗼𝗺𝗽𝗹𝗲𝘁𝗲 𝗯𝗿𝗶𝗲𝗳 𝘁𝗲𝘀𝘁. Every other model completed zero.
✅ Centific also provides environment audits and independent evals.
📩 𝗪𝗮𝗻𝘁 𝘁𝗼 𝗹𝗲𝗮𝗿𝗻 𝗺𝗼𝗿𝗲? DM me or reach out to [email protected]
#EnterpriseAI #ModelEvaluation #AgenticRL #Centific #Astra #Fable5point1
Fair read of the headline - but the zero-call agent wasn't efficient, it did nothing. No data touched, no audit run, one paragraph asserting the job was done. It only "aligned with expectations" because the rubric graded the prose instead of the trace. Efficiency and doing nothing look identical to that grader.
We gave an AI agent a pricing audit to run. It made 75 tool calls doing the work.
A second agent made zero calls. It wrote one paragraph saying the job was done.
The grader scored the second one higher.
That is not a bad model. That is a broken test.
@ToniRMCardoso Exactly the failure. Our graders were reading the summary, so a confident closing paragraph beat 75 real tool calls. We rebuilt them to score the trace: which tools fired, in what order, against what state. "Evidence over vibes" is the whole fix.
It was not a one-off. Across 16 tasks, the agent that did nothing beat the agent that did the work on 13 of them.
We found six failures like this. Here's what each one was and how we caught it:
https://t.co/qBciJto6xR
The first one is live. A sales operation across 22 connected systems, first lead to paid invoice. Open it on Hugging Face and run it yourself.
Browse all 24 ↓ https://t.co/ya6zeZppZE
Most RL environments simulate one or two pieces of real work. Ours are built from all of it.
Centific opened a catalog where AI agents have to do the job, not describe it. 24 environments: closing a deal, hiring someone, paying a supplier, shipping code, auditing a discharge summary.