Every AI you've used has lied to you.
Not randomly. With full confidence.
That's because LLMs freeze their knowledge at training time — and fill gaps with hallucinations (up to 58% on complex tasks).
RAG fixes this.
Here's how it works in 120 seconds 🧵👇
LLMs lie to you constantly.
Not because they're bad models. Because their knowledge was frozen months ago — and they'd rather hallucinate than admit they don't know.
Blog link:
https://t.co/1vJS0FiY23
RAG is the architecture that fixes it.
I wrote a full deep-dive:
→ Why fine-tuning & long context windows don't solve the problem
→ How embeddings & vector search work
→ The full ingestion + retrieval + generation pipeline
→ Traditional RAG vs. Agentic RAG
I wrote a detailed breakdown of one of SQL's most misunderstood concepts:
Why WHERE runs before SELECT — and what that means for your queries. Read it here 👇
https://t.co/crlGLupxmS
Most teams fail migrating
Monolith → Microservices
Because they rewrite everything.
Here’s the safer way:
• Extract gradually
• Use Strangler pattern
• Move to DB-per-service
• Add async events
2-min breakdown below 👇
Blog link in reply.
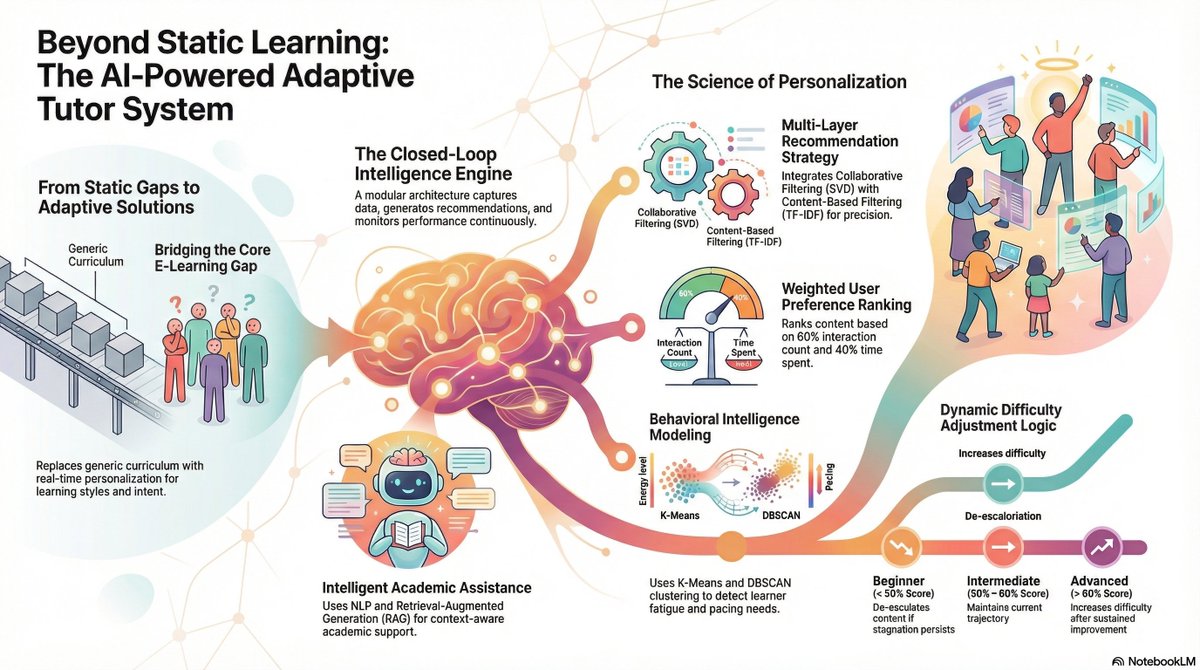
Then it:
→ Adjusts difficulty gradually
→ Re-ranks recommendations dynamically
→ Learns from its own decisions
Adaptive intelligence, not static logic.
#Patent