What if the computer you needed didn't have to fit inside the server you bought?
Mercury Rack composes pooled GPUs, xPUs, SSDs & FPGAs over native PCIe-over-optical into right-sized blocks: one 32-GPU domain, two 16s, or four 8s.
https://t.co/18fvgYjBiX
In the Lab: 8x AMD Radeon AI PRO R9700, One Fabric
AMD specs the R9700 for 4-way. We ran 8 as one fabric.
Every GPU-to-GPU pair: ~111 GB/s bidirectional, line-rate PCIe 5.0 x16. Flat topology, no cross-domain cliff.
ROCm + PyTorch. No NVLink, no CUDA. ~2× what NVIDIA targets for the RTX PRO 6000.
Full breakdown https://t.co/zycHJHFU7F
The asset a lender repossesses isn't a GPU. It's a rack. And most AI racks financed at scale are HGX boxes: 8 accelerators welded to one baseboard, one topology, one cooling design, one generation.
New from Bill Koss on why bankable compute runs through the rack, not just the runtime: https://t.co/4ypo0YVnKY
The most expensive GPU is the one you can't fully use.
Wrong ratio, and half the rack sits idle waiting for a job shaped like the box.
Scale-across composes the exact compute, memory & I/O each workload needs — then reclaims it.
Utilization is the multiplier.
https://t.co/EWq3b7Ta9N
The inference era won't be won by the biggest boxes. It'll be won by the fabric that composes GPUs, memory & I/O around each workload, then reclaims it for the next one.
Tokens per dollar, not GPUs per rack.
https://t.co/WxzDqM78cO
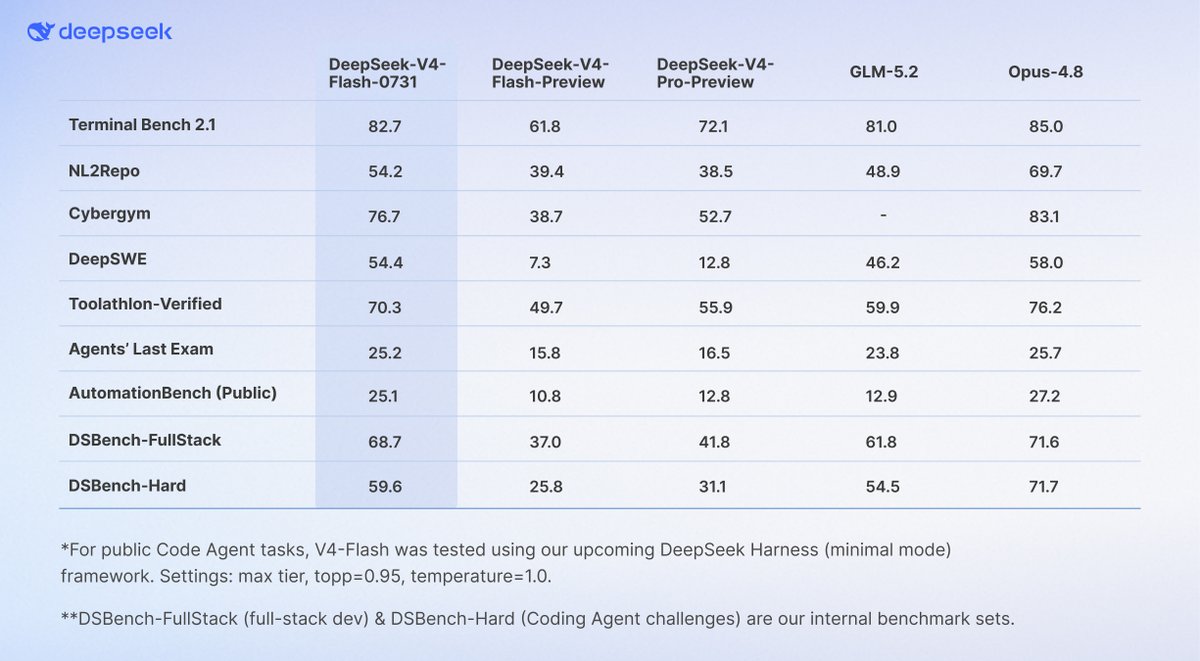
🚀 DeepSeek-V4-Flash Official API is now LIVE in public beta!
🔷 We’ve massively upgraded its Agent capabilities—benchmark scores are now far surpassing the V4-Pro-Preview. Check out the massive performance leap below! 👇
🔷 The official V4-Flash now natively supports the Responses API format and is fully adapted for Codex!
Check out the configuration details in our official API docs: https://t.co/smCwQZMeiq