$CUMULUS now live on Robinhood Chain.
CA: 0xc2fD09F96313BB4CAc7A9D21a7Fe28B7E0BFceF3
Cumulus Labs is one platform from GPUs to agents. Paladin runs the GPU fleet, Ion serves the models, Talos operates the agents.
Built on @NVIDIAAIInfra, on our infrastructure or yours. The stack behind 7,167 tokens per second on a single chip.
$CUMULUS pays for inference on IonRouter. Same models, same OpenAI-compatible endpoint, one more way to pay. Add it to your balance and every request draws from it. Change nothing in your code.
$CUMULUS pays for inference on IonRouter, the same models, the same endpoint, one more way to pay.
Launching on @ponsdotfamily. on the @RobinhoodApp. Add it to your IonRouter balance and every request draws from it, per token in, per token out.
No new API, no new client, change nothing in your code. The GPUs underneath are ours, the runtime is Ion, the numbers are the ones you've seen all week.
https://t.co/dHNVf3DyPk
$CUMULUS is live.
This isn't a token looking for a product. The product shipped first: a GPU fleet, an inference engine, an agent platform, and a public benchmark you can run yourself.
Every $CUMULUS spent on IonRouter buys real compute on real Grace Hopper chips. Usage you can measure, not a roadmap.
Builders: the endpoint is OpenAI-compatible, so your first request is a base URL away.
Traders: read the blog, check the numbers, then decide. We'd rather earn it.
https://t.co/dHNVf3E6ES
vLLM is an open-source library for fast and efficient large language model inference and serving.
Originally developed at UC Berkeley, it has become one of the most widely adopted LLM serving engines because of its strong throughput, broad model coverage, and OpenAI-compatible API.
vLLM supports LLaMA, Mistral, Qwen, GPT-NeoX, Falcon, and most other major architectures.
https://t.co/MAOXfq9qOA
Inference is the act of executing a trained model on new data to produce outputs.
It is what happens every time a user sends a prompt to a language model, asks an image generator to render a scene, or calls a classifier on a document.
While training updates a model's parameters, inference holds them fixed and uses them to compute predictions for new inputs.
https://t.co/J78UJCGd6L
Built around your workload.
Manage AI computing capacity with Paladin, run models with Ion, or build agents with Talos.
Start with the product your application needs.
https://t.co/rwlNRi6wUY
Where Ion started, and where it is now.
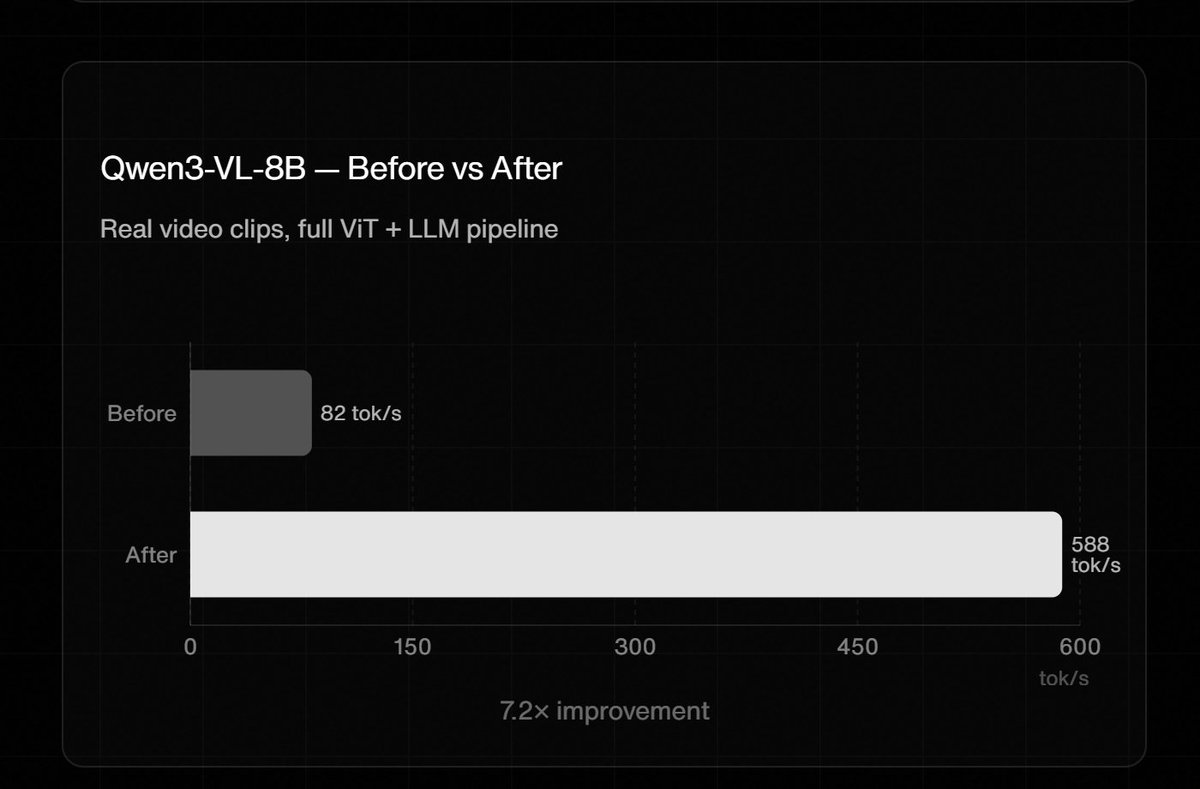
Qwen3-VL-8B, real video clips, full ViT plus LLM pipeline. 82 tok/s before. 588 after.
7.2× from the same hardware.
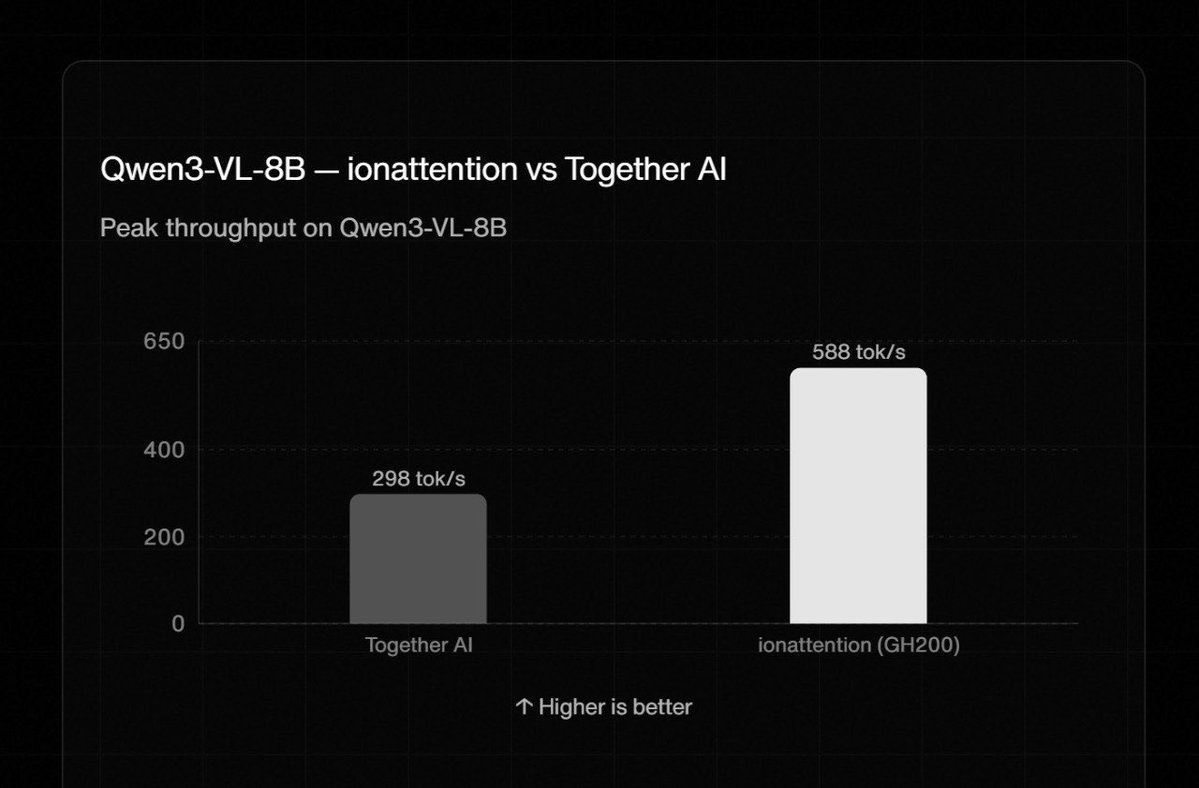
Same model, same benchmark tool, different runtime.
Qwen3-VL-8B on ionattention: 588 tok/s. Together AI on the same workload: 298.
Measured with their tooling, not ours.
Seven posts about what Ion does. Here's what it measures.
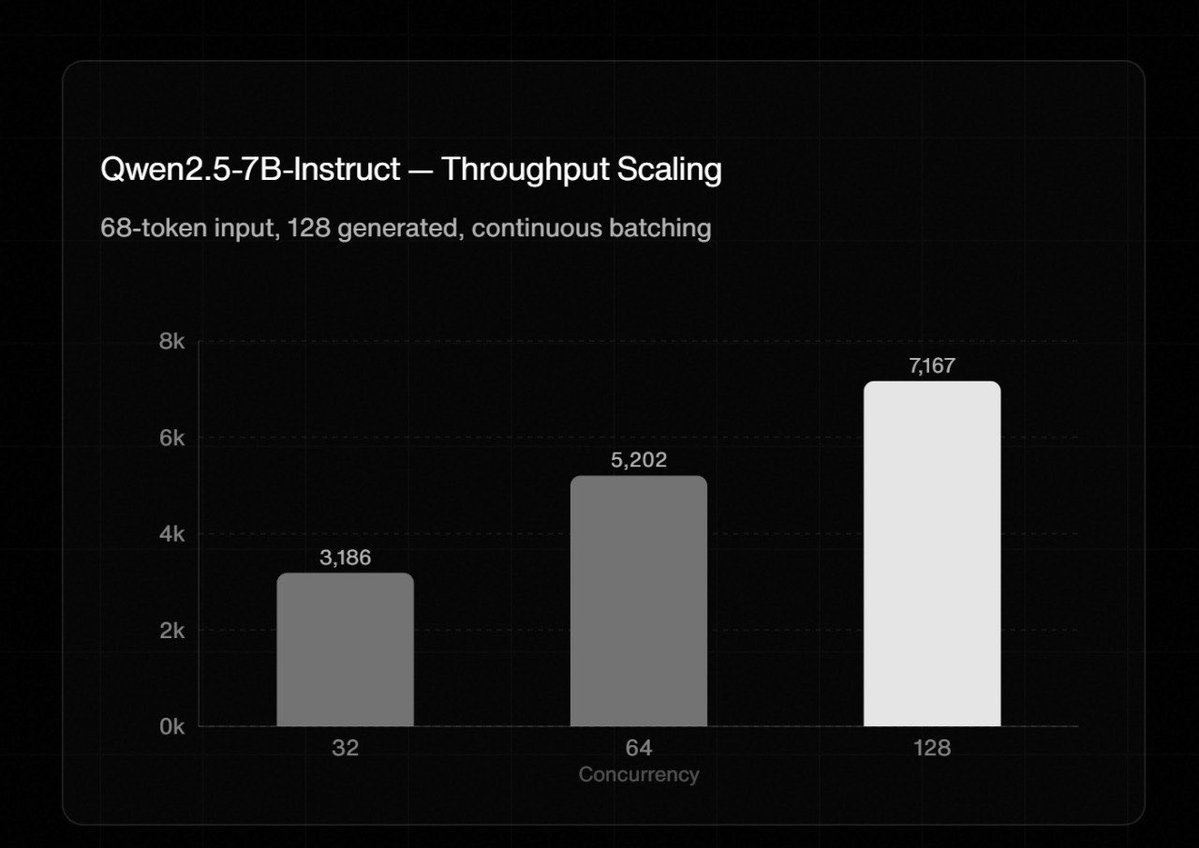
7,167 tokens per second on a single GH200 chip. Qwen2.5-7B, continuous batching, concurrency 128.
Not a cluster. One chip.
Bottom of the stack: Paladin.
Three GPU pools, one fleet. Compatible jobs share a device, idle capacity goes to whoever needs it next.
Teams get quotas and usage visibility. Workloads move as demand shifts, without anyone reserving a whole GPU for one job.
More work. Same GPUs.
One layer down: Ion.
Text, vision, or audio goes in. The engine runs it on custom GPU kernels, tuned to the model and the hardware underneath.
OpenAI-compatible endpoint. Sign up, add credits, grab a key, and you're serving Qwen, Llama, or DeepSeek in minutes.
Hosted now. Dedicated when you outgrow it.
Top of the stack first: Talos.
A customer asks "where is my order?" The agent looks it up, calls the model, replies "arrives tomorrow."
Every step is traced. Input, model, tool call, reply. Open any request and see exactly what happened.
Found an answer that falls short? Replay it, compare prompts and models, see the change before you approve it.
Same agent on chat, email, phone, or edge. Ion runs the models. Paladin runs the GPUs underneath.
Give it a job. Watch it work.
GPUs to agents shouldn't take 3 vendors.
We built one platform for the whole stack.
Paladin runs your GPU fleet, Ion serves models, Talos operates agents.
On our infrastructure or yours.
Start at any layer, connect the rest.
https://t.co/gHbzEf2qCc