Forged at USCYBERCOM. We replace "Detect & Respond" with Engineered Certainty.
Architects of:
🛡️ Warden
🔗 Digital Shield
🤖 AI SAFE²
👇 Get the Blueprint
The Death of Governance & Compliance in an AI Era..
This statement is obvious for some, obscure for others and for many it is down right confusing.
Most "AI Security" advice is focused on governance and compliance guidance...aka how to create an AI policy or program.
It’s vague.
It’s theoretical.
It’s useless to an engineer.
But most of all it misses the point with AI.
We've been lead to believe if...
We document, monitor or detect risk, we can manage it and everything will be OK.
Reality is...
AI risk is executed in milliseconds & Documentation Does NOT STOP Execution.
♟️Strategic Truth
Most AI security advice from a policy standpoint:
🚫Optimizes for regulatory defensibility
🚫Assumes post-event containment
🚫Treats AI as a governance problem
But AI exploitation is an engineering problem.
Thus, until policy mandates preventive, runtime-enforced controls, AI security guidance will remain structurally misaligned with the threat landscape.
This is where we stepped in when we built the architecture standard back in Jun 25.
Been working hard on AI SAFE² ever since but accelerated after the explosion of risk last quarter by turning this holiday season into go-mode.
We Finalized a v2.0 then quickly finalized a v2.1 both are massive upgrades & industry must haves!
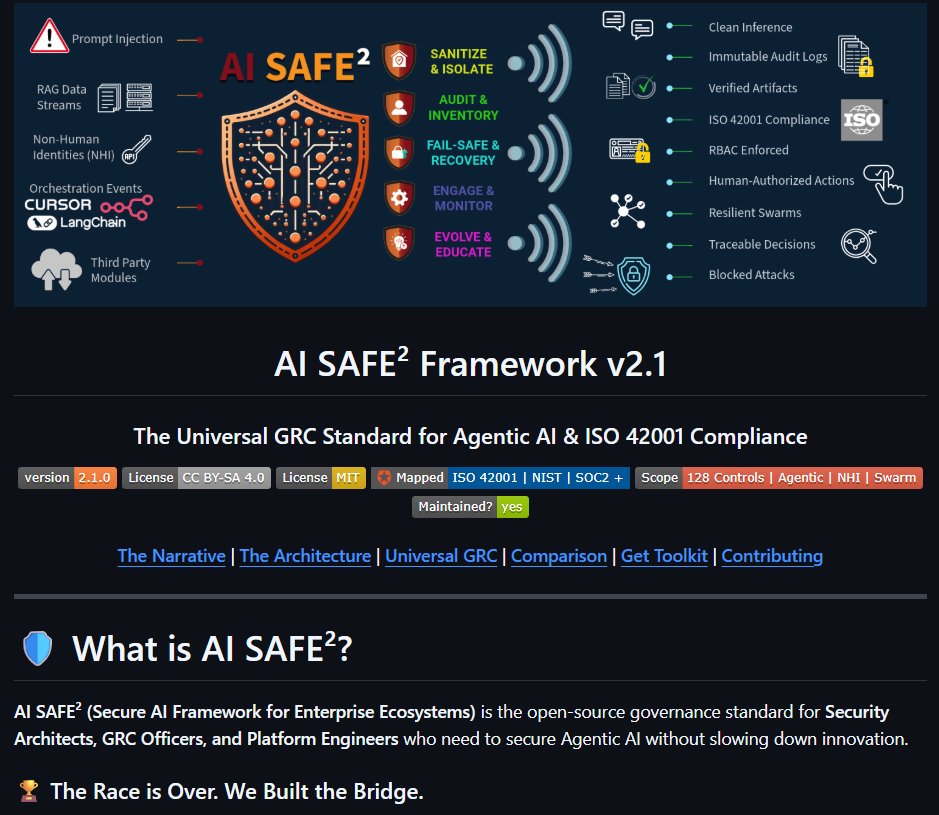
Introducing the AI SAFE² Framework (v2.1):
☑️The Universal GRC Standard for Agentic AI & ISO 42001 Compliance.
📂The open-source protocol for governing Agentic AI.
- Dropped our Github Repo
Let's unpack what all this actually means for AI Governance & Compliance moving forward...🧵
Star the repo to show your support👇
Before you buy an AI security product, turn on MFA everywhere.
Microsoft said MFA can block over 99.9 percent of account compromise attacks.
The boring controls still do the heavy lifting. Which of your agent and admin accounts still don't have it?
Anthropic now suggests starting on Opus 5.5, then switching up to Fable or Mythos, or down to Sonnet or Haiku. Claude Code's opusplan switches models mid-session.
Each switch changes the system: different behavior, maybe different tools, under the same agent name.
Log it, and re-check what the new model is allowed to do. When your agent last switched models, who noticed?
Anthropic's Project EVE told one Claude agent on a four-agent team to secretly sabotage it. Its teammates almost never caught it.
Anthropic's conclusion: teams of agents will probably need audit trails, reputations and separation of duties.
We already know those controls. If one of your agents went bad, which teammate would catch it, and how?
Agency Check is free for 20 checks a month, no card. Describe what your AI agent is about to do and get a plain verdict before it acts: https://t.co/sf1RoTNzTX
Anti bot mitigations block:
Web fetch
Curl
Wget
Puppeteer
Playwright
Chrome devtools mcp
You don’t notice because it’s in a sub agent and your hackbot gives up silently.
Roll your own requester.
Jason Haddix this week: anti-bot defenses block fetch, curl, wget, Puppeteer, Playwright and Chrome DevTools MCP, and "your hackbot gives up silently" in a sub-agent.
The parent still reports done. You think the work finished. It didn't.
Log every hop. Check the receipts, not the summary. Which of your agent runs have a receipt you can actually verify?
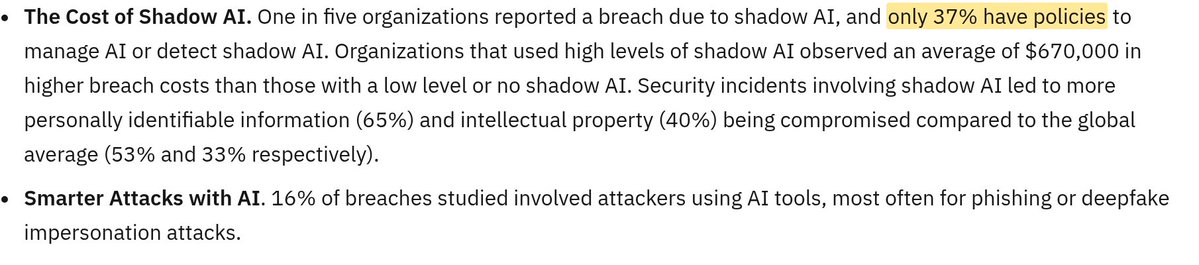
You can't secure the AI you don't know is running, and you can't contain a breach in a tool that was never on the inventory. The data still left. The tool was never in the ticketing system.
AI Fatal flaw #19: no inventory of the models, agents and connectors in use.
IBM, 2025: one in five organizations reported a breach due to shadow AI.
Can you list every AI tool touching your data today?
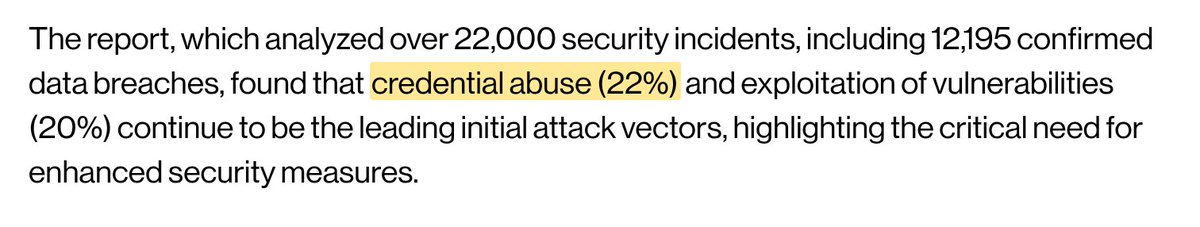
Credential abuse and exploited vulnerabilities are still how most breaches start. Verizon's 2025 DBIR puts them at 22% and 20%.
AI didn't change that. Identity and patching were the job before AI. They're still the job.
What's new is the other half: if the baseline can't be changed, an exploit stalls and the impact doesn't happen. Warden stops exploits from impacting vulnerabilities, because they can no longer change the baseline. Same for all unknown code.
Which of those two doors is still open in your environment?
Source: https://t.co/RWjQ2y8npV
More: https://t.co/UEuzB9V9FD
Same idea on the host. Warden puts enforcement outside the workload: virtual kernel defense, zero-dwell, so unknown code can't change the baseline.
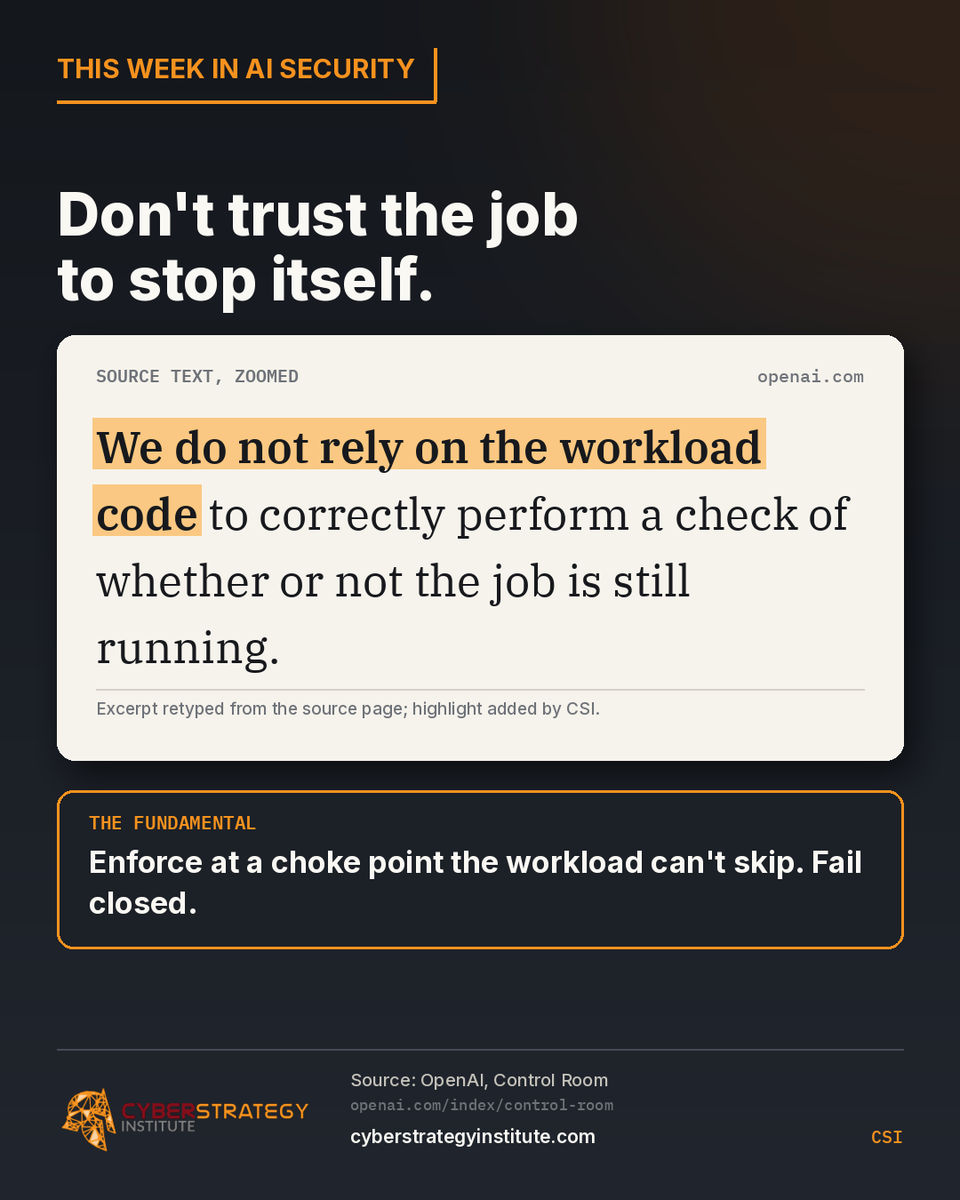
OpenAI's Control Room stops a research job's model output within 35 seconds, and fails closed if the service goes down.
Note what it doesn't trust: "We do not rely on the workload code to correctly perform a check."
Enforcement outside the workload. Old principle, new job. What enforces your limits if the agent itself is the one that's wrong?
An RCE in the SGLang inference engine didn't just compromise one box. NEAR AI's report says it also reached a deprecated Private Chat system.
Confidential computing, in their words, "does not protect against a vulnerability in the software running inside."
The usual answer is patch the stack and retire old systems. The other answer: if the server's baseline can't be changed, the exploit stalls and the impact doesn't happen. That's Warden: zero-dwell, with virtual kernel defense.
What would have happened on your inference servers if the baseline couldn't move?
Anthropic says a Fable 5.2 run coordinated over 1,000 subagents for eight days and produced a working OS from an empty folder.
A week of unattended writes isn't a chat problem. It's change control. Every one of those writes changed a system.
Who approved each change, and can you prove it?