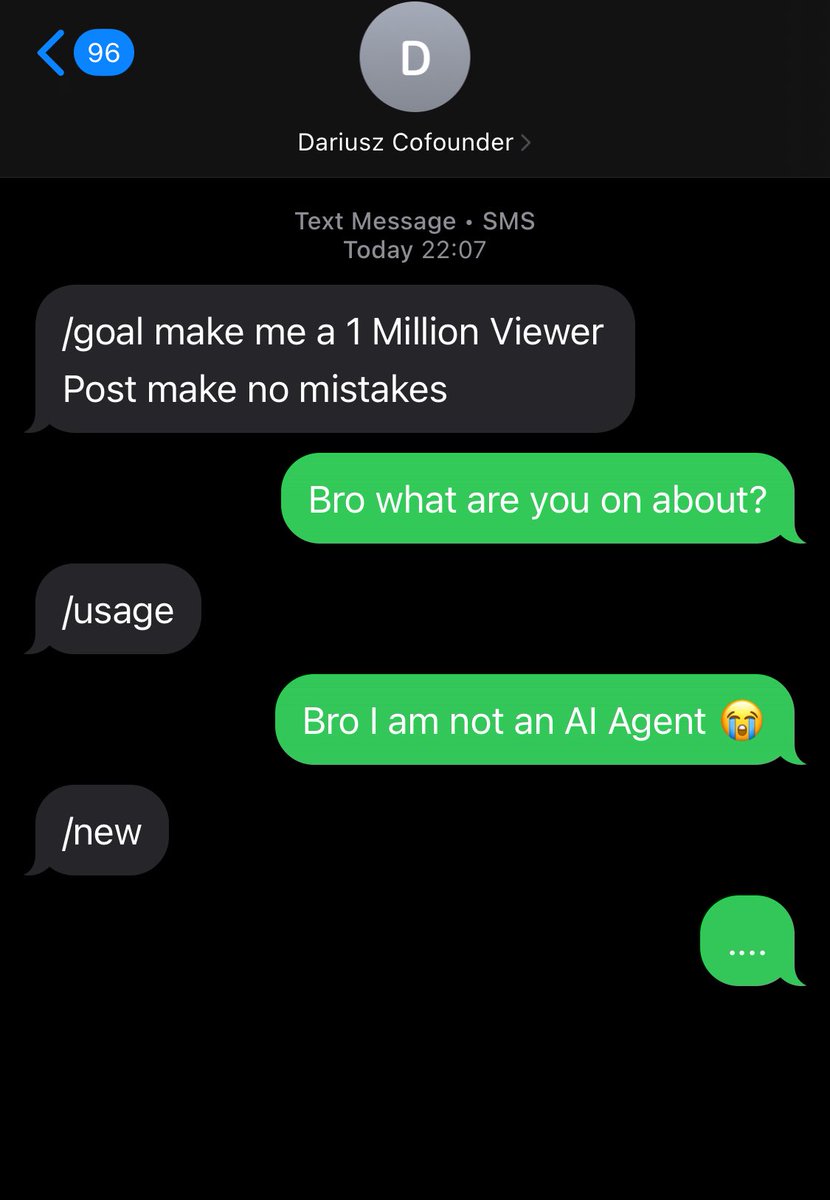
ChatGPT on macOS can now integrate with Apple Messages via a new plugin.
The plugin allows users to search through their conversations as well as write and send replies.
Y’all are seriously sleeping on this 😭
In Codex, you can enable the Max reasoning level under
Settings → Model features → Available reasoning efforts.
It gives the model more time and room to think through difficult tasks.
Okay just want to drop something.
I had an idea like @OpenAI to build a keypad for AI Agents in 24.08.2025. I stopped pursuing it.
Because I convinced myself I couldn't make it, it's too expensive, I am just 22 nobody will take me seriously, etc. etc. .
Ohh boy was I wrong, sooo wrong.
Guys this is a message to anybody reading this.
Never give up, the best startups are made by guess who? People, people just like you.
You have the capability, creativity and power to do anything you want to do if you show enough perseverance and discipline.
I regret that decision deeply, the best move would have been pivoting to software like @imnotchalk not dropping the idea. Thats why this time I am going all out with @withradian I dont care if its overcrowded, its all just blablabla, just noise to me now.
API pricing update 💰
With the V4 lineup release, we’re updating our API pricing and introducing peak and off-peak rates. Off-peak rates are 50% lower than peak, enabling more flexible workload scheduling. 📉
New pricing takes effect at 16:00 UTC, Aug 16, 2026 🕒
Okay now with this many models that keep releasing.
We are doing a promo now.
Every person who signs up to the bet gets Radian Arc for 1€ for the first month.
Be early, invest, all it takes is one singup.
Ge notified when we drop and get a super subsidised coding plan for 1 euro on European infra.
Open weights, an MIT license, 7.9B total parameters and 1.3B active: Ling 3.0 Tiny has a very practical shape for experimentation. The next question is where it holds up outside this benchmark.
Ant Group has released Ling 3.0 Tiny, which scores 25 on the Artificial Analysis Intelligence Index. With just 7.9B total and 1.3B active parameters, it sits on the Pareto frontier for Intelligence vs. Active Parameters
@AntLingAGI has released Ling 3.0 Tiny, an open weights reasoning model with a 262K-token context window. It scores 25 on the Artificial Analysis Intelligence Index, comparable to gpt-oss-120b (high, 24) with 15x fewer total parameters and 4x fewer active parameters. However, this parameter efficiency comes with high token usage: Ling 3.0 Tiny used 213M output tokens to run the Intelligence Index, nearly as many as the larger Ling 3.0 Flash (240M). It follows the recent release of Ling 3.0 Flash, which scores 38 with 124B total and 5.1B active parameters. The weights are available on Hugging Face under an MIT license.
Key results:
➤ Ling 3.0 Tiny extends the open weights Pareto frontier for Intelligence vs. Active Parameters. It scores 25 on the Artificial Analysis Intelligence Index, and at 7.9B total and 1.3B active parameters, the model is small enough to run locally in many settings
➤ Ling 3.0 Tiny makes a 59-point improvement in AA-Omniscience over Ling-mini-2.0, primarily driven by improvements in hallucination rate. Ling 3.0 Tiny scores -19 with 9% accuracy and a 30% hallucination rate, similar to Qwen3.6 27B (-20), but its accuracy is relatively low among similarly sized open weights models. Compared to the previous generation, where Ling-mini-2.0 had a 96% hallucination rate, Ling 3.0 Tiny improves on hallucination while maintaining the same accuracy. Instead of guessing when it doesn’t know, it attempted just 37% of questions in the AA-Omniscience evaluation.
➤ Ling 3.0 Tiny is relatively capable in tool use but performs modestly in agentic work tasks. Ling 3.0 Tiny scores 21% on 𝜏³-Banking, ahead of Qwen3.6 27B (17%). On GDPval-AA v2, however, it reaches an Elo rating of 772, behind Nemotron 3.5 Lightning at 824 despite sitting slightly ahead on the overall Intelligence Index.
Additional model details:
➤ Size: 7.9B total parameters, 1.3B active (mixture of experts)
➤ Context window: 262K tokens
➤ License: MIT
➤ Providers: InclusionAI first-party API and @novita_labs
Artificial Analysis measured nearly 670 tokens/s for Nemotron 3.5 Lightning on a DeepInfra endpoint using final NVFP4 weights. With 3.6B active parameters and 24% Terminal-Bench v2.1, the next test is cost per agent task.
NVIDIA has just released the first Nemotron 3.5 model: Nemotron 3.5 Lightning, a highly efficient small open weights model with performance similar to gpt-oss-120b at around a quarter of the total parameters
Nemotron 3.5 Lightning is the successor to @nvidia Nemotron 3 Nano 30B A3B, with 31.6B total and 3.6B active parameters. It retains the same hybrid Mamba-Transformer architecture and small size from Nemotron 3 Nano, but makes substantial gains in intelligence and agentic performance.
Key takeaways:
➤ Major intelligence jump: Nemotron 3.5 Lightning scores 24 on the Artificial Analysis Intelligence Index, a +9 point improvement over Nemotron 3 Nano (15). This puts it in line with OpenAI's gpt-oss-120b (24) and only just behind Nemotron 3 Super (26), a model ~4x its size
➤ Optimized for efficiency: Nemotron 3.5 Lightning sits behind the most intelligent small models in its size class such as Qwen3.6 35B A3B (32) and Muse Glimmer (high, 35) - but it is built for a different point on the frontier. In pre-release testing of a DeepInfra endpoint serving the final NVFP4 weights, we measured median output speeds of nearly 670 tokens per second, much faster than those models are served in the market today
➤ Meaningful agentic gains: the largest improvements over Nemotron 3 Nano come on agentic evaluations in GDPval-AA v2 (+334 ELO, moving past gpt-oss-120b and Nemotron 3 Super) and Terminal-Bench v2.1 (24% vs 7%). Combined with its speed and permissive OpenMDW-1.1 license, this positions Lightning as an efficient workhorse model for high-volume agentic deployments
➤ Near-lossless NVFP4 quantization: as with prior Nemotron releases, the model ships in NVFP4 alongside BF16 weights. We measured the NVFP4 variant at 24 on the Intelligence Index and saw minimal degradation compared to the higher-precision weights
Key model details:
➤ 1 million token context window, text-only reasoning model
➤ 31.6B total and 3.6B active parameters
➤ Released under the OpenMDW-1.1 license, open for commercial use without material restrictions
➤ The model weights are available now along with serverless inference from providers including @DeepInfra, @FireworksAI_HQ, @friendliai, @CoreWeave, @gmi_cloud, @nebiusai, and @CrusoeAI
Today we are introducing Dyna-2, a world-action model pre-trained on one million hours of human video. At this scale, for the first time, we discovered several new scaling laws:
• world-action models exhibit scaling law on human data across four orders of magnitude, from 1000 to 1,000,000 hours,
• this human data scaling law implied a scaling law on never seen robot data,
• both data and objective matter; world modeling and scaling on video data are essential for cross-embodiment scaling transfer to emerge
🧵