BlackBird is now on Windows!
Spin up powerful AI agents in just a click.
Train models locally, privately, and offline, right from your laptop.
Download now: https://t.co/5e2NgTnk0d
The full power of AI is now in your hands.
My pov is simple. We need more compute, but at an affordable price, where we don’t make AI a bubble. Excited to introduce our heterogeneous inference’s V0.
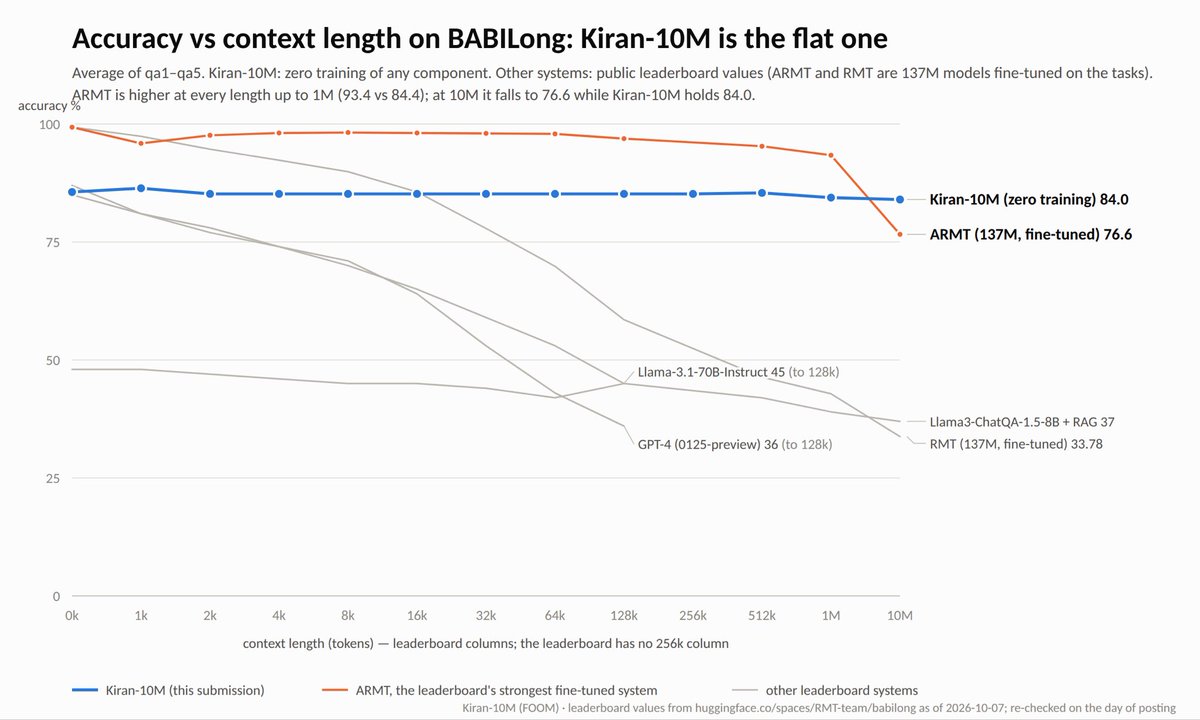
Introducing Kiran-10M: 84.0% average accuracy on BABILong qa1–qa5 at 10M tokens — and 85.6% at 0k. Same frozen 4B-class open-weights LLM, same memory, every length in between inside 84.0–86.4. Ours is the flat one. 1/7
Some early numbers from our new attention method Manojava, O(n) strictly linear on an adversarial dataset. This is completely algorithmic and different than our BF1 implementation. Both methods do not require pre-training.
It’s overwhelming to see how many people messaged me to appreciate BF1, and how it does not need model to be pre-trained to reduce attention to O(n log n). I truly enjoyed each conversation and felt inspired. Thank you! 🙏🏻
The distinction is simple: BF1 does not need to search the entire history to decide where to attend. No learned router. No history-wide similarity search. No retrieval system bolted onto the model. No need to pretrain a new architecture from scratch.
DeepSeek DSA takes a different approach: its Lightning Indexer cheaply scores each query against preceding tokens, then runs the expensive attention computation only over the selected top-k. That makes the core attention sparse—but the indexer itself remains O(n²) in prefill.
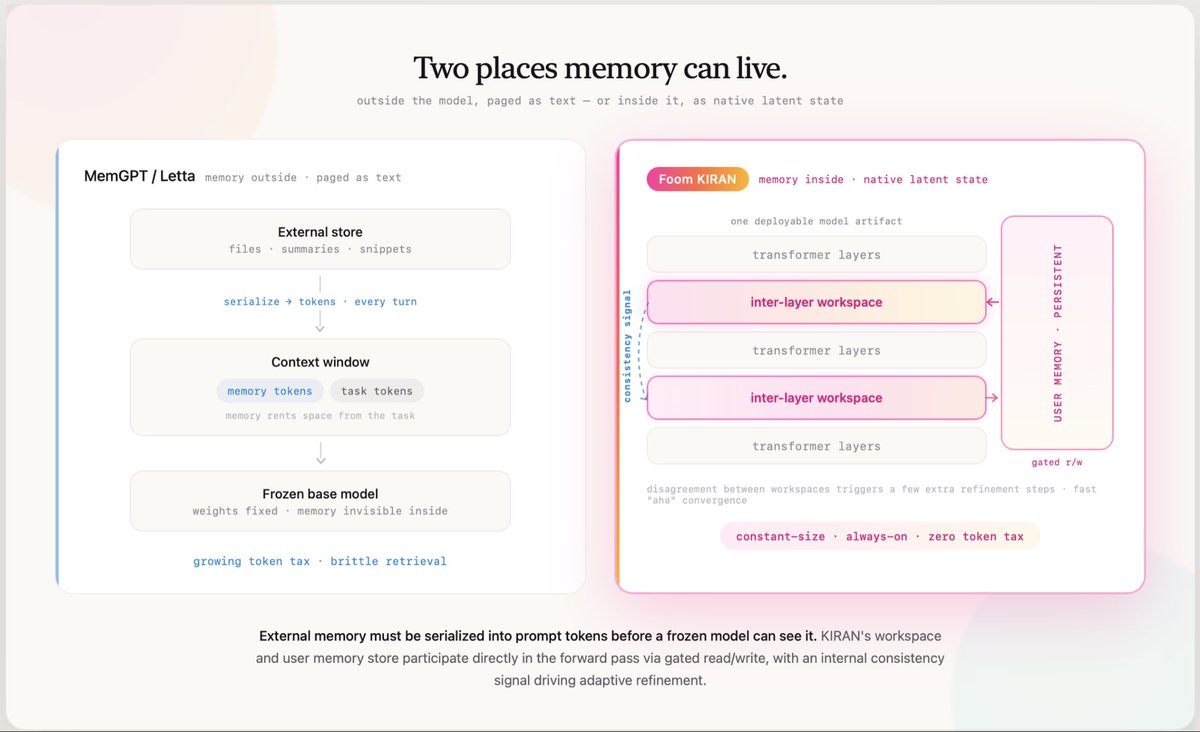
Introducing my latest work: KIRAN gives a model writable state it can revise mid-reasoning. Same weights, workspace off→on: 60.3% → 79.1%.
The next frontier is state. Not more memory - memory that can change the model’s mind.
Get your local model to learn from your Fable5 interactions, just a few clicks away. check out https://t.co/jXQzkhB6Vn to set up a local model as student and Claude as the teacher. Distill your model, with simple steps!!
Download Decompute Claude Gateway, to save on tokens, and also enable your personal model to learn from your interactions/serve you offline.
https://t.co/jXQzkhB6Vn 🚀
Companies want AI to learn from sensitive work without exposing the underlying data.
Echelon trains across privacy boundaries with aggregate-only updates.
Decompute: train without centralizing. Tune without retraining. Deploy without lock-in.
https://t.co/FWyrvBGX4A