You can achieve almost anything you want in life if you learn to master one thing: Shame. That fear of looking stupid. Fear of being judged. Fear of trying and failing in public. The reality is: People judge. People talk. And then… people forget. So, fuck what people think. Just do what you gotta do. This one singular mindset shift can change your whole life.
As an AI Engineer, you must build these projects.
Systems that prove you can retrieve, reason & ship.
1.) Production RAG Pipeline
Build: Ingestion → chunking → hybrid search → reranking → cited answers over 1000+ docs.
Why: Retrieval quality decides if your LLM product lives or dies.
2.) Structured Output Engine
Build: Pydantic schema enforcement with retries, validation, graceful fallbacks on malformed JSON.
Why: Apps break on free text. Schemas make LLM output usable.
3.) Context Assembly Service
Build: Dynamic context builder that budgets tokens across memory, docs & tools per request.
Why: Context engineering beats prompt tweaking in production.
4.) LLM Evaluation Harness
Build: Golden dataset + LLM-as-a-judge + CI gate that blocks merges on quality regression.
Why: You cannot ship what you cannot measure.
5.) Semantic Cache Layer
Build: Embedding-based cache returning stored answers for similar queries, with hit-rate tracking.
Why: The cheapest token is the one you never generate.
6.) Model Routing Gateway
Build: Complexity-based router across 3 model tiers with fallbacks and per-request cost tracking.
Why: Unit economics decide if your AI product survives.
7.) Multi-Tenant LLM API
Build: Per-tenant keys, rate limits, token budgets, isolated data access.
Why: Enterprise customers demand isolation and spend control.
8.) Fine-Tuning Pipeline
Build: LoRA/QLoRA fine-tune of a small model on synthetic data, benchmarked vs prompt-only baseline.
Why: Know when adaptation beats prompting, and when it doesn't.
9.) Agent Memory System
Build: Working + episodic + semantic memory with compression and eviction policies.
Why: Agents without memory fail by turn five.
10.) Guardrails Middleware
Build: Input/output filtering, PII redaction, injection detection as a reusable service layer.
Why: One leak destroys trust. Safety must be infrastructure.
11.) Streaming Response Infrastructure
Build: SSE streaming with backpressure, reconnects, time-to-first-token tracking.
Why: Perceived latency is the UX of AI products.
12.) Prompt Versioning and A/B System
Build: Registry for prompts and configs with rollback, traffic splitting, outcome tracking.
Why: Prompts are production code. Treat them that way.
13.) LLM Observability Stack
Build: Tracing for prompts, tokens, latency, cost per request with alerting on anomalies.
Why: You cannot debug what you cannot see, especially non-determinism.
14.) Tool-Calling Framework
Build: Typed function schemas with discovery, retries, sandboxed execution.
Why: Tools turn chatbots into systems that actually do work.
15.) Self-Correcting RAG Agent
Build: Query rewriting, retrieval critique, confidence-based fallback to web search.
Why: Production retrieval must repair itself, not hallucinate.
Most people watch tutorials. Builders ship systems.
Bookmark & Repost.
at this age? focus on your career & goals. save money & travel. we can no longer afford to waste time again. focus on things that matter in the long run. you will never be this young again.
AI engineers are printing money right now.
But only if they know this:
Most people are learning the wrong things.
Courses won’t get you hired.
Skills will.
Here’s what actually pays in 2026:
→ Building end-to-end LLM systems
(not just calling APIs)
→ Working with real data pipelines
(cleaning, chunking, retrieval)
→ RAG that actually works in production
(not tutorial-level demos)
→ Inference optimization
(vLLM, batching, caching)
→ Evaluations
(DeepEval, human feedback loops)
→ Agents (only where needed)
(LangGraph > hype wrappers)
What companies actually want:
→ Someone who can ship
(not just experiment)
→ Someone who understands tradeoffs
(latency vs cost vs quality)
→ Someone who can debug broken outputs
(not blame the model)
→ Someone who thinks in systems
(not prompts)
The gap is simple:
Most people are learning tools.
Few people are building systems.
That’s where the money is.
If you’re learning AI right now:
Stop collecting certificates.
Start shipping projects.
Kobe Bryant once said:
“I have nothing in common with lazy people who blame others for their lack of success. Great things come from hard work and perseverance. No excuses.”
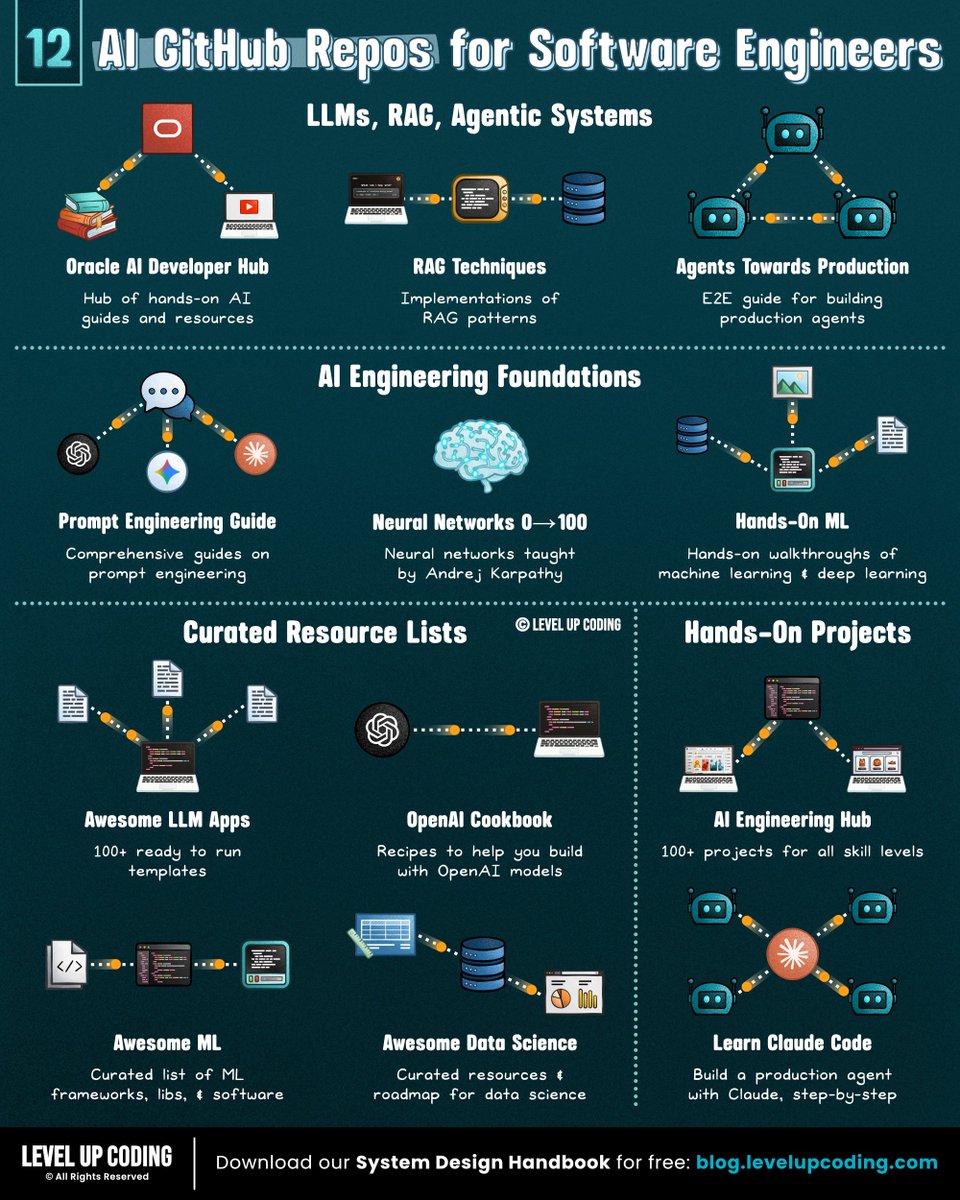
12 GitHub repos to improve at AI engineering (categorized):
𝗟𝗟𝗠𝘀, 𝗥𝗔𝗚 & 𝗔𝗴𝗲𝗻𝘁𝗶𝗰 𝗦𝘆𝘀𝘁𝗲𝗺𝘀
1) Guides to build RAG, agents, vector search
↳ https://t.co/4pS9LoP7Jj
2) RAG patterns
↳ https://t.co/CuxQNIWvi7
3) E2E guide for building agents
↳ https://t.co/X0NG8cD5Uz
𝗔𝗜 𝗘𝗻𝗴𝗶𝗻𝗲𝗲𝗿𝗶𝗻𝗴 𝗙𝗼𝘂𝗻𝗱𝗮𝘁𝗶𝗼𝗻𝘀
4) Prompt engineering
↳ https://t.co/M52RFxgbQi
5) Hands-on ML + deep learning
↳ https://t.co/53ptKmr0ha
6) Neural networks
↳ https://t.co/CWXnpHdWLJ
𝗖𝘂𝗿𝗮𝘁𝗲𝗱 𝗥𝗲𝘀𝗼𝘂𝗿𝗰𝗲 𝗟𝗶𝘀𝘁𝘀
7) Examples building with openAI
↳ https://t.co/KhOcsplmnN
8) Ready to run templates
↳ https://t.co/m90Wvs3UiN
9) ML frameworks, libs, & software
↳ https://t.co/iymK7nAD3y
10) Data Science resources
↳ https://t.co/6EyxbXUhMn
𝗛𝗮𝗻𝗱𝘀-𝗢𝗻 𝗣𝗿𝗼𝗷𝗲𝗰𝘁𝘀
11) 100+ projects
↳ https://t.co/IoHAVVMY8t
12) E2E project with Claude Code
↳ https://t.co/APyrkkA3d0
If you're serious about AI engineering, this repo is worth bookmarking (star it): https://t.co/J9Xcu4JUMc
It’s not just theory; you’ll find:
• Full AI apps and reference implementations
• Jupyter notebooks for RAG, agents, and vector search
• Practical guides on agent architecture and memory systems
If you found this list useful, star the repo so you can come back to it later (and support more content like this)
What other AI GitHub repos should be on the list?
——
♻️ Repost to help others learn AI engineering.
🙏 Thanks to @Oracle for sponsoring this post.
➕ Follow me ( Nikki Siapno ) to improve at AI engineering.
SOFTWARE ENGINEERS,
This 24 minutes video will teach you how to actually prompt Claude.
Not only Claude, basically any LLM.
Anthropic's own team leading this workshop.
Worth more than thousand bucks, Available FREE.
Watch NOW.
Bookmark for LATER.
Why is no one talking about this?
@nvidia is offering around 80 AI models via hosted APIs absolutely for free.
You get access to MiniMax M2.7, GLM 5.1, Kimi 2.5, DeepSeek 3.2, GPT-OSS-120B, Sarvam-M etc.
This plugs straight into OpenClaude, OpenCode, Zed IDE, Hermes agent and even with Cursor IDE.
Setup:
– Grab API key: https://t.co/Wfdclm0hY2
– base_url = "https://t.co/VOGC10LmGP"
– api_key = "$NVIDIA_API_KEY"
– select model (e.g. minimaxai/minimax-m2.7)
If you’re building or experimenting, this is basically free inference.
Lock in and start building today anon.
Thank me later.
DAY 02 of #100DaysOfCode
Here is my activity log :
🎯Problems Solved:
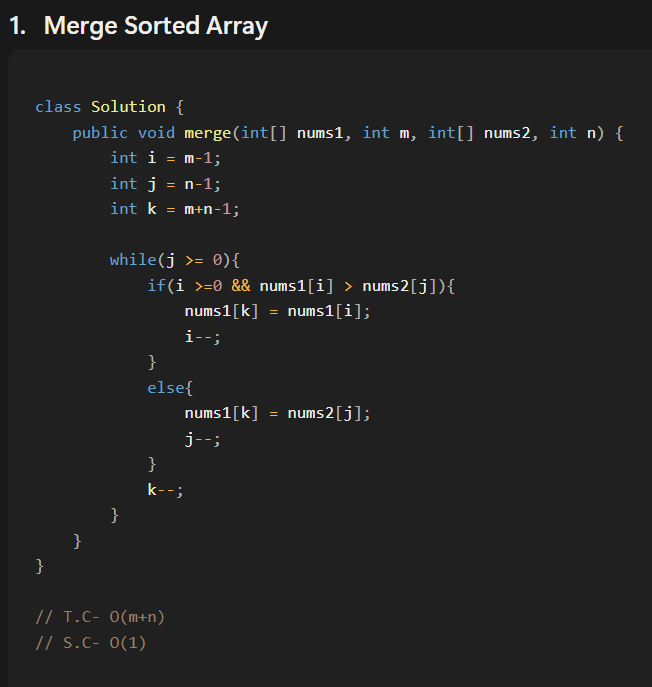
1- Merge Sorted Array
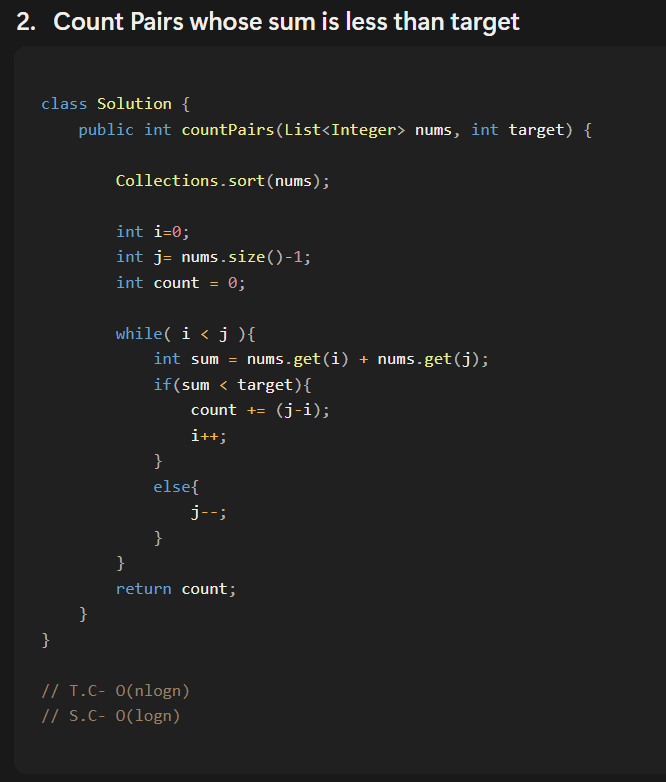
2- Count Pairs Whose Sum is Less than Target
3- Two Sum
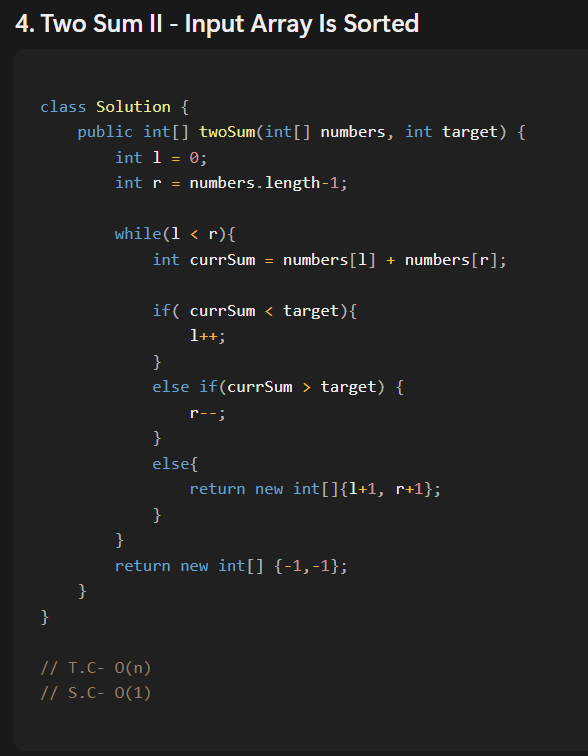
4- Two Sum II - Input Array Is Sorted
5- 3Sum
#DSA#LearningInPublic#TwoPointers#DSAinJava