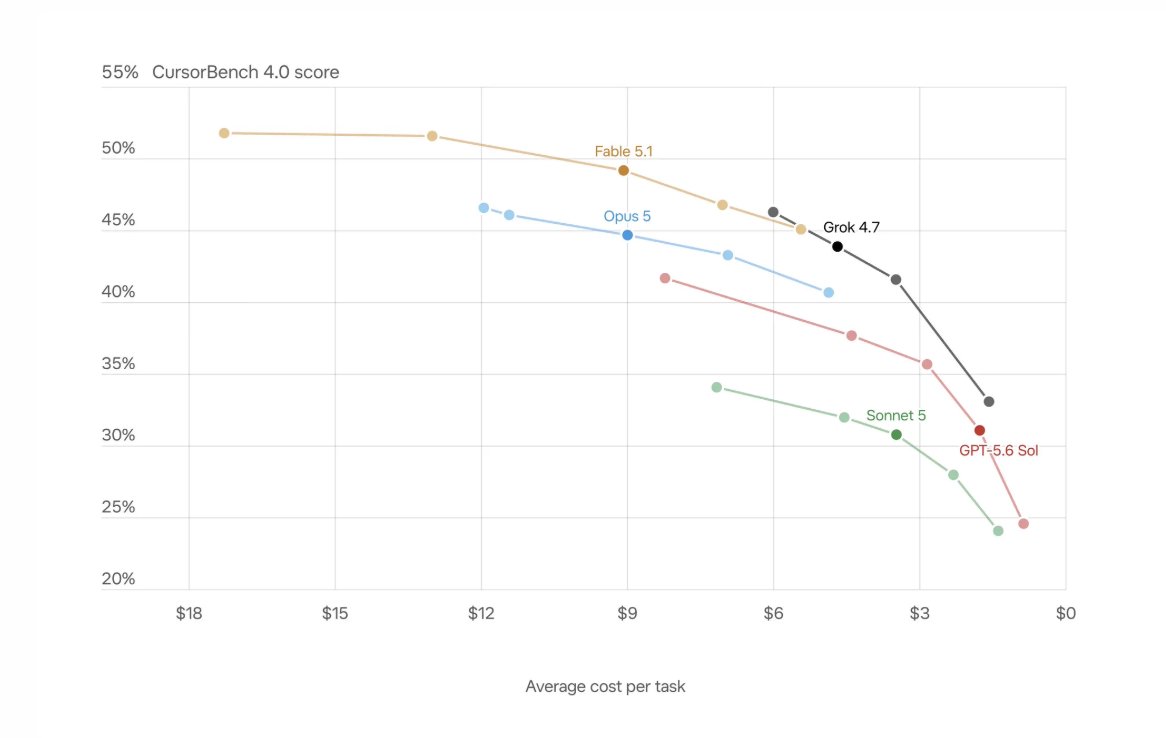
Grok 4.7 just released and it's an EXCELLENT model
It was trained FOR Grok Bot
Meaning this is a fully agentic model trained to do your knowledge work better than you can
In this video I show you how to use Grok 4.7 and a Grok Bot workflow that will 10x your productivity:
Grok 4.7 xHigh is now at the top with just ONE point away from Claude Fable 5.1 Max on Artificial Analysis’ AA-Briefcase benchmark
Claude Fable 5.1 Max — 59%
Grok 4.7 xHigh — 58%
Just a 1-point difference at the very top
And Grok is ahead of GPT-6 Astra, GPT-5.6, Gemini, Kimi, GLM and nearly every other frontier model on the benchmark
and here’s the grok 4.7 model card. a few jumps vs 4.6 that stood out:
- Terminal-Bench: 20.3% → 38.0%
- SWE-Marathon: 31.9% → 46.0%
- HealthBench Pro: 48.5% → 56.7%
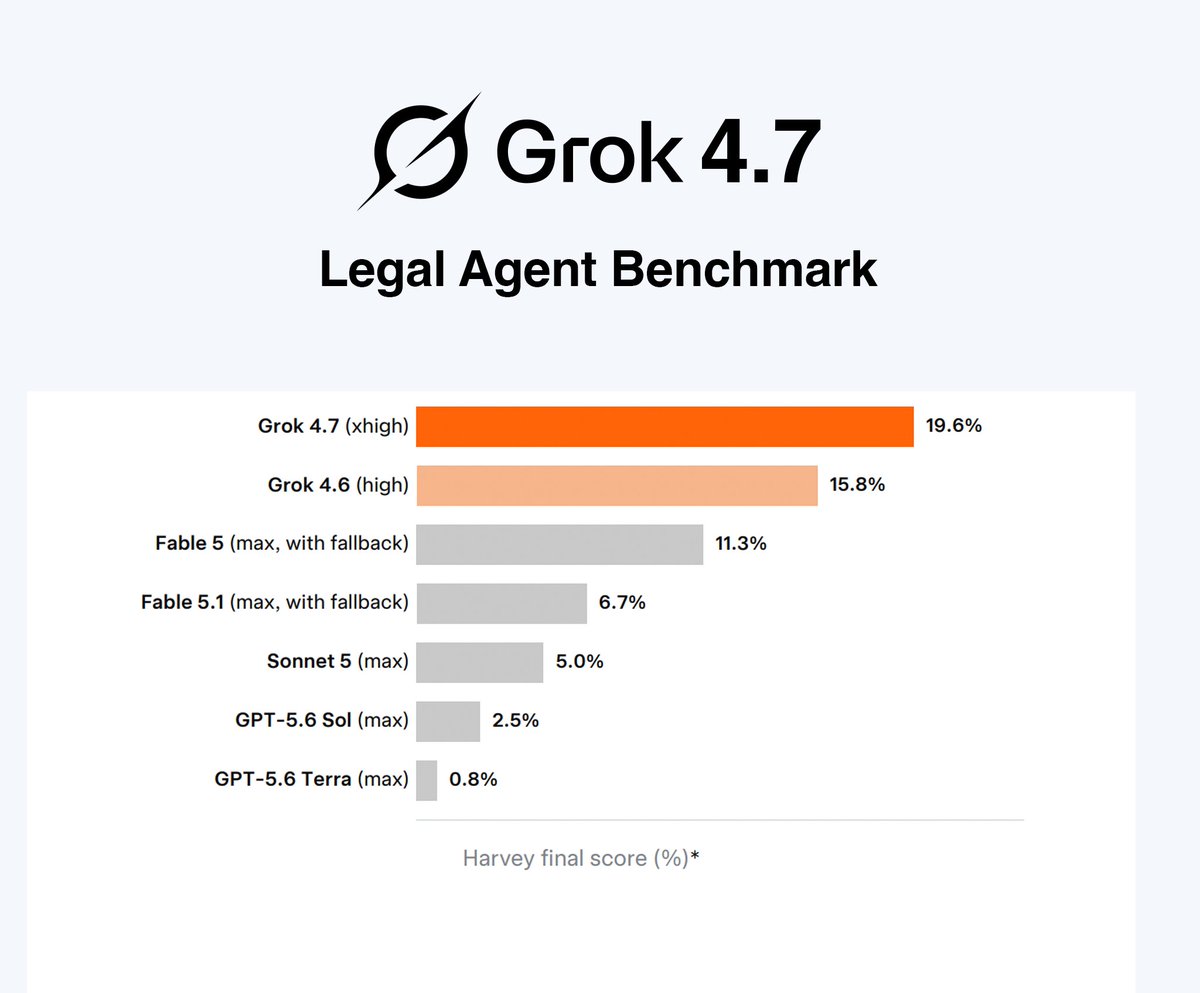
- Legal Agent: 15.8% → 19.6%
- EEBench: 60.0% → 66.0%
for the same price as 4.6!
https://t.co/C0iyfYirQf
“I’ve used FSD for like 90%+ of my miles since Saturday morning. Literally feels like magic. Has handled issues on the road better than I would have at times.
Just remarkable technology”
A demo drive might change your life
https://t.co/YkC5K8ofeR
BREAKING: Grok 4.7 dominates the Legal Agent Benchmark.
It scored 19.6% on realistic, long-term legal tasks, beating every other model tested. That is nearly 3× Fable 5.1.
Another major win for Grok 4.7 and SpaceXAI.