🎬 𝗔 𝟯𝟱𝗕 𝗔𝗜 𝗹𝗮𝗻𝗴𝘂𝗮𝗴𝗲 𝗺𝗼𝗱𝗲𝗹. 𝗥𝘂𝗻𝗻𝗶𝗻𝗴 𝗹𝗼𝗰𝗮𝗹𝗹𝘆 𝗼𝗻 𝗮 𝗠𝗮𝗰.
This is 𝗘𝗱𝗴𝗲𝟬-𝟯𝟱𝗕 𝗶𝗻 𝗮𝗰𝘁𝗶𝗼𝗻 in our macOS desktop app.
💻 Edge0 keeps the quantized model weights on SSD and streams the expert weights it needs on demand, instead of loading the full 35B model into memory.
📊 In our macOS app benchmark, 𝗘𝗱𝗴𝗲𝟬-𝟯𝟱𝗕 𝗿𝗮𝗻 𝗮𝘁 𝟭𝟬–𝟭𝟮 𝘁𝗼𝗸/𝘀 𝘄𝗶𝘁𝗵 𝟰 𝗚𝗕 𝗿𝗲𝘀𝗶𝗱𝗲𝗻𝘁 𝗺𝗲𝗺𝗼��𝘆 𝗼𝗻 𝗮𝗻 𝗠𝟯 𝗠𝗮𝗰𝗕𝗼𝗼𝗸 𝗔𝗶𝗿.
🔒 Once the model is downloaded, inference runs 𝗹𝗼𝗰𝗮𝗹𝗹𝘆 𝗮𝗻𝗱 𝗼𝗳𝗳𝗹𝗶𝗻𝗲 — your prompts stay on your device, with no cloud API or per-token fees.
🖥️ And yes, there’s an actual desktop app. 𝗡𝗼 𝐦𝐨𝐫𝐞 𝘄𝗿𝗲𝘀𝘁𝗹𝗶𝗻𝗴 𝘄𝗶𝘁𝗵 𝘃𝗲𝗻𝘃. Open the app, download a model, load it, and start chatting.
𝗢𝗽𝗲𝗻-𝘀𝗼𝘂𝗿𝗰𝗲. 𝗙𝗿𝗲𝗲 𝘁𝗼 𝘁𝗿𝘆.
👇 𝗧𝗿𝘆 𝗶𝘁 𝘆𝗼𝘂𝗿𝘀𝗲𝗹𝗳
https://t.co/eMgSvUs86l
💬𝗝𝗼𝗶𝗻 𝗼𝘂𝗿 𝗗𝗶𝘀𝗰𝗼𝗿𝗱 to get help with setup or share what you’re building:
https://t.co/mylrAoTyDi
Follow us for more Edge0 demos, benchmarks, and use cases.
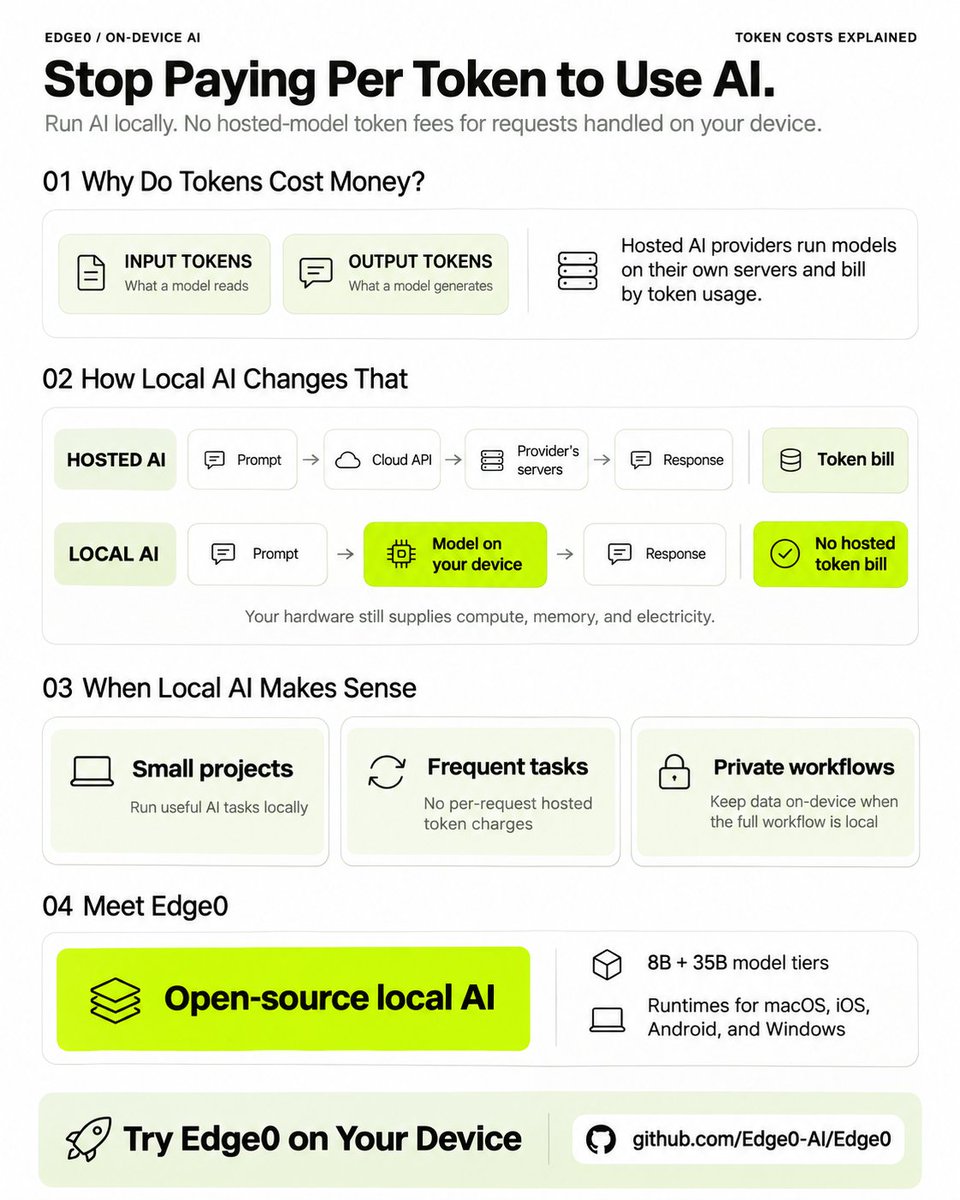
Edge0 is open source, with 8B and 35B models and runtimes for macOS, iOS, Android and Windows.
Want to try local AI on your own hardware?
Code and setup:https://t.co/6TrEfyTlry
Discord:https://t.co/wHJXOvr870
Stop paying per token for AI tasks you can run locally.
Hosted AI APIs charge for the tokens your model reads and generates. With local AI, your own hardware does the work.
And no, you don't need an expensive workstation to get started.
Here's how.
How?
Edge0 uses 4-bit quantization and streams expert weights from storage as needed, rather than keeping the entire model in RAM.
That makes large sparse models practical on smaller devices.
Hardware, storage and electricity still cost money, of course.
Code and setup: https://t.co/6TrEfyTlry
Join our Discord for setup help or to share what you’re building: https://t.co/wHJXOvr870
Follow @Edge0_AI for implementation notes and upcoming releases.
As @rauchg said: "Own your intelligence." We agree.
That includes running AI locally, choosing which model your application uses, and deciding when to update it.
At @Edge0_AI, our 35B and 8B model weights and inference code are available under Apache 2.0. You can download a model, run it locally, and inspect or modify the runtime.
Your application can call that deployment through a local API. You can keep a tested version running while evaluating updates, and use hosted models alongside it.
We want local AI to be a real option for everyone, not just people with high-end hardware.
That's what we're building toward at Edge0.
We're open source, and we have a major release coming next month. Check out our GitHub, join the discussion, and follow along!
Links in the comment section:
Own your intelligence.
Anyone that opposes this has something to sell you (perhaps your own intelligence back to you.)
Local models need to continue proliferating. The “absolute unit” massive models may be out of reach for now locally, so your best option is to, indeed, keep your options open. Own your harness, data, connections, runtime: your agents. Embrace open source.
@rauchg If you’re exploring local AI, we’d love to have you join us.
GitHub: https://t.co/6TrEfyTlry
Discord: https://t.co/wHJXOvr870
We have a major local AI release planned for next month. Follow along—we’re excited to share it.
@rauchg One thing holding local AI back is the trade-off between capability and hardware. Smaller models don't always cover what people need, while more capable ones can be tough to run on a regular 16–32GB laptop.
That's a gap we're working to close at Edge0.
Now THIS is chicanery.
@aisearchio cloned Chuck McGill’s voice using nothing but clips from his Better Call Saul hearing.
Something tells me Jimmy wouldn't approve of this, although Saul Goodman would probably be asking how he could get in on the action. Here's how you can start: https://t.co/wNK93s5v1H
Or join our community: https://t.co/GHS2msUmmm
Try Edge0 on GitHub: https://t.co/6TrEfyTlry
Model info: https://t.co/AVlaGxpHiF
Join our Discord to get help with setup or share what you’re building: https://t.co/GeArDbDefs
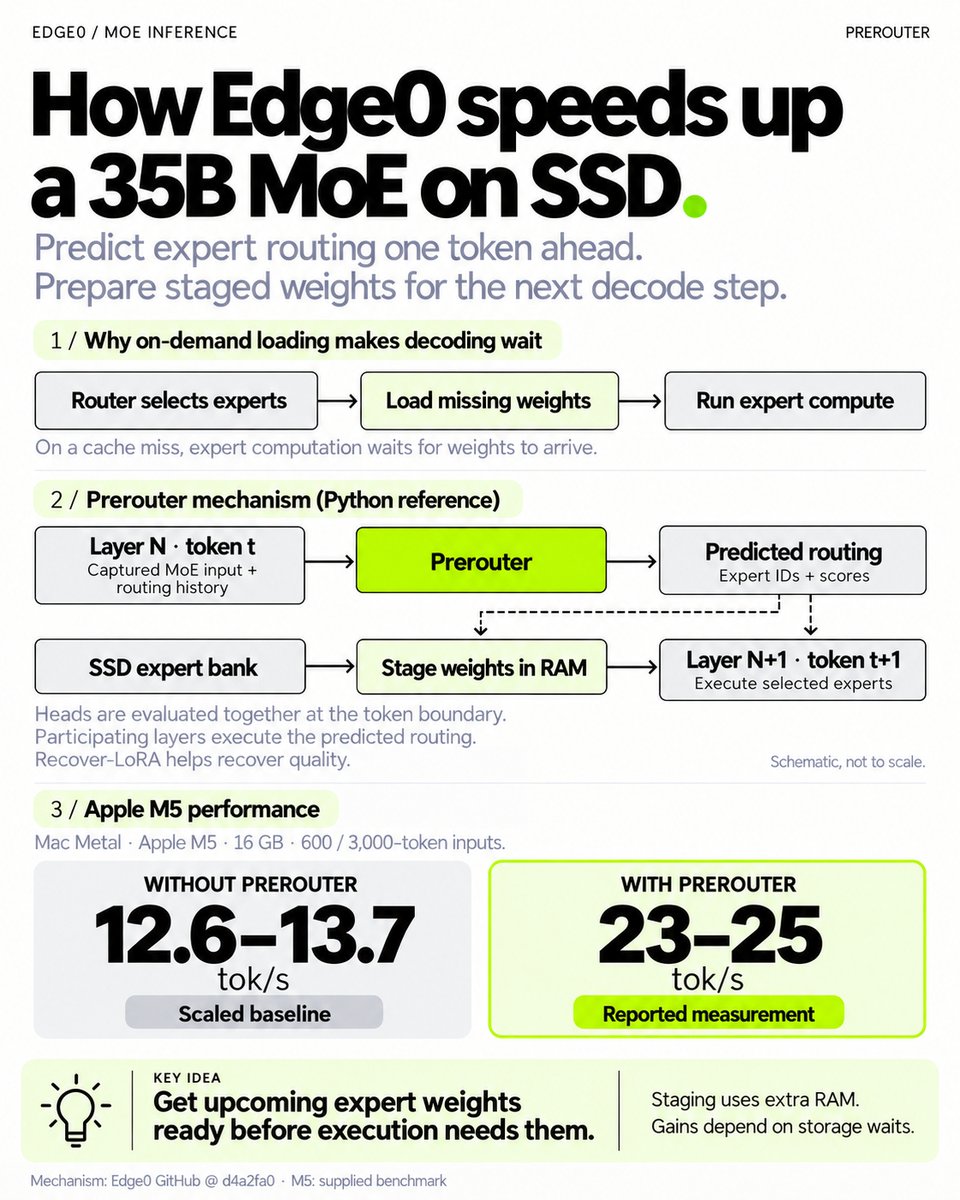
1/6 Edge0’s Mac Metal engine decodes at 23–25 tok/s on Apple M5 with 16 GB RAM, while keeping its expert bank on SSD.
How do you keep a 35B MoE moving when a needed expert’s weights may still be on storage?
Our Prerouter predicts expert selections one token ahead, giving the engine advance notice of which weights to prepare. 🧵
6/6
SSD offload changes where expert weights live. The prerouter changes when the engine can prepare them.
That advance knowledge lets Edge0 stage upcoming experts before execution needs their weights.