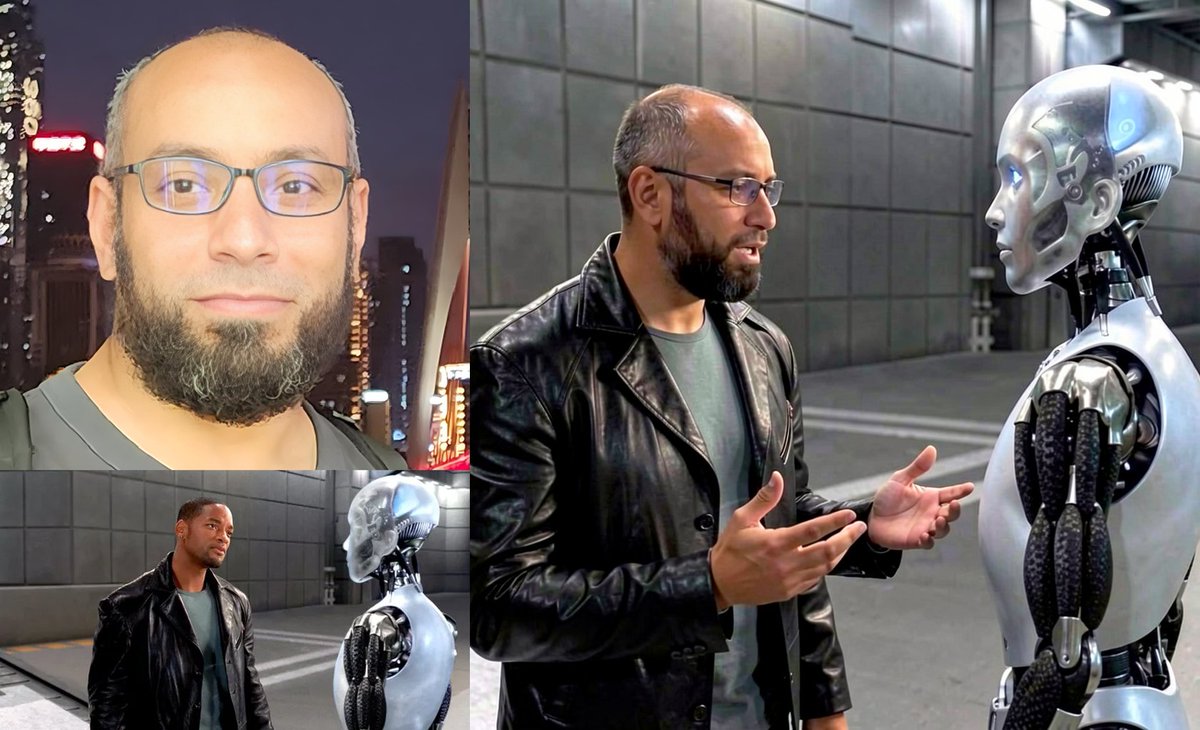
Testing Minimax H3 with ComfyUI. Me and Will Smith doing the spaghetti test...
Inference done locally on 5090 24GB VRAM, 20 Steps, Sage Attn + Sol Attn + Spectrum, took about 27 minutes for a 15s 1280x736 video.
We are cooked.
China's Alibaba just revealed Wan Streamer.
AI agents can now see you, hear you, and talk back on video in real time.
This is not voice mode anymore 🤯
@JoelDeTeves@DJLougen@spiritbuun I'm using DJLougen/Ornstein-27B-GGUF:Q4_K_M on RTX5090 (24GB VRAM Laptop), getting about 32-34 TPS. It's good with Hermes so far but a bit slow, would you recommend to switch to Ornstein-26B-A4B to get higher TPS or will it sacrifice the quality?
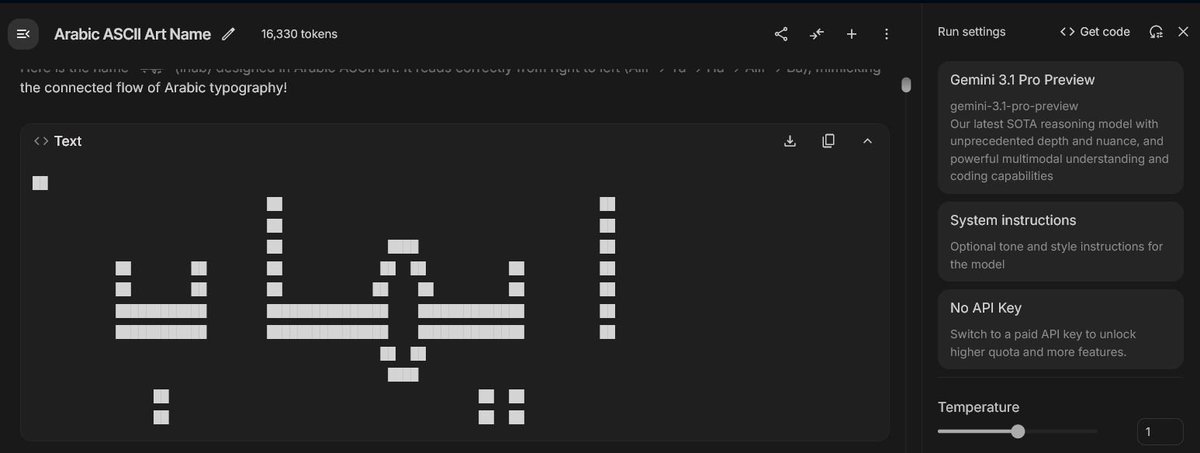
I was playing with Gemini 3.1 Pro on Google AI Studio, and I've to say that this model is easily the best model out there, even better than Opus 4.6.
Also this is the only model that managed to successfully create Arabic ASCII art for my name "إيهاب"
Black Forest Labs released FLUX.2 [klein], it's the latest, fastest and greatest image model that you can run locally even as low as 8GB VRAM. It's also supporting multi-referenced images! I played with it and now it's easily one of my favorite models...