50 crazy things you can build with a $4 ESP32:
Tracking, Radar & Physical Access:
1. Wi-Fi Radar (ESP-CSI): Tracks human movement and detects breathing through solid walls using Wi-Fi wave reflections.
2. Satellite Ground Station (TinyGS): Catches live telemetry from satellites orbiting 500 km in space.
3. Free Worldwide GPS (OpenHaystack): Hijacks Apple's Find My network to track physical items globally without an AirTag or SIM card.
4. Badge Reader Wiretap (ESPKey): Tucks behind an office badge reader to steal employee cards and pop doors open over Bluetooth.
5. Magstripe Emulation (MagSpoof): Drives an electromagnet to wirelessly spoof magnetic stripe card swipes at payment terminals.
6. Sub-GHz Gate Replay: Captures and replays 315/433 MHz radio signals to open motorized gates and barriers.
7. Covert Audio Bug: Streams live microphone audio over encrypted local Wi-Fi from an implant smaller than a coin.
8. Passive Foot Traffic Sniffer: Logs nearby smartphone probe requests to map crowd movement and visitor arrival times.
9. Elevator Floor Override: Connects to elevator relay banks to activate restricted floors without a keycard.
10. NFC/RFID Cloner: Reads 13.56 MHz High-Frequency badges and clones card UIDs on demand.
🧵 (1/5)
Por favor, difusión 🙏
Hi @AnthropicAI, @ClaudeDevs, @claudeai and @DarioAmodei, please help.
Our friend @miriamgonp needs access to your models to keep fighting breast cancer. She has built her own team of AI agents to help study her case, and credits to use your models would be a tremendous help.
The Dana-Farber Cancer Institute itself has acknowledged that the information uncovered by the agents can be very helpful.
It’s a small thing for you, but it would mean so much to her. Thank you.
@ItsmeAjayKV Congrats on 100+
Made you a receipt-style badge for the README if you want it, updates itself from the GitHub API:

My tool, free, no strings. Four styles (brutal, metal, cyber, thermal) if metal isn't your thing.
Qwen3.8-27B on a single RTX 3060 12GB. Best 2-bit setup I've found for a 12GB card. (config below)
Same GGUF, one flag apart:
MTP on -> 40 tok/s, 110K ctx
MTP off -> 23 tok/s, 165K ctx
Prefill barely moves (470 vs 493). It's decode speed vs context, nothing else.
Weight is @atomic_chat_hq AD-IQ2_XXS (8.98 GB), not @UnslothAI's smaller 7.27 GB -- the MTP head is inside the GGUF instead of a sidecar. Unsloth's chart plots size "with removal of MTP"; add the sidecar back and the gap mostly closes.
Draft acceptance 0.57-0.71, mean len 2.7-3.1.
I run reasoning_effort low. medium is fine for some tasks, but the default xhigh doom-loops at 2-bit. (effort level benchmark in the replies)
-m Qwen3.8-27B-AD-IQ2_XXS.gguf -ngl 99 -c 110000 -fa on --jinja -np 1 --spec-type draft-mtp --cache-type-k q4_0 --cache-type-v q4_0 -b 1024 -ub 512 --temp 1.0 --top-p 0.95 --top-k 20 --min-p 0.0 --presence-penalty 0.0 --repeat-penalty 1.0 --reasoning on --chat-template-kwargs '{"reasoning_effort":"low"}'
Drop --spec-type draft-mtp and set -c 165000 for the long-context variant.
@fyidhrumil@DogukanUrker at $0/token and with private data.
No, it doesn't replace a frontier model. It doesn't need to.
The whole point is 35B-scale capacity with ~3B active params on hardware people already own.
@fyidhrumil@DogukanUrker “Only useful for autocomplete” is a pretty wild definition of useful.
I'm running it locally on a 12GB RTX 3060 for coding, repo analysis, debugging, refactoring, agents, tool calling, automation, research, SEO pipelines, classification/extraction and long-running workflows
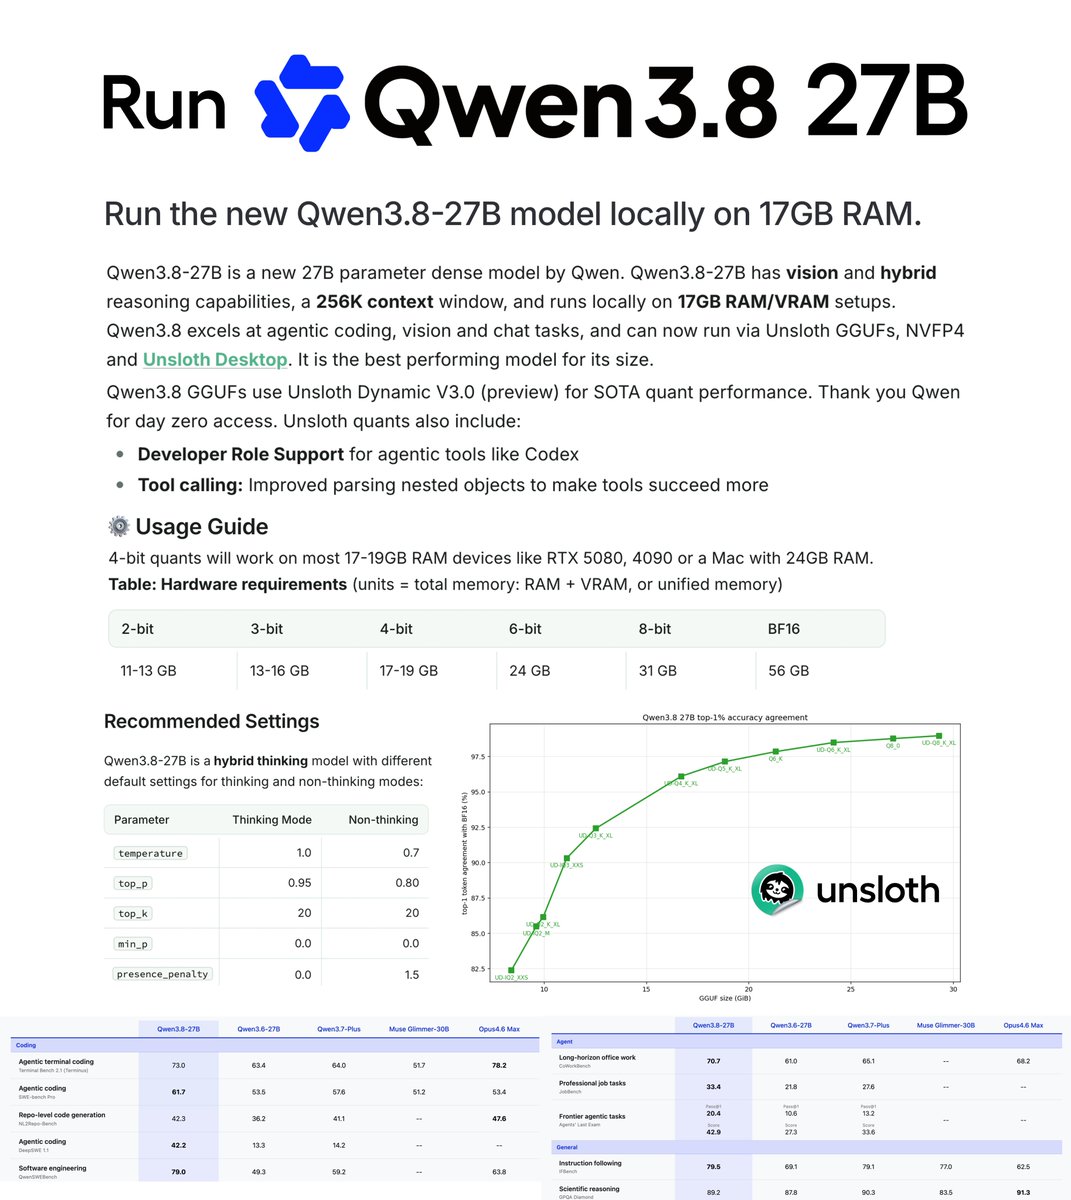
Qwen3.8-27B can now be run locally! ✨
Run on 17GB RAM via Unsloth Dynamic GGUFs.
Qwen3.8-27B is by far the strongest model for its size. We also uploaded NVFP4 quants.
GGUF: https://t.co/xIdNwm7CLQ
Guide: https://t.co/J2PwgMP6GZ
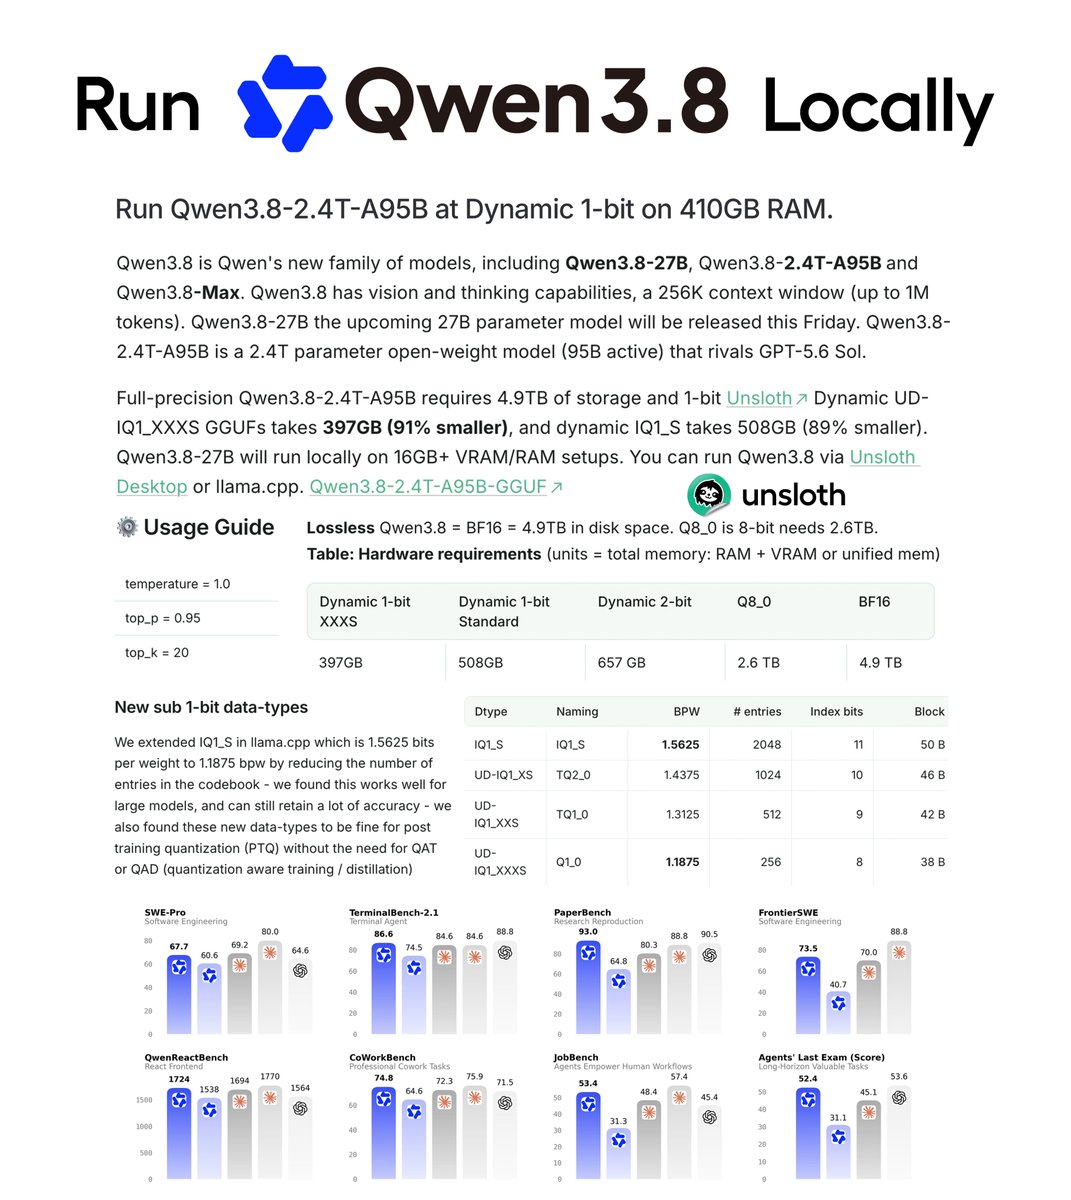
Qwen3.8 can now be run locally! 🔥
We shrank Qwen3.8-2.4T-A95B from 4.9TB to 397GB (-91% size) via Dynamic 1-bit by selectively quantizing layers
Run on 410GB+ RAM/VRAM via Unsloth Desktop
Qwen3.8 rivals GPT-5.6 Sol
Guide: https://t.co/J2PwgMP6GZ
GGUF: https://t.co/7K1KdtnO2I
Introducing NVIDIA Nemotron 3.5 Lightning⚡
An open 30B MoE model with 3B active parameters, built for always-on agents to complete high-volume, specialized tasks faster.
It delivers up to 4x the output speed of similar-sized models.
95K / 184K context used.
99.9% cache hit.
Qwen running locally through llama.cpp.
And it’s not answering questions.
It’s actually running the workflow, inspecting the system, making decisions and moving the project forward.
Local agents are getting serious. 🧠🔥




My tool, free, no strings. Four styles (brutal, metal, cyber, thermal) if metal isn't your thing. https://t.co/0QZNdyNuln](https://pbs.twimg.com/media/HQbbRzqW8AAC54n.jpg)