Turn documents into Agent-Friendly data!
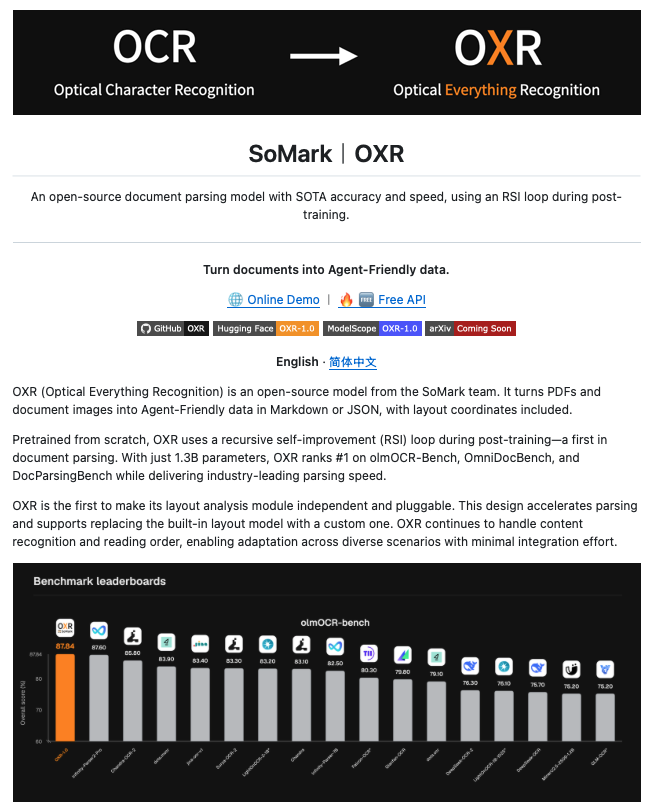
OXR is a 1.3B open-source document parsing model that turns PDFs and document images into structured Markdown or JSON.
Instead of extracting text alone, it recognizes 13 different document elements including tables, formulas, figures, code blocks, footnotes, and chemical structures, while preserving reading order and layout coordinates.
That makes the output much more useful for RAG and agents, where knowing what the text says is only one part of the problem. You also need to know what is a table, where a formula belongs, which caption maps to which figure, and how the document should actually be read.
The technical part I found interesting is how OXR was post-trained.
It uses a recursive self-improvement loop where OXR first parses unlabeled documents, then a general VLM reviews the outputs for errors and uncertainty.
Disagreement across multiple OXR rollouts helps surface uncertain examples, those failures are grouped by cause, and the VLM generates targeted training data for the next round.
So instead of manually labeling new data for every iteration, the model’s own parsing failures help decide what it should train on next.
The architecture is also different from the usual parsing pipeline.
Layout analysis stays independent and pluggable, while recognition and content-aware reading order run in parallel inside the main model. That means teams can replace the layout model for their own document structure without replacing the rest of OXR.
And the results are strong for a 1.3B model.
OXR ranks #1 on olmOCR-Bench, OmniDocBench, and DocParsingBench. In the reported 100-page speed test on a single RTX PRO 6000, OXR finished in about 101 seconds vs. 161 seconds for DeepSeek-OCR-2.
The full model is open source.
Looks like Cursor 1.2 is rolling out, now with:
- Todo items that stick right by the chat box 😍
- Ability to queue up messages (or interrupt)
- Faster Tab
- Resolve merge conflicts with Agent
- Background Agent improvements
- VS Code upgrade to 1.99
وزير الدفاع الإسرائيلي يعترف بالهزيمة اليوم في غزة ويقول : "لقد تكبدنا ثمنا باهظا خلال العملية البرية في غزة"
و أبو عبيدة يعلن :"دمرنا 22 آلية عسكرية في كل المحاور ونلتحم مع العدو وقتلنا عددا كبيرا من الجنود"
ويهدد نتنياهو قائلا:"نبشر نتنياهو أنكم ستجثون على ركبكم ولا يزال في جعبتنا الكثير وغزة مقبرة للعدو"
إن ما يمارسه الاحتلال الصهيوني الغاشم الآن في غزة من قصف مكثَّف، وقتل، وقطع للكهرباء والإنترنت، وتدمير لكل مظاهر الحياة، وحجب كلِّ مصادر الحقائق والمعلومات حول ما يحدث من مجازر وجرائم حرب، لهو إرهابٌ أعمى، وانتهاكٌ واضحٌ لكل المواثيق والأعراف القانونية والإنسانية، وعلى العالم إدانته واتخاذ الإجراءات الحاسمة لوقفه فورًا، ولن يرحمَ التاريخ كل مَن تخاذلوا في الدفاع عن الفلسطينيين الأبرياء، وكلَّ مَن دعم استمرار هذا الإرهاب الصهيوني.
وواجب على الأمة العربية والإسلامية وكل أحرار العالم التكاتف لإيجاد حلٍّ فوري لإنقاذ هذا الشعب المظلوم الذي يُمارسُ ضده مجزرة إنسانية لم يعرف التاريخ الإنساني مثيلًا لها.
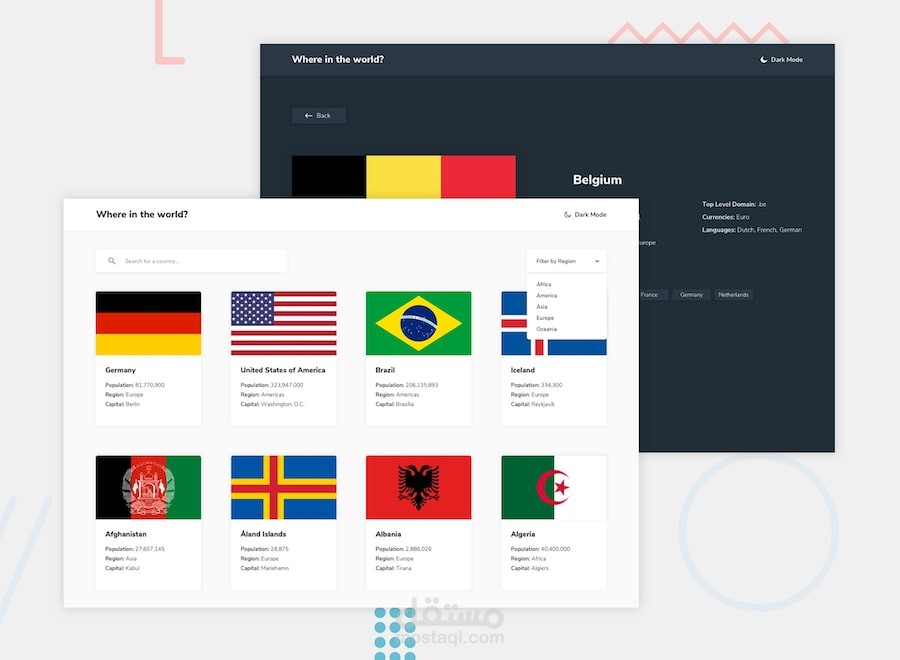
تنفيذ موقع لعرض بيانات دول العالم متجاوب مع جميع الشاشات باستخدام Tailwind-CSS و Vanilla JS من موقع (Frontend Mentor) https://t.co/xMgGspjdQg 272 via @MostaqlCom@fr
I've just completed a front-end coding challenge from @frontendmentor! 🎉
You can see my solution here: https://t.co/OttDZBgg9l
Any suggestions on how I can improve are welcome!
#FrontendMentor#CodeChallenge