Introducing FLUX 3 Max, the latest post-trained video model from fal Research in partnership with @bfl_ai.
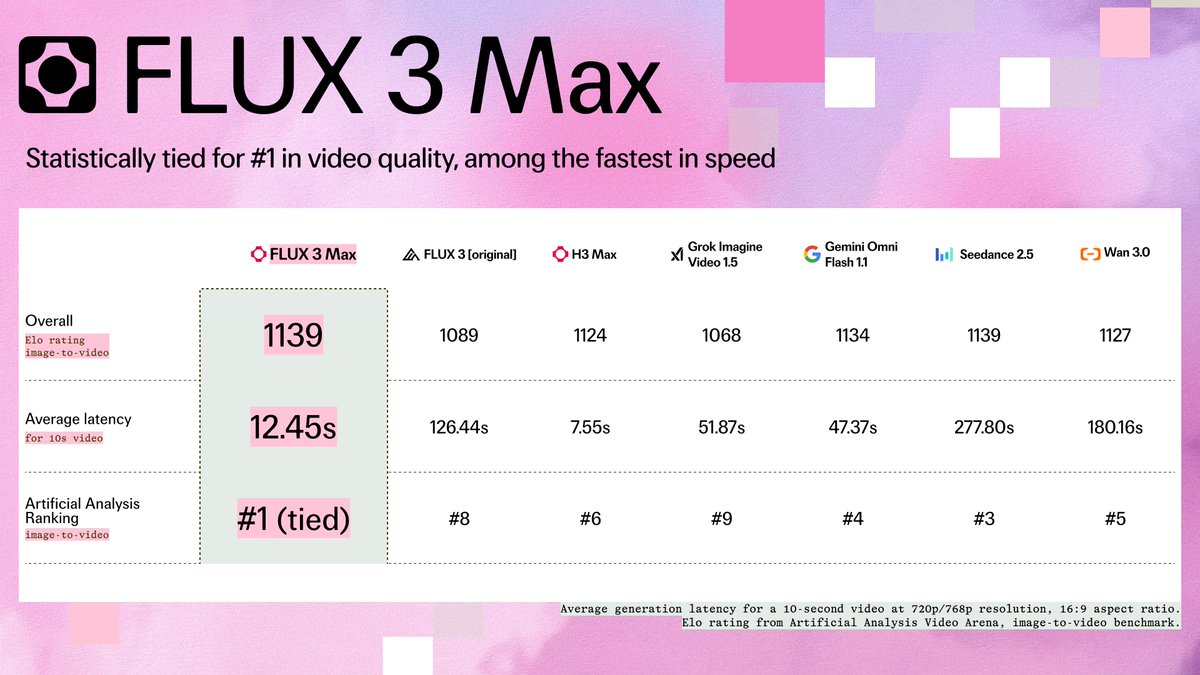
FLUX 3 Max is tied for #1 in image-to-video quality on independent third-party benchmarks, generating a 10-second, 720/768p video in ~12 seconds.
For the next three weeks, FLUX 3 Max is 75% off, making it the most affordable frontier video model at its quality level.
@Kling_ai Try Kling 4.0 on API here today!
Text to Video
https://t.co/Fb7d7iBYRe
Image to Video
https://t.co/Ff3ULJbXZp
Reference to Video
https://t.co/aXPPK792w0
Video Editing
https://t.co/odj8IbiALN
Kling 4.0 is now publicly available on fal, with API access open to all customers.
The latest model from @Kling_ai brings:
• Up to 30 seconds of native video generation with audio
• Up to 15 image, video, and element references
• Precise control with up to 10 keyframes
• Improved motion, character consistency, and cinematic storytelling
Start building with Kling 4.0 on fal today.
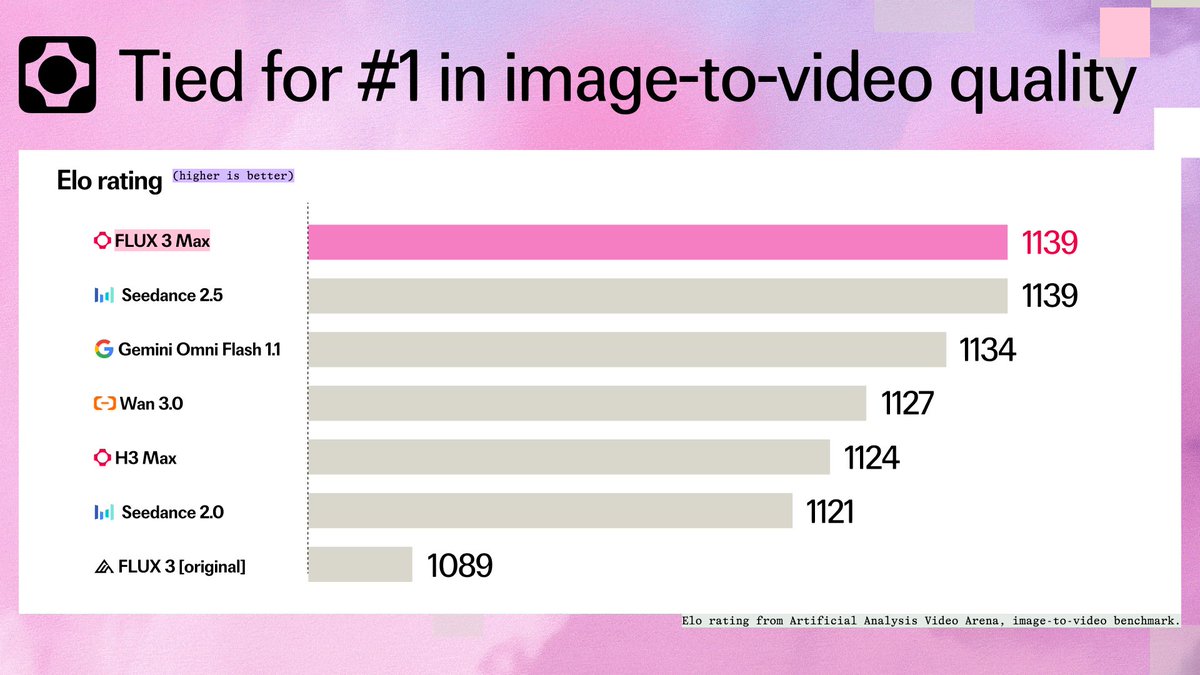
FLUX 3 Max, our latest post-trained model, generates a 10-second video in just 12.45 seconds, compared to 277.8 seconds for Seedance 2.5, while achieving the same Elo score of 1,139 on third-party benchmark evaluations.
Read how we pushed the frontier of speed and quality through post-training and inference optimization: https://t.co/JBoRMfIkeP
Introducing FLUX 3 Max, the latest post-trained video model from fal Research in partnership with @bfl_ai.
FLUX 3 Max is tied for #1 in image-to-video quality on independent third-party benchmarks, generating a 10-second, 720/768p video in ~12 seconds.
For the next three weeks, FLUX 3 Max is 75% off, making it the most affordable frontier video model at its quality level.
Ideogram Vector is now live on fal.
Generates editable SVGs from text.
Converts existing images into vector graphics.
Supports reference images for guided generation.
@HeyGen Try it here today!
Text to Video
https://t.co/wRU9RH5Uik
Image to Video
https://t.co/ZuUE8XpNpF
Reference to Video
https://t.co/2kAnySDy5Y
Voice
https://t.co/1jMcf9geRT
Voice Turbo
https://t.co/94tzBe8VIP
HeyGen Video and HeyGen Voice from @HeyGen are now live on fal.
Video and speech models with sound built in.
- Text, image and reference to video with dialogue, ambience and effects in every clip
- 5 to 15 second clips at up to 2K
- Speech in 39 languages with instant voice cloning and a faster Turbo tier
Try Kling 4.0 on fal UI and fal Agent today!
Text to Video
https://t.co/3ztzxVurox
Image to Video
https://t.co/sl9eJ719Dd
Reference to Video
https://t.co/hfQASE5HFF
Video Editing
https://t.co/U10fxlHcg9
fal Sandbox
https://t.co/WUuRP7G14t
fal Agent
https://t.co/ivppewpLZf
Kling 4.0 is now live on fal.
A next-generation native multimodal video model with improved stability for complex motion, stronger reference consistency across characters and scenes, and more precise control over cinematic storytelling.
Available exclusively through the fal UX and fal Agent. API access coming soon.
We are excited to work together with @FireworksAI_HQ on the early-launch of EAGLE-4.
Check out our technical blog to understand how EAGLE-4 works and why it matters for creative workflows: https://t.co/YnYzQ89uCv
EAGLE-4 is here.
From EAGLE-1 to EAGLE-3, we’ve kept making inference faster.
EAGLE-4 is our fastest yet.
961.6 tokens/s on @Alibaba_Qwen’s Qwen3.8-27B with TokenSpeed (BF16, 4× @NVIDIA B300, TP4, one request, T=0).
Github: https://t.co/GwocZk1UTU
FLUX 3 Max scores 1,139 Elo on third-party benchmark evaluations, placing it in the #1 tier of frontier image-to-video models based on independent human preference evaluations.
fal Research is continuing to post-train the model, with further improvements to quality and performance on the way.
Introducing FLUX 3 Max, the latest post-trained video model from fal Research in partnership with @bfl_ai.
FLUX 3 Max is tied for #1 in image-to-video quality on independent third-party benchmarks, generating a 10-second, 720/768p video in ~12 seconds.
For the next three weeks, FLUX 3 Max is 75% off, making it the most affordable frontier video model at its quality level.
Bria Fibo 2.0 from @bria_ai_ is live on fal.
The #1 open-weight image editing model on Artificial Analysis, with text-to-image generation and targeted editing. Trained only on licensed data, with clear commercial rights.
- Image editing with up to four input images
- Background swaps, product restaging and lighting changes
- Text-to-image generation for reasoning-heavy prompts
Congrats @dreamlabs_ai on launching Dream-1.
A robot foundation model that controls robots it has never seen, on tasks it was never shown. Proud to power Dream API's inference on fal Serverless.
Today, Dream Labs is coming out of stealth with Dream-1, a robot foundation model that controls bimanual robots it has never seen, on tasks it was never shown, in places it has never been, from $3/hour.
Dream API is live for everyone, today. 🧵