Introducing H3 Max, new post-trained video model by fal Research.
H3 Max ranks #1 for overall quality, prompt understanding, and aesthetics against leading video models, on both first-party and third-party independent evaluations while generating a 5-second 720p video under 3 seconds.
H3 Max is 50% off for the next week, making it the highest quality, fastest and cheapest model for overall video generation tasks.
Lyria 3.5 from Google DeepMind is now live on fal
- Turns detailed prompts into music
- Blends genres and instrumental styles
- Shapes vocal delivery and musical dynamics through text
US hosted Seedance 2.5 endpoints:
- Text to video: https://t.co/yoSJrQQjjU
- Image to video: https://t.co/3xKOWtNM55
- Reference to video: https://t.co/c83XUvbxgl
We're excited to share that Seedance 2.5 is now available on US-hosted infrastructure on fal.
This follows the availability of US-hosted Seedance 2.0 on fal last week, bringing even more of the latest generative media models to US customers.
For customers who want face restrictions lifted, our team can support you through the appropriate process.
Build securely on fal.
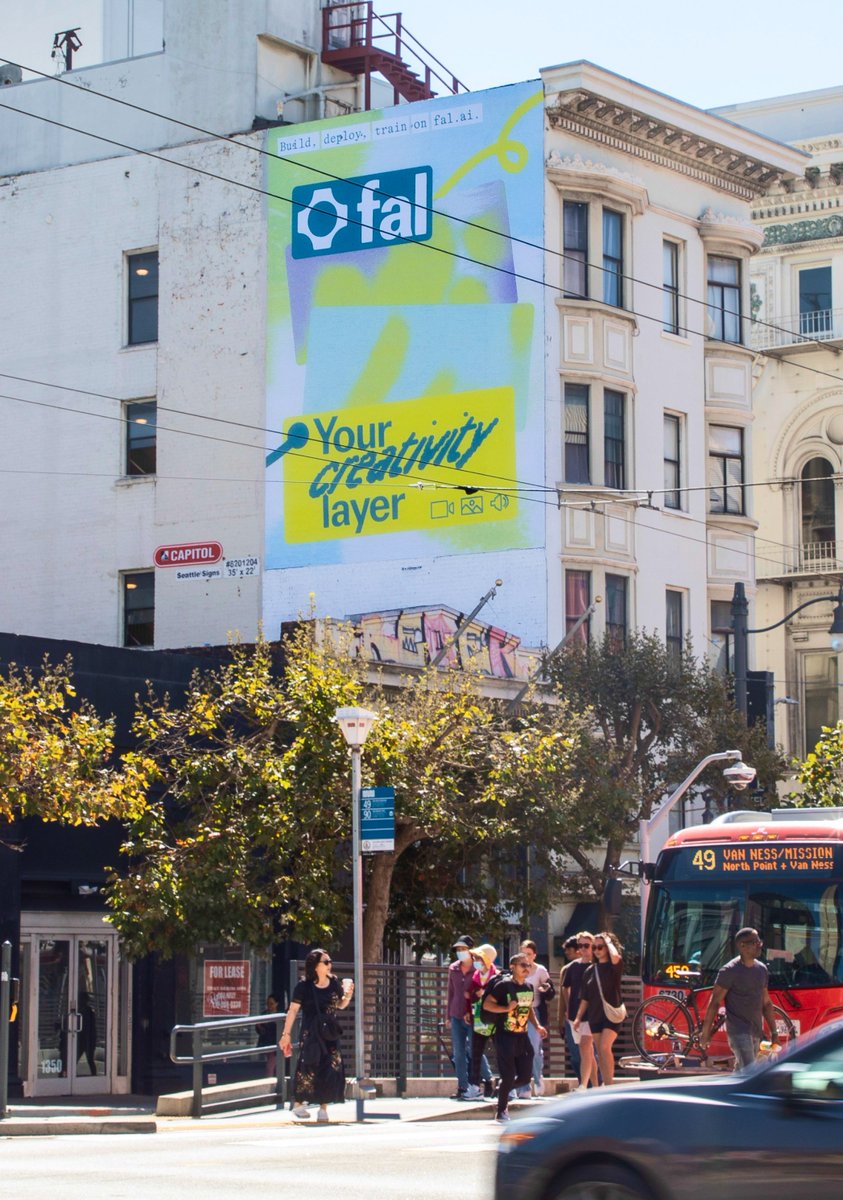
Out-of-home campaign for @fal: Your creativity layer.
Really proud of the whole team for getting this out!
Designed at *fal design lab* / with Hyun Jung Lee
We've been pushing diffusion RL into new verifiable tasks. The surprise: lip-sync is one of them.
The result is the highest-quality, fastest, and cheapest lip-sync model on the planet. Built on top of H3 Max by @fal
H3 Max Lip Sync is now live on fal.
Upload one photo and one audio clip and get back a lip-synced video in seconds, with natural expression and movement, in any language.
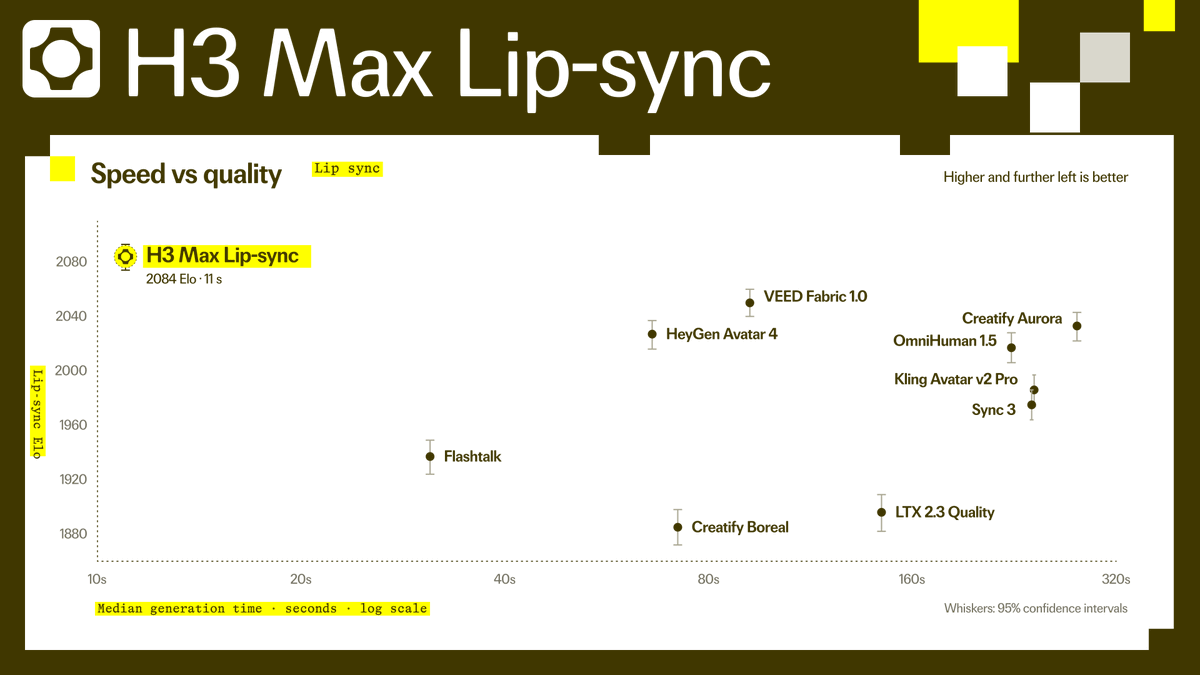
In our evals, H3 Max Lip Sync ranks #1 for both quality and speed, with a median generation time of just 11 seconds.
Try it now on fal.
The speed gap is significant.
H3 Max Lip Sync generates in a median 11 seconds, compared with ~30 seconds for the next-fastest model tested, and several minutes for others.
Here’s how H3 Max Lip Sync compares with other leading lip-sync models on speed and quality:
full runthrough of the boss fight in my game, this is all running in the BROWSER which feels crazy to say!
tech stack:
→ @fal for generated assets
→ @threejs for rendering
→ Blender + Mixamo for rigging and animations
→ @suno for music and SFX
→ GPT-6-Astra for development
Product Holding and Virtual Try-On from @bria_ai_ are now live on fal
- Creates product-in-hand imagery from existing photos.
- Changes multiple garments in a single call.
- Supports product listings, lookbooks and campaign creative.
One week until GenMedia Conference 2026.
500+ leaders across AI, media, entertainment and creativity. One day to talk about where generative media is going, and how it’s actually being used today.
See you in San Francisco on September 24.
Full list of speakers and topics is now live at https://t.co/lUC3PTVOFt.
The bottleneck in generative video is shifting.
Speed and cost are becoming solved problems. The frontier is now quality, control, and reliability.
@gorkem and @isidentical with @JenniferHli on how we’re pushing that frontier with H3 Max, and what it means for production.
.@fal's Gorkem Yurtseven and Batuhan Taskaya on making an open source video model 35x faster, and what Hollywood wanted after they built it:
Last month, MiniMax released H3, an open source video model. fal rebuilt it - they cut down the steps the model takes to make a video, rewrote the code under each stage, and got the GPUs to 70-80% of their theoretical ceiling instead of their usual 30-40%. No quality loss.
Video now generates faster than you can film it. The models have gotten so cheap and fast that end users aren't even asking for improvements in either category anymore. The gap has moved to quality, or how closely the model follows the prompt.
Hollywood wasn't a customer a year ago and is now fal's fastest growing segment. Studios love it for the little things - extending a shot, moving the camera, changing the lighting. Those edits land 80-90% of the time. fal is chasing 99.9%.
In this conversation with a16z's Jennifer Li:
00:00 Intro
01:45 The first open model worth rebuilding
03:45 The industry ran out of compute in April
06:25 35x faster without losing quality
11:05 5s of video generated in 1.5s
14:25 The weekend fal dropped everything
16:15 3 viral projects nobody planned
18:20 Teaching a video model to remember
20:25 An hour of video that's consistent
23:30 2x the usage of other models in 3 weeks
26:35 The case for giving video away for free
29:00 Blender sketch in, finished shot out
30:40 Chasing 99.9% reliability
34:15 Hollywood, fal's fastest-growing customer
36:50 Why studios wouldn't touch it until now
YouTube: https://t.co/gY1OotPW4j
@gorkem@isidentical@fal@JenniferHli
fal Marketing is HIRING!
Since I joined a year ago, we’ve 4x’d the team, grown to 2.5M+ users, and shipped more products and launches than I can count.
If you care deeply about where media and creativity are going, this is the place for you. We’re a scrappy team that’s constantly experimenting, iterating, and building.
We’re hiring for:
- Growth marketers
- Solutions marketers
- Community growth
- Creative producers
- Creative technologists
And if you don’t fit one of the roles above reach out anyway. If you’re excited about what we’re doing we’ll find a place for you.
Justine Moore @venturetwins, Partner at Andreessen Horowitz, is joining us at GMC 2026.
Justine invests in consumer and creative AI and tracks new image and video models more closely than almost anyone.
She’ll lead a conversation on what still needs to be built in generative media.
September 24 in San Francisco.
it's insane what you can now do with GPT-6-Astra + fal
i made this browser horror game inspired by the weeping angels in Dr. Who: they only move when you can't see them
Try it. Desktop + headphones 👁️
https://t.co/HiKzpk5k1v
We trained a custom H3 Max LoRA on 335 clips of footage to generate scenes for an Emmy-finalist interactive murder mystery.
fal creative engineer @PSDWizzard breaks down the full process, from story-engine JSON and character bibles to audio separation, captioning, and prompt compilation.
A very good thread on what it actually takes to train a model for a specific creative world.
I tested 5,000, 8,000, and 10,000 step runs with the dataset. The captions mattered, adding an explicit matte toon style and descriptions of individual areas within each set helped anchor the look we wanted.