Founder & CEO Fuel Online | Global SEO/AEO Authority & Visionary | AI SEO + GEO Pioneer | Best-Selling Author | Investor | Leading Digital Growth since 1998
This is a photo of #Amazon's Jeff Bezos in 1999. Screenshot this or retweet it and look at it every time you start to feel doubt or fear trying to steal your dreams...
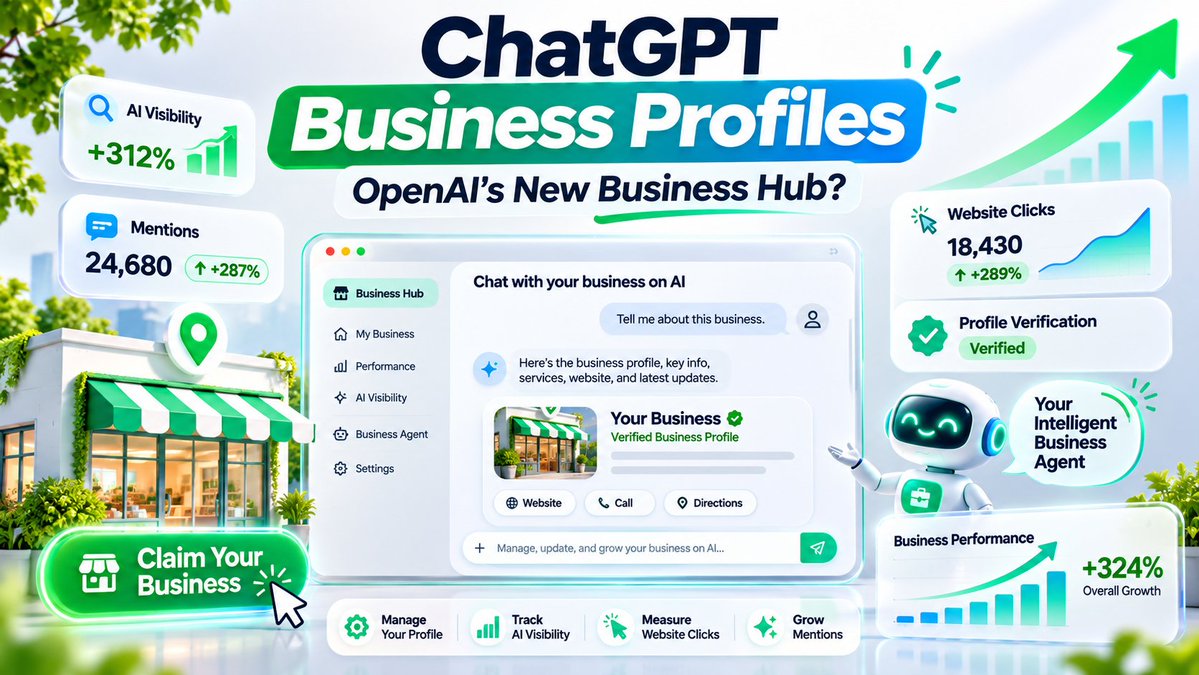
BIG NEWS: OpenAI appears to be building its own version of Google Business Profile inside ChatGPT!
And this could be a MASSIVE development for AI SEO, AEO, GEO, and how businesses compete for visibility in AI search.
An unreleased feature called "Claim your business in ChatGPT" has surfaced, revealing what could become ChatGPT's new Business Hub.
Here's what the early reports suggest businesses may be able to do:
Claim and verify their business directly inside ChatGPT.
Track how frequently ChatGPT mentions their brand.
Measure website clicks generated from ChatGPT.
Manage business information, products, and services.
Potentially deploy AI business agents to answer customer questions.
The BIGGEST development? First-party AI visibility analytics directly from OpenAI.
Imagine knowing how often ChatGPT mentions your company, rather than relying entirely on third-party prompt tracking estimates.
But there are limitations. The reported dashboard doesn't reveal individual prompts, competitor rankings, or exactly WHY a company is being recommended.
And there's currently no evidence that claiming your business will improve AI recommendations.
No official launch date has been announced.
My prediction: This could become an essential platform for businesses, just as Google Business Profile and Search Console became essential for traditional SEO.
We're entering an era where it's no longer just about ranking on Google.
It's about whether AI knows your brand, trusts your expertise, and recommends your business when customers are ready to buy.
The AI visibility race is heating up FAST.
#ChatGPT #AISEO #GEO #OpenAI
The GEO question almost nobody wants to ask:
“Why should someone NOT buy from us?”
A Sep report from Semrush/Exploding Topics found 57.5% of surveyed AI users had abandoned a purchase based on chatbot information. July survey: 2,338 US adults; the stat is the AI-user subgroup, self-reported.
Run a disqualification audit:
• Poor-fit use cases
• Missing capabilities
• Extra costs
• Better-suited alternatives
Classify the answer:
Real limitation → qualify buyers.
Outdated fact → correct the source.
Unsupported claim → gather evidence.
Missing context → explain the condition.
Do not try to erase honest tradeoffs.
A good GEO strategy should reduce bad-fit sales as well as improve discovery.
What limitation would you rather a prospect understand before the first call?
For more info or help from the Most Advanced Digital Agency on the planet:
https://t.co/V1TN7fC9J9
200 OK is not a content audit.
A page can return successfully while the initial HTML contains almost none of the answer.
Ahrefs highlighted JavaScript-heavy pages in its Oct 7 AI-crawl update.
Test one commercial template:
• Initial response
• Rendered page
• Access conditions
• Verified bot logs, if available
Can you find the service scope, product facts and usable links?
Different crawlers behave differently. A spoofed user-agent string is not proof of a real bot visit.
If crucial facts depend on fragile client-side loading, review the delivery architecture. Keep content consistent for humans and crawlers.
Then check the other pages using that template.
Access is the first test. A citation is another.
For more info or help from the Most Advanced Digital Agency on the planet:
https://t.co/V1TN7fCHyH
Stop comparing AI models only by token price.
Haiku 5.5 launched Oct 7 for high-volume tasks. Here is the test I’d run before routing marketing work to it:
30 approved examples.
Easy + ambiguous + missing-information cases.
A known answer for each.
Compare:
• Acceptable outputs
• Material errors
• Correction minutes
• Total cost
• Completion time
Cost per accepted result = model spend + review labor, divided by accepted results.
Illustrative: $2 in generation plus an hour of repairs can lose to $5 plus five minutes.
Route easy work only after it passes the test. Escalate ambiguity. Sample approved outputs for missed errors.
The winning model is the one that makes the whole job work.
For more info or help from the Most Advanced Digital Agency on the planet:
https://t.co/V1TN7fC9J9
“Make it pop” gives an image model permission to guess.
Try a visual contract:
MESSAGE: one takeaway.
SUBJECT: one dominant object.
TEXT: exact short headline.
LOCKS: logo + product + facts.
FREEDOM: lighting + background.
REJECT: unreadable copy or invented evidence.
Nano Banana 2.1’s October model card still lists small-text and consistency limitations. New model, same need for QA.
Generate 3 genuinely different compositions. Compare them at phone size.
For data posts: calculate the chart first. Let AI design the surrounding concept.
A beautiful fabricated dashboard is worse than a plain accurate chart.
What is your most common AI-design failure: text, consistency or composition?
For more info or help from the Most Advanced Digital Agency on the planet:
https://t.co/V1TN7fC9J9
The article is accurate.
The metadata invents a promise.
That is a real workflow failure to test.
Google’s updated AI-content guidance includes metadata in the accuracy review.
Create one approved fact record:
US only.
Business plan.
Annual billing.
Check title, description, alt text, social preview and structured data against it.
Have the reviewer return:
CLAIM → EVIDENCE → MISMATCH → FIX
Seed a test with “worldwide,” “all plans” and a missing billing condition. Include valid claims too.
Measure missed errors and false alarms.
An AI editor that checks only the body copy is checking only part of what you publish.
Which field is most likely to go live without a human reading it?
For more info or help from the Most Advanced Digital Agency on the planet:
https://t.co/V1TN7fC9J9
Google added UGC Fresh Data Program docs on Oct 8.
This is for eligible UGC platforms through an application process—not a universal “submit my blog” hack. Search appearance is not guaranteed.
Useful readiness test for platform owners:
Sample 20 recent contributions.
Check stable public URL, signed-out access, author context, accurate structured information and working moderation.
Group defects by template.
One template fix can matter more than manually repairing 200 posts.
For brands using communities, contribute actual expertise. Participation on a platform does not make your brand a Google program partner.
The first growth question should be: “Are we eligible, and is the content usable?”
For more info or help from the Most Advanced Digital Agency on the planet:
https://t.co/V1TN7fCHyH
57% AIO exposure.
0.48% AI traffic.
Semrush’s manufacturing study reports both. The first is search-volume-weighted presence across 458 tracked keywords in July. The second comes from a separate website-session dataset.
Do not divide one by the other.
The practical opportunity is a broken evidence chain:
Part number → specs → compatibility → limits → replacement → quote.
Pick one product family. Make every transition answerable.
“Similar” is not “compatible.”
A PDF download is not proof the buyer found the requirement.
A citation is not a completed purchase.
Track relevant answer inclusion and qualified quote completion separately.
What information does your sales engineer request on almost every inquiry? Put that requirement where buyers can use it.
For more info or help from the Most Advanced Digital Agency on the planet:
https://t.co/V1TN7fCHyH
The next PR filter: relevance to the buyer’s problem.
Ben Wills’ Oct 13 OppAlerts research reports a 0.57 average within-industry correlation between relevant backlink counts and GPT-6 Astra recommendation scores across 100 industries.
Correlation. Not a universal #1-factor verdict.
Turn it into a test:
Score 20 prospects from 0–2 on:
• Buyer overlap
• Problem overlap
• Evidence you can contribute
Read the page, not just the domain score.
A trade publication explaining the exact problem you solve may be a better opportunity than an unrelated high-authority mention.
Earn the placement with a useful finding or demonstration. Track qualified referral conversations and AI visibility separately.
The goal: a specific, accurate association—not a larger mention count.
For more info or help from the Most Advanced Digital Agency on the planet:
https://t.co/V1TN7fC9J9
Add a second attribution question.
Not just “How did you hear about us?”
Also: “What helped you decide to contact us today?”
Ahrefs says more than 1 in 5 signups named ChatGPT or Claude as discovery sources in its Oct 6 report. That is self-report, not a universal AI conversion rate.
Store:
• First discovery
• Decision influence
• Observed arrival channel
• Original answer
• Unknown
A buyer can discover you in AI and arrive through Google.
Do not overwrite the referral. Do not label every unexplained direct visit “AI.” Do not count the same deal twice.
Use 20 qualified inquiries as a pilot. The repeated decision questions are also excellent content briefs.
For more info or help from the Most Advanced Digital Agency on the planet:
https://t.co/V1TN7fCHyH
A fact page is not a comparison strategy.
Ahrefs’ separate 20,000-prompt US test: official sites supplied 63.4% of citations for factual questions and 46.4% for comparisons.
Build two assets:
1. A current fact sheet: scope, version, price, exclusions.
2. A decision test: use case, tradeoff, verification step, alternative.
“Integrates with your CRM” is weak.
“Creates contacts; custom-object sync requires X” is useful, if verified.
Give independent reviewers evidence they can reproduce. Do not script their verdict.
The move is to make your facts easy to verify and your tradeoffs easy to understand.
What claim in your sales deck is technically true but missing the condition?
For more info or help from the Most Advanced Digital Agency on the planet:
https://t.co/V1TN7fC9J9
Your U.S. GEO playbook may not travel.
Semrush’s new UK benchmark: news represented 29.5% of ChatGPT citations among the top 100 cited UK domains vs 19.6% in the US, averaged Jan–Jul.
Not all citations. Not proof buying news coverage causes recommendations.
The useful move: build a market-specific source map.
Take one buyer problem. Run comparable questions with local requirements. Record recurring publishers, review sites, businesses and cited pages.
Then ask: what local evidence could we contribute that these sources would actually use?
Currency swaps and British spelling are the easy part.
Local proof, distribution and buyer constraints are the strategy.
For more info or help from the Most Advanced Digital Agency on the planet:
https://t.co/V1TN7fCHyH
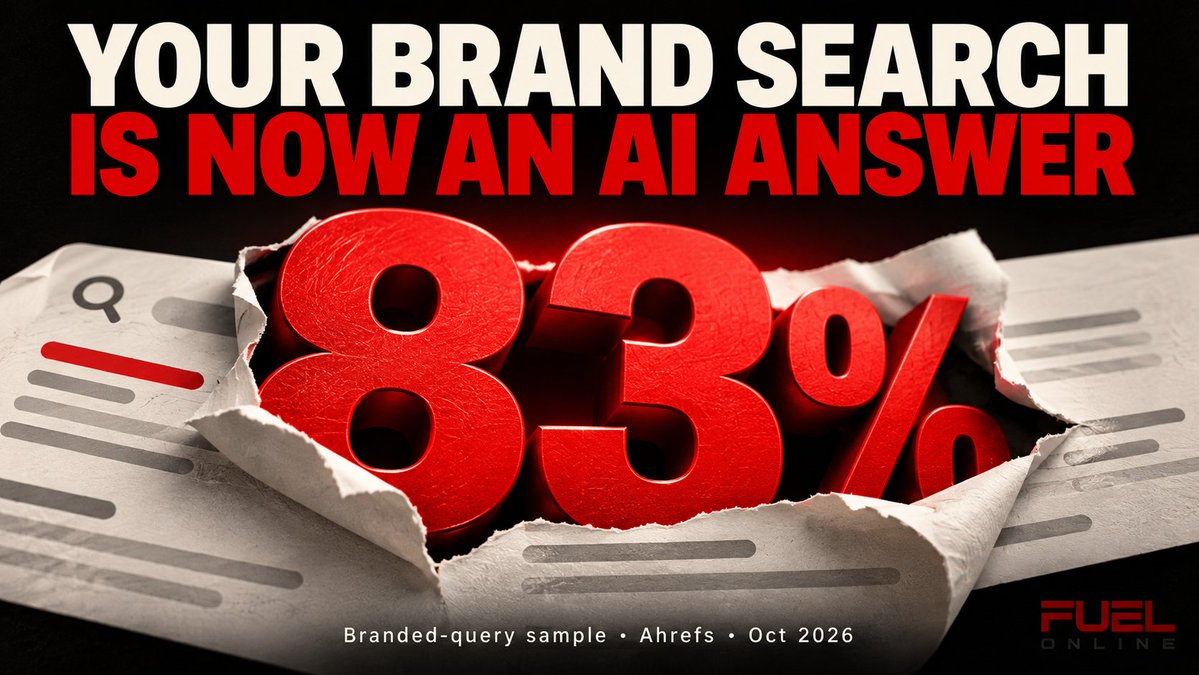
Your branded SEO dashboard can be green while the answer above your listing is wrong.
Ahrefs reported 82.91% AIO presence in its US desktop branded-keyword sample on Sep 29. September’s average: 73.3%.
Do not turn that snapshot into “83% of all brand searches.”
Use it as a trigger for a brand-answer audit:
1. Brand + pricing.
2. Brand + reviews.
3. Brand + alternatives.
4. Brand + main service.
5. Brand + buyer concern.
Extract claims. Attach cited URLs. Mark current / outdated / incomplete / unsupported.
Fix the source you control. Approach other publishers with a precise correction and evidence.
A flattering hallucination is still a bad brand answer.
What outdated claim would you want corrected first?
For more info or help from the Most Advanced Digital Agency on the planet:
https://t.co/V1TN7fC9J9
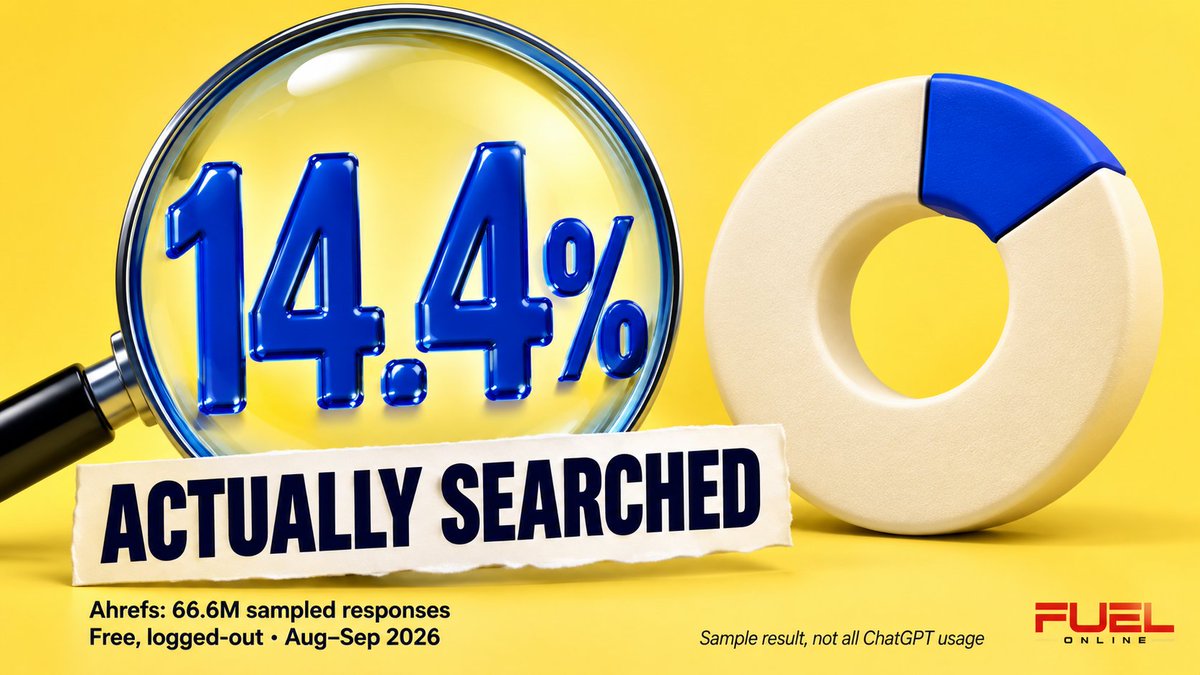
14.4% searched the web.
Ahrefs found that in 66.6M free, logged-out GPT-5.6 Luna responses from Aug–Sep. It is a sample result, not a rule for every ChatGPT session.
The tactical implication: stop treating all buyer prompts as the same SEO opportunity.
Split them:
• Lookup: current price, availability, integration, policy.
• Explanation: what something means.
• Decision: which choice fits a constraint.
For lookup questions, give the model something specific to retrieve: current facts, explicit scope, a dated source and an accessible page.
For decisions, expose the tradeoff instead of stuffing in more definitions.
Take your next 20 content ideas. How many answer a fact that actually needs checking?
That is where I’d start the next GEO sprint.
For more info or help from the Most Advanced Digital Agency on the planet:
https://t.co/V1TN7fCHyH
A ranking cliff can be a data-quality incident.
Nozzle’s Oct 10 research classified 8% of its post–Sep 13 SERPs as “poisoned,” using its own historical-result test. The full analysis covered 27.5M SERPs.
Worth investigating. Not a reason to declare every ranking report fake.
Build a 5-query incident packet:
1. Save the tracker snapshot.
2. Note country, device and collection time.
3. Compare complete-day GSC query/page trends.
4. Inspect a live result under recorded conditions.
5. Check whether the whole competitor set vanished together.
If only one feed screams, investigate that feed before rewriting pages.
Manual search also varies. Use several signals; preserve disagreements.
The expensive mistake is “fixing” a website to solve a measurement problem.
What’s the strangest false ranking alarm you’ve encountered?
For more info or help from the Most Advanced Digital Agency on the planet:
https://t.co/V1TN7fCHyH
Build a search intelligence agent that can say: “This news does not require action from us.”
That may be its most valuable output.
A daily pile of summaries isn't a decision system. Start with a narrow question: which search changes warrant a review of our pages?
Give the agent a relevance profile: business model, markets, critical page types and current implementation. Keep unnecessary secrets and customer data out.
Then separate six jobs:
DISCOVER
Industry reporting and public discussions surface possible changes.
VERIFY
Check consequential claims against primary announcements and documentation. Popularity isn't corroboration.
DATE
Record original publication and retrieval dates separately. Discovering an old page today doesn't make its contents new.
CLASSIFY
Behavior change, eligibility change, documentation clarification or editorial revision? A new supported property doesn't automatically imply a ranking benefit.
RECOMMEND
Change, evidence, affected business area, smallest useful check, owner and confidence.
DISQUALIFY
What would make the recommendation unnecessary? Wrong region, unused feature, already-compliant implementation?
Send a limited digest for human review. Keep production edits and publishing separate from research recommendations.
Test the agent on known examples: actual policy change, irrelevant launch, speculative claim, duplicate report and documentation clarification.
Measure accepted recommendations, false alarms, missed changes and review time. Audit discarded items so a quiet inbox doesn't hide missed signals.
The useful agent doesn't just know what changed. It explains why your team should—or shouldn't—do something about it.
For more info or help from the Most Advanced Digital Agency on the planet:
https://t.co/V1TN7fC9J9
An AI agent that sends 40 marketing alerts a day has built you another inbox.
Give it a harder job: nominate three decisions worth your attention.
Require each recommendation to answer:
What changed?
Where's the primary evidence?
What part of our business is affected?
What's the smallest useful check?
What would make this recommendation unnecessary?
That last field catches irrelevant regions, unused features and work you've already done.
Separate publication date from retrieval date. A newly discovered old page isn't fresh news.
A documentation clarification isn't automatically a behavior change. A popular post isn't automatically a ranking factor.
Measure accepted recommendations, false alarms, missed changes and review time.
Automate the evidence trail before automating the decision.
For more info or help from the Most Advanced Digital Agency on the planet:
https://t.co/V1TN7fCHyH
Seeing your edited page in one AI answer is not proof your edit worked.
Maybe the model changed. Maybe the question changed. Maybe you got a favorable draw.
Here's a GEO pilot that learns more than a screenshot collection.
ONE INTERVENTION
Example: add a verified compatibility section with supported versions and exceptions. If you also change URLs, titles, links and distribution, you can test the package—not isolate the section.
COMPARABLE UNITS
Match pages by purpose, type and baseline visibility. Randomize within pairs where feasible. Watch for shared content or link changes spilling between groups.
FIXED MEASUREMENT
Freeze prompts, engines, locale, observation schedule and citation definition. Exact URL, any domain URL and an unlinked brand mention are different outcomes.
BEFORE AND AFTER
Observe both groups. Allow discovery time without inventing a universal waiting period. Save raw answers, dates and unfavorable results.
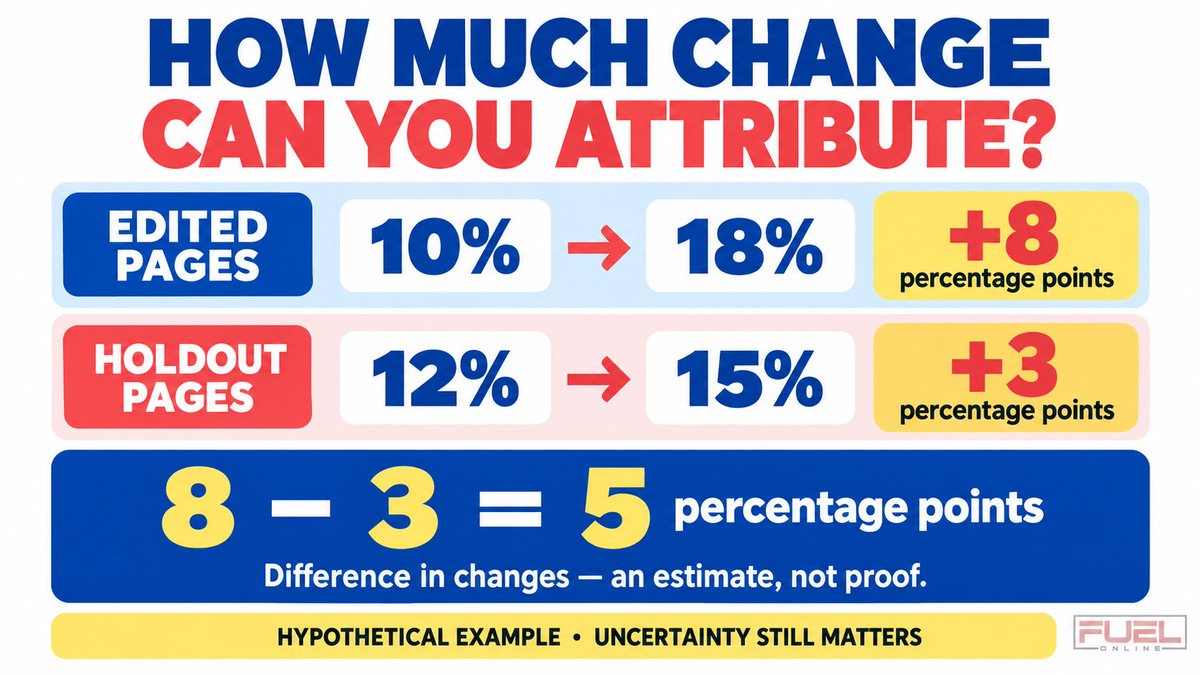
Hypothetical:
Treatment: 10% → 18%.
Comparison: 12% → 15%.
Raw gain: 8 percentage points.
Difference in changes: 5 points.
That estimate still depends on sample size, uncertainty and whether the groups would otherwise move similarly.
DECISION RULES BEFORE RESULTS
Define success, failure and inconclusive. Repeated answers to one prompt aren't independent customers. Report unique pages and topics.
Read the citations: are they relevant and supporting the right claims? A larger count on the wrong questions isn't a strategic win.
Confidence should come from surviving alternative explanations—not cropping them out of the screenshot.
For more info or help from the Most Advanced Digital Agency on the planet:
https://t.co/V1TN7fCHyH