📢 The EU AI Act is changing the game! 🚀
AI model providers must now get authorization from rightsholders for text & data mining (https://t.co/WF6c48FuO5). This is a turning point for artists, coders, and creators.
Unsolicited data access is ending. Do you agree? 👇
🚨 Quick Tip: Protect your content from unsolicited AI scraping!
@Cloudflare's new feature helps you block unwanted AI bots and scrapers, ensuring your work stays secure. It should always be YOUR choice to opt-in your data for ethical #AI training. 🛡️✨
https://t.co/0eh0v659QQ
Open-source code lacks AI-era protections, leaving it vulnerable to large-scale scraping by AI giants. Although many claims were dismissed, the battle continues! ⚖️
We fully support the plaintiffs’ unjust enrichment case. 💪
https://t.co/IpNdnQMiE8
#OpenAI#GitHub#Microsoft
Did you lose count? 🤔 We haven’t.
Another lawsuit added to the pile of copyright infringement cases against AI companies.
The unsanctioned scraping of our work must end, and @FairAIData IS doing something about it. Join us! ✊
https://t.co/u9xW4A6Uji
Feels like a good moment to stress again how important it is that legislators require AI companies to keep records of their training data.
If there is reason to believe AI companies have trained on copyrighted work without a license, rights holders will sue. Training records are critical to a fair process under the law.
There would be no downside to this legislation. It is the lowest hanging legislative fruit imaginable.
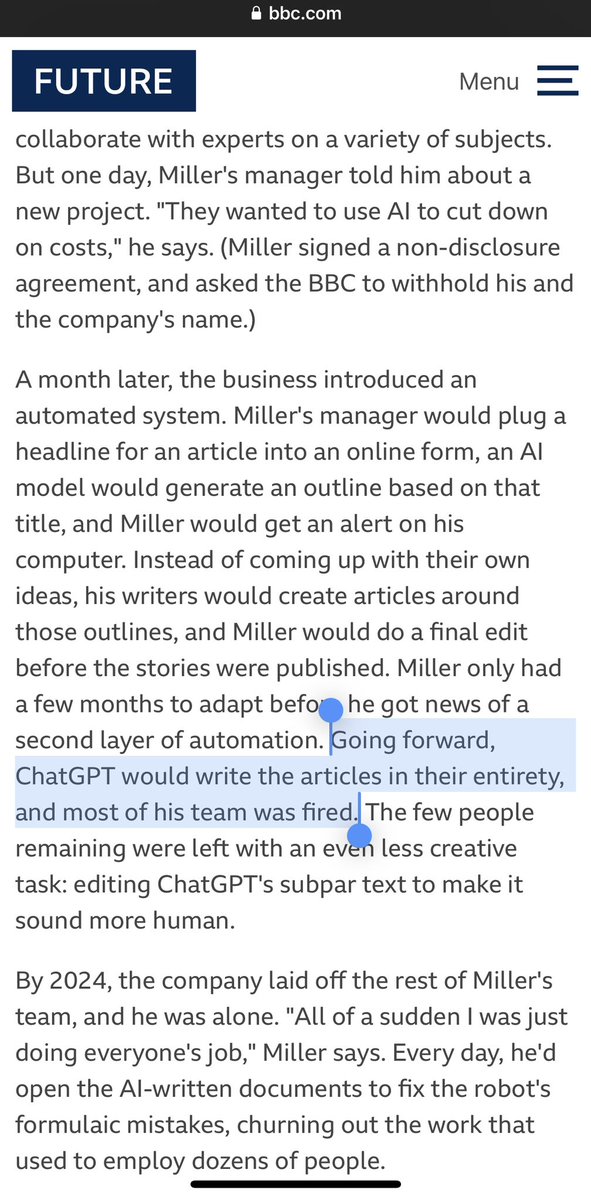
Generative AI replaces jobs. More in the growing trove of evidence for this here.
It’s crucial to remember that it does so by using the work of the people it replaces without permission. This is not business as usual in technological progress.
🚨Protect your code from being used in AI training!🛡️
@alexprokopec created a repo modifying popular licenses (Apache 2.0, MIT, etc.) to block AI training.
🔗https://t.co/pLQZ3dMHhj
Curious if these licenses are enforceable? Follow @FairAIData to stay updated!
#GenerativeAI
🌟 Get rewarded for your creative and expert work; the Fair AI Data Claim phase has launched ✅
Become a contributor and secure your stake in the first ethically sourced AI training datasets.
Dive in now: https://t.co/ByizWNg2M6
#CreatorsFirst#GenerativeAI#AI
(5/5) 📜 Immutable Data Integrity: Blockchain’s immutable records ensure that data accreditation is permanent and tamper-proof. Your data will remain securely under your ownership, providing indisputable evidence to protect against unauthorized usage.
Why are we creating a decentralized data marketplace? 🤔
Blockchain networks combine—and improve on—the most desirable properties of earlier network designs. Let’s dive into why this is crucial for Fair AI Data! 🌐💡
(4/5) 🔒 Reliability: Blockchain’s consensus mechanisms and immutability make it resistant to human intervention, ensuring that the platform operates as intended without relying on the promises of individuals or companies.
Fact: AI is only as good as the data it learns from.
We should start by building a trustless system that tracks contributions to datasets. And then pay everyone who wants to participate.
Data is the foundation of the AI stack — skimp on that, and the whole structure collapses.
Questions that should be asked of any gen AI company announcing fundraises in the multiples of millions:
- How much of your fundraise are you paying to the people who created your training data (without which your product wouldn’t work, and who your product will compete with)?
- If you’re allocating any of the fundraise to training data creators, are you paying all of them or only some? If only some, why?
Closed AI networks like OpenAI lack transparency. Remember Watkins? Her revelations changed history. 📜
Since YOUR data powers AI innovation 🌐 we ought to be part of the regulation discussions.
Let’s set the building blocks for an ethical AI future.
https://t.co/if6vn2BKuZ