you watched the numbers go up for weeks. here’s what they were.
kettei: a family of tunable, multimodal decision models for agents. show it text or a screenshot plus your agent’s options, get a probability for every option in one pass, in milliseconds.
strongest decision models we know of. two sizes open weights, as promised
One pair of shoes. 13 decisions. 0.68 seconds.
The video is slowed down just so you can follow each step.
The task: “Buy me black running shoes under $100 in size 42.”
On every screen, kettei-fat looks at a screenshot and picks the next thing to click. Search box, filter, shoe, size, Continue: each gets a probability, and the agent clicks the top one. 13 decisions later, order placed.
The end of the video shows the real speed: 0.68 seconds of kettei’s time for the whole checkout. About 50 ms a decision, and never less than 93% sure.
Try it on your own agent at https://t.co/4ZZpONc1eD
Jev 1.14 vs kettei-fat vs d1-ultra in Mario Kart (well SuperTuxKart)
Three tracks, three wins. Never trained on games. WILD.
As with agents, each call shapes the next, and the next. Pick your driver well.
Try kettei-fat at https://t.co/VYNpM5xrYF
thanks Florian, can you link to the correct company account please? @sqwishai
we are really proud that our kettei models are ahead of the board on composite score and capability for text and images... but they can also be continually trained on your data and served at the same ridiculous speed and prices. Can't wait to see what the decision model community will build with them! 😊
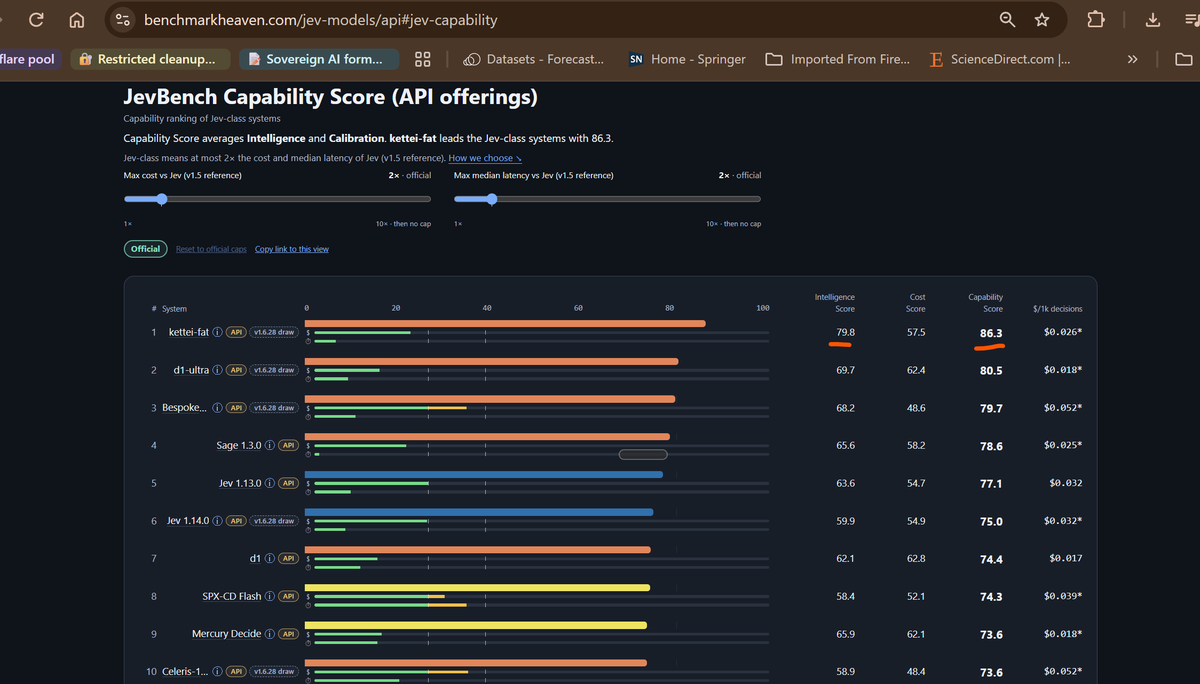
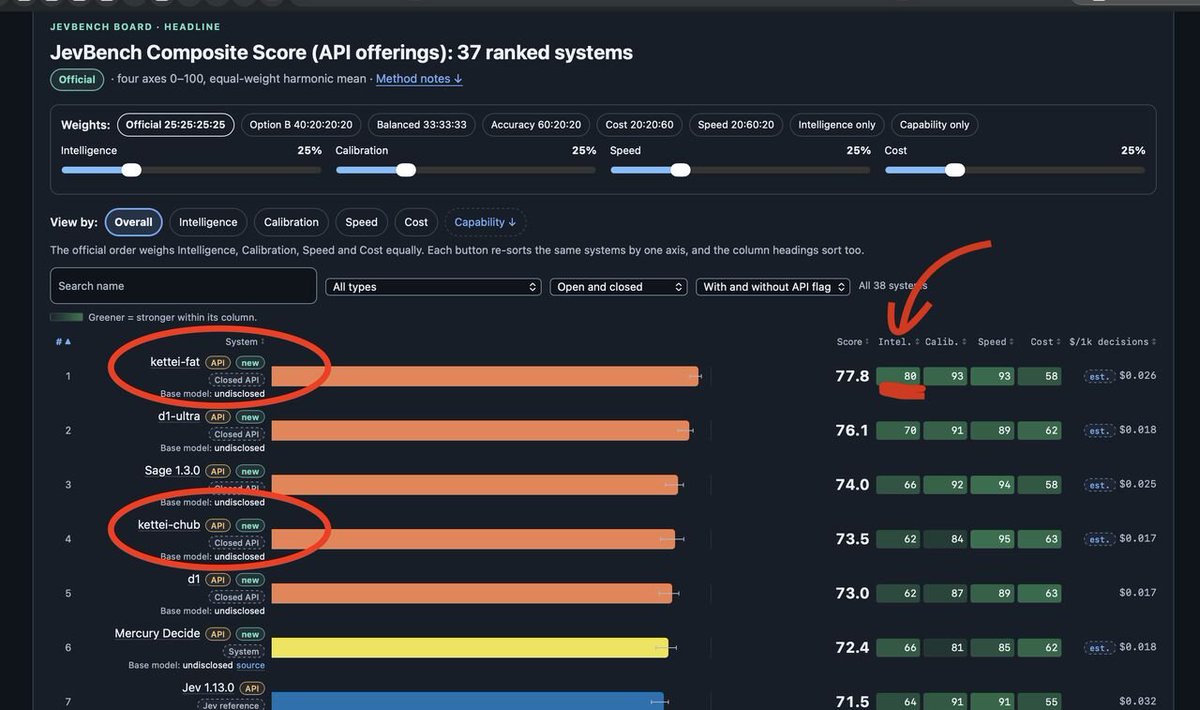
kettei-fat is #1 on JevBench (chub is #4!) and #1 on ImageJevBench, with the highest intelligence score of any decision model on the board.
Benchmarks get a bad rap. You’ll hear people say they can’t be trusted, that they’re gamed, that they don’t mean anything.
We see it differently. At @sqwishai we believe in closed-loop AI: measure the right thing, improve it relentlessly, then measure the next right thing. The right thing keeps moving. That’s the point.
For that loop to work, the measurement has to be trustworthy. Florian @airesearch12 at JevBench does it properly. He keeps updating the leaderboard, keeps his test questions private, checks for contamination, and runs every model through the same transparent evaluation process. That’s what makes a result worth something, and why we’re proud of this one.
But the benchmark we care about most isn’t public. It’s yours: the thousands of small decisions inside your product, each with its own definition of right. That’s why we’re obsessed with continual fine-tuning, so your model keeps getting better on your outcomes, served fast enough and cheap enough to use everywhere.
Millions of micro-benchmarks. We want ketteis to win every one of them.
Try and fine-tune your own kettei on OneHot: https://t.co/AmqFmjUXqj
@airesearch12 @decisionmodels_ @benchmarkheaven Thanks Florian! We’ve sent through the requested Kettei submission updates and replied by email. Could you check they’ve landed when you get a moment? Looking forward to seeing how they do 🙂
@airesearch12 @decisionmodels_ don’t forget your old friends in all the excitement 😉 just sent our kettei models your way for JevBench, looking forward to their big day😄
the part i care most about: fine-tune it on your own data on OneHot in ~15 min, serve it at the same speed, and then keeps continually training (without catastrophic instabilities and forgetting!) as new data comes in. a new version only ships if it beats the last one. banking77 went 83.1% → 93.4%
you watched the numbers go up for weeks. here’s what they were.
kettei: a family of tunable, multimodal decision models for agents. show it text or a screenshot plus your agent’s options, get a probability for every option in one pass, in milliseconds.
strongest decision models we know of. two sizes open weights, as promised
Does the @Cloudflare Jev win?
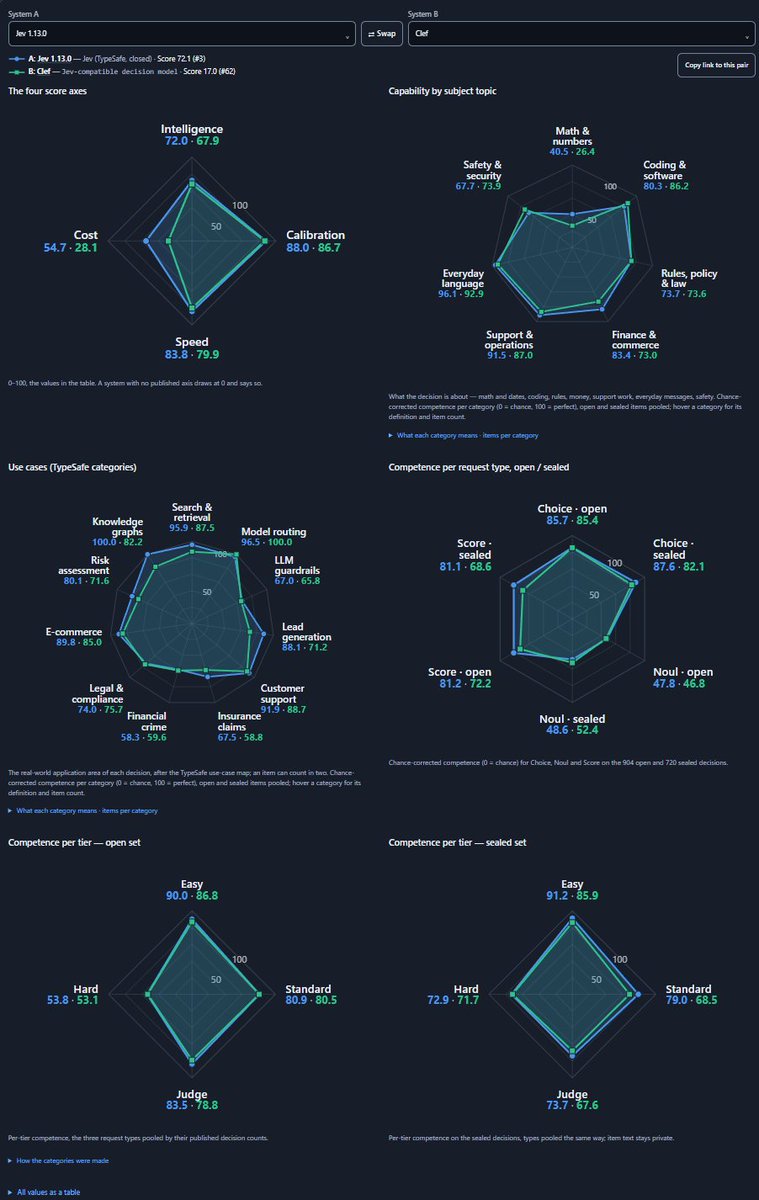
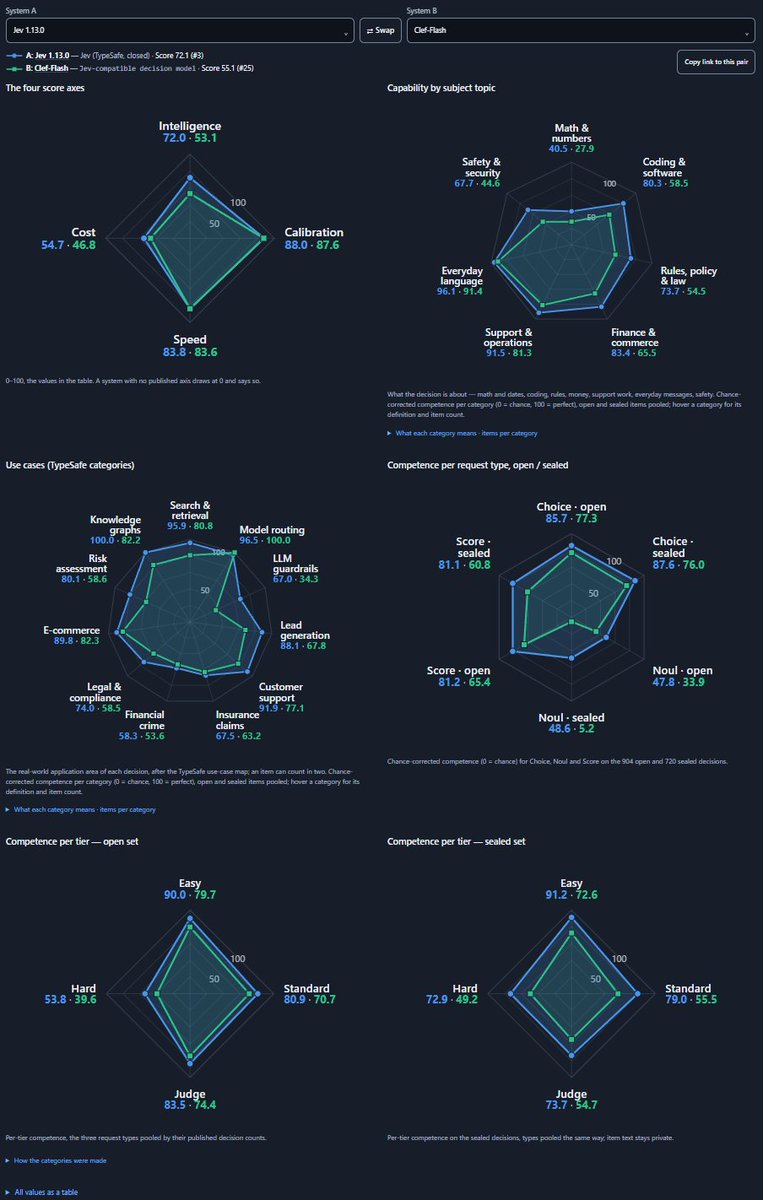
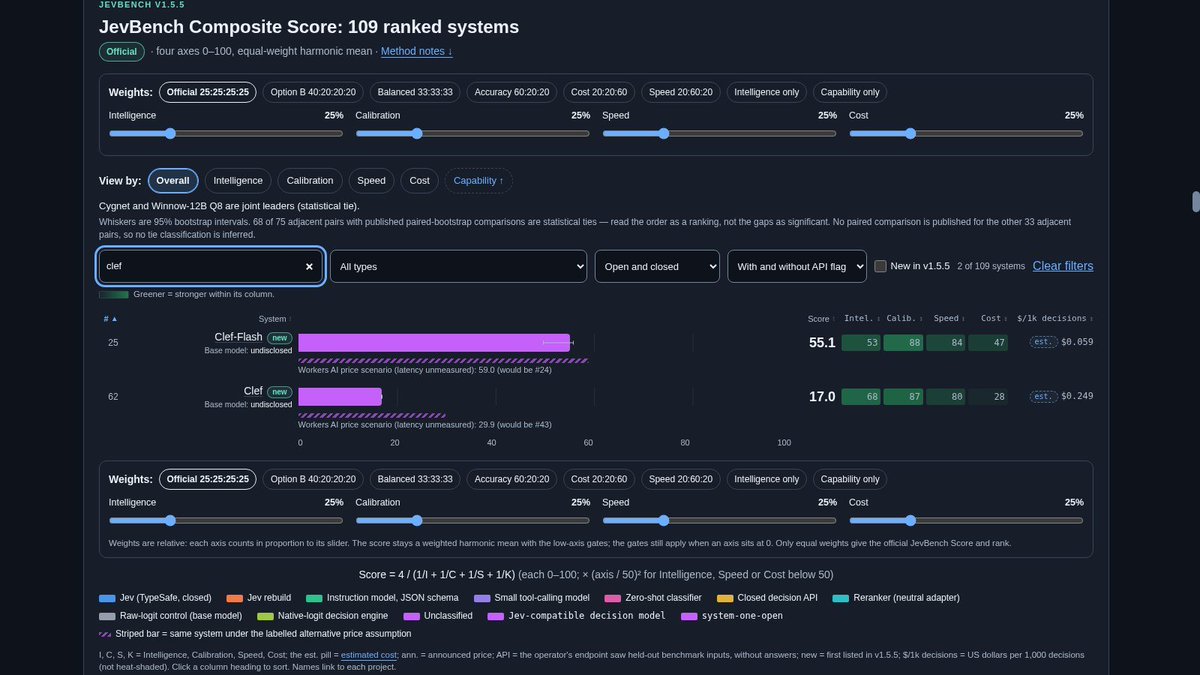
Due to public interest, results of my clef and clef-flash eval.
Short answer: No.
Longer answer:
- Both are strong models, in model routing use case they even beat original Jev.
- clef-flash is generally weaker than clef or Jev.
- clef winning vs Jev in coding and safety/security but pretty much same or weaker than Jev on everything else.
- Biggest issue: clef is too pricy (!)
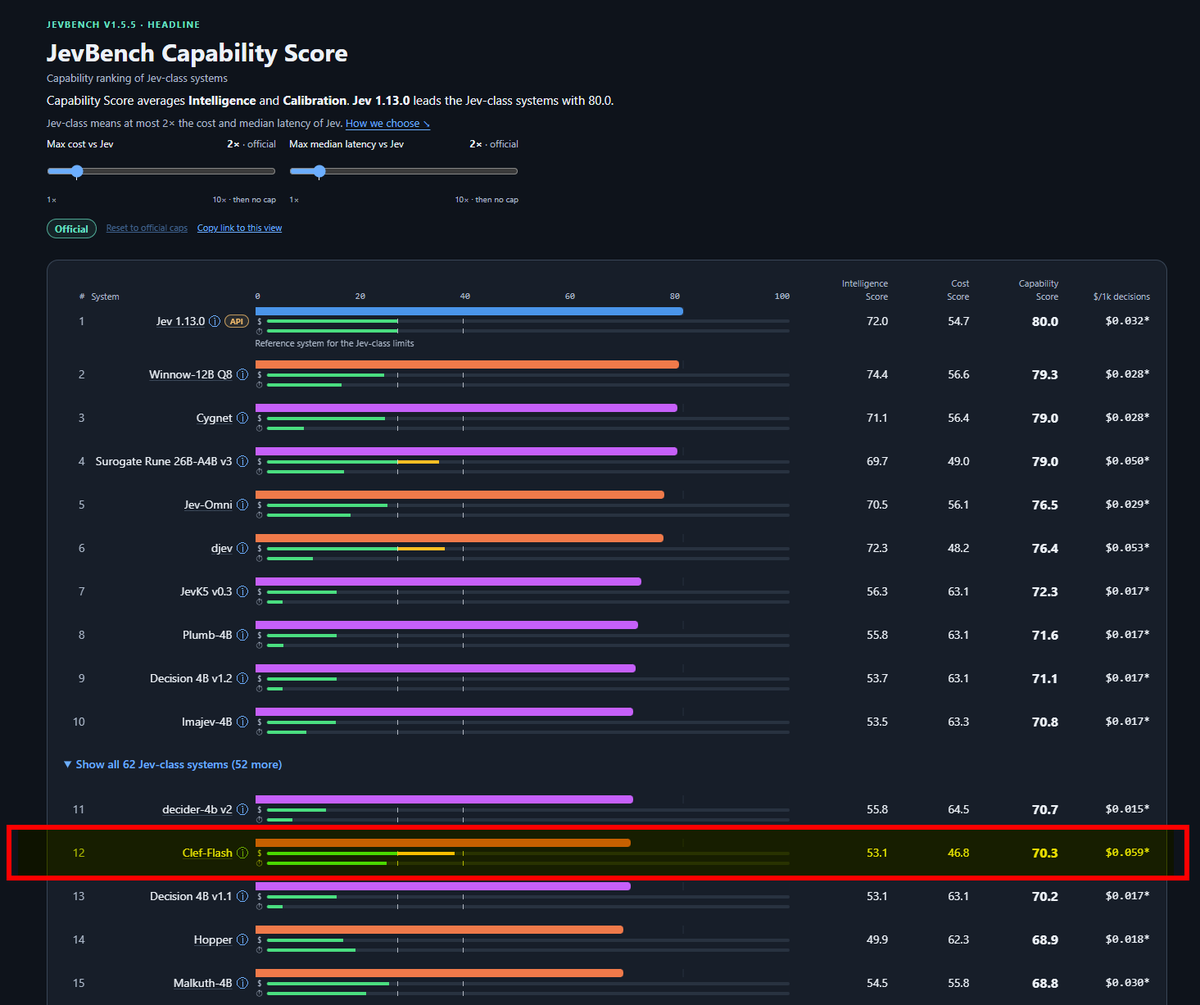
In Capability Score clef-flash scores #12 and clef is disqualified because so expensive that my benchmark does't even regard it as a Jev-class model.
In Composite Score they score #25 and #62 each (mostly because of the cost dimension)
You can experiment with the leaderboard and adjust the parameters here:
https://t.co/8WVGzH7KRg
Made with Claude Opus 5.5.
The fearmongering about AI always makes us forget that NOTHING WENT FOOM, as was always predicted.
Send this to your doomer friend who has a very high P(Doom).
Accelerate.
I stayed up til 2am and spent $1,000 benchmarking Jev Router so you don't have to.
Performance on DeepSWE was roughly the same as GPT-6 Astra on low. It costs slightly more, and it took almost 5x longer to run.
we’re training a foundation model for decisions. live.
sqwish-d1 is already at 85% on our held-out set, vs jev’s 77%. if it holds up, we’ll open-source it.
watch it learn: https://t.co/DxUGtYTEeE
we don’t have a launch video. we have a live dashboard with every seed, every domain, and a dollar counter so you can watch us burn runway in real time.
finishes friday. if it holds up, we open-source it 😌
we’re training a foundation model for decisions. live.
sqwish-d1 is already at 85% on our held-out set, vs jev’s 77%. if it holds up, we’ll open-source it.
watch it learn: https://t.co/DxUGtYTEeE
our bet: calibrated judgement needs a huge amount of data, but only a few bits of supervision each. the entire answer key of our 800k training dataset fits on a floppy disk.
a pretrained model + a LoRA can absorb that signal. big data, modest compute