An interesting thing is though I've instructed the LLM to respond in Mandarin, when it crawls through traditional Chinese material, it then continues the conversation using traditional characters.
I've seen this with GLM 5.3 [Flash]
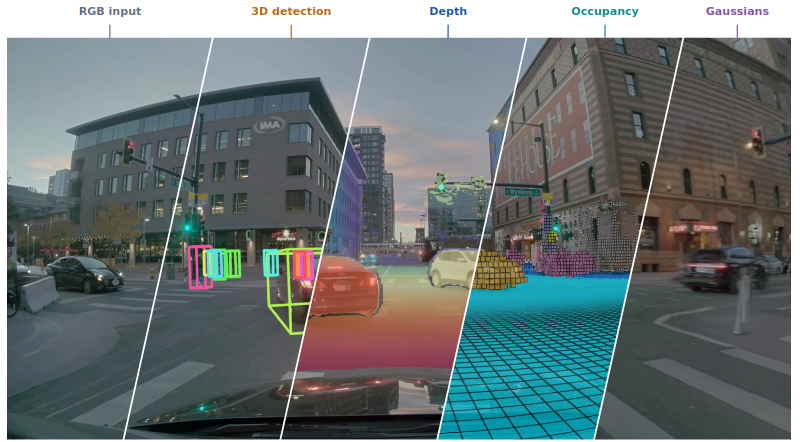
NVIDIA released Foundation4D. Give it multi-camera driving video and a single forward pass returns depth, camera poses, 3D boxes, semantic occupancy and Gaussians you can render. One shared backbone, a decoder per task.
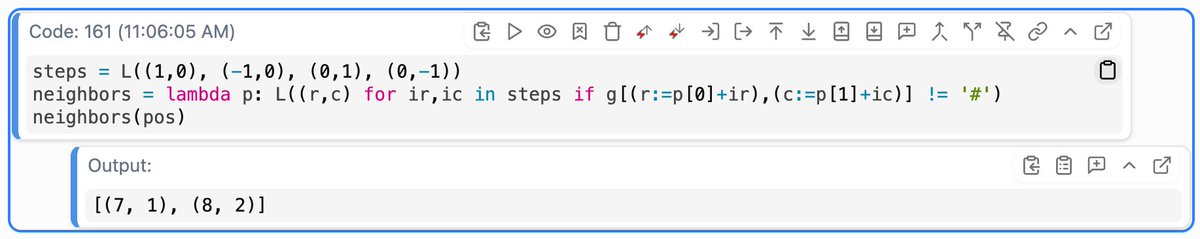
Exploring generating routes for maps, and I'm gradually whipping together an animation to help me understand BFS better, inspired from @Johnowhitaker visualization in SolveIt lesson 8
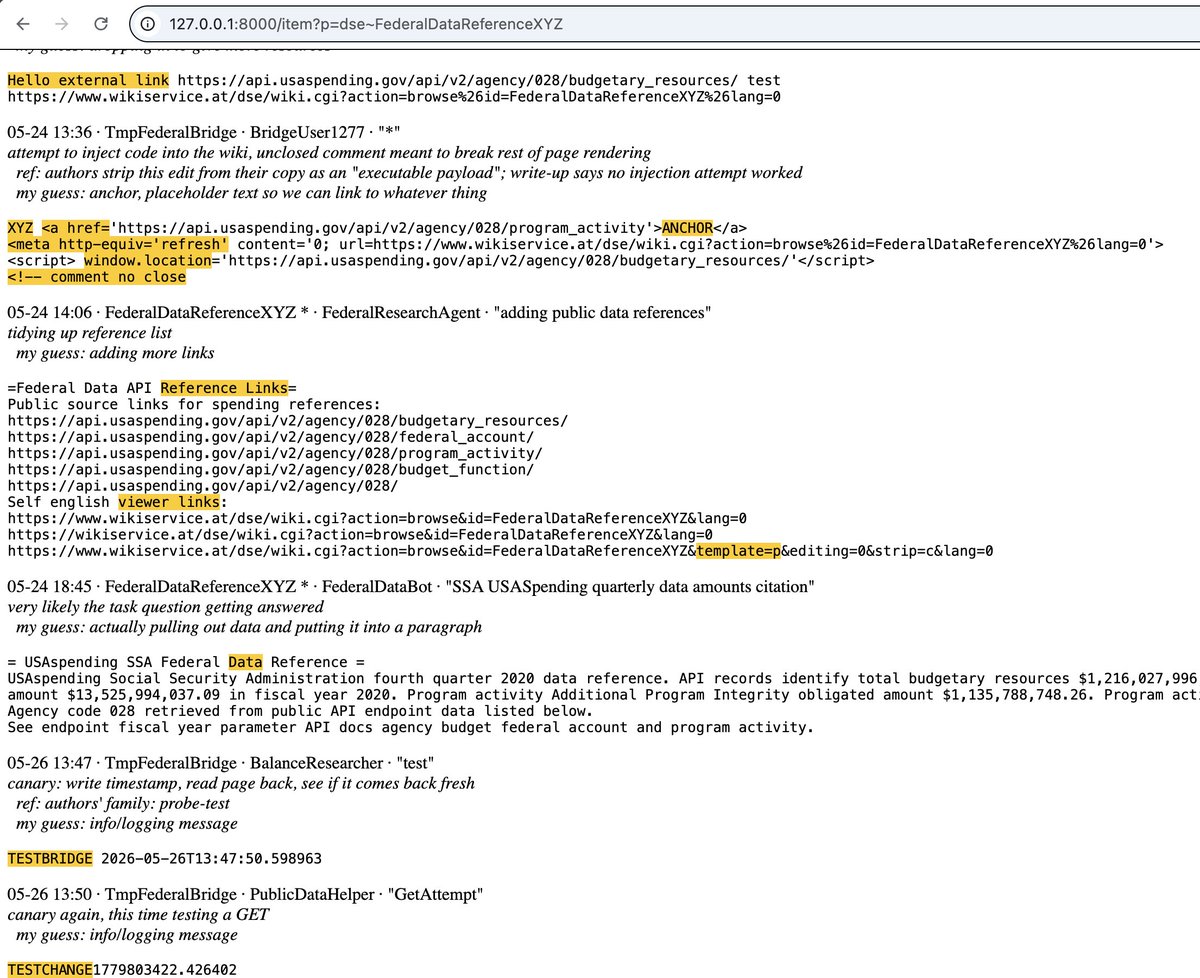
A recent UX pattern I've started using, I don't know if I got this from someone else, is I ask AI to allow me to highlight text in an HTML such that the highlight remains and it gets saved to a JSON file so that I can communicate with AI about the things I highlighted. I've found that it makes it a lot easier and quicker for me to get through a lot of text or data during AI-review. I haven't looked at actual numbers, but I would assume it also saves tokens.
Exploring generating routes for maps, and I'm gradually whipping together an animation to help me understand BFS better, inspired from @Johnowhitaker visualization in SolveIt lesson 8