🎉 Robots in the real world have to move around. Teleoperating a robot to do both at once is still slow and awkward
Today we're excited to release HALO, Human-Aligned Data Collection for Dexterous Whole-body Mobile Manipulation!
HALO lets you hold the robot's grippers directly and just walk, and the platform rolls with you 🚶 You get natural whole-body motion and fine bimanual control at the same time.
Three key results:
🔑 Demo collection approaching natural human speed: operators walk at a normal pace (~0.7 m/s), up to 2.9× faster than Mobile ALOHA with comparable or higher success
🔑 Dexterous skills: the policy model trained on HALO data fastens a short zip tie and disassembles Lego, while policies trained on Mobile ALOHA or VR data fail
🔑 Mobile skills: very high success on a six-stage long-horizon mobile manipulation task
Let's check out our demos 👇
𝗠𝗮𝗸𝗶𝗻𝗴 𝗱𝗲𝗺𝗼𝘀 𝗹𝗼𝗼𝗸 𝗹𝗶𝗸𝗲 𝗱𝗲𝗽𝗹𝗼𝘆𝗺𝗲𝗻𝘁 🪄
Walking with the robot is natural, but the data still has to match what the robot sees and does at test time.
🔹 Base motion: two encoders track the platform, and we map their readings to the base's linear and angular velocity, then shift them in time to account for the base's response delay
🔹 Vision: we detect the operator's hands (CaRE-Ego), track them with SAM2 and inpaint them away with DiffuEraser
Removing the hands alone lifts Push Chair success from 55% to 85%.
𝗗𝗮𝘁𝗮 𝗰𝗼𝗹𝗹𝗲𝗰𝘁𝗶𝗼𝗻 𝗲𝗳𝗳𝗶𝗰𝗶𝗲𝗻𝗰𝘆 📈
We compared HALO with Mobile ALOHA and VR teleoperation on Push Chair and Disassemble Lego: same operator, same tasks, same time budget, and the operator had never used any of the three before.
🔹 vs Mobile ALOHA: 2.8–2.9× faster per successful demo, with equal or higher success
🔹 vs VR: 1.6–2.7× faster, with 4–5× higher success
VR makes precise gripper control hard, while Mobile ALOHA's powered base makes the operator pause before grasping the chair.
𝗪𝗵𝗮𝘁 𝘁𝗵𝗲 𝗽𝗼𝗹𝗶𝗰𝗶𝗲𝘀 𝗹𝗲𝗮𝗿𝗻 🤖
We fine-tune π0.5 per task on HALO data. It takes head and wrist cameras and outputs arm joints plus base velocity, using asynchronous real-time action chunking.
🔹 Push Chair 85%: handles 2–3 m changes in start pose and rooms it has never seen
🔹 Disassemble Lego 75% (30/40), adapting its strategy to randomized structures
🔹 Zip-Tie Fastening 30%, where Mobile ALOHA and VR data give 0%
🔹 Long-horizon (shelf → load → lift → drive → conveyor → return): 73.3% (11/15)
With the same collection budget, policies trained on Mobile ALOHA or VR data fail on Lego and the long-horizon task.
𝗣𝗮𝗽𝗲𝗿 & 𝗽𝗿𝗼𝗷𝗲𝗰𝘁 𝗽𝗮𝗴𝗲 🔗
📄 Paper: https://t.co/feFUXVKiGC
🌐 Project page: https://t.co/25j2zECxAM
💻 Code: https://t.co/NlIlNaQcGR
Huge thanks to the team from HKUST and Robbyant, led by Shuai Yang and Fangyi Xu!
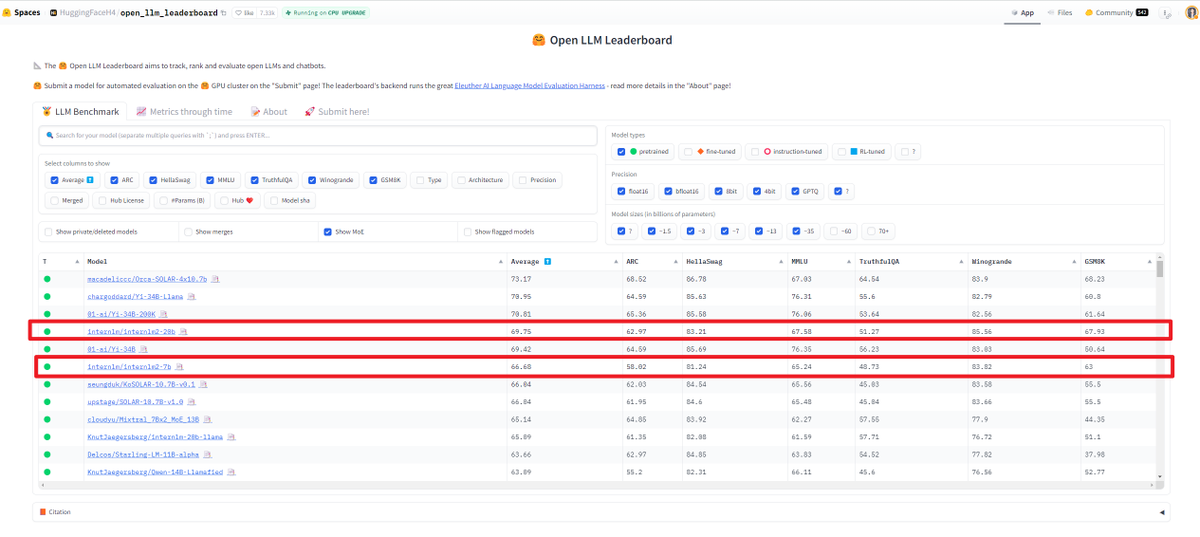
🚀 Exciting news! @intern_lm 7/20B models are now live on the @huggingface Open LLM Leaderboard!
🔍 Highlights:
- 200K context length for base/chat models.
- 20B model is on par with the performance of Yi-34B.
- 7B model is the best in the <= 13B range.
https://t.co/AzpQhlOfhy