CS Ph.D. at @FudanUniversity | Diffusion Model Pretraining | MoE/MoT Scaling | Video Generation
@TencentHunyuan Project UP Talent Program | @MSFTResearch
StableAvatar NeurIPS 554 accept!
Baton NeurIPS 5554 accept!
Finally, my first-author paper got accepted at a top-3 ML conference 🩵
See u guys in Sydney! #NeurIPS2026
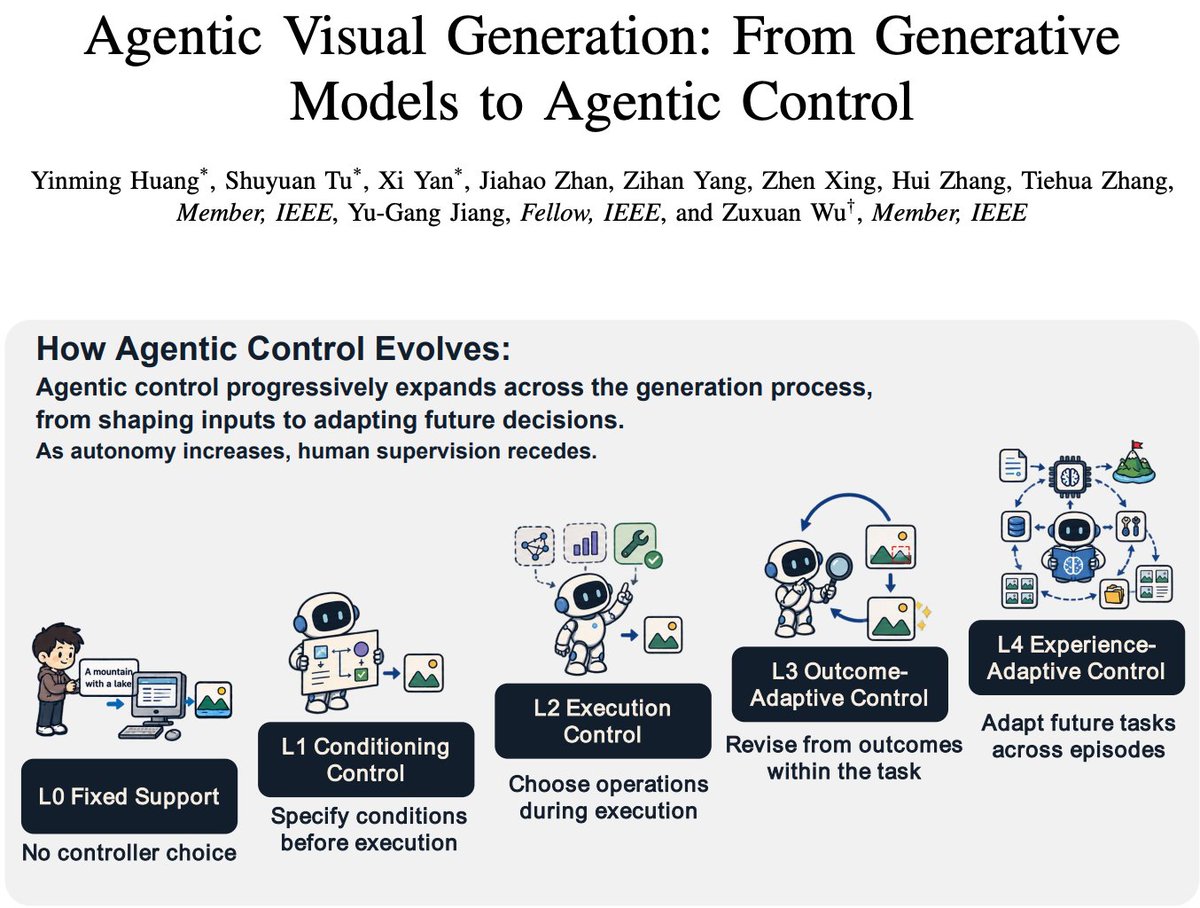
🚀 The first survey on Agentic Visual Generation is out!
We review 300+ works across Image, Video, 3D, World Models, Slides & Rendering, mapping the rapidly evolving landscape of agentic visual generation. @_akhaliq
📄 https://t.co/KrgajRKWdy ⭐ https://t.co/M0XJ5j4NMT
Excited to share our work, VA-Judger, the first reward model for joint video-audio generation! 🎥🔊
Powered by VA-Judger, post-trained LTX-2 generates high-quality content that better aligns with human preferences.
📄Paper: https://t.co/qlb1w7xHGo
💻Code: https://t.co/znBST9dPH9
🚀 Awesome Agentic Visual Generation is live!
A taxonomy-driven paper collection covering image, video, 3D & world models, organized into four levels of controller capability.
⭐ Explore, star & contribute:
https://t.co/agE81HgVEf
📄 Survey coming soon!
#AIAgents#GenerativeAI
Excited to share our work: ArcFlow, a 2-Step Text-to-Image Generation Framework via High-Precision Non-Linear Flow Distillation.
Code: https://t.co/lt3CwyWii1
It ensures high-quality alignment with teacher, delivering 40× speedup and 4× faster convergence with <5% parameters.
Excited to share our work: FlashPortrait
It is more powerful than the Runway Act series and open-source, capable of synthesizing infinite-length videos while achieving up to 6X acceleration in inference speed.
Paper: https://t.co/RkG7SGeTdm
Code: https://t.co/YXAFd6kHJG
Have you ever seen Professor Snape like this at Hogwarts? With StableAvatar, anything is possible! We’re excited to share brand-new demos synthesized by StableAvatar!
Paper: https://t.co/6s8SwzFIKg
Code:https://t.co/i7jdxgZYcT
🚀 Check out StableAvatar demo on Hugging Face!
🎭 Audio-driven avatar video generation with just 1 image + 1 audio.
👉 https://t.co/yhoURQJEAF
⚠️ Due to video generation limits, currently only Hugging Face Pro users can try it out.
Thanks @gradio for the awesome interface! 💡
Excited to share our work: StableAvatar
It is the first Wan2.1-1.3B-based video diffusion transformer, which synthesizes infinite-length high-quality avatar videos, conditioned on a reference image and audio.
Paper: https://t.co/6s8SwzFIKg
Code:https://t.co/i7jdxgZYcT
Excited to share our #CVPR2025 paper: StableAnimator
It is the first end-to-end ID-preserving video diffusion framework, which synthesizes videos without any post-processing, conditioned on an image and poses!
Paper: https://t.co/mwQPTnpaok
Code: https://t.co/rbIqdQPHLk