"The data #scientists spend 80% of their time cleaning #dataset and 20% complaining about cleaning data."
Ok the data quality feeds the #model, but believe me, the data throughput to the #GPU determines its speed. And without #synchronization, even the best algorithm runs idle!⚡
@alex_verem The weights, refinetuning and production are permitted under Apache 2.0. Datasets and training scripts are not open source, due to trade secrets and R&D time constraints. Explained by the culture of secrecy that prevails in certain sectors: CyberSecurity, Banking and Defense.
Meet Gemini 4 Hydrogen.
It brings cutting-edge intelligence to everyone, with speed and efficiency for everyday coding and agentic work.
Across 4 thinking levels, it stands on its own or teams up with Carbon and Argon — 2.5X faster than 3.8 Flash, outpacing competing models in its class.
Gemini 4 Carbon is live in Google Antigravity.
Built to explore thoroughly, reason deeply, and run extended verification loops, our strongest model for long-horizon agentic workflows is rolling out today in the desktop app, CLI, and IDE Extensions for Google AI Ultra subscribers and in Gemini for business. We are working on expanding access to more paid users soon.
Watch how we are using Carbon and Antigravity:
@Greg_GL_87@TeksEdge Forecasting timesheets in 140 ms with a 209M foundation model might confirm with P99 quantile certainty that everyone logs their Friday hours at 4:55 PM. 😅 Next step: balancing CPU/GPU inference and reasoning tokens just to figure out why Monday mornings are an anomaly ? 👋
Google AI Pro plans now package premium Colab benefits, landing you A100s with 80GB VRAM (Ultra subs even unlock H100s 🔥).
Here’s what that 80GB headroom unlocks directly in your browser:
✨ Run Gemma 4 31B in bf16
✨ Full fine-tune up to Gemma 4 E4B in bf16
✨ LoRA tune up to Gemma 4 26B A4B in bf16
✨ QLoRA tune up to Gemma 4 31B in bf16
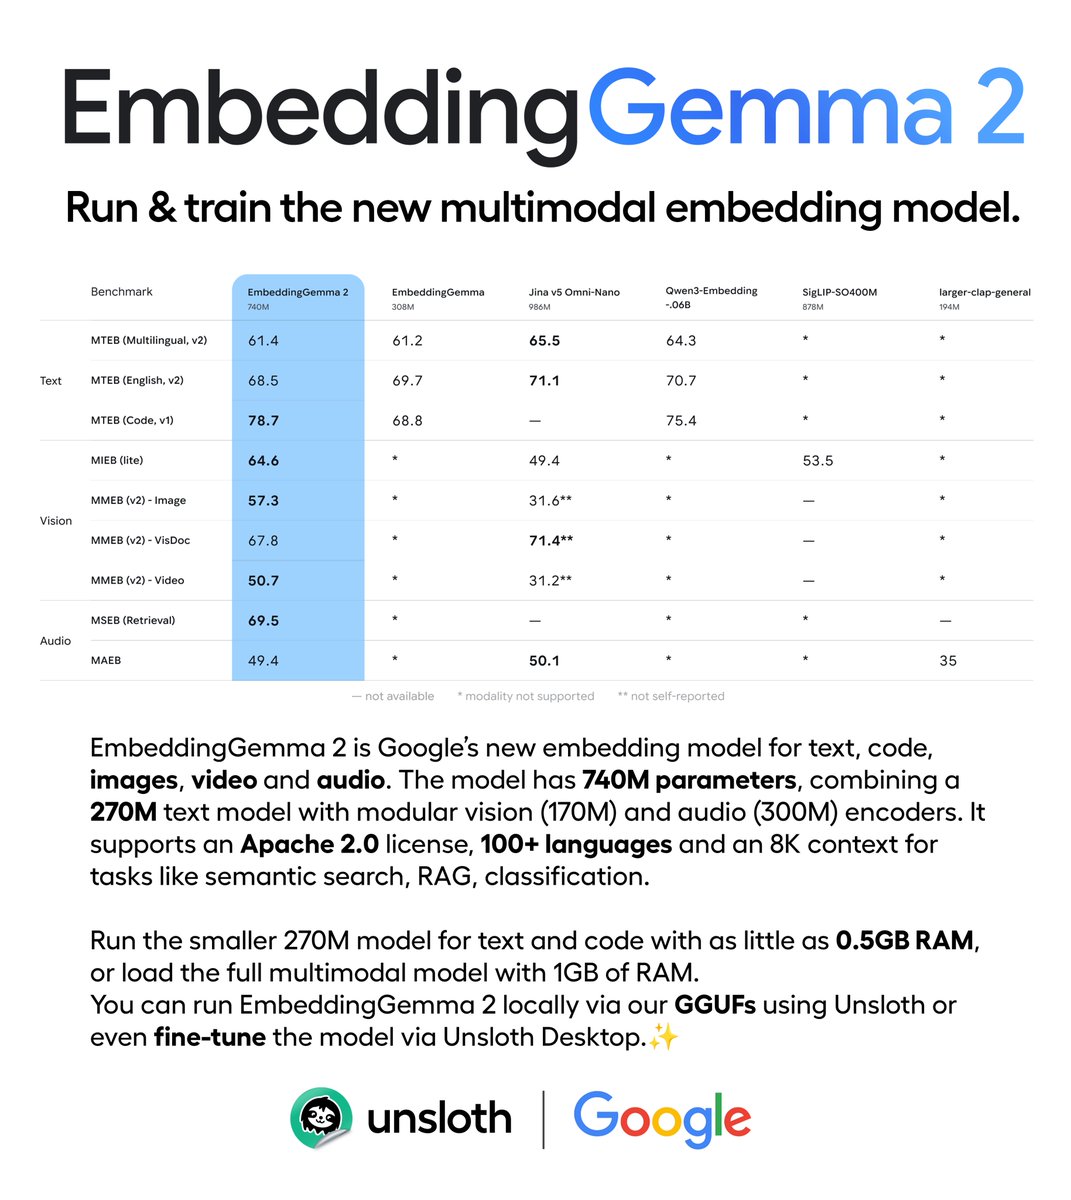
Google releases EmbeddingGemma 2, a new open model that runs locally on 0.5GB RAM.
The 740M parameter Apache 2.0 model combines a 270M text model with vision (170M) + audio (300M).
Run & train the model via Unsloth.
GGUF: https://t.co/yVUJs3MNG9
Guide: https://t.co/jw67IZPTek
Meet Mistral Large 4, aka Le Chonk.
• 1T parameters, natively multimodal. 49B active.
It is the best open weights model from US or Europe on aggregated benchmarks.
• State-of-the-art on critical workloads, including cyber defense, manufacturing and finance and it surpasses closed frontier models on visual grounding.
• Forged in Europe end-to-end and is deployable from Europe via our own Mistral Cloud infrastructure.
• Available to all via API today. Working with cybersecurity partners privately.
Open weights release end of October.
If you don’t want to wire up your own Jev client in Spring Boot, I created a simple starter for you.
Add the dependency, set your API key, and inject JevClient. Built for Spring Boot 4 with RestClient and typed questions and answers.
https://t.co/2YfgxEwp6C
A perfect system, devoid of all #Entropy, becomes fragile. Without injected noise it is too pure, thus dogmatic and vulnerable to novelty. Introducing controlled noise forces a system to develop far more powerful error-correction mechanisms🌌💻 #MachineLearning#ChaosEngineering
Classifier IronJean 1.0! Un filtre WAF IA ultra-performant basé sur ModernBERT.
Bloque les attaques complexes (XSS, SQLi) grâce à une analyse sémantique du flux HTTP.
Exports ONNX (INT8/FP16) inclus pour les backends Java.
#CyberSecurite#IA#WAF#ONNX
https://t.co/dYyMN3Vjz1
Classifier IronJean 1.0! A highly accurate WAF powered by ModernBERT.
Defeats obfuscated XSS/SQLi via deep semantic HTTP analysis.
Production-ready: ONNX exports (INT8/FP16) included for Java/C++ backends!
#CyberSecurity#WAF#ModernBERT#Java#ONNX#AI
https://t.co/dYyMN3ULJt
Introducing Gemini 3.8 Flash in Antigravity!
3.8 Flash is our most intelligent workhorse model, built for long-horizon coding and autonomous agents. Try it out today.
Gemini 3.8 Flash is here⚡️
it's our most intelligent workhorse model, delivering significant improvements from 3.7 Flash across software engineering, agentic tasks, and critical, multi-step reasoning in specialized domains
available at the same introductory price as 3.7 Flash at $0.75 per million input tokens and $3.75 per million output tokens
try it today via the Gemini API and in AI Studio: https://t.co/h3Kmz2ypDi