A new generation of embedding models, built from scratch in India, is coming.
Not fine-tuned. Not adapted. Built from the ground up on custom architectures.
Introducing NandiBert and EmbeddingNandi, each in two sizes.
Proudly built at FrontiersMind !!
Coming soon. Stay tuned 🔥
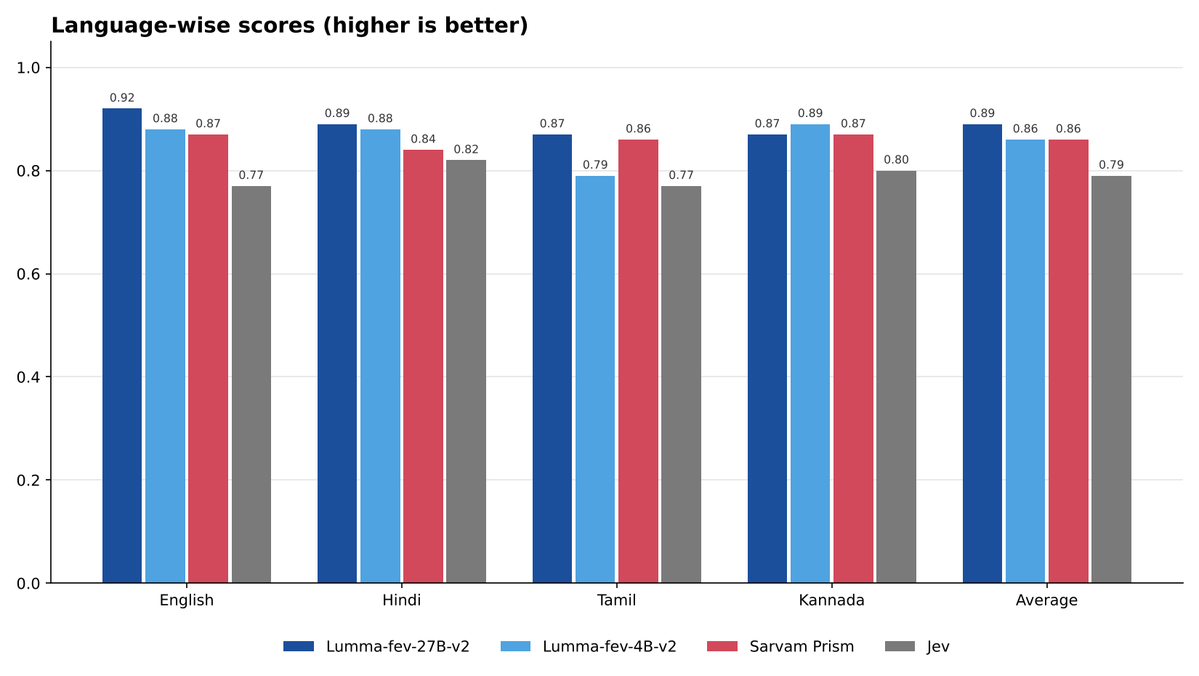
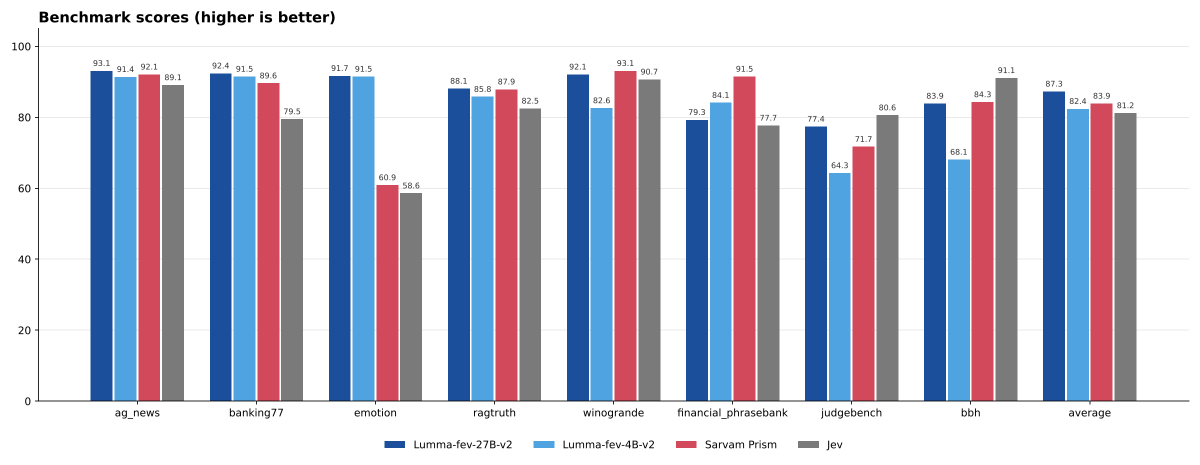
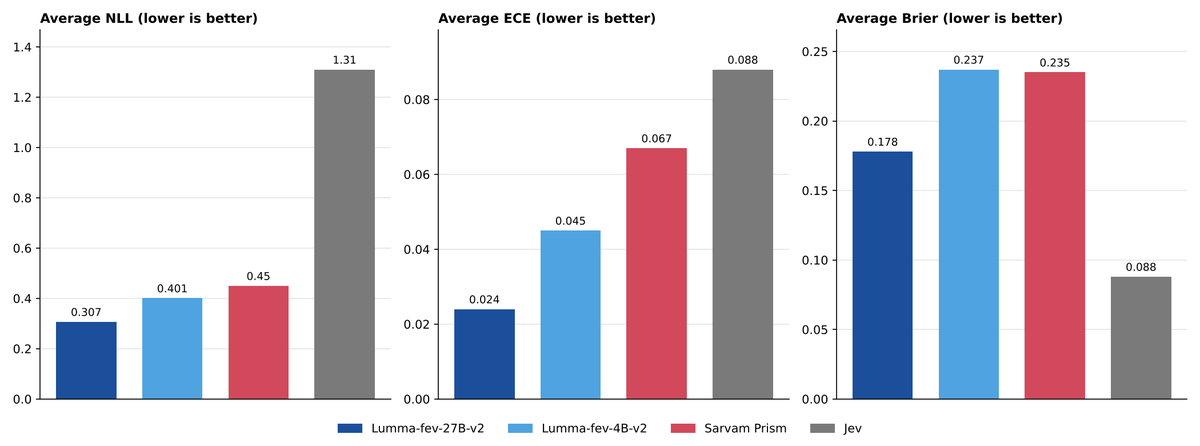
Our v2 decision model, Lumma-fev-v2, has outperformed @SarvamAI 's Prism on several benchmarks while remaining 3× smaller in size.
Trained on just three Indic languages - Hindi, Kannada, and Tamil : Lumma-fev-v2 also delivers competitive performance across our internal Indic benchmarks.
Congratulations to @SarvamAI on the launch of Prism! It's great to see more teams in India advancing frontier AI research while focusing on Indic languages
Explore Lumma-fev-v2: https://t.co/Ur3Cfg8T4F
Lumma-Fev v2 is now available as GGUF. 🚀
We've released GGUF versions of Lumma-Fev-27B-v2 and Lumma-Fev-4B-v2, so you can run them with llama.cpp. Every quantization is included, from Q2_K to full BF16.
It works in English, Hindi, Tamil and Kannada.
🔗 27B: https://t.co/TiPKkgRx62
🔗 4B: https://t.co/brT4mvC2vS
📖 Blog: https://t.co/4enwbD2QYn
🚀 Introducing the Lumma-fev-v2 family of decision models!
🏆 Our model ranks in the Top 3 on the Decision Index, with the PR awaiting merge.
From 27B to 0.1B parameters, we’re releasing models across the entire size spectrum !
📦 Explore the models:
https://t.co/Ur3Cfg8T4F
📖 Read the technical blog:
https://t.co/4enwbD2QYn
Open-sourcing DecisionFormer 🚀
Think "Transformers library", but for decision models.
🤗 @huggingface made it easy to use any language model. We wanted the same for decision models: models that don't write an answer but make a call with a calibrated probability for every option, in a single forward pass.
🔧 Full fine-tune, LoRA, QLoRA
🧠 Causal, bidirectional, prefix-bidirectional attention
📦 Any backbone: Qwen, Gemma, Llama, ModernBERT,
One forward pass, calibrated probabilities, no generation.
https://t.co/OGtpm7a6Tj
Tell us what you build.
Open-sourcing DecisionFormer 🚀
Think "Transformers library", but for decision models.
🤗 @huggingface made it easy to use any language model. We wanted the same for decision models: models that don't write an answer but make a call with a calibrated probability for every option, in a single forward pass.
🔧 Full fine-tune, LoRA, QLoRA
🧠 Causal, bidirectional, prefix-bidirectional attention
📦 Any backbone: Qwen, Gemma, Llama, ModernBERT,
One forward pass, calibrated probabilities, no generation.
https://t.co/OGtpm7a6Tj
Tell us what you build.
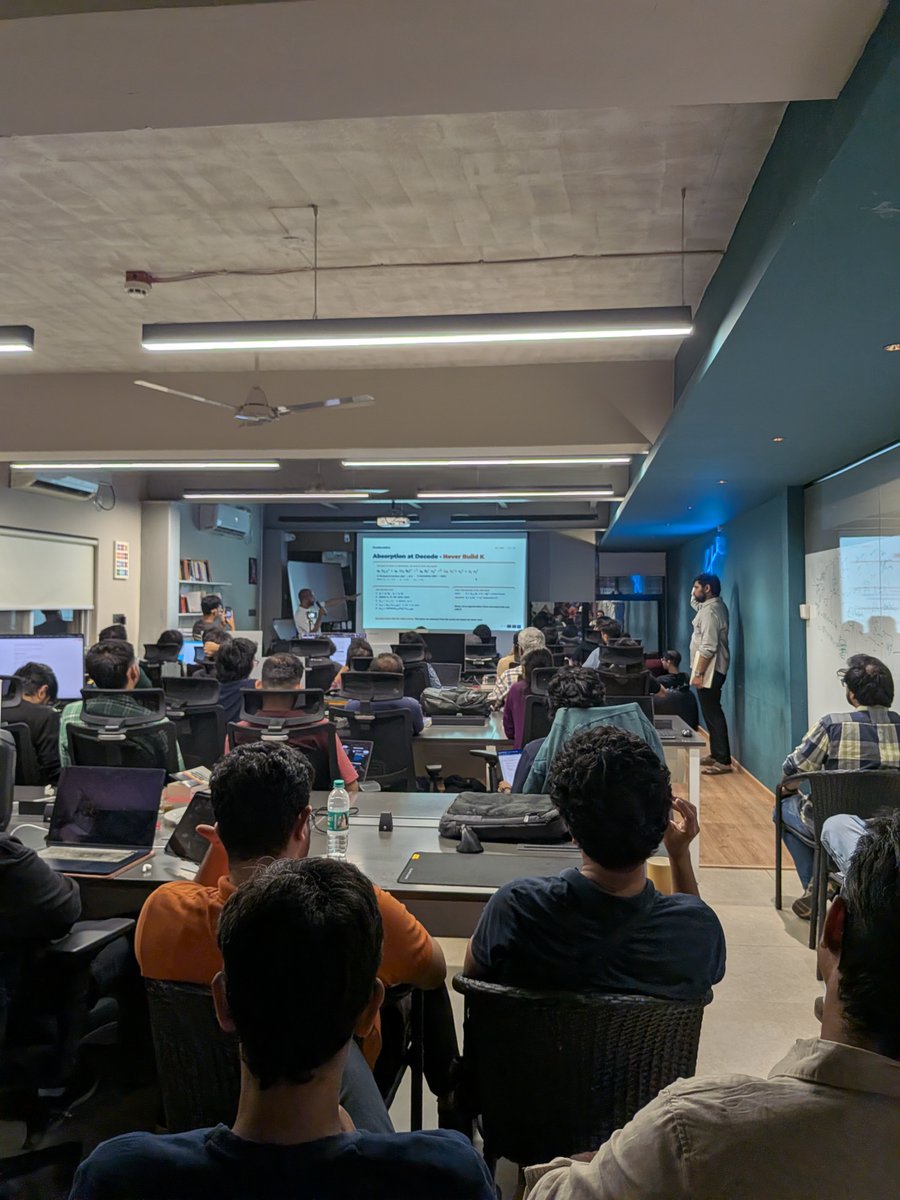
Yesterday evening, I had the opportunity to present our latest research, Grouped Value Attention (GVA) at @lossfunk .
It was great connecting with fellow researchers and developers, exchanging ideas, and discussing how we can make LLMs more efficient. Thank you to everyone who joined, asked insightful questions, and showed interest in our work.
Special thanks to @lossfunk and @paraschopra for hosting us and creating a space for meaningful technical discussions and knowledge sharing.
Looking forward to more such conversations with the AI research community!
Yesterday evening, our CEO Abhay kumar presented our latest research on Grouped Value Attention (GVA) at @lossfunk . A big thank you to all the fellow researchers and developers who joined us, asked insightful questions, and showed such great interest in our approach.
It was wonderful to see the community engage so deeply with our work! And a special thanks to @lossfunk for hosting us and providing a space for great conversations and knowledge sharing
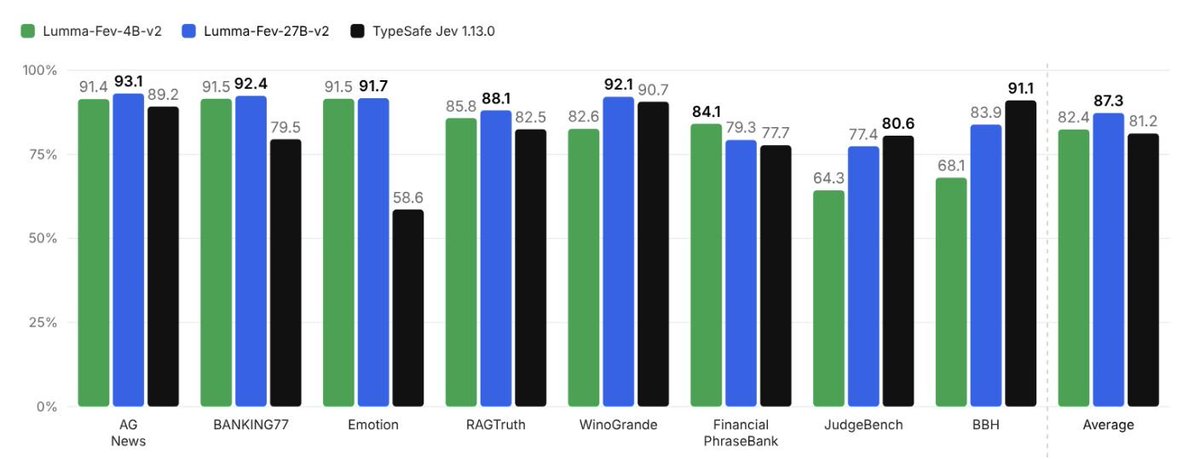
We're open-sourcing Lumma-fev-27B, our most capable Multimodal decision model, outperforming Jev across multiple benchmarks
It is trained on English and 3 Indic languages including Hindi, Kannada and Tamil
📜 Blog: https://t.co/buGgI0ngmF
🤗 Model: https://t.co/ASyhNx1G04
We're open-sourcing Lumma-fev-27B, our most capable Multimodal decision model, outperforming Jev across multiple benchmarks
It is trained on English and 3 Indic languages including Hindi, Kannada and Tamil
📜 Blog: https://t.co/buGgI0ngmF
🤗 Model: https://t.co/ASyhNx1G04
🔥 Adding a new member to our Lumma-fev Decision Family!
Today, we're open-sourcing Lumma-fev-27B, our most capable Multimodal decision model, outperforming Jev across multiple benchmarks. It is trained on English and 3 Indic languages including Hindi, Kannada and Tamil.
📜 Blog: https://t.co/fwkX2sGwRQ
🤗 Model: https://t.co/1fmXhEzk6C
#jev #decisionmodels #llm #ai #ml #openSource
🔥 Adding a new member to our Lumma-fev Decision Family!
Today, we're open-sourcing Lumma-fev-27B, our most capable Multimodal decision model, outperforming Jev across multiple benchmarks. It is trained on English and 3 Indic languages including Hindi, Kannada and Tamil.
📜 Blog: https://t.co/fwkX2sGwRQ
🤗 Model: https://t.co/1fmXhEzk6C
#jev #decisionmodels #llm #ai #ml #openSource
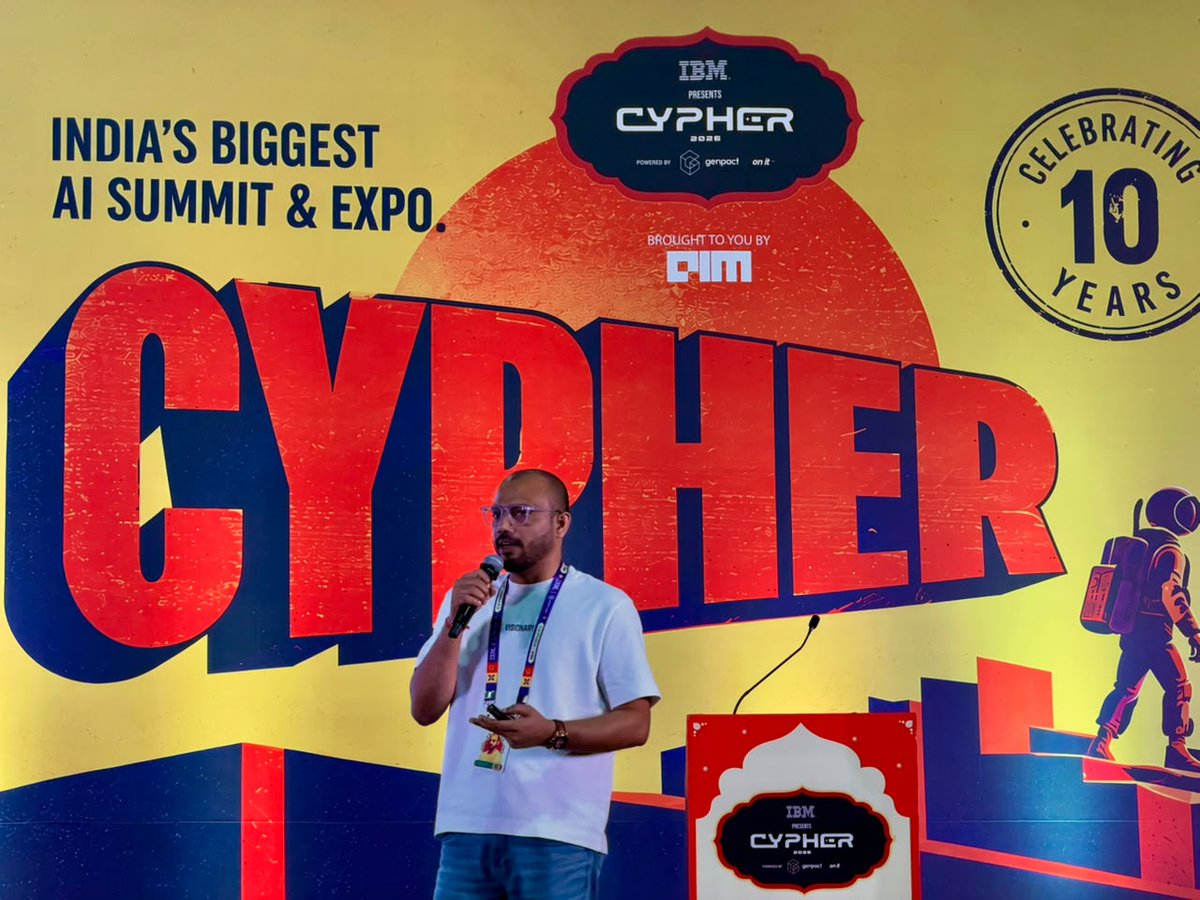
Our CEO, Abhay Kumar, had the opportunity to speak at Cypher 2026!
It was a great experience for the FrontiersMind team, with plenty of insightful conversations and meaningful discussions with fellow founders, developers, and AI enthusiasts
A big thank you to @Analyticsindiam for having us at the event and for bringing together such a vibrant AI community!
Thanks to Sysone-bench for benchmarking our model along with other state of the art models.
On various tasks and domains, Lumma-Fev Models have given great performance.
Checkout the benchmarks here: https://t.co/pU0SNjtAUZ