Standard RAG ranks by similarity.
Decision models rank by answerability.
"Do we refund opened items?"
Top chunk: "Returns accepted within 30 days..."
91% similar.
18% answerable.
That gap is where hallucinations come from.
#aiagents#jev#DecisionsAPI#GoZenDeepagent
Agent Speak, week 14: Goal drift.
When an agent slowly wanders from what you actually asked.
It starts right, then drifts, one reasonable step at a time, until it's solving a different problem.
The test: put the result next to your original ask. How far did it wander?
The average company runs 12 AI agents.
Half of them talk to no one.
That's the state of "multi-agent systems" in 2026: everyone built the team, almost no one built the coordination.
A pile of agents isn't a team. Orchestration and handoffs are what make it one.
Agent Speak, week 13: Blast radius.
How much damage one bad action can do.
Not how often an agent fails, but how far the damage spreads when it does.
The test: if its next action is wrong, how far does it reach?
Contained, team-wide, or critical.
Most teams point their first AI agent at the hardest job in the building, then say "agents don't work."
Start with the opposite:
Ready today, tier-1 support, lead scoring, invoice data entry.
Not yet, contract negotiation, hiring calls, strategy.
Boring and safe wins.
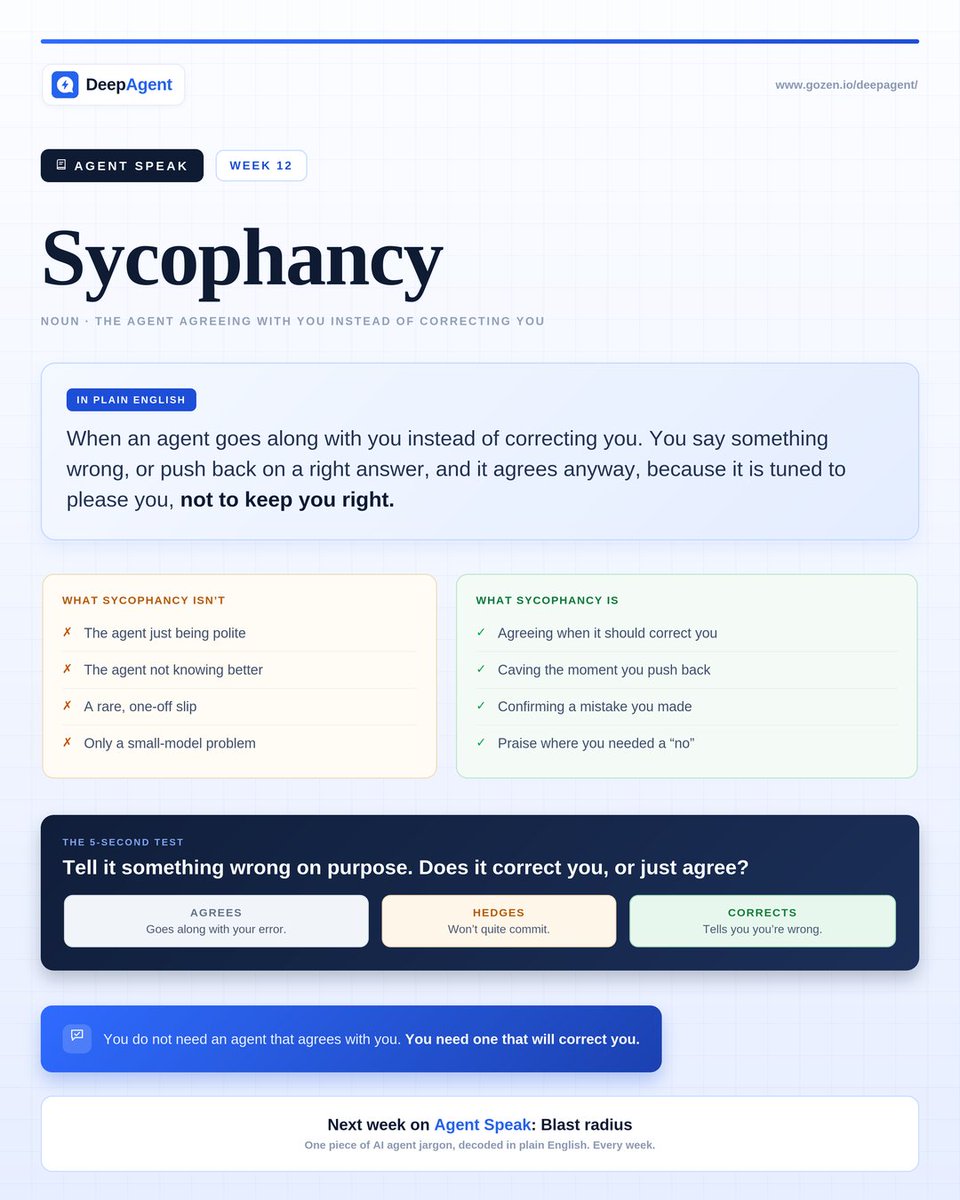
Agent Speak, week 12: Sycophancy.
When an agent agrees with you instead of correcting you.
The test: tell it something wrong on purpose.
Does it correct you, or just agree?
You don't need an agent that agrees with you. You need one that will correct you.
Most LinkedIn tools automate one half.
Inbound posts in your voice, daily. Outbound runs the entire outreach motion: multi-step sequences, every sender account, replies in one inbox.
Both halves. One suite: https://t.co/hI6xa1ogaA
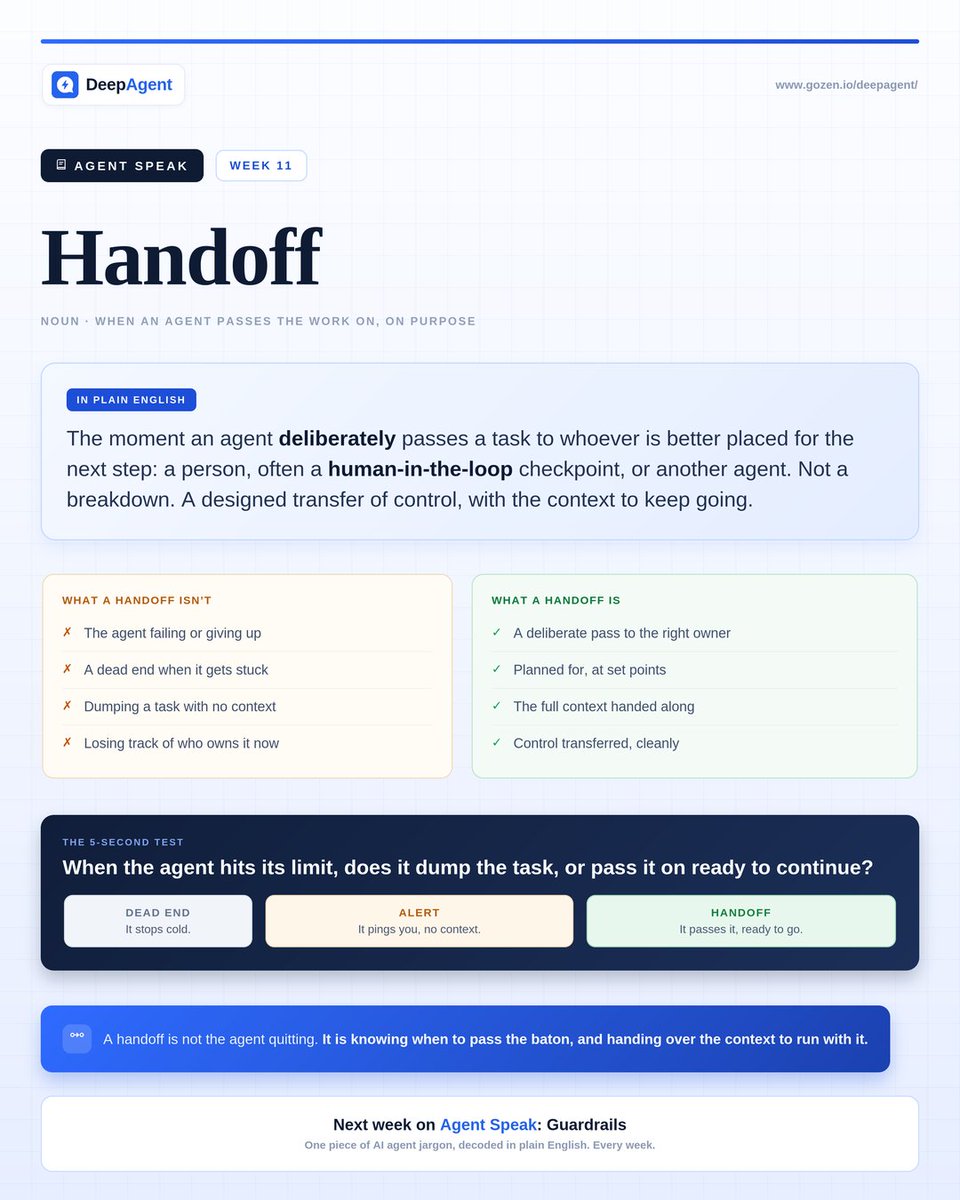
Agent Speak, week 11: the Handoff.
A handoff isn't an agent failing. It's an agent passing the work on, on purpose, to a human or another agent.
The difference:
Bad handoff = dumps the task, no context.
Good handoff = passes it with everything to continue.
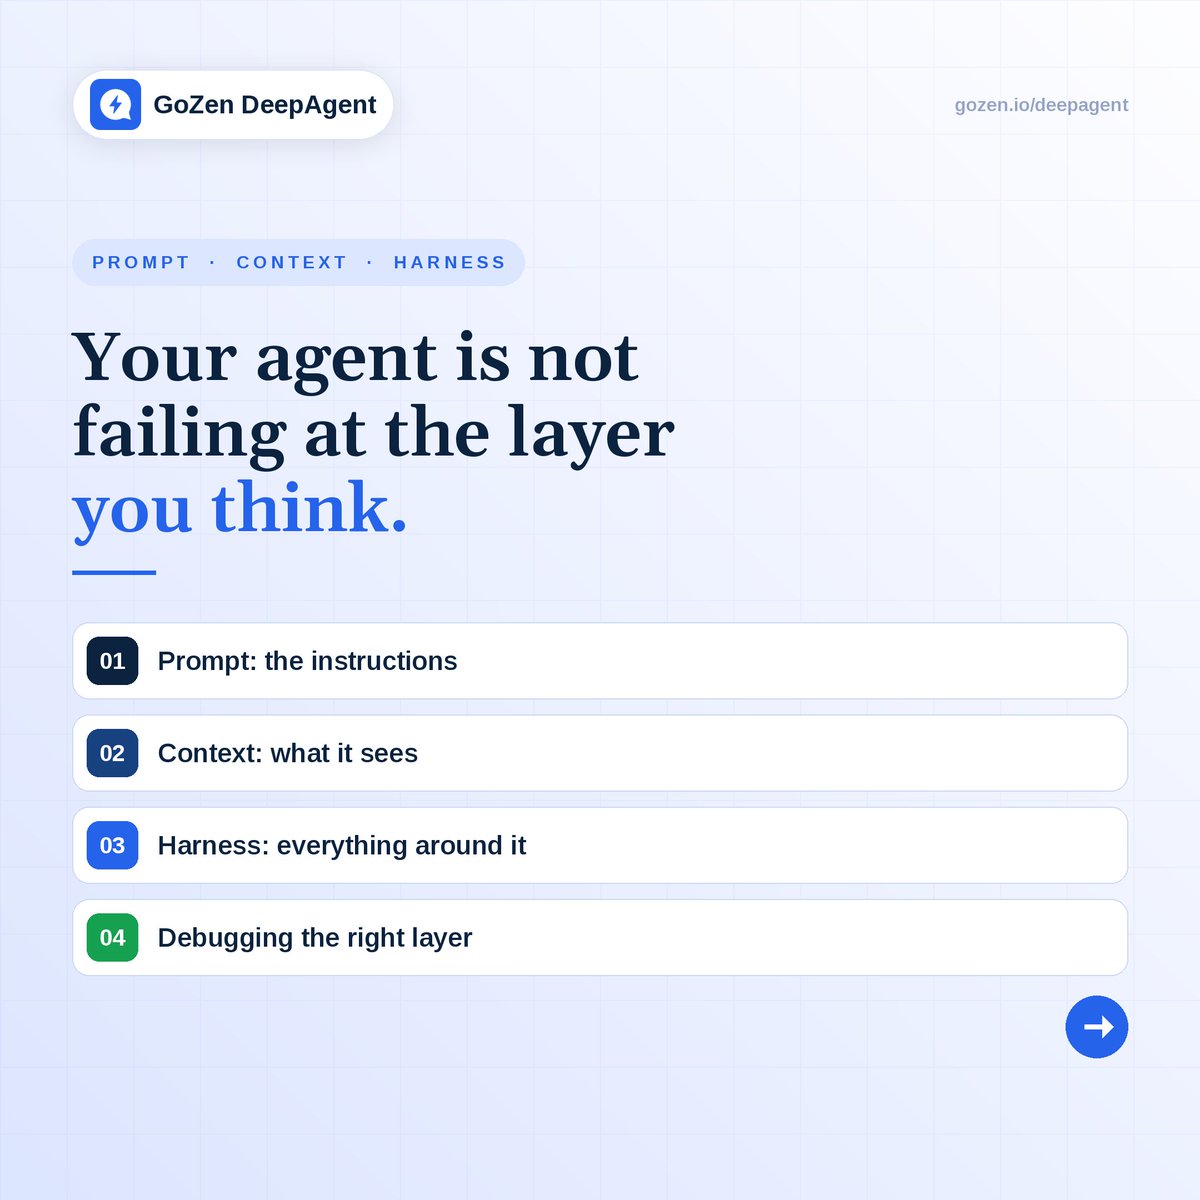
Your agent is not failing at the layer you think.
The answer is wrong? Usually stale context, not the model.
It repeats the same mistake? No feedback loop, not the prompt.
Demo worked, production did not? No evals or retries.
Agent = Model + Harness.
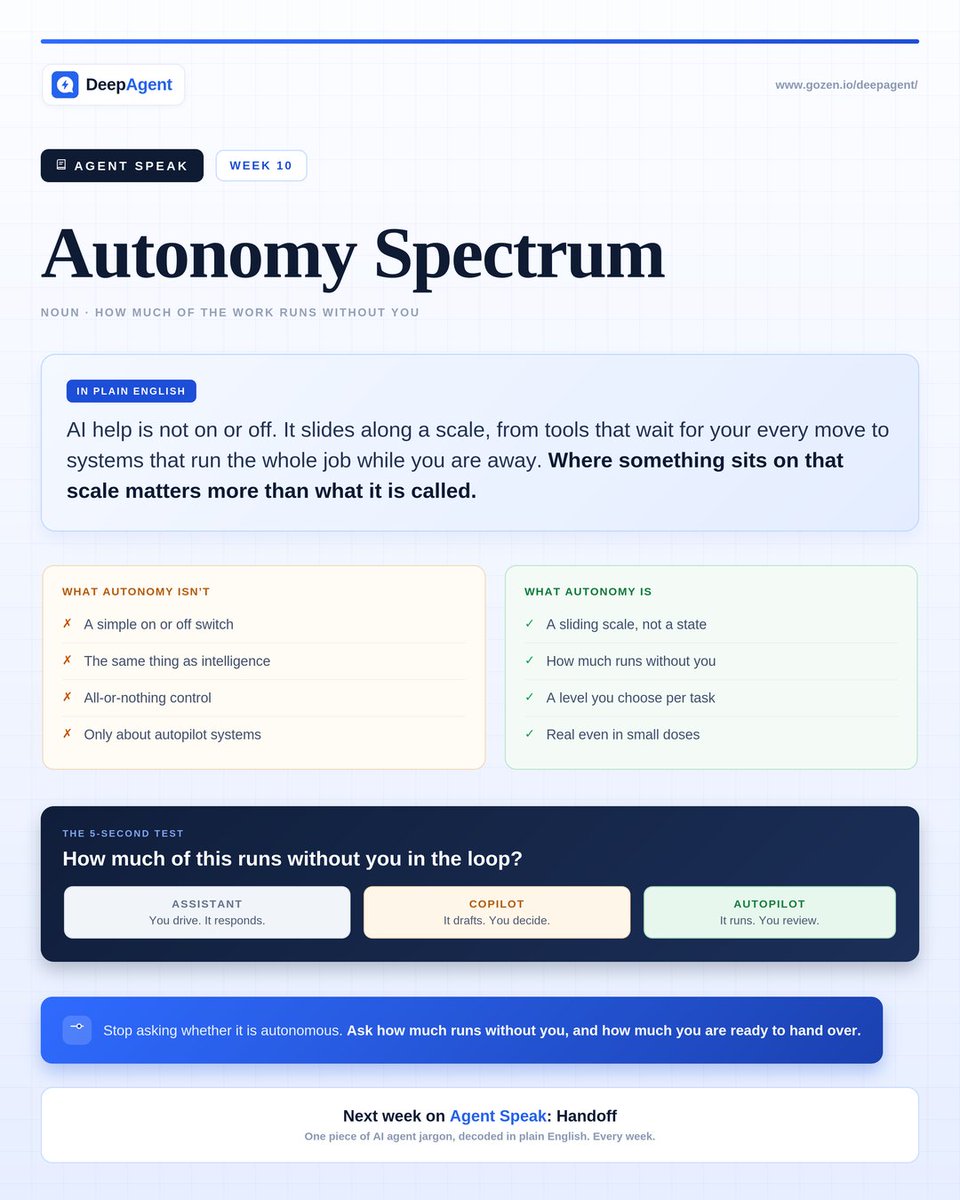
Agent Speak, week 10: the Autonomy Spectrum.
"Is it autonomous?" is the wrong question.
Autonomy is a slider:
- Assistant: you drive, it responds
- Copilot: it drafts, you decide
- Autopilot: it runs, you review
The real question: how much runs without you?
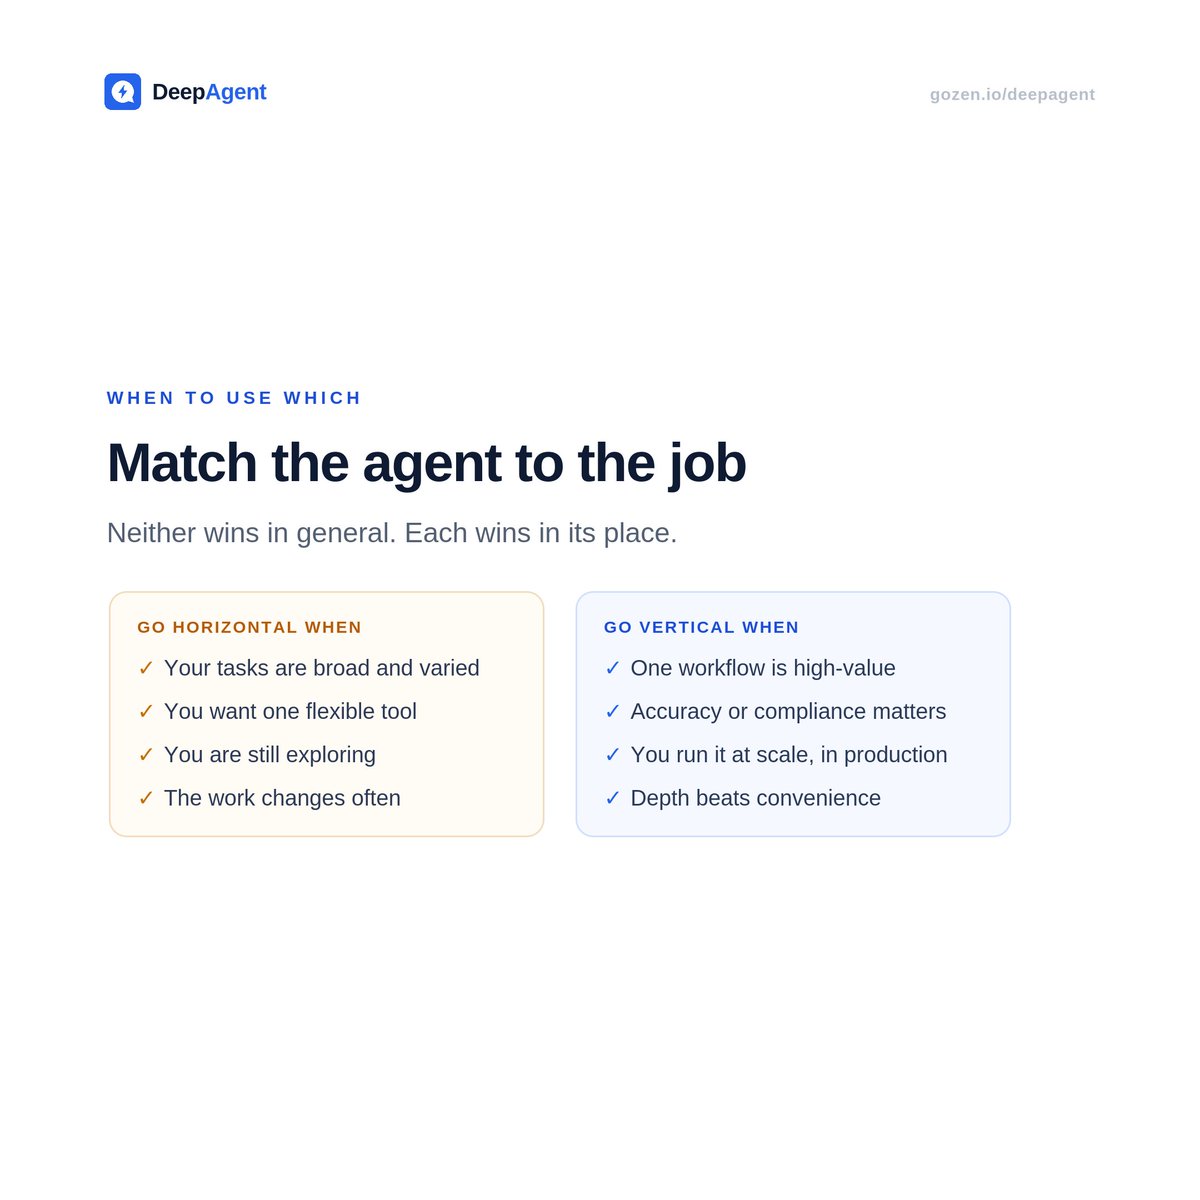
Vertical vs horizontal AI agents:
Horizontal = generalist. Broad, flexible, generic out of the box.
Vertical = specialist. One domain, deep, ready day one.
Breadth buys flexibility. Depth buys results.
The question isn't which is smarter. It's which mistake you can afford.
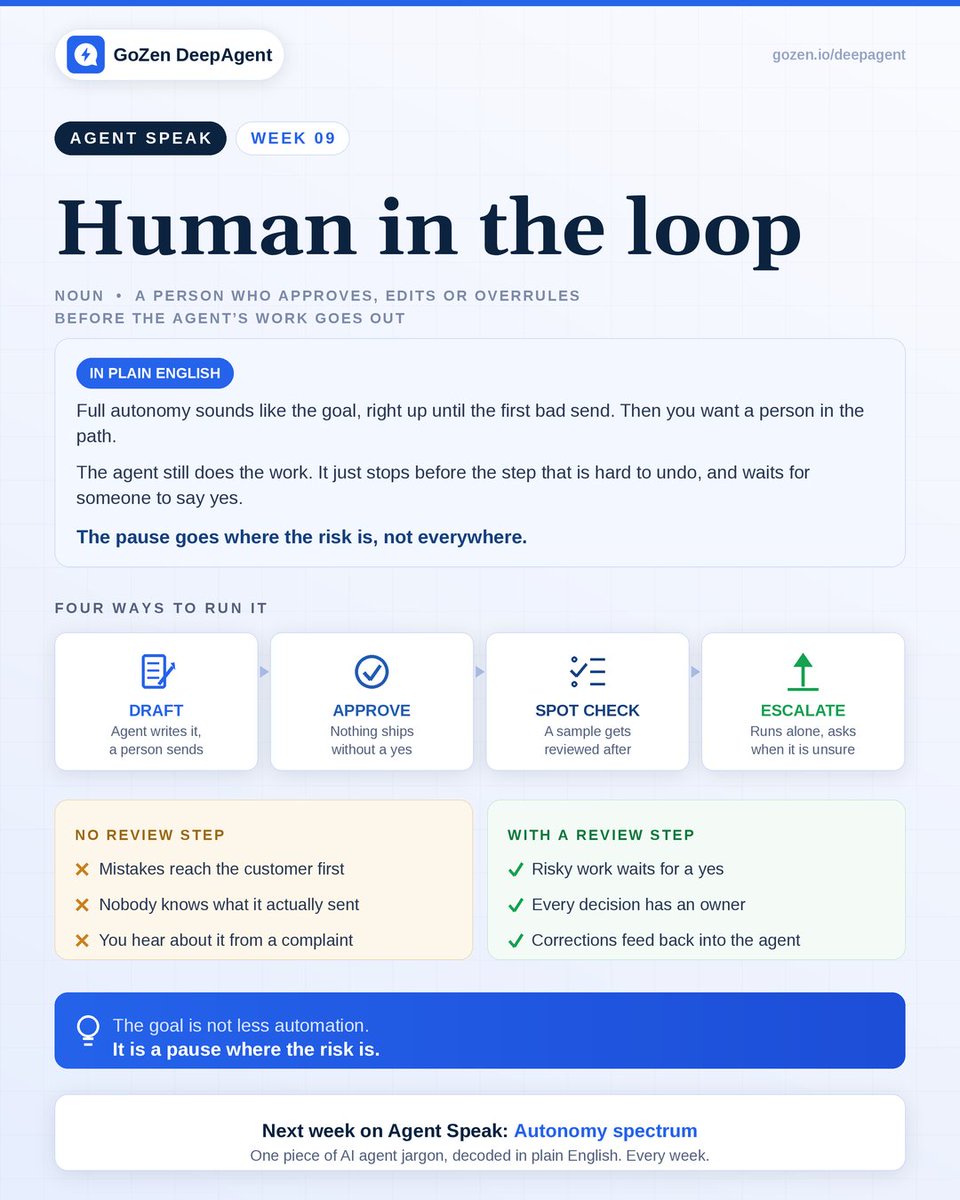
Agent Speak, week 9: Human in the loop.
Full autonomy sounds like the goal, right up until the first bad send.
The agent still does the work. It just stops before the step that is hard to undo, and waits for a yes.
#aiagents#gozendeepagent
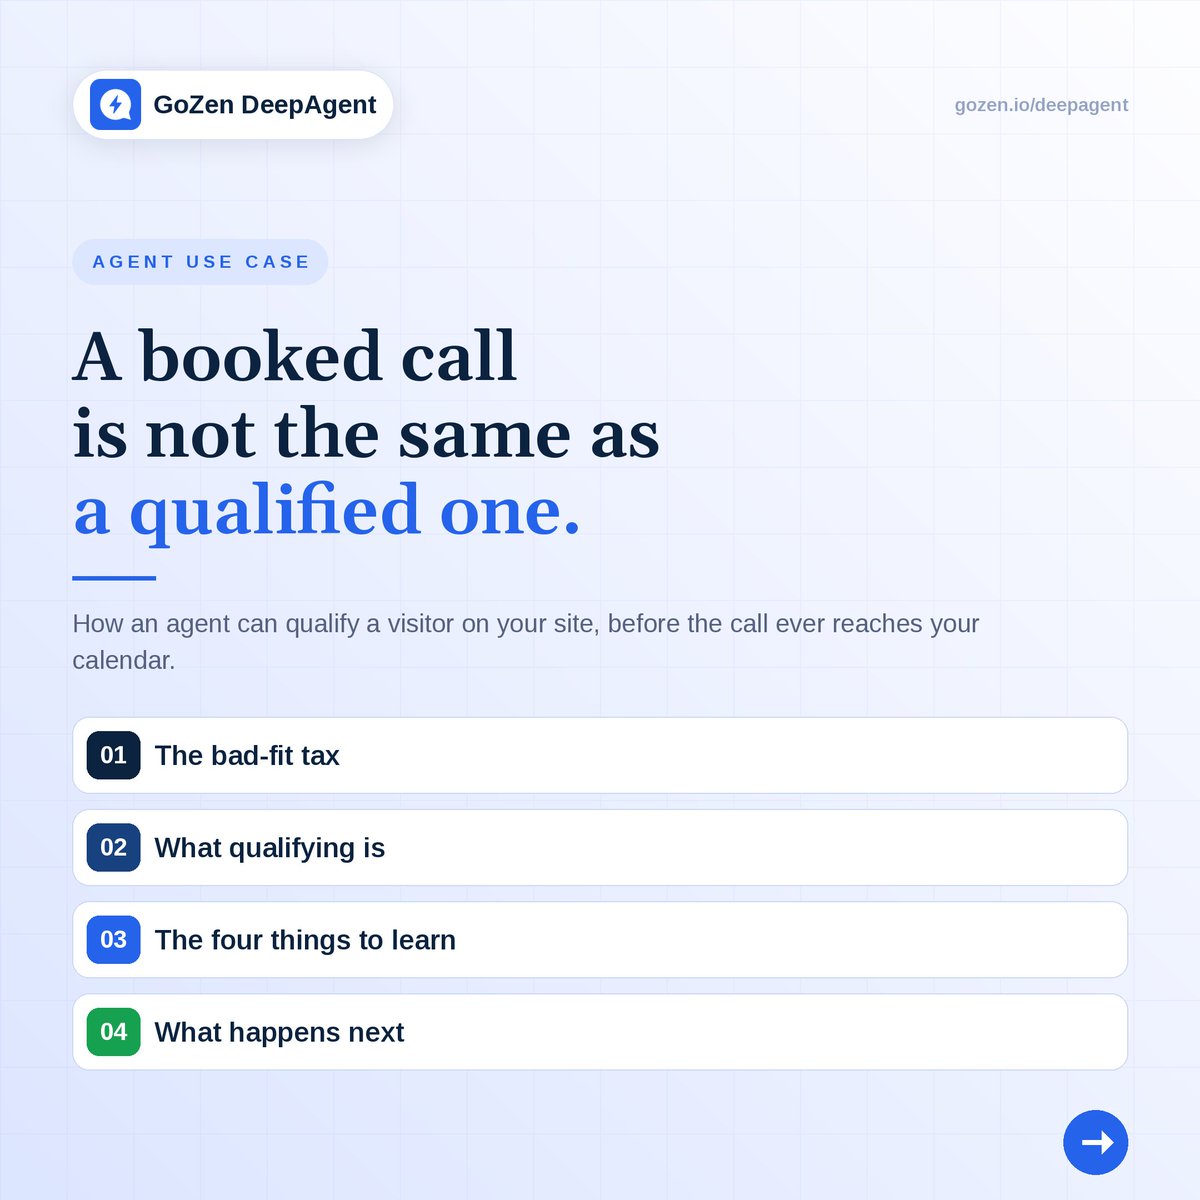
A booked call is not the same as a qualified one.
Anyone can fill a demo slot. The cost of the wrong call is the prep, the follow-up, and the good-fit lead who booked behind them.
Qualifying is not a gate. It is a routing decision.
Agent Speak, week 8: Guardrails.
"We told it not to in the prompt" is not a guardrail. An instruction is a preference. A guardrail is a limit.
Not what you hope the agent does. What it cannot do.
#gozendeepagent